Stripping Out the Noise in Strategic Decision Models
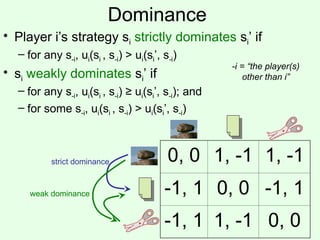
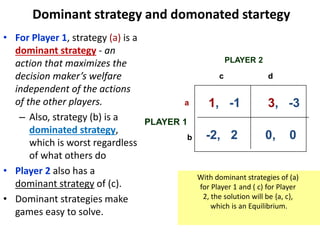
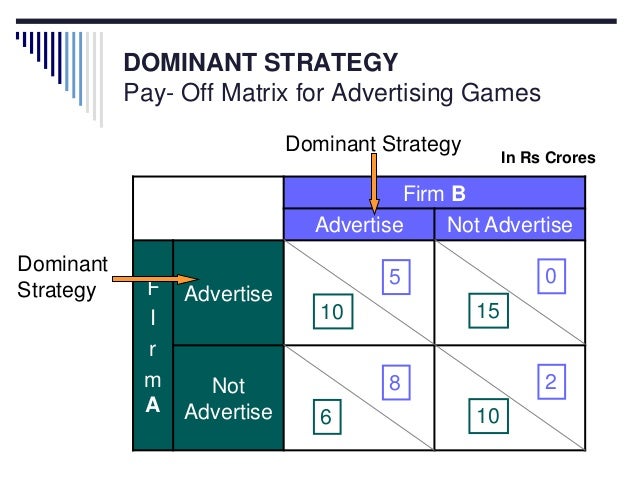
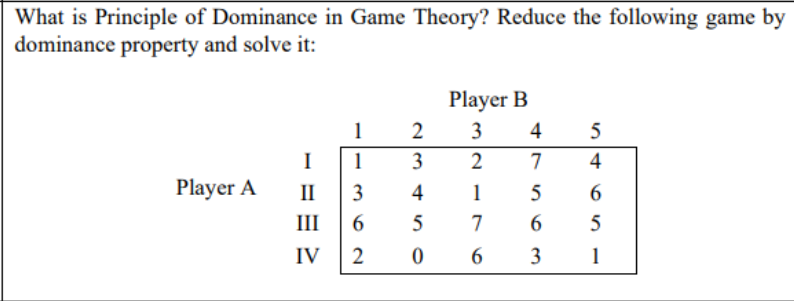
When you are looking at a payoff matrix with five strategies per player, the first thing you should do is remove the ones that make no sense to ever pick. That process is what people call Dominance In Game Theory. It is not glamorous, but it is about the fastest way to shrink a massive decision tree into something you can actually solve by hand or pass into a solver without timing out. A strategy is dominated when another strategy gives you equal or better payoffs no matter what the opponent does. Strict dominance means the alternative is always strictly better. Weak dominance means it is better in at least one case and never worse. The difference matters because the order in which you eliminate strategies changes your outcome when weak dominance is involved. I learned this the hard way on a routing optimization project a few years back. I was modeling a two-player game where one side chose between three bandwidth allocation strategies and the other chose between three congestion control mechanisms. The payoff matrix was 3x3 with integer values ranging from 12 to 247. I ran iterated elimination of strictly dominated strategies and got a clean residual matrix. Then I ran the same process including weakly dominated strategies and ended up at a completely different Nash equilibrium. I had to go back and rebuild the model with a proper support enumeration routine instead of relying on dominance alone. The workaround was straightforward: I separated the strict and weak passes, compared the reduced forms, and then fed both results into a Lemke-Howson path enumeration to verify consistency. That added about twenty minutes to the build but saved me three days of debugging false conclusions later.
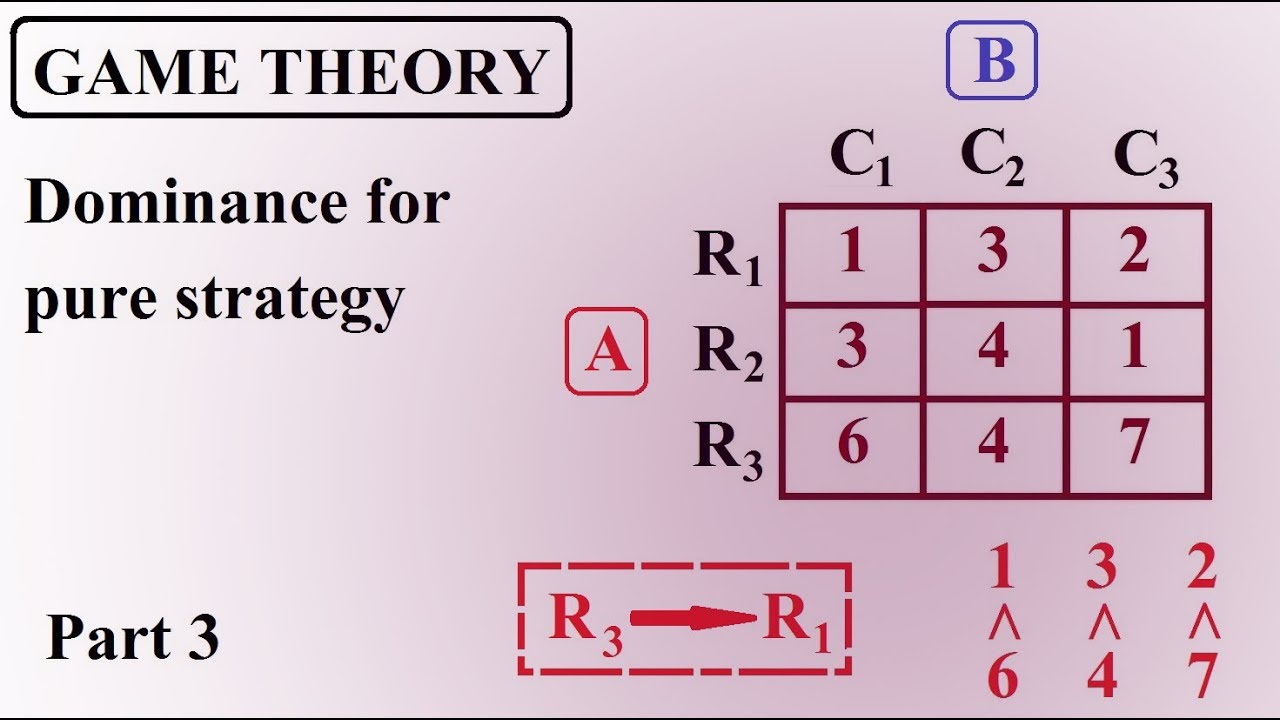
The practical method goes like this. Lay out your payoff matrix with row player strategies down the left and column player strategies across the top. Each cell contains an ordered pair where the first number is the row player payoff and the second is the column player payoff. Scan the row player strategies first. Pick any two rows and compare them cell by cell. If row A is greater than or equal to row B in every column, then row B is dominated by row A for the row player. Cross it out. Repeat until no more strict dominations exist. Then do the same for the column player, comparing columns from the column player's perspective, keeping in mind that the column player wants to maximize their own payoff number in the ordered pair. After the strict pass is done, run a weak dominance pass. This is where most people make mistakes. A weakly dominated strategy can sometimes be part of a Nash equilibrium if the opponent plays the specific strategy that makes the payoffs equal. Eliminating it too early removes valid equilibria from your analysis. I usually mark weakly dominated strategies in a separate color in my spreadsheets and run the reduction twice: once with them gone and once leaving them in. The equilibrium sets should be compared afterward. For larger matrices where hand elimination becomes impractical, you can write a short script. A Python function using NumPy takes about ten lines. You vectorize the comparison across rows and columns, flag the dominated indices, drop them, and loop until convergence. A typical 8x8 matrix reduces in under a second on a modern laptop. A 12x12 matrix might take two or three passes and also runs in well under a second. The bottleneck usually appears when you are working with continuous strategy spaces where dominance has to be checked through integration rather than discrete comparison. That is a different problem entirely and dominance alone will not save you.
One thing beginners consistently miss is that dominance is relative to the opponent's remaining strategies, not absolute. When you eliminate a column, the dominance relationships in the remaining rows can change. A strategy that was not dominated before might become dominated after a weakly dominated column is removed. This is why iterated elimination is necessary and why doing it in one pass is wrong. The correct approach is a loop: scan for dominance, eliminate, rescan, repeat, until a full pass produces no new eliminations. Another counter-intuitive point is that a game can have a unique Nash equilibrium even when no strategy is strictly dominated in the original matrix. Dominance is a sufficient tool for finding equilibria in some games, but it is not necessary. Zero-sum games with a saddle point often resolve through dominance quickly, but many asymmetric games with mixed strategies do not reveal anything through dominance until you are deep into iterated elimination. If your matrix reduces to a 2x2 or smaller after strict dominance elimination, you can solve the remainder using the standard mixing formula or linear programming. If it does not reduce at all, dominance has not helped you and you need a different approach. There are scenarios where dominance fails completely. Simultaneous move games with more than two players expand the complexity dramatically because pairwise dominance checks do not capture the full strategic interaction. Multi-player games also introduce the possibility of correlated equilibria, which dominate reasoning alone cannot identify. I ran into this when modeling a three-firm pricing game where each firm had four price points. Dominance elimination removed about forty percent of the strategy profile space, but the remaining 12x12x12 structure still had no clean equilibrium visible through dominance. The workaround was to use a quantal response equilibrium simulation instead, which gave me a distribution of likely outcomes rather than a single point prediction.
Get the Full Details
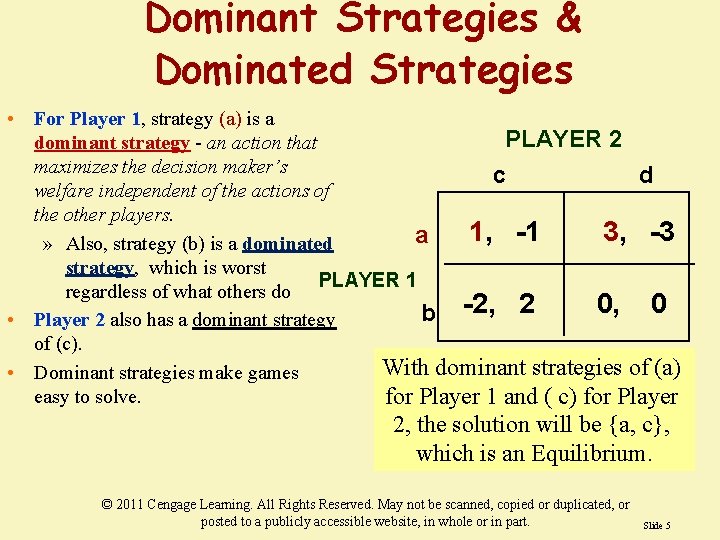
Another limitation worth noting is that dominance assumes rationality on both sides. In behavioral or experimental settings, players often do not avoid dominated strategies at the rates that theory predicts. I have seen lab data where roughly fifteen to twenty percent of subjects still played weakly dominated strategies even after multiple rounds of feedback. If you are building a model for actual human subjects rather than theoretical opponents, dominance-based reduction will overstate the predictability of the outcome. You need to factor in a noise parameter or switch to a level-k reasoning model. The computational shortcuts from dominance are real. In my experience, iterated strict dominance reduces a well-behaved game matrix by about sixty to eighty percent in the number of strategies before it stalls. That reduction turns a problem that would require thirty minutes of numerical computation into one that finishes in under two minutes. The trade-off is that you lose visibility into equilibria that depend on weakly dominated strategies being played with non-zero probability. If your application requires exact equilibrium selection rather than just a rough strategic picture, you need to document which strategies you eliminated and why, so the reduction path is transparent. If you want a working implementation, the logic is simple enough to build from scratch. Load your payoff matrices, run the strict dominance loop, record each elimination step, then run the weak dominance loop separately. Output the reduced matrices along with a log of which strategies were removed at each iteration. That log is what separates a useful analysis from a black box that nobody can verify later.