How To Actually Use The Dot Product Without Overcomplicating It
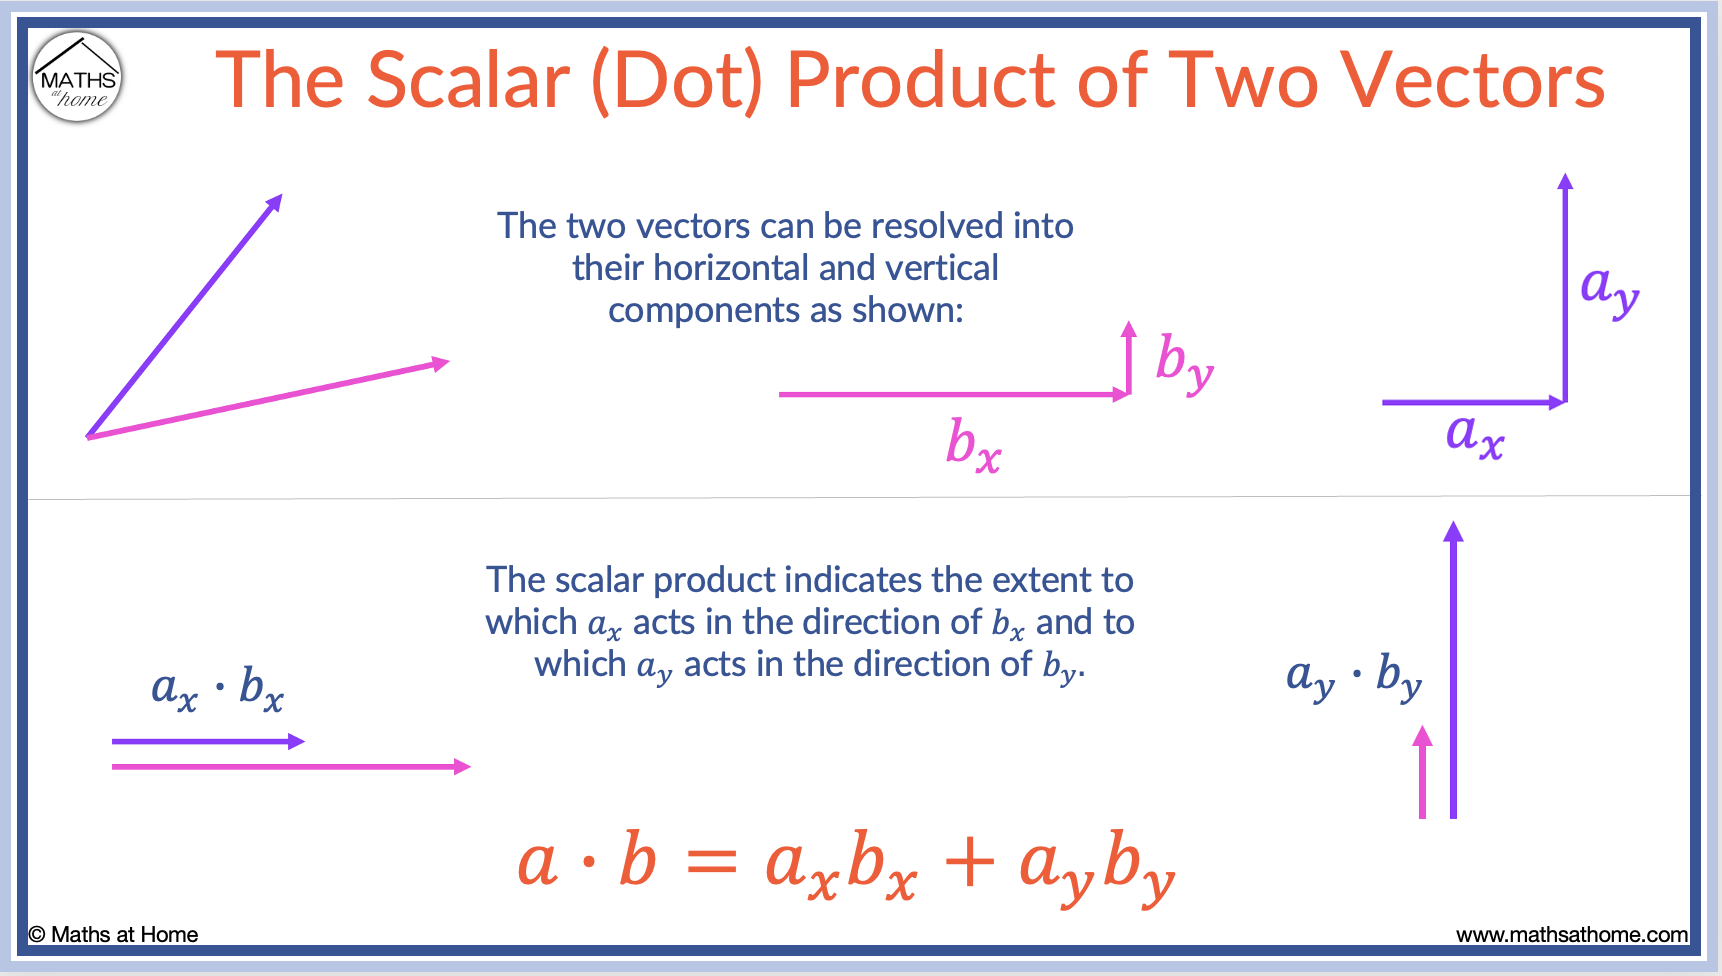
The dot product takes two equal-length vectors and squashes them into a single number. You multiply each corresponding pair of components and add those products together. That's it. The result is a scalar—no direction attached, just a value. People make this way more complicated than it needs to be. Let me show you the practical side before the textbook definition gets in the way.
The Mechanics
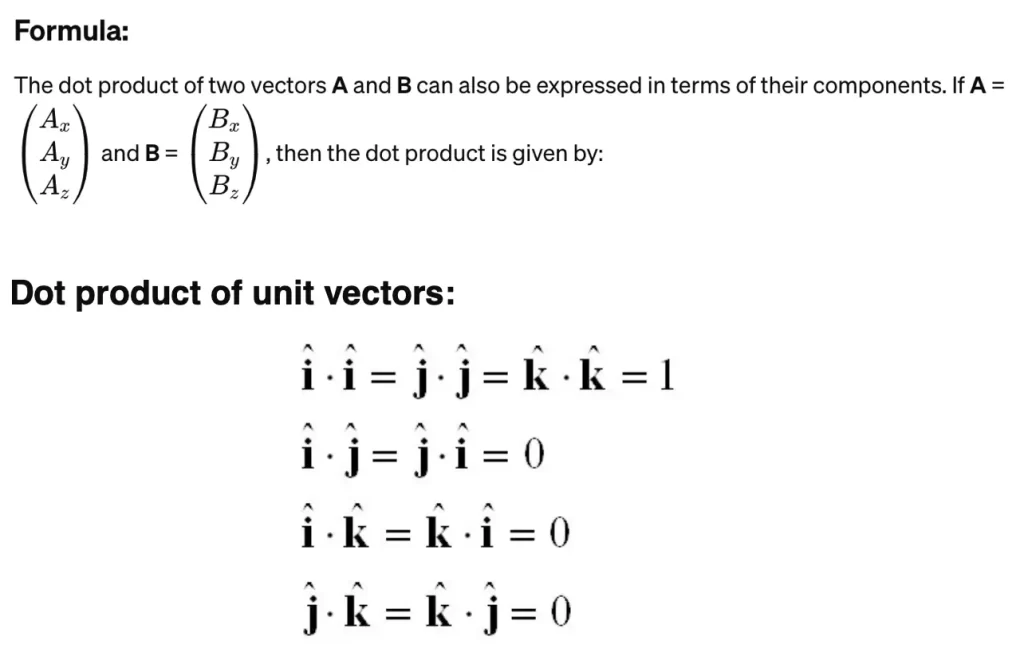
Take two vectors: a = [3, 4] and b = [1, 2]. The Dot Product Of Vectors is calculated as: (3 × 1) + (4 × 2) = 3 + 8 = 11 For three dimensions, it's the same pattern: a = [a, a, a], b = [b, b, b], result = ab + ab + ab. For N dimensions, you extend that pattern. No exception. No special case. Just pairwise multiplication and summation.
In code, this looks like:
Get the Full Details
def dot_product(a, b):
    return sum(x * y for x, y in zip(a, b))
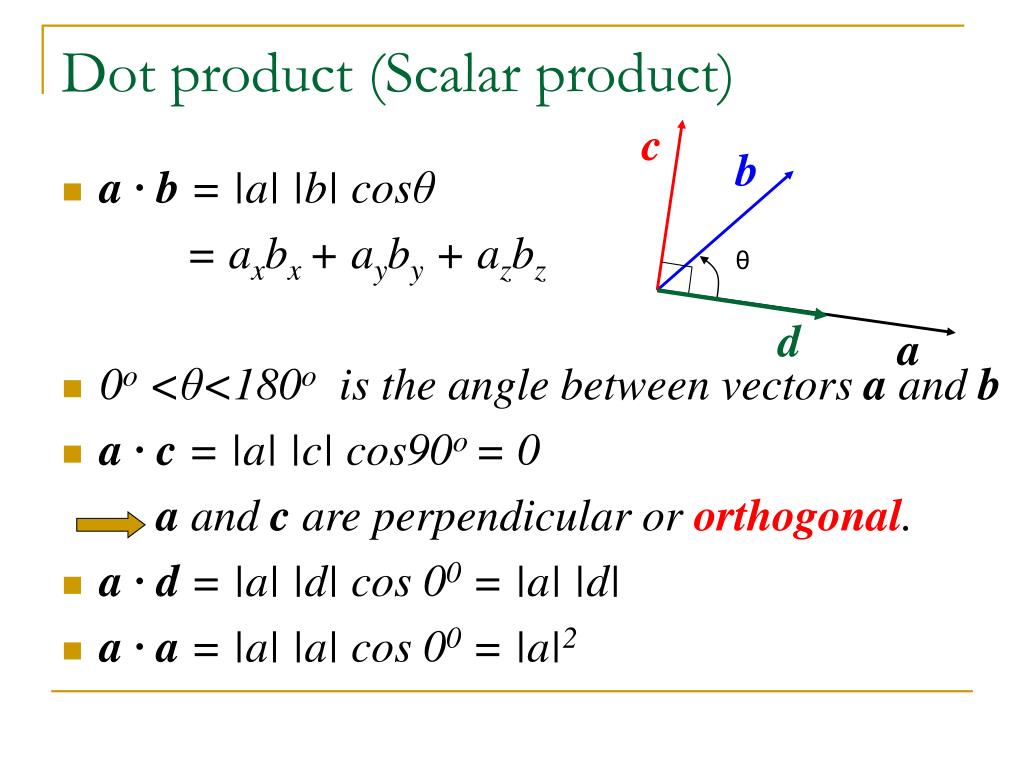
Short, readable, and correct. Don't overthink the implementation. The bottleneck in practice isn't the math—it's making sure your vectors are actually the same length before you pass them in. A silent dimension mismatch will cost you more time than the calculation itself. The scalar result tells you how much two vectors point in the same general direction. That's the entire intuition behind it. If the result is positive, the vectors lean toward each other. If it's negative, they lean away. Zero means they're perpendicular—orthogonal. Larger positive numbers mean stronger alignment, but only if you account for the lengths of both vectors. This is where most explanations go sideways. The dot product is not a pure measure of directional similarity because it's scaled by magnitude. Two long vectors pointing at a 60-degree angle can produce a larger dot product than two short vectors pointing in nearly the same direction. Always normalize first if you care about direction alone.
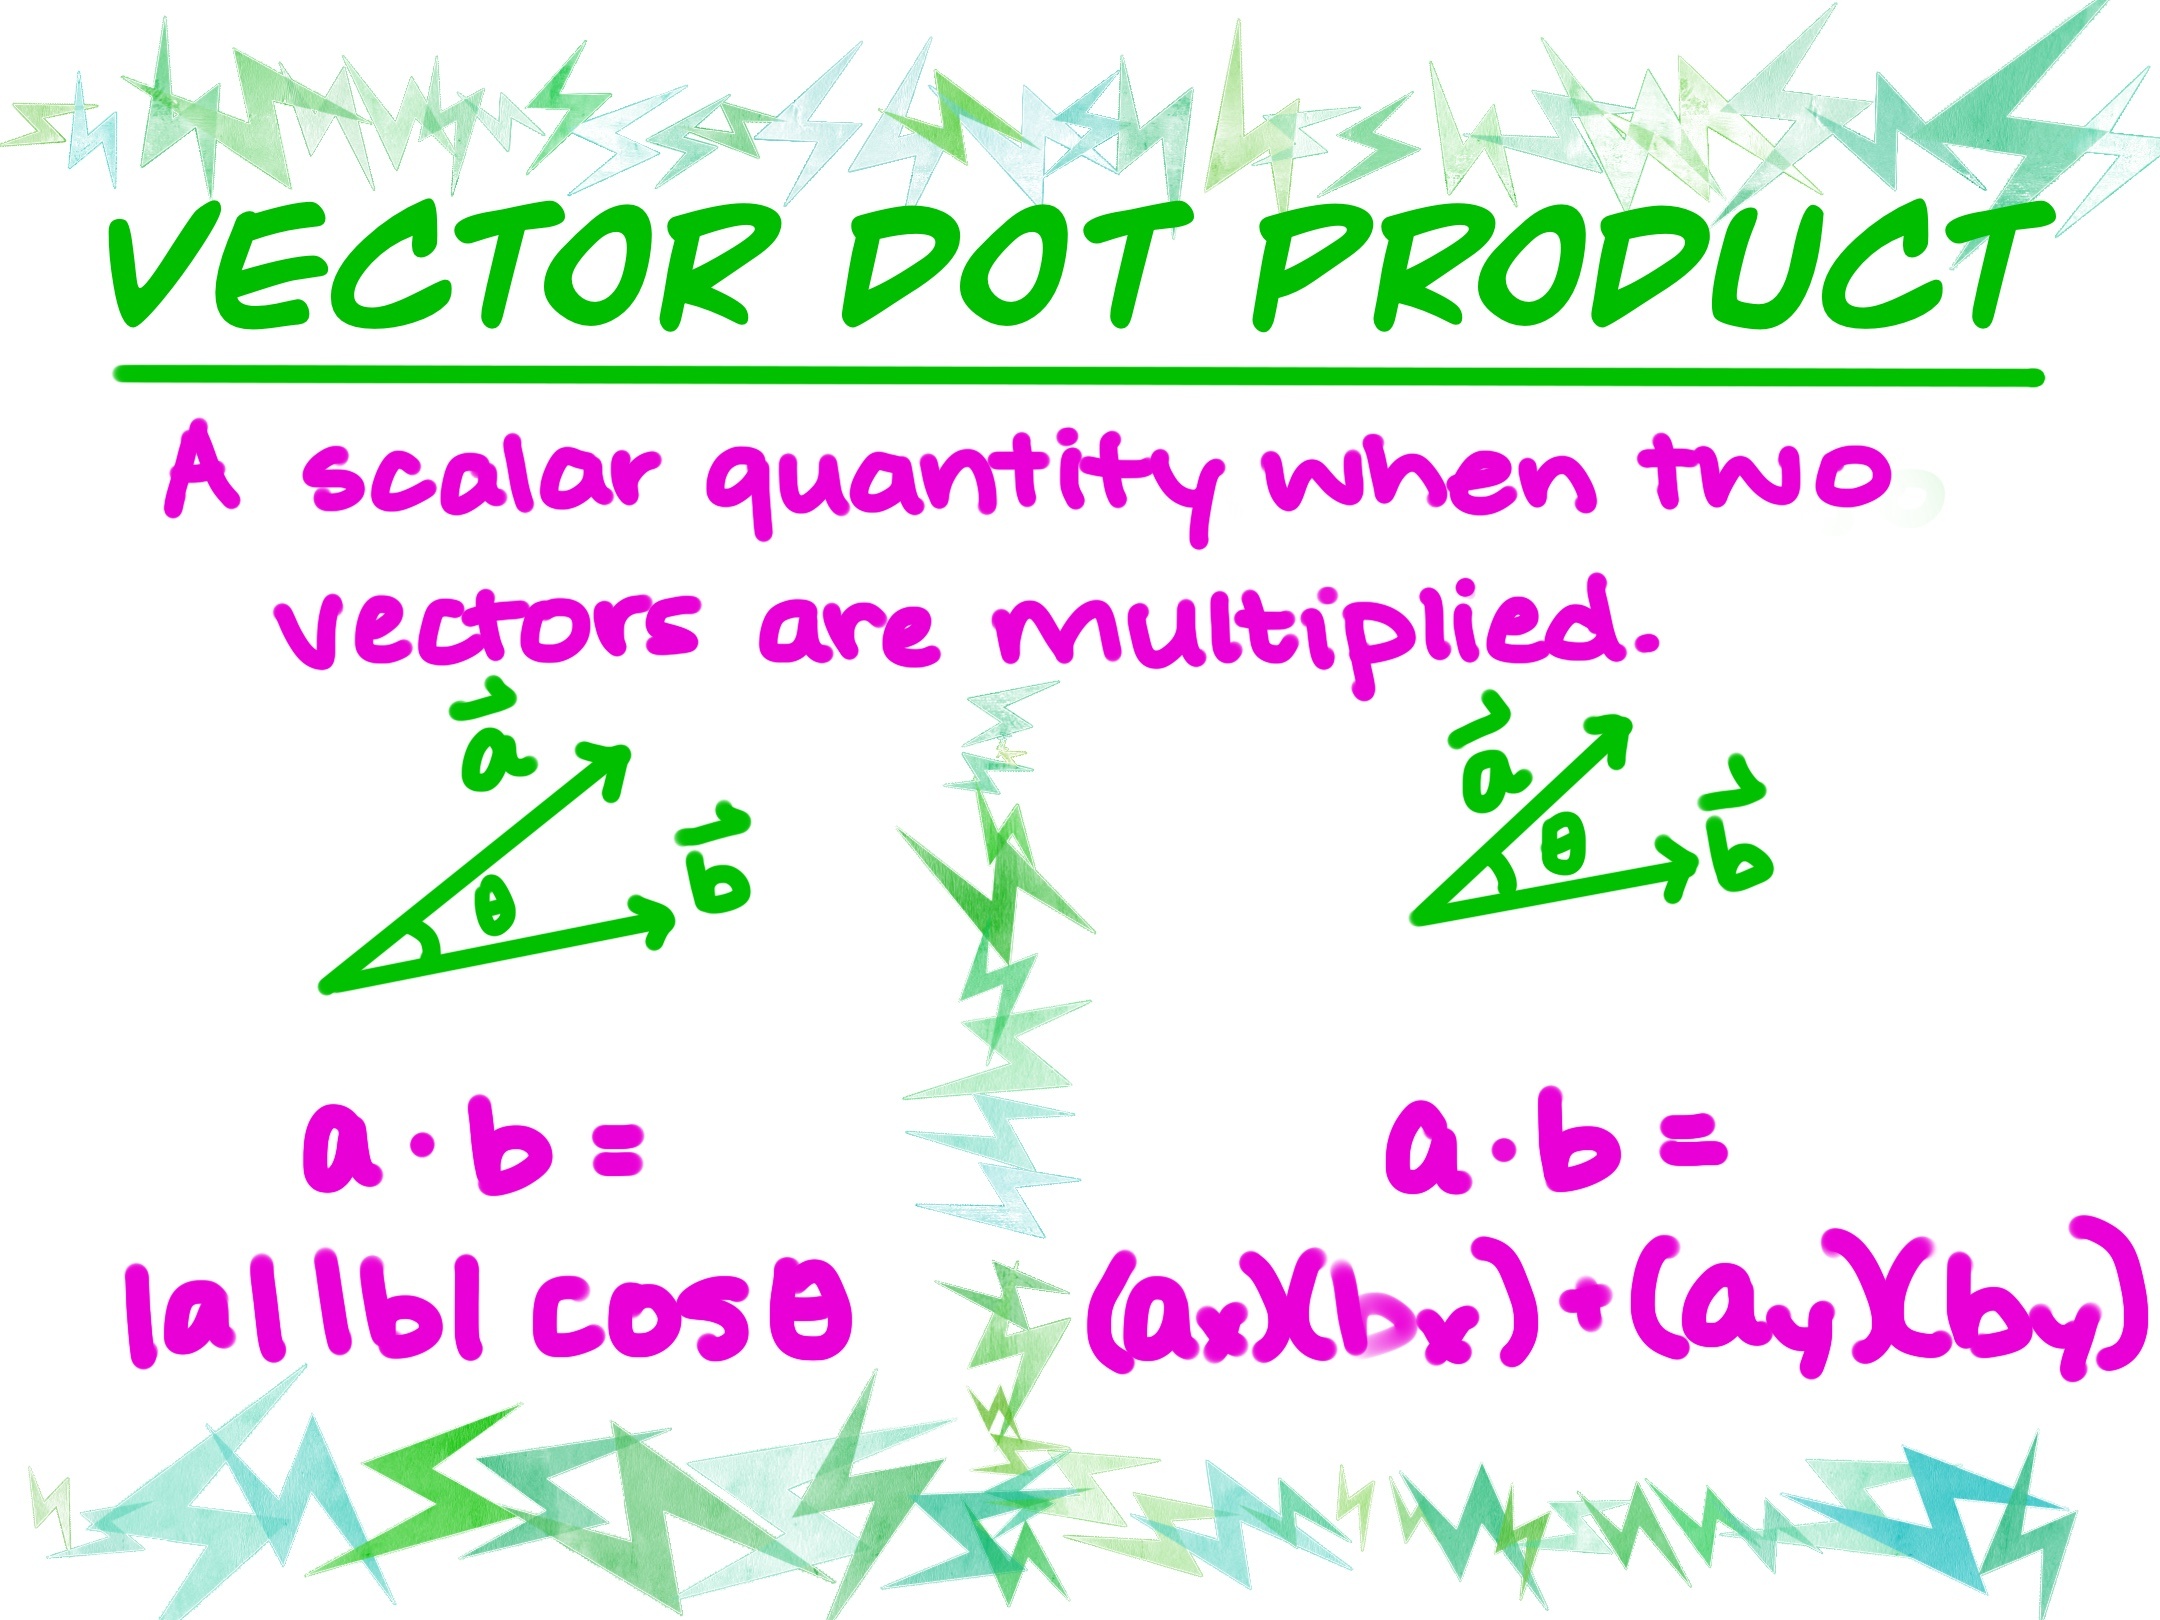
The geometric formula is abcos(), where is the angle between them. Rearranged: cos() = (a · b) / (|a||b|). That division by the magnitudes is why normalization matters. Skip it and you're measuring something completely different from what you think you're measuring.
Where It Actually Gets Used
I don't reach for the dot product often, but when I do, it's usually for one of three things: checking if two directions overlap, projecting one vector onto another, or determining whether a point is on a particular side of a plane. In graphics and simulation work, the plane check is where it shows up most. Given a plane defined by its normal vector n and a point p on the plane, you can determine which side any other point q sits on by computing (q - p) · n. Positive result means one side, negative means the other, zero means it's on the plane itself. This is how visibility checks, clipping, and backface culling all work under the hood. For projections, the dot product gives you the scalar component of one vector along another. The actual projected vector is that scalar times the unit vector in the target direction. So proj_a_on_b = (a · b) × b where b is b normalized. This comes up constantly in physics simulations when you need to decompose forces or velocities.
A Specific Problem I Faced
Early in a physics project, I was using the dot product to determine whether two rigid bodies were approaching or separating along a contact normal. The theory says: if the relative velocity dotted with the contact normal is negative, the bodies are moving toward each other and a collision response is needed. If it's positive, they're separating and you skip the impulse calculation. I hit a wall where the collision system was occasionally firing response forces even when objects were clearly moving apart. The culprit was floating point drift in the relative velocity vector. When the true dot product should have been exactly zero—objects sliding perfectly parallel to the contact plane—the computed value would oscillate between tiny positive and tiny negative numbers due to accumulated rounding error. This caused the collision system to treat near-zero values as meaningful separation checks, toggling back and forth every frame. The fix was simple: introduce a dead zone threshold. If |dot_product(relative_velocity, contact_normal)|
epsilon, treat it as zero regardless of sign. I used epsilon = 1e-6 for the specific precision of my velocity representation. Once applied, the glitch stopped entirely. No additional complexity in the impulse solver, no change to the math, just a guard rail around the edge case. I wish someone had mentioned this during the initial implementation. It cost me about three hours of debugging.
Common Pitfalls That Waste Time
Not normalizing before comparing direction. This is the most frequent mistake. Two vectors at the same angle but with different lengths will produce different dot products. If you're using the dot product to compare alignment across different scenarios, normalize both vectors first. Otherwise you're comparing magnitude-weighted alignment, not pure direction. Assuming the dot product is commutative for all purposes. It is mathematically commutative—order doesn't matter—but in practice, the interpretation depends on which vector you treat as the reference. When projecting, a · b gives you the projection of a onto b. The result has the same magnitude either way, but the geometric meaning shifts based on context. Be explicit about which vector is being projected. Mixing up dot product with cross product in 3D. The dot product returns a scalar. The cross product returns a vector perpendicular to both inputs. If your function name or comment says "dot" but you're getting a vector out, check the implementation. Conversely, if you need an angle between vectors and get a vector result instead of a scalar, you've computed the wrong operation. I've seen this error in code reviews more often than I'd like to admit.
Advanced Nuance: The Sign Problem With Nearly Parallel Vectors
When two vectors are nearly parallel, the dot product approaches the product of their magnitudes. When they're nearly anti-parallel, it approaches the negative of that product. Near these extremes, floating point precision becomes problematic. Computing the angle via arccos becomes unstable because the derivative of arccos approaches infinity as the input approaches ±1. Small errors in the dot product value produce disproportionately large errors in the computed angle. If you need accurate angles near 0° or 180°, use the atan2 formulation instead: = atan2(|a × b|, a · b). The cross product magnitude gives you the sine component and the dot product gives you the cosine component. This avoids the arccos instability entirely. For 2D vectors, the cross product magnitude simplifies to |ab - ab|, so no actual 3D cross product computation is needed.

Limits Of The Approach
The dot product only works with vectors in the same vector space and of equal dimension. You can't dot a 2D vector against a 3D vector without padding or projecting one into the other's space first. This seems obvious but pops up in pipeline code where dimensions get silently dropped or expanded at different stages. It's also insensitive to rotation in the subspace orthogonal to both vectors. Two vectors can have the same dot product with a third vector while pointing in completely different directions within that orthogonal plane. The dot product compresses a lot of geometric information into one number, and you lose everything except the component of alignment along the line connecting them. If your problem requires preserving angular relationships in higher dimensions, the dot product alone won't carry that information. For high-dimensional data—think machine learning feature vectors with thousands of dimensions—the dot product becomes less discriminative. The concentration of measure phenomenon means that in very high dimensions, most random vector pairs become nearly orthogonal. The dot product values cluster tightly around zero regardless of whether the vectors are actually related. In those cases, cosine similarity or learned distance metrics tend to perform better. The dot product isn't wrong, it's just losing signal to noise.
Practical Implementation Tips
Vectorize the operation if you're working with batches. Instead of looping through individual vector pairs, use matrix operations. NumPy's np.dot or np.einsum handles this efficiently and the speed difference is usually measured in orders of magnitude rather than percentages when you're processing thousands of pairs. Always validate input dimensions before computation. A runtime error from a dimension mismatch is far cheaper than a silently wrong result that propagates through your system. I keep a single assertion at the top of my dot product utility: assert len(a) == len(b), "Vectors must have equal dimension". Five characters of failure mode visibility for the cost of one line. Store unit vectors separately when you compute them frequently. If you're normalizing the same vector repeatedly inside a loop, precompute and cache the normalized version. The square root operation in normalization is relatively expensive compared to the multiplications in the dot product itself. For tight loops running millions of iterations, this distinction matters.