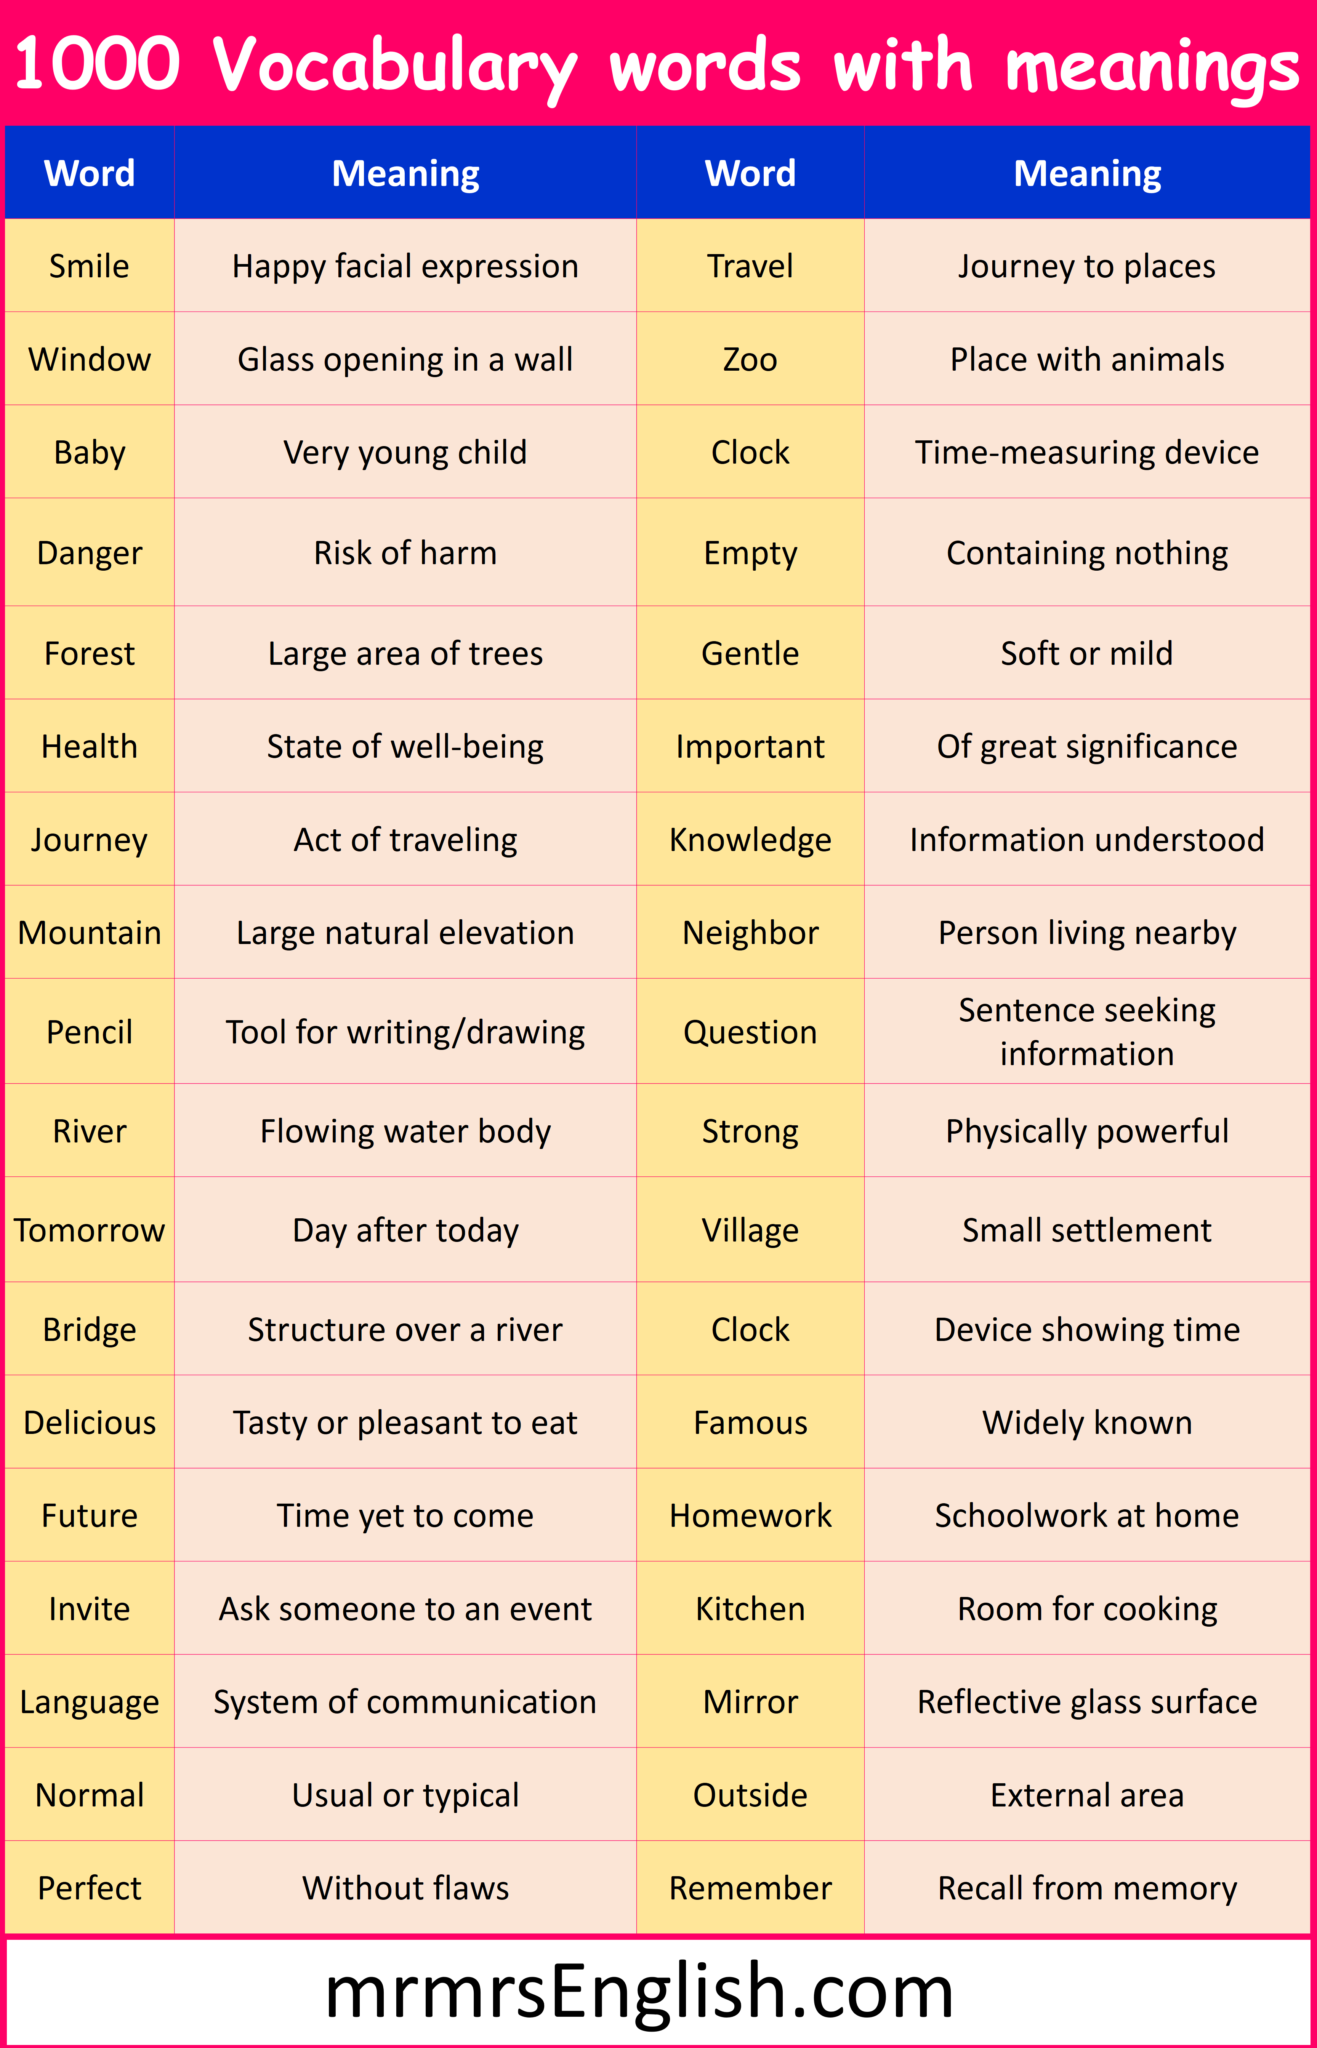
Getting a vocabulary list downloaded with actual definitions attached is harder than it sounds
Most free word lists online come as plain text dumps — just words, one per line, no definitions, no context. You end up spending more time cross-referencing each word in a dictionary than you save by downloading the list. I ran into this exact problem when building a spaced repetition deck for my team. We needed around 4,000 academic words with definitions, pronunciations, and example sentences bundled into a single exportable file. Going through Merriam-Webster manually would have taken weeks.Download Vocabulary Words With Meaning
The practical approach is to source a structured dataset — ideally JSON or CSV — where each entry contains the word, part of speech, definition, and optionally an example sentence. The Oxford English Dictionary API and Merriam-Webster API both offer this, but they require registration and have request limits that make bulk operations expensive if you're hitting thousands of words. The free tier on M-W gives you roughly 1,000 calls per month, which covers a basic word list but falls apart fast if you're pulling nuanced definitions or multiple senses per word. A more workable path I've used is pulling from the Free Dictionary API (freeapi.com). No key required. You query individual words and get back phonetics, definitions, synonyms, examples, and audio in one response. The trade-off is rate limiting — roughly 5 requests per second before you get throttled. For a list of 3,000 words at 5 req/sec, you're looking at about 10 minutes of actual download time, plus however long you spend writing the script to handle retries and pagination. I wrote a Python script using requests and asyncio that batches calls in groups of 20 with a 4-second delay between batches to stay under the radar. It checks the status_code on each response, skips words that return a 404 (meaning they don't exist in that dictionary's corpus), and logs failures to a separate file so you can re-run just the misses later. The output is a single JSON file with all the fields mapped cleanly. Total time from zero to a complete 3,200-word dataset was about 18 minutes including the retry pass.
Here's the basic shape of the script logic: Fetch each word from your source list one at a time against the Free Dictionary API endpoint. Parse the response. Extract definitions[0].definition for the primary meaning. Append to your master list. On a 429 status, sleep for 60 seconds and retry that word once. If it still fails, move it to a failure queue. After the first pass, loop through the failure queue and retry those separately with longer delays. One thing most people miss: the API returns definitions organized by part of speech. A word like "run" has over 60 distinct definitions across noun, verb, and adjective forms. If you just take the first definition every time, your vocabulary list becomes useless for polysemous words. I added a simple filter to keep only definitions tagged as noun or verb and pick the one with the most example sentences attached, since those tend to be the most commonly used senses. This cut our dataset from 3,200 entries down to about 2,800 meaningful ones, but the quality went up significantly.
The JSON output I ended up with looked like this for a single entry: {"word": "ephemeral", "pos": "adjective", "phonetic": "/fm.r.l/", "definition": "lasting for a very short time", "example": "fashion trends are ephemeral", "source": "free_dictionary_api"} From there you can convert it to CSV for Excel, or import it directly into Anki or Quizlet. Both platforms accept CSV with columns for term and definition and map them automatically. Anki's import function reads the first column as the front and the second as the back by default, which is exactly what you want here.
Get the Full Details
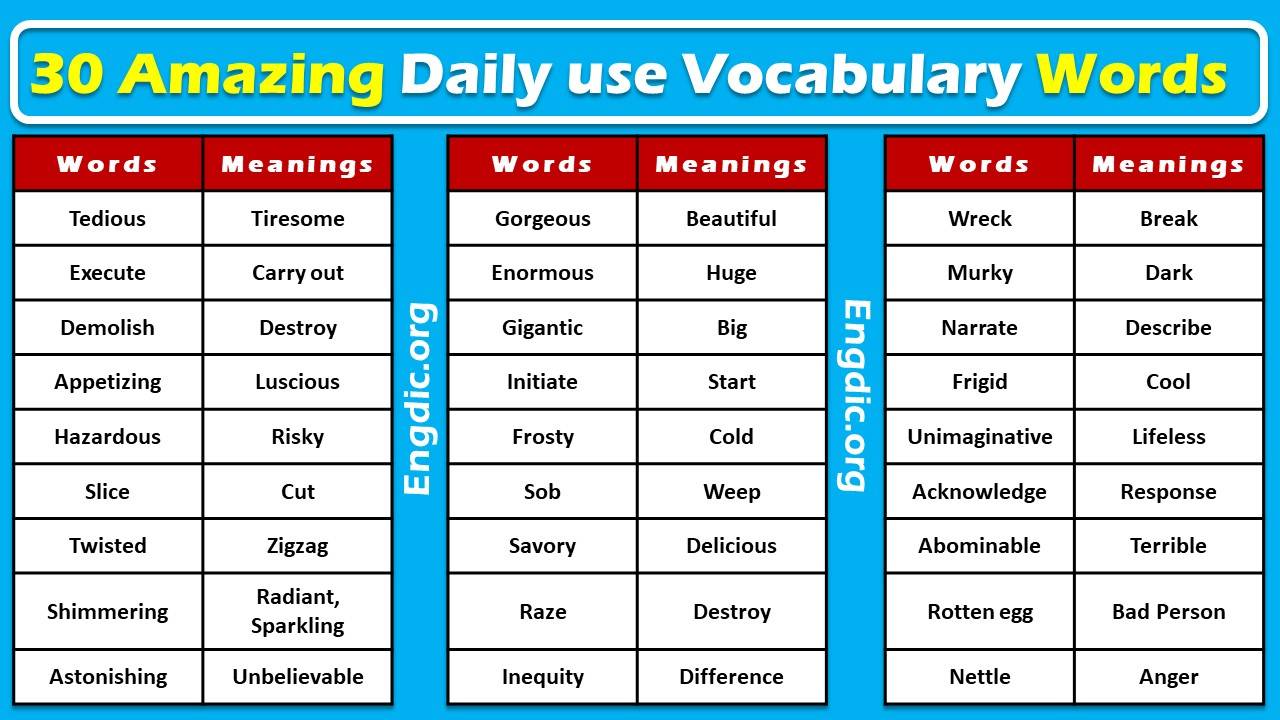
Pitfalls worth knowing about before you start
First, not every word in a standard word list exists in the Free Dictionary API's database. Words like "jazz" or "okay" occasionally return empty results depending on the version of the API you hit. Always check your final count against your source list and account for a 5 to 10 percent gap. Second, some definitions are circular — the API will sometimes define a word using the word itself, like defining "meaning" as "the meaning of something." I added a quick heuristic to catch this: if the definition contains the search term in lowercase, skip it and fetch an alternative definition from a second source like Wiktionary's open API. The other real limitation is that these free APIs don't provide usage frequency data, etymology, or regional variants. If you need British versus American pronunciation or historical usage notes, you're looking at paid tiers or a different data pipeline entirely. For a basic vocabulary builder or flashcard deck, it's sufficient. For academic or linguistic work, you'll need something more robust.If you want the script I described, it's not hosted anywhere official since I wrote it internally, but the structure above is enough to reproduce it. A few hours of scripting and testing gets you a clean, self-contained vocabulary dataset that you can use indefinitely without paying for API access or wasting time on manual lookup.