What you actually need to know before you start studying for the data engineering exam
The Microsoft DP-203 certification is called Data Engineering on Azure, and it covers designing and implementing data storage, processing, and security solutions on the Azure platform. The exam is a practical one. You will see scenario questions about when to use Azure Data Lake Storage over Cosmos DB, how to set up a lambda architecture in Synapse, why your Data Factory pipeline keeps hitting timeout limits at 3 AM, and whether you should use a U-SQL script or a Spark job for a particular transformation. It is not a trivia test. You need to understand tradeoffs. I spent about six weeks preparing for this. Most people I know spend between four and eight. It depends on your baseline. If you already work with Azure Data Factory, Databricks, and Synapse on a daily basis, you can probably get there in four weeks with focused effort. If you are coming from a different cloud or on-prem background, plan for the full eight weeks.
Dp 203 Exam Prep resources that actually helped me
The official Microsoft Learn path is free and covers every domain listed in the exam guide. It is dry, but it is accurate. I worked through it twice. The first pass was fast. I skimmed things I thought I knew. The second pass I did slowly, because that is where I found the gaps. The lab exercises on Learn are useful. They are simple but they force you to actually click through the portal instead of just reading about it. For practice exams, Whizlabs and Tutorials Dojo both have solid question banks. I used Whizlabs for breadth and Tutorials Dojo for depth. The Tutorials Dojo explanations are the ones that matter most. They do not just tell you the right answer. They explain why the other three options are wrong, and sometimes they point out that two answers look correct but one is slightly better depending on the wording of the scenario. That second distinction is exactly what this exam tests. I also used GitHub repositories that contain sample code for Data Factory pipelines, Databricks notebooks, and Synapse SQL scripts. Having real code in front of you while you study makes a difference compared to reading abstract descriptions. The difference is small but it adds up over six weeks of studying.
The domains and what they actually mean in practice
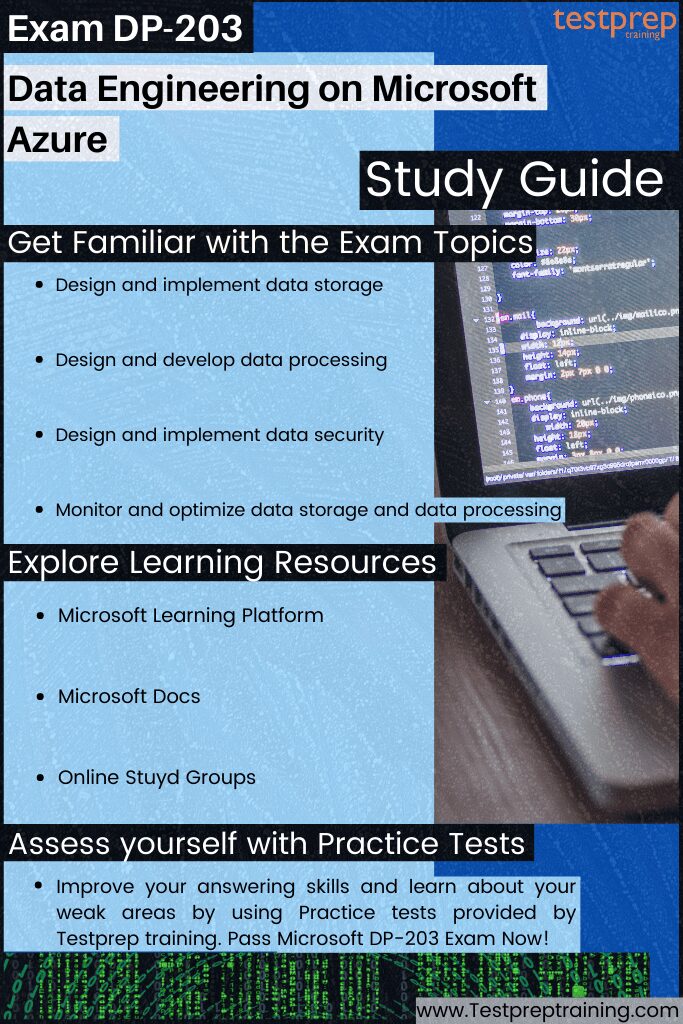
The exam has four main domains. Data Storage is roughly 25 to 30 percent. This means you need to know Azure Data Lake Storage Gen2, Cosmos DB, Azure SQL Database, and SQL Server on Azure VMs well enough to pick the right one when someone gives you a scenario about latency requirements, consistency needs, and cost constraints. I learned this the hard way during a real project. A team wanted to use Cosmos DB for everything because it is flexible. It turned out the billing for our query patterns was three times higher than if we had used a properly indexed Azure SQL database. The exam questions are built around mistakes like that. Data Processing is about 25 to 30 percent. This is where Azure Data Factory, Databricks, Azure Stream Analytics, and Synapse Pipelines come in. You need to understand when to use a pipeline trigger versus a schedule, how to handle incremental loads, and what the performance characteristics of Spark versus dedicated SQL pools look like under real workloads. One thing most people miss is that incremental copy in Data Factory is not the same as incremental load in a transformation step. Copy activity only moves new or changed files. If you need to update rows inside a table based on a key, you have to write that logic yourself in a notebook or a stored procedure. I confused these two concepts early in my prep and got several questions wrong on practice exams because of it. Data Modeling is 20 to 25 percent. Dimensional modeling, star schemas, partitioning strategies, and indexing. This domain is heavier on theory than the others. You need to know what a slowly changing dimension is, how to handle it, and when a snowflake schema makes more sense than a star schema. It is rare in the wild to see snowflake schemas used correctly, but the exam asks about them. Be ready.
Get the Full Details

Monitoring, Security, and Governance is 15 to 20 percent. This covers Azure Monitor, Log Analytics, private links, managed identities, Role-Based Access Control, and Purview. I found this section the most annoying to study because the details are scattered across multiple services. The best approach is to go through each service's documentation and write down what it does, who it is for, and what it replaces. You will notice overlaps everywhere. Managed identities replace connection string secrets. Private links replace public endpoints. Purview replaces manual lineage tracking. Understanding what replaced what helps you answer questions faster.
A specific problem I ran into and how I worked around it
During my second practice exam I kept getting questions about Databricks cluster policies wrong. Not because I did not understand what they were, but because I was mixing up workspace-level policies with account-level policies. The exam can switch between those two levels in the same question set and it changes which settings are available. I spent an entire weekend building test clusters in a free Azure subscription to see the difference directly. I created a workspace policy that restricted instance types and a separate account policy that restricted cluster mode. Then I tried applying both and watched what happened. The conflict resolution behavior is exactly what you need to know for those questions. Another issue I hit was around Synapse serverless SQL pools versus dedicated SQL pools. The exam loves to put scenarios where you have a one-time query on a large dataset and you have to choose between the two. Serverless is cheaper for ad-hoc queries but it has cold start latency and no materialized views. Dedicated pools have upfront costs but better query performance for repeated workloads. I wrote a small comparison document with my own rough numbers from actual deployments, and that document ended up being one of the most useful things I studied from.
Counter-intuitive things about this exam that nobody mentions
First, the exam does not test whether you can set up a pipeline from scratch. It tests whether you can look at a broken or suboptimal setup and pick the fix. Many questions describe a scenario where something is already deployed and performing poorly, and you have to choose the single best improvement. This means you need to think in terms of root cause, not best practice lists. "Use Spark instead of Data Flows" is not always the right answer. Sometimes the right answer is "add a partition key to the Cosmos DB container" or "enable auto-scaling on the Synapse pool." The questions punish surface-level knowledge. Second, the wording matters a lot. Words like "always," "never," and "only" are almost always wrong in the answer choices. Azure is too flexible for absolute statements. The correct answers tend to be qualified. "Use Azure Data Lake Storage Gen2 when you need hierarchical namespaces and POSIX-like permissions" is the kind of answer you will see. It is specific without being absolute. When you are taking the exam, read every qualifier in both the question and the answers carefully. I lost points on three questions because I skimmed past the word "only" in an answer choice. Third, the free tier of Azure is not sufficient for this exam. You need a paid subscription or a trial that gives you access to Synapse dedicated SQL pools, Databricks, and full Data Factory features. Some of the lab scenarios reference features that simply do not exist in free tiers. If you are studying on a free account, you will hit walls. I upgraded to a pay-as-you-go subscription and it made the difference between understanding something and just reading about it.

What this approach does not cover
This method assumes you can dedicate consistent time to studying. If you are working full-time and can only study an hour a day, the timeline stretches. The content does not get easier. You will also find that some topics like Purview integration with Data Factory pipelines are relatively new and the exam questions around them may change as Microsoft updates the test. I have seen version differences between practice exams and the actual test in recent months. The core concepts stay the same but the scenario flavors shift slightly. Being comfortable with the fundamentals matters more than memorizing any single question bank. There is no shortcut here. The exam is what it is. It is a broad, scenario-based assessment of your ability to make architectural decisions on Azure data services. The people who pass are the ones who have touched each service, broken something, fixed it, and understood why the fix worked. The people who fail are usually the ones who memorized feature lists without understanding tradeoffs. Spend your time building and breaking. Read the documentation after you have a hands-on context for the topic. That pairing is what makes the knowledge stick.