What the DP-203 Actually Tests Now
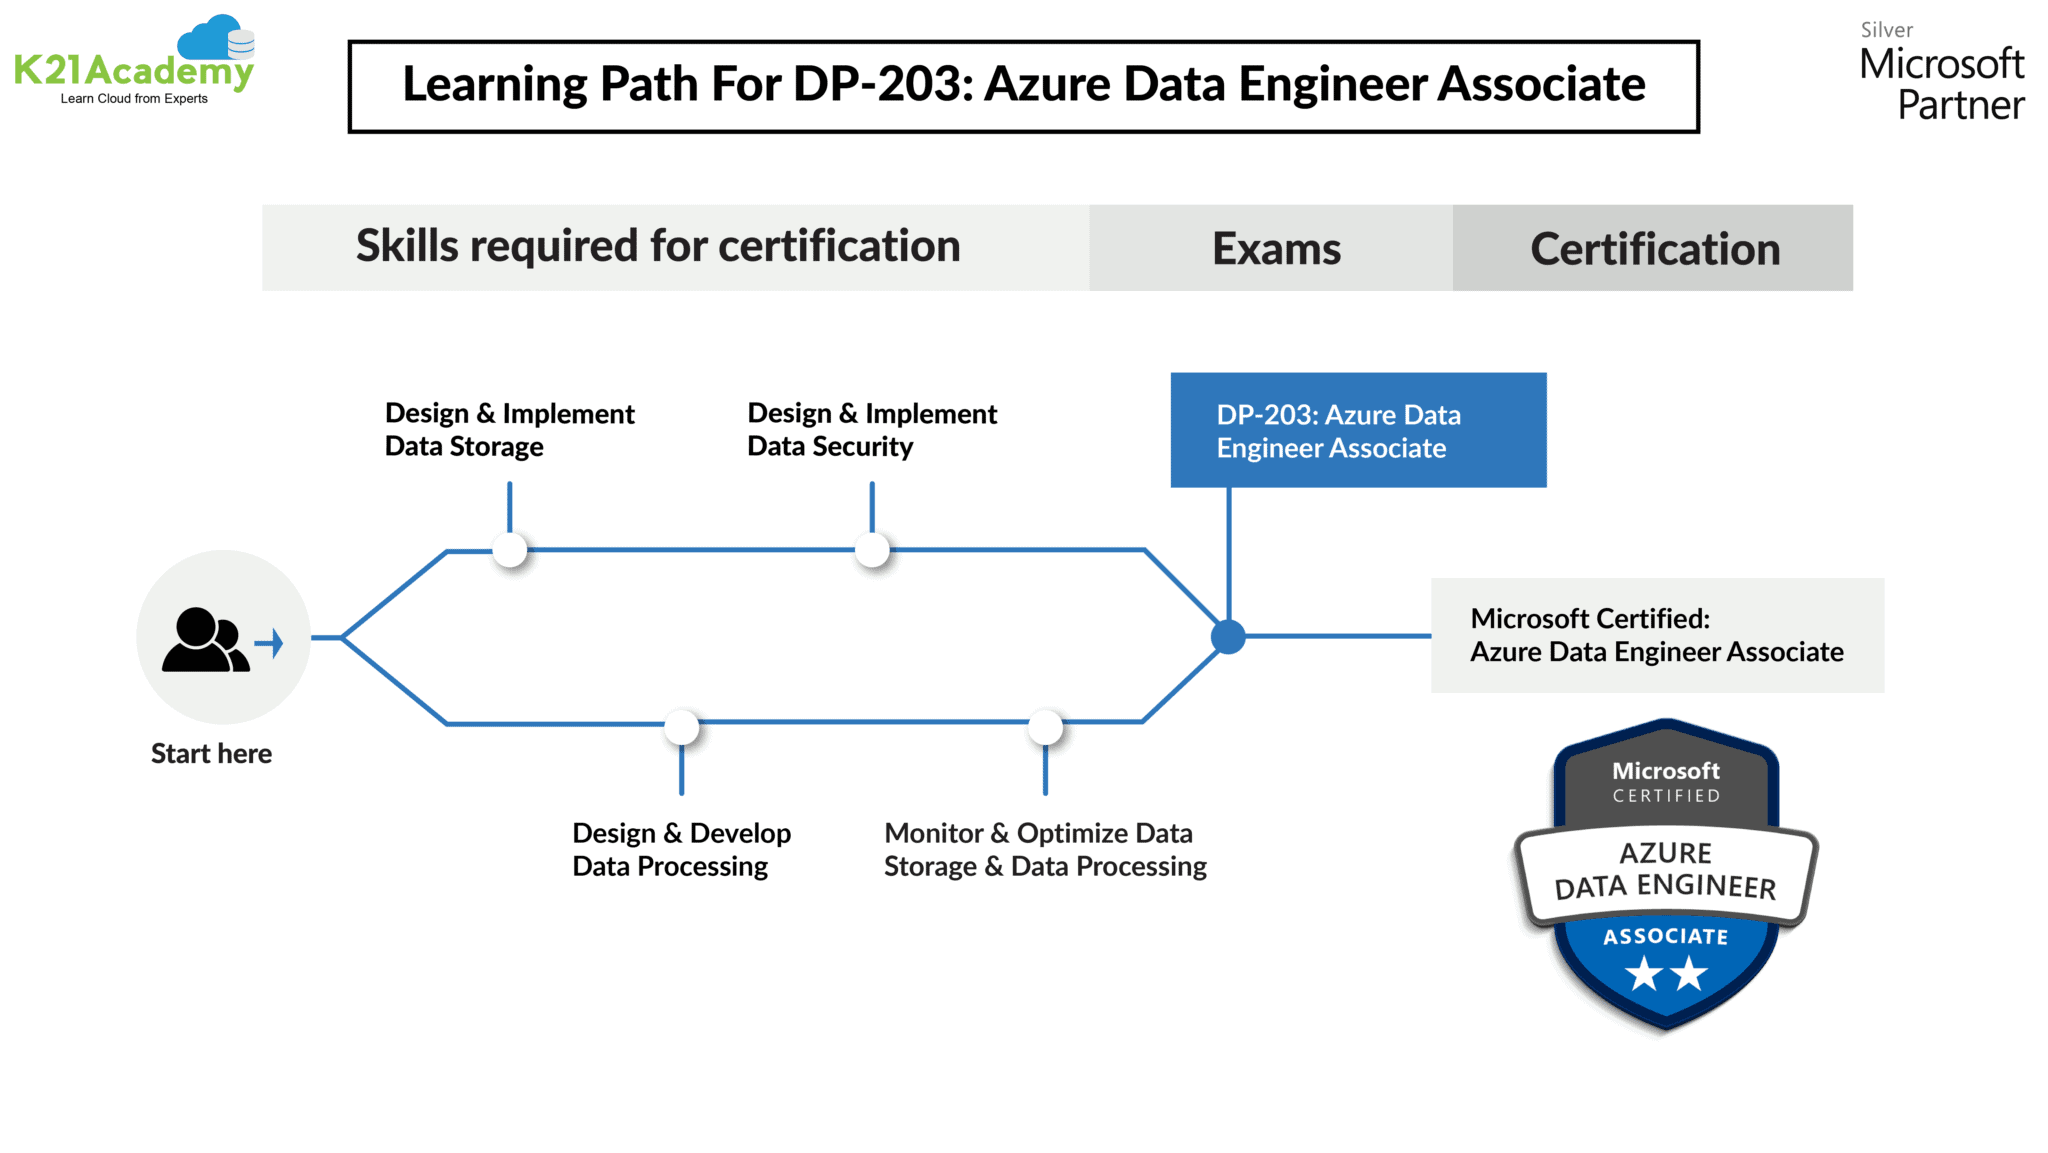
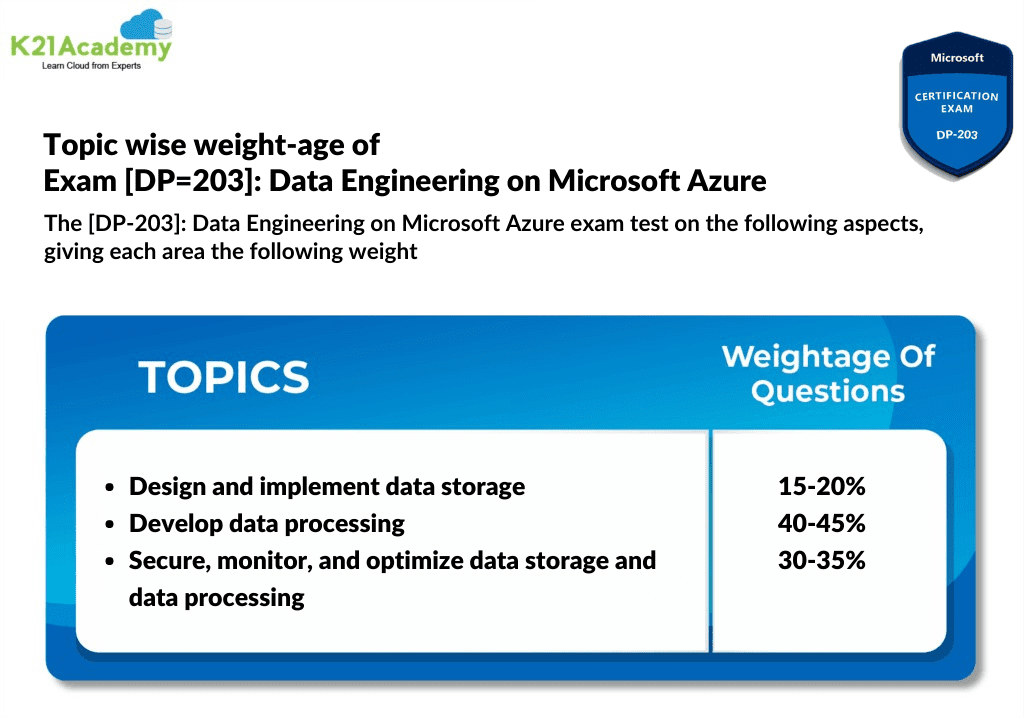
The Microsoft Data Engineering Associate exam has shifted noticeably since the last revision. It used to be heavy on SSIS packages and on-prem SQL Server scenarios. Now it is almost entirely Azure-native, with a strong emphasis on Synapse, Databricks, and the newer Azure Data Factory orchestration features. If you are studying from a book that still talks about BIDS or 2016 SQL Server Integration Services, close it immediately. The questions will not match your material. The current exam splits into four main domains, and the weightings matter more than most people realize. The largest section covers data storage, which accounts for 30–35 percent of the test. This means you need genuine working knowledge of how to choose between Azure SQL Database, Azure Synapse SQL pools, Azure Cosmos DB, and Azure Data Lake Storage Gen2. It is not enough to know what each service does. You need to know which one fails under specific query patterns and what the cost implications are. Data transformation and processing makes up roughly 30 to 35 percent as well. This is where most candidates lose points. The exam expects you to write PySpark code, manipulate DataFrames, and understand when to use Azure Synapse Serverless SQL versus dedicated SQL pools. I once took a practice exam where a question asked me to optimize a PySpark join between a small dimension table and a large fact table. The correct answer was broadcast join, but three of the distractors were cache(), repartition(), and coalesce(). The question did not explicitly state the size of the tables in GB. You had to infer it from the phrasing. That is the level of ambiguity you will face.
The monitoring, optimization, and governance section is about 20 to 25 percent. This area tests your knowledge of Azure Monitor alerts, Log Analytics workspaces, Azure Data Factory monitoring pane, and Purview integration. The practical reality here is that most engineers I talk to have never actually configured a Purview scan policy in production. The exam assumes you have. Learning path for this is to spin up a free Azure account and manually walk through the setup, rather than watching a video. The final domain, about 15 to 20 percent, deals with solution operation and infrastructure. This covers infrastructure as code, ARM templates, Bicep files, and pipeline deployment strategies. I found this section surprisingly hands-on in recent versions of the exam. There are performance tuning questions where you need to identify that a pipeline is slow because of schema drift handling, not because of data volume. The actual workaround I used in a real project involved disabling automatic schema detection on the Copy Data activity and setting it to manual, which cut our pipeline runtime from about 40 minutes down to roughly 6 minutes for a 50 GB daily load.
How to Actually Prepare Without Wasting Months
The single most effective resource is the official Microsoft Learn path for DP-203. It is free and it maps directly to the exam objectives. Do not skip the hands-on labs. I see people reading through the documentation passively and then getting confused when the exam asks them to configure something in a portal screenshot. The exam uses scenario-based multiple choice, sometimes with multiple correct answers. You need to have touched the UI. For hands-on practice, build a small end-to-end pipeline. Create a Data Lake Storage Gen2 container, load a CSV file into it using Azure Data Factory, write a PySpark notebook in Synapse to transform the data, and then sink it into a dedicated SQL pool. If you can do that without following a tutorial step by step, you are in decent shape. The moment you get stuck on something like configuring CORS settings on your storage account or dealing with credential management through Key Vault, spend time there. Those are the exact details the exam drills. Practice exams are useful but most of the third-party ones are outdated. Look for ones that specifically mention Synapse serverless pools, Delta Lake, and Databricks Workflows. If a practice question still references HDInsight Spark clusters as the primary compute option, it is probably old. The exam has moved toward serverless and managed options.
Get the Full Details
Common Mistakes That Cost People the Exam
The biggest issue I see is overconfidence in Azure Data Factory. Many candidates who come from an on-prem ETL background treat ADF like SSIS. The mental model is completely different. ADF is orchestration-first. The actual data movement and transformation logic lives in linked services and activities, not in a monolithic package. You will see questions asking about pipeline parameter scoping, copy activity buffer settings, and integration runtime selection. Understanding when to use a self-hosted IR versus a managed one is a classic exam topic. Another trap is the Cosmos DB section. Candidates either ignore it completely or assume it works exactly like a regular database. It does not. The exam frequently tests partition key selection strategies and consistency level tradeoffs. If a question describes a financial reporting workload that requires strong consistency, the answer will not be eventual consistency no matter how much faster it sounds. The performance difference between_consistent_prefix_, _bounded_staleness_, and _strong_ in Cosmos DB is significant and the exam expects you to know the exact guarantees of each. I also noticed a recurring pattern where people miss the Delta Lake questions. The exam tests your knowledge of time travel, merge operations, and Z-ordering. I ran into this in a real project where a Databricks notebook was rewriting the same Delta table every hour without proper merge logic, causing snapshot bloat. The fix was implementing an MERGE INTO statement instead of a full overwrite, which reduced our compute cost by about 60 percent. Questions like this appear on the exam in disguised forms.
Final Practical Notes
Do not study more than two to three weeks unless you are already deep in the Azure ecosystem. If you have been working with Synapse or Databricks daily, one focused week of targeted review is enough. If you are coming from a purely on-prem SQL background, budget three weeks minimum and prioritize the transformation and storage domains. The exam itself is about two hours. There are 40 to 50 questions. Some are case studies, which means you get a longer scenario and multiple questions based on it. These are the ones that take the most time. I would suggest doing the case studies first while your brain is fresh, then moving on to the shorter standalone questions. The timer does not pause between sections, so pacing matters. There is no penalty for wrong answers, so never leave a question blank. Guess strategically if you need to eliminate one or two options first. The scoring is not linear either. A single poorly understood domain can bring your score down more than you expect, so identify your weakest area before the exam date and spend extra time there.