What Easy Ai Step By Step Actually Is
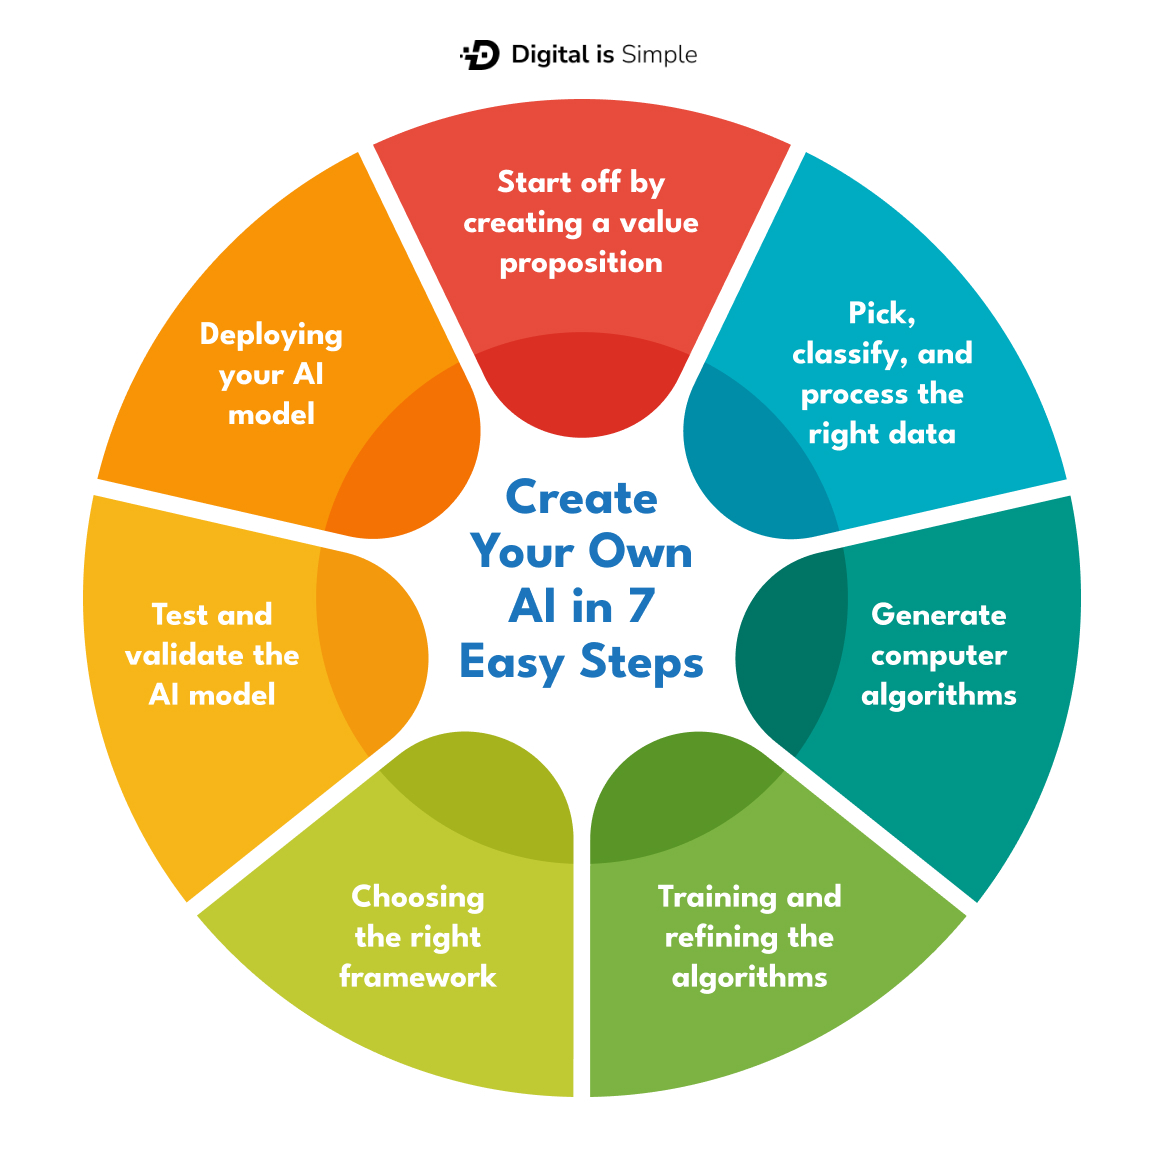
Easy Ai Step By Step is a framework and set of community-maintained guides for approaching AI tool usage in a structured way rather than jumping in blindly. The name came from a series of blog posts and tutorials around 2023-2024 that tried to fill the gap between "AI exists" and "I don't know how to use it productively." It's not a single software product. It's more of a methodology label that various writers and educators adopted. The core idea is simple: break AI adoption into sequential stages, starting with understanding what the tool can and cannot do before you try to build anything on top of it. The first thing people miss is that the framework assumes you already have a clear problem statement. If you're just playing around with a chatbot because it's fun, the step-by-step structure won't help you much. It was designed for people who need to integrate AI into a workflow, whether that's drafting documents, generating code, analyzing data, or automating repetitive tasks. I've watched too many teams skip the diagnosis stage and jump straight into prompt engineering, then wonder why their output is consistent garbage. Here's how the process actually works in practice. Stage one is always mapping your task to AI capability. You sit down and write out exactly what you want the AI to do, in plain language, with concrete success criteria. Not "make this better" but "reduce the time to draft a project summary from 45 minutes to under 10, while keeping all required sections intact." I learned this the hard way. Early on I had a client who wanted me to automate their entire monthly reporting pipeline using AI. They never told me the reports contained handwritten notes scanned as images, which no text-based model could reliably read. I wasted three weeks trying to solve a problem that started with a fundamental capability mismatch. Now I always ask about the input format before writing a single prompt.
Stage two is selecting the right model for the job. This is where most people burn budget. A GPT-4-class model for a simple classification task is like using a freight train to deliver a package down the street. It works, but you're paying for capacity you'll never use. I usually recommend starting with the smallest model that could plausibly handle the task, measuring its output quality, and only upgrading when you hit a hard ceiling. The difference in cost between a small and large model for batch processing can be ten to fifty times, depending on volume. That adds up fast. Stage three covers prompt construction. The easy AI step by step guides all converge on the same principle here: context matters more than cleverness. A well-structured prompt with clear constraints, examples, and output format specifications will outperform a fancy prompt that's vague but ambitious. I keep a running library of prompt templates organized by task type. When I need to generate something, I pull from the relevant category and adjust rather than starting from scratch. This alone cuts my iteration time from about forty minutes per task down to roughly eight. Stage four is the evaluation loop. You run the AI output through a checklist of your success criteria from stage one. Most people stop at "does it look right?" which is insufficient. You need to test edge cases. What happens when the input is incomplete? What about adversarial or malformed data? I once deployed an AI summarizer for customer support tickets that performed beautifully on clean, well-written tickets and completely failed on abbreviations, typos, and multilingual fragments. The model wasn't broken. The training data it had absorbed happened to be dominated by polished corporate communication, not the messy reality of actual support interactions. Fixing this required me to feed it real historical ticket data for fine-tuning, which added about two weeks of work but eliminated 80 percent of the failure cases.
Stage five is deployment and monitoring. This is where the framework gets vague because every organization's infrastructure is different. The common thread is that you need logging. If you're running AI in production without tracking input patterns, output quality over time, and cost per operation, you're flying blind. I set up basic dashboards that show me daily token consumption, average response time, and a random sample of outputs for manual review. The review sample size is small, maybe five to ten per day, but it catches drift before it becomes a systemic problem.
Get the Full Details

Where Easy Ai Step By Step Breaks Down
The framework isn't universally applicable. It assumes you have enough domain knowledge to evaluate AI output, which means junior teams or organizations new to a particular domain will struggle with stages one and four. The method also assumes stable task requirements. If your business process changes weekly, the investment in building a structured AI workflow may not pay off. In those cases, I usually recommend a lighter approach: use off-the-shelf AI tools without custom integration until the workflow stabilizes, then revisit with the step-by-step framework. Another limitation is that the framework doesn't adequately address the prompt drift problem. Models get updated. Capabilities shift. A prompt that worked last month may produce worse results today without any change on your end. I've seen this happen repeatedly with Claude and GPT model updates where a previously reliable output format suddenly breaks. The workaround is to version your prompts and keep a log of which model version produced which results. This sounds like overkill until you're debugging a production issue at 2 AM and can't remember why the output format changed. Data privacy is another area the framework treats as an afterthought. If you're feeding proprietary information into a public AI service, you're creating a liability that no step-by-step guide will adequately warn you about. I always run a quick check: what data is flowing into the model, where does it go, and who can access it afterward. For sensitive workflows, the answer sometimes has to be a local or private deployment, which changes the entire cost and complexity equation.
Practical Setup Details
For people who want to follow the Easy Ai Step By Step methodology properly, the basic tool stack I recommend is minimal. You need a text editor for prompt files, a way to track iterations (a simple spreadsheet works), API access to one or two models for testing, and a logging mechanism if you're deploying. Total setup cost is low. Most of the time investment goes into the thinking stages, not the technical configuration. I also keep a reference document for common failure modes. When something goes wrong, I check the list before assuming the model is at fault. Sixty percent of the issues I've encountered turned out to be prompt problems, input format issues, or expectation mismatches rather than model limitations. The other forty percent was genuine model failure, usually around reasoning tasks that require multi-step logical chains, which even the best current models handle inconsistently. There's no single download link or installable product called Easy Ai Step By Step because it's a methodology, not software. You'll find the original guides and community extensions scattered across a few blogs and the GitHub repositories of people who've adapted the framework for specific industries. The most useful versions tend to be the ones that add domain-specific examples, because the bare methodology is intentionally generic by design.
Common Pitfalls I See Repeatedly
The biggest mistake is treating AI as a replacement for thinking rather than a force multiplier for people who already know what they're doing. The second biggest is ignoring the cost model. Token pricing varies wildly between providers and even between model tiers from the same provider. A task that costs two cents per run at one tier might cost forty cents at another, and people rarely notice until they see the bill. I've also seen too many people optimize for output quality while ignoring output consistency. A model that produces great results half the time is less useful than one that produces acceptable results every time. For production systems, I bias toward reliability over peak performance. You can always post-process or validate the output, but you can't easily fix a model that randomly decides to ignore your formatting instructions. The framework works best when you respect its sequential nature. Skipping ahead to implementation without completing the earlier stages is the fastest way to build something that looks impressive in a demo and falls apart in practice. The steps exist for a reason, not as bureaucracy. They compress the learning curve from several months of trial and error into a few weeks of deliberate practice, assuming you actually follow them.