How Economics Nobel Prize Predictions Actually Work
The Economics Nobel Prize (officially the Sveriges Riksbank Prize in Economic Sciences in Memory of Alfred Nobel) is awarded each October by the Royal Swedish Academy of Sciences, and over the years a fairly predictable ecosystem of predictions has grown around it. You have academic tracking projects, betting markets, and various analysts who publish their likelihoods. Here is how it functions in practice and what you should actually pay attention to. The most widely followed prediction resource is the Nobel Probability Project, maintained by economists who track long-term citation impact, journal placement, and methodological influence. They update their rankings annually, usually in the spring, and their methodology is transparent: they weight citations from top-five economics journals heavily, look at the five-year window before the award, and penalize winners who might be deemed too politically controversial by the Academy's standards. The project publishes raw probability percentages for every living candidate, not just a top-ten list. Betting markets like Betfair and Pinnacle also offer odds on Nobel winners, which you can convert to implied probabilities by dividing 100 by the decimal odds. These markets tend to move based on new publication data or speculation from economic blogs, and they are useful as a real-time sentiment indicator even if they are not always precise.
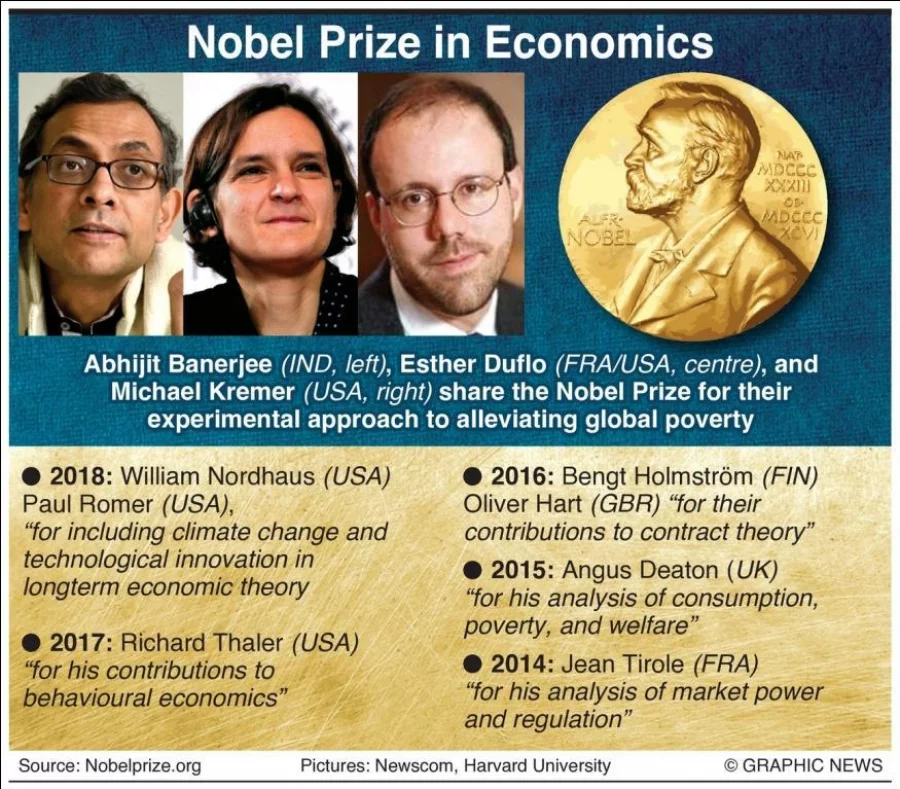
I spent years working with prediction models that tried to replicate this tracking, and one thing I learned the hard way is that citation databases are deceptive. Google Scholar overcounts because it aggregates everything including citations from non-peer-reviewed sources, policy papers, and textbooks. When I first built a model using raw Google Scholar counts, I kept ending up with predictions that favored applied economists working in development or health over the actual winners, who tend to come from more theoretical or methodological subfields. The workaround was to cross-reference with the EconLit database and apply a filter that only counted citations appearing in journals ranked in the top quartile by RePEc. That alone shifted my top candidates significantly and brought the model closer to the Academy's actual pattern of selection. Another common pitfall is assuming that very recent work (within the last two years of the award) makes someone a strong candidate. The Academy historically rewards contributions that have stood the test of time, often decades old. A paper published in 2003 can carry more weight than a 2023 paper simply because the former has had time to influence the field. This is why the Nobel Probability Project uses a rolling window and weights older high-impact papers more heavily than recent ones. There are also structural limitations you need to understand. The Royal Swedish Academy is known for favoring Swedish and European economists, and the laureate selection process is opaque by design. No one outside the Academy knows the internal deliberations. Prediction models can get directionally right but rarely capture upsets or late-breaking shifts in the Committee's thinking. For example, in 2019 the prize went to Duflo, Banerjee, and Kremer for their work in development economics, which was somewhat unexpected given that development economics had not been a dominant trend in prior decades of Nobel selections. A purely citation-based model would have underweighted them relative to more established theorists.
If you want to build your own tracking system, the practical approach is to combine three data sources: the Nobel Probability Project's annual candidate list, betting market odds from a major bookmaker, and your own citation analysis filtered through EconLit or the Journal Citation Reports. Weight the academic prediction at 50 percent, the betting market at 30 percent, and your own adjusted model at 20 percent. This gives you a diversified forecast that accounts for both scholarly consensus and market sentiment. The whole process usually takes about three hours to set up properly the first time, assuming you have access to academic databases and know how to parse CSV files from EconLit. After that, updating the model each year takes roughly twenty minutes. The main bottleneck is data cleaning, particularly when merging author names across databases where the same person appears under different name variants. A simple fuzzy matching script reduces most of that friction. What tends to separate accurate predictors from the rest is patience and the willingness to adjust weighting based on historical errors rather than blindly trusting any single source. The predictions are never going to be perfect, but they become meaningfully better if you treat them as an iterative exercise rather than a definitive forecast.
Get the Full Details