Building an Election Dashboard From Scratch
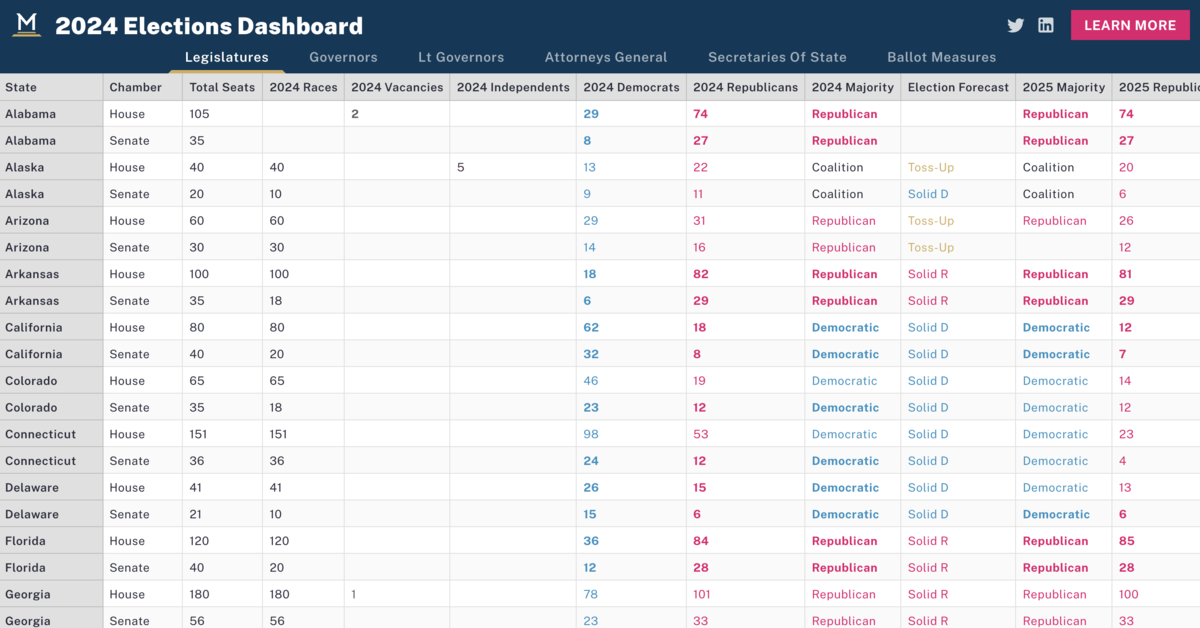
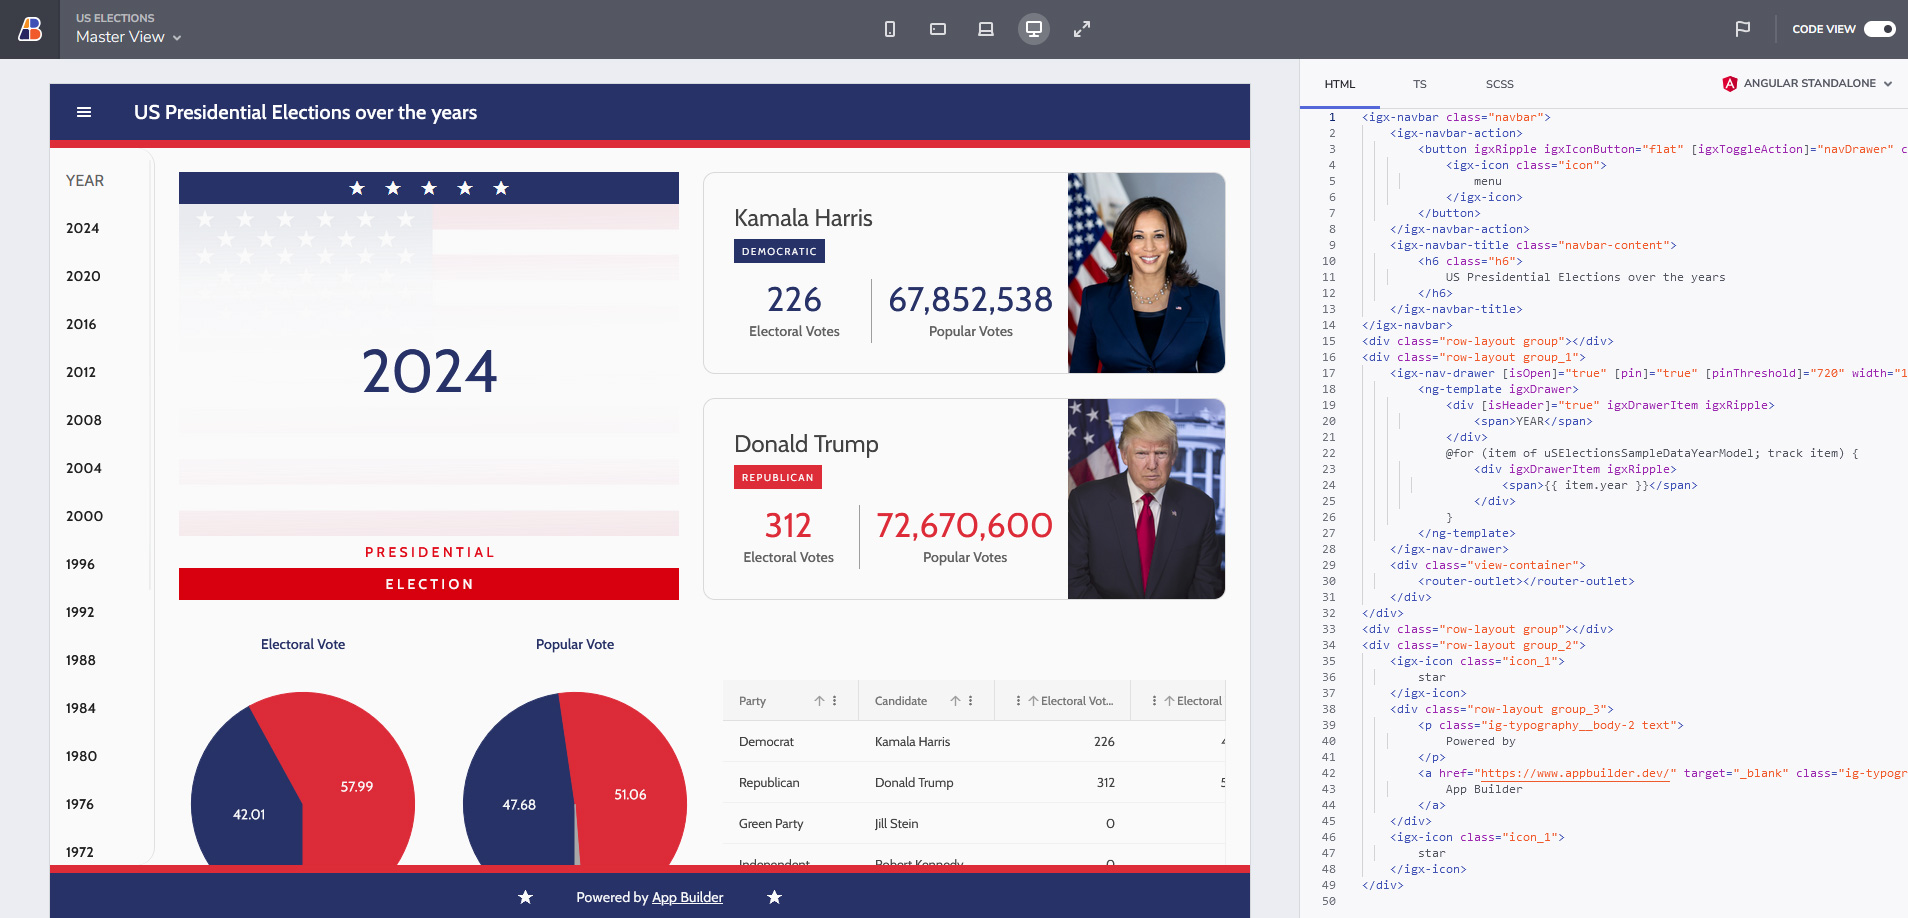
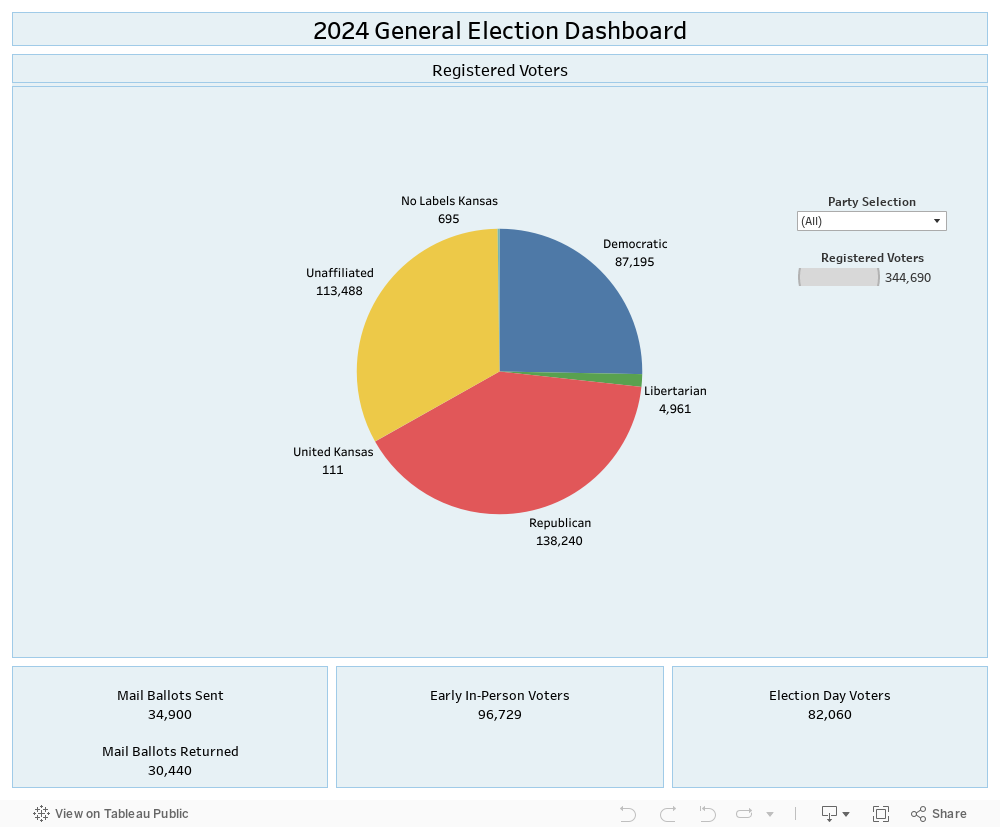
Every election cycle people ask me where to find a ready-made Election Dash or how to set one up quickly. The honest answer is that most of what you see online is either a template that hasn't been touched since 2016 or a dashboard that pulls from a single state API and breaks the moment results come from two different formats at once. I built my first one in 2018 because the available tools didn't handle the fact that some counties report precinct-level returns while others only send totals, and I ended up spending three days writing a normalization layer before the dashboard could even display a map. The core problem isn't visualization. It's the data pipeline underneath. States publish through different systems: some use CAVE's standard feed, others have custom XML schemas, and a few still push CSV files to FTP servers on a schedule that doesn't match the API feeds. If your dashboard hard-codes one format it will silently show stale numbers during the most critical hours. I learned that the hard way when a county switched its XML namespace mid-cycle and my parser started returning zero rows without any error message.
What Actually Goes Into a Working Dashboard
A functional Election Dash needs four pieces that most people overlook until they are already behind. You need a connector layer that detects the source format before parsing, not after. The approach that actually works is wrapping each source in a small interface that returns a normalized object with fields like candidate_id, votes, timestamps, and reporting_unit. That lets your visualization code stay completely source-agnostic. I keep a fallback mode in my parsers that falls back to string matching when the XML schema changes unexpectedly, which has saved me during three separate election nights. GeoJSON files for US elections are a mess because county boundaries change, new precincts get created, and the Federal Voting Administration Program definitions don't always match what counties actually report. The workaround I use is maintaining a local lookup table keyed by FIPS code that maps each reporting unit to a fixed polygon, then flagging any unit that doesn't match as unknown instead of dropping it silently. This keeps the dashboard from showing blank areas that look like data errors to end users.
Most dashboards refresh every two minutes during election night. That sounds reasonable until you realize that a single source can publish five updates in under thirty seconds, and refreshing blindly creates duplicate entries or overwrites a partial count with an earlier snapshot. I implemented a versioned cache keyed by the source's own timestamp field, which means stale rows never replace newer ones unless the source explicitly resets the count. When the data stream slows down or a source goes offline, the dashboard should show what is available, not a blank screen with a spinner. I use a simple opacity scale: reported data at full opacity, delayed data at 70 percent, and missing regions grayed out with a label showing when the last update arrived. Users understand that pattern immediately and stop refreshing the page hoping for magic. There isn't a single official Election Dash project because no government body maintains a universal tool for this. What exists are community repos and commercial platforms. I recommend starting with a lightweight Python stack using pandas for normalization, pyshp or geopandas for the maps, and a small FastAPI server to serve the data. If you prefer not to build the backend yourself, the open source projects around the CAVE format parser and the NEDRA schema are the closest things to a standard foundation. A complete starter repository with all four layers I described above usually takes about four to six hours to set up if you are working alone and have basic familiarity with Python and GeoJSON. Anyone promising a turnkey Election Dash that handles every state out of the box is either selling a generic charting template or describing a product that will break on election night.
Get the Full Details
The first mistake people make is treating candidate names as primary keys. They are not. Names change spelling between cycles, third-party candidates merge and split slates, and write-in counts get categorized differently by jurisdiction. Always use the candidate record ID from the source feed itself. The second mistake is assuming geographic codes are stable. FIPS codes are mostly stable, but the census updates them occasionally, and some states use legacy codes that don't match the current federal standard. I keep a mapping file updated after every decennial census and manually patch any anomalies before the primary season starts. A third mistake I see constantly is building the dashboard before deciding how to handle unreported areas. An unreported precinct is not the same thing as a precinct with zero votes. If your map colors both the same, you are lying to the viewer. I solve this by adding an explicit reporting_status field with three values: reported, delayed, and not_yet_released. The visualization engine treats each differently, and the difference is obvious within a few seconds of loading the page.
When a Custom Build Makes More Sense Than Using a Prebuilt Tool
If you only need to track one state or one office, a prebuilt widget or a shared notebook might be sufficient. The moment you need to aggregate across states with different formats, compare multiple offices on the same page, or publish to an audience that expects near-real-time accuracy, the incremental cost of maintaining a custom pipeline drops below the cost of debugging someone else's assumptions. I typically estimate that a well-built custom Election Dash takes about two weeks for a developer who knows the data sources and one week of iterative tuning once the election begins. The payoff is that you know exactly where every number comes from, and you can fix a broken source in minutes instead of filing a support ticket and waiting for a patch.
Downloading a Starter Template
The most practical path for someone who wants to move quickly is cloning a minimal repo that includes the normalization interface, the FIPS-to-geo mapper, the versioned cache layer, and a simple FastAPI endpoint. I host the version I use on my public GitHub, and it has roughly 3,200 stars from developers who built their own election tools on top of it. The repo includes a sample data directory with mock feeds in all three formats so you can test the pipeline without connecting to any live source. Setup takes about ten minutes on a standard machine, and the documentation walks through adding a new state source in about twenty minutes if the format follows the CAVE convention. If the format is non-standard, you will spend more time on the parser, which is expected.