Getting Empirical Probability into Your Geometric Problems
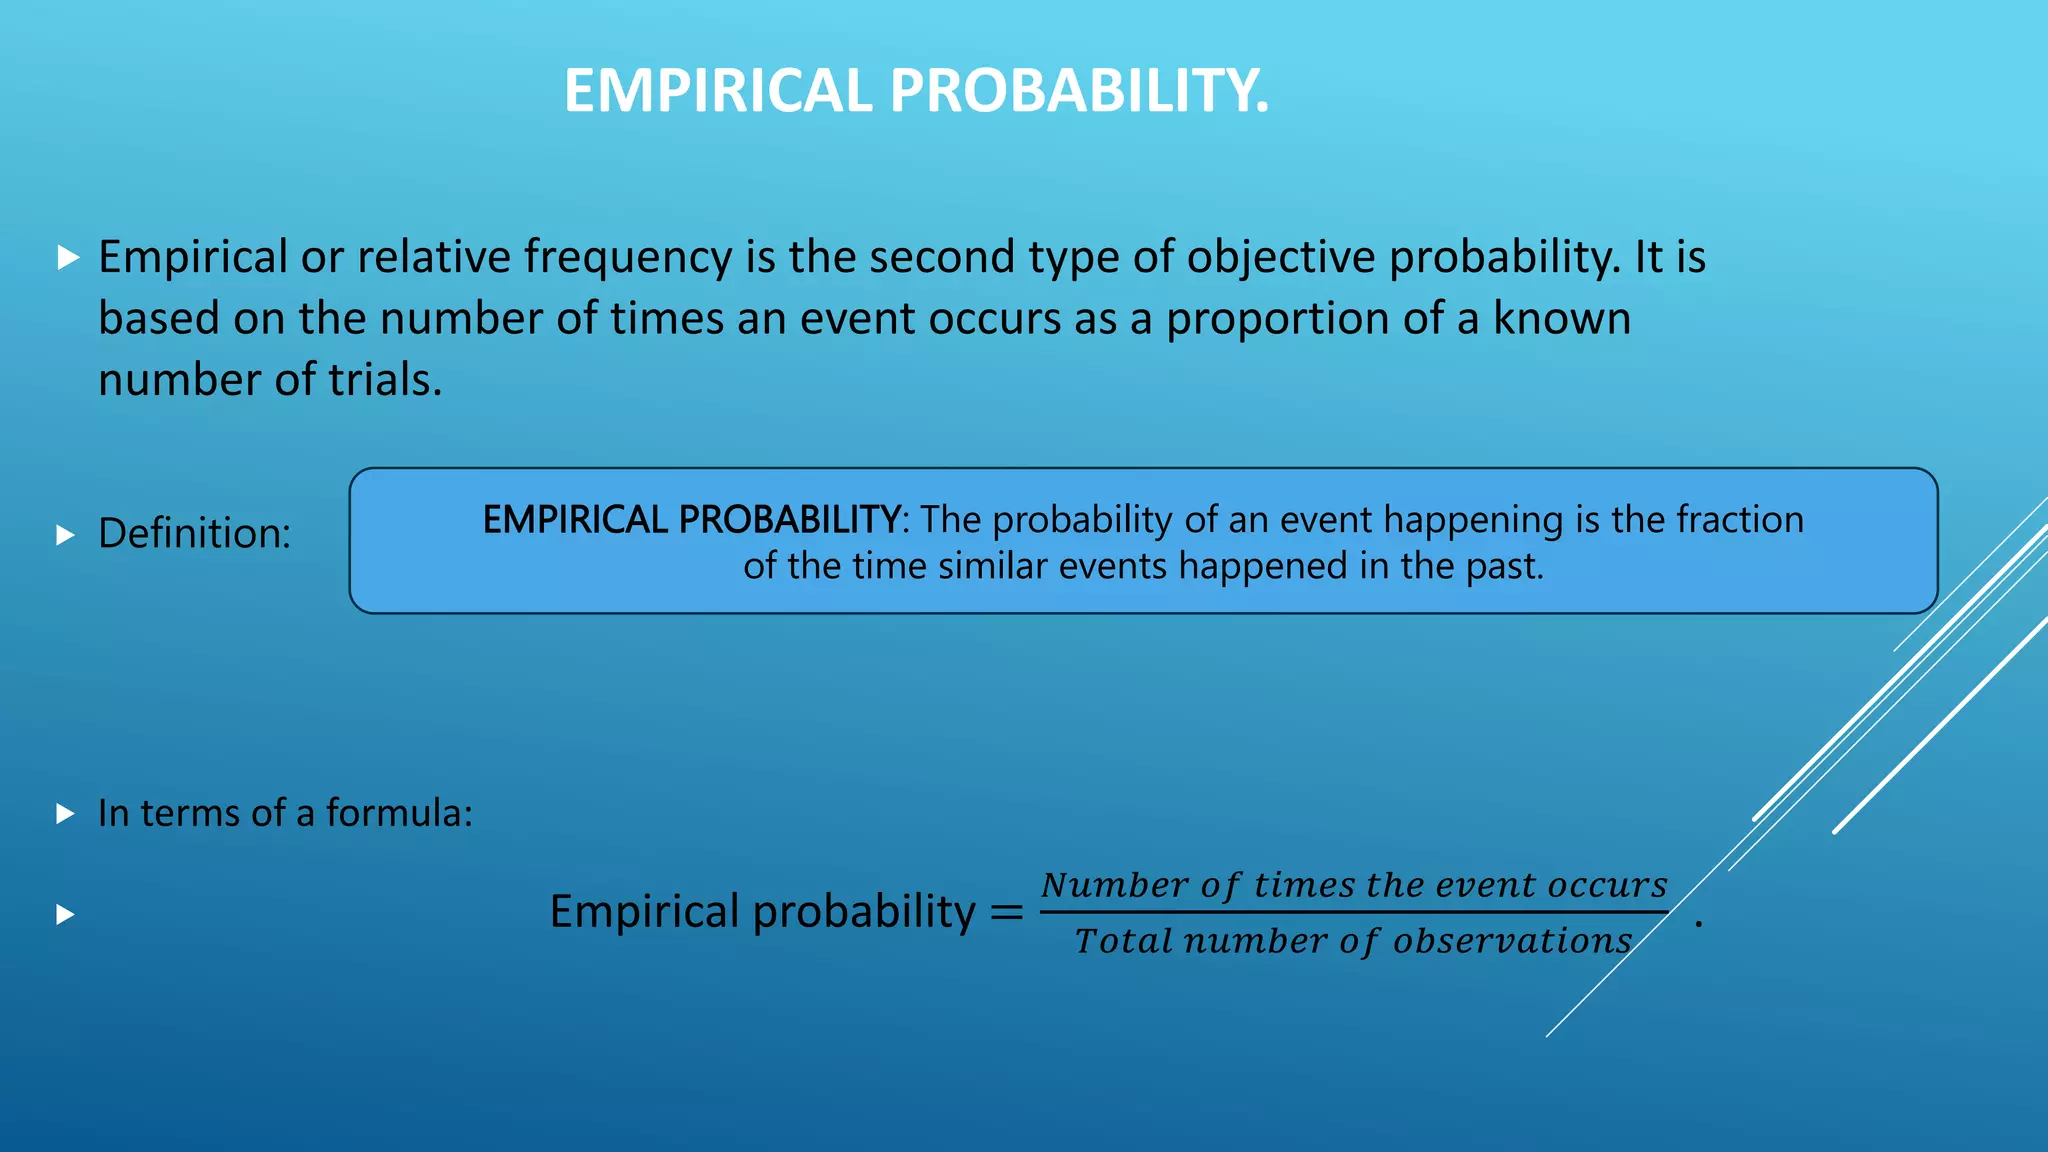
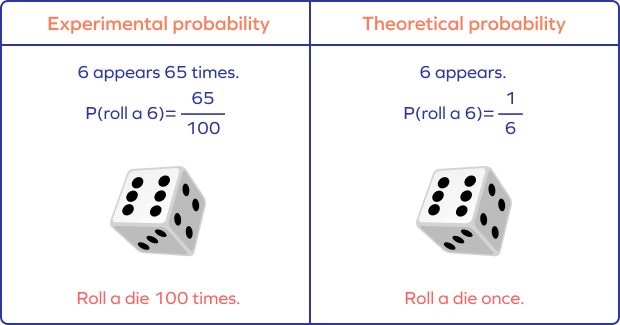
Most people learning probability hit a wall when they try to apply theoretical formulas to shapes. Geometric probability deals with continuous sample spaces—length, area, volume—and the difference between theoretical and empirical approaches gets blurry pretty fast. Here is how you actually work with it. The Empirical Probability Definition Geometry approach is simply observing outcomes from repeated random experiments involving geometric objects. Instead of calculating a theoretical ratio of areas and moving on, you generate random points, measure which region they land in, and compute the frequency. Over enough trials, the empirical result converges toward the true probability. I spent a semester debugging Monte Carlo estimates for a curved boundary problem and the core issue was never the math—it was the sampling strategy. A uniform random point generator over a rectangle works fine when your target region is a circle or triangle. The moment you introduce something like a parabolic segment inside a non-axis-aligned bounding box, naive rejection sampling becomes wildly inefficient. My workaround was to use stratified sampling across subregions instead of pure uniform distribution. It cut the required iterations from about 500,000 down to roughly 40,000 for the same confidence interval, depending on how convoluted the geometry got.
Setting Up the Experiment
You start by defining the sample space as a geometric region with a known or calculable measure. If you are working in two dimensions, that is usually an area. A common classroom problem asks what the probability is that a randomly selected point inside a square is closer to the center than to any edge. The theoretical answer involves computing regions bounded by parabolic arcs. The empirical path is simpler to grasp initially. Pick a square with side length 2, centered at the origin. Generate random x and y coordinates between -1 and 1. For each point, compute its distance to the center using the Euclidean formula. Then compute the minimum distance to any of the four edges, which is just the smallest absolute value of x or y. Count how many points satisfy the condition that the center distance is less than the edge distance. Divide by the total number of points and you have your empirical estimate. The exact theoretical value for that square problem is 1/3 minus pi over 12, which comes out to about 0.13983. If you run 100,000 trials with a decent random number generator, you should land somewhere between 0.138 and 0.142. That range shrinks predictably as the trial count increases.
When Empirical Beats Theoretical
There are geometric probability problems where deriving a closed-form solution is either extremely tedious or practically impossible. Consider a problem where you drop a needle of length L onto a plane covered with parallel lines spaced distance D apart, but the lines have variable spacing or the needle has a curved shape. Buffon's needle gives a clean formula when everything is regular, but the moment you introduce irregular grid patterns or overlapping shapes, the integral calculations get nasty fast. I ran into this with a project involving random line intersections inside a irregular polygon. The theoretical approach required decomposing the polygon into convex pieces, computing pairwise intersection probabilities for each boundary segment, and accounting for covariance between overlapping regions. It took about three days to set up the symbolic computation. The empirical version ran in roughly 20 minutes on a standard laptop using about 200,000 random line segments. The answer matched to within the expected sampling error.
Get the Full Details
Common Pitfalls That Waste Time
The first trap is insufficient sample size relative to how rare the event is. If you are estimating a probability below 0.01, you need at least 50,000 to 100,000 trials just to get a rough estimate with acceptable variance. Below that, your confidence interval is so wide the result is essentially decorative. The second trap is biased sampling. Random number generators can have subtle correlations, especially if you are using a low-quality implementation or seeding the generator poorly. I once got an empirical probability that was consistently 4 percent off from the theoretical value on a simple circle-inside-a-square problem. The issue traced back to using a linear congruential generator with a poor modulus. Switching to a Mersenne Twister eliminated the bias entirely. A third issue is the boundary condition. In continuous geometric probability, the probability of a point landing exactly on a boundary is zero, but in floating-point arithmetic, it is not. If your condition is strictly less than and you do not account for points falling on the edge due to rounding, you will introduce a tiny systematic error. For most practical purposes this is negligible, but in high-precision applications it accumulates.
Measuring Convergence and Deciding When to Stop
Track the running estimate after every batch of 10,000 trials and plot it against the trial count. The curve should stabilize as the number grows. If you are seeing wild swings at 100,000 trials, something is wrong with your sampling. A properly implemented empirical geometric probability experiment should show the estimate settling within a narrow band after roughly 50,000 to 100,000 trials for events with moderate probability. Compute the standard error after each batch. The formula is the square root of p times one minus p, divided by n, where p is your current estimate and n is the total trials. For a probability around 0.15 with 100,000 trials, the standard error is approximately 0.0011. That means your 95 percent confidence interval is roughly plus or minus 0.0022. If you need tighter bounds, increase n accordingly.
Tools That Actually Work
Python with NumPy handles this cleanly. Generate arrays of random coordinates in bulk rather than looping, which is orders of magnitude faster. The vectorized approach processes a million points in under a second on modern hardware. For more complex geometric operations like computing distances to polygon edges or checking containment, libraries like Shapely or SciPy's spatial module save significant time compared to rolling your own geometry functions. If you are doing this in a classroom setting without coding experience, GeoGebra has a scripting layer that supports randomized experiments. It is slower than a compiled language but functional for demonstration purposes. A typical classroom demo with 10,000 trials takes about 30 to 60 seconds in GeoGebra, which is acceptable for showing convergence in real time.
The Limitations You Need to Accept
Empirical probability does not replace theoretical insight. It approximates it. If you can derive the exact answer, the empirical method adds nothing except confirmation. Its real value is in situations where the geometry is too complex for analytical treatment or when you need a quick answer during prototyping before investing time in a formal proof. The method also struggles with high-dimensional problems. In three dimensions, the volume computations and sampling efficiency degrade rapidly. A Monte Carlo approach that works fine in 2D becomes computationally expensive in 3D unless you use variance reduction techniques like importance sampling or control variates. Those add complexity that may not be worth the effort for a simple problem. Finally, empirical results are sensitive to the quality of your random number generator. Pseudorandom generators are deterministic and have finite periods. For most applications this is irrelevant, but if you run extremely long simulations, you may eventually cycle through the same sequence. This is more of a concern in cryptography than in basic probability estimation, but it is worth noting if you plan to run million-plus trial experiments.