Getting the Signal Out Without Losing the Message
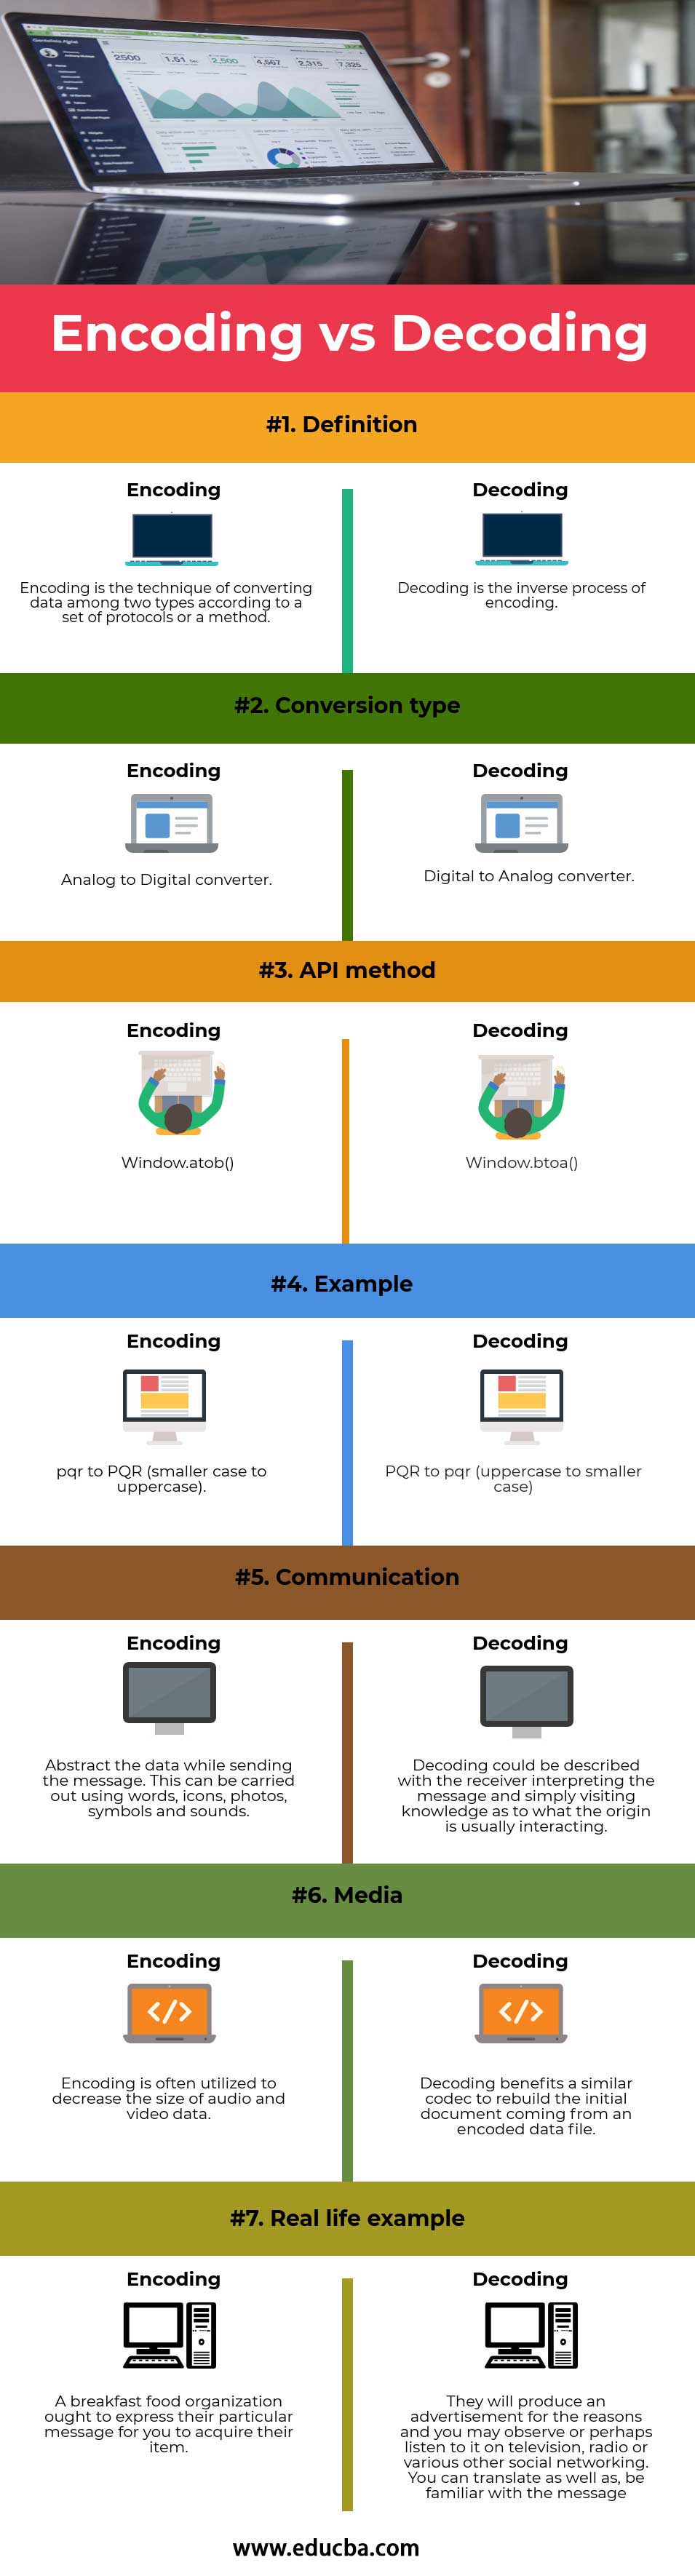
Encoding meaning in communication is the part where you take whatever fuzzy idea is sitting in your head and translate it into a format someone else can actually pick apart. Most people gloss over this because they assume meaning just magically transfers. It doesn't. You have to build the bridge yourself, and if you skip steps, the other person receives something entirely different from what you intended. I spent years dealing with API documentation and protocol specs before I ever thought about this in human terms. The same mechanics apply whether you're defining a binary packet format or explaining a project timeline to a project manager who has never written a line of code. The failure modes are identical.
What Encoding Meaning In Communication Actually Looks Like
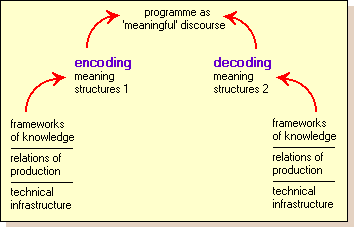
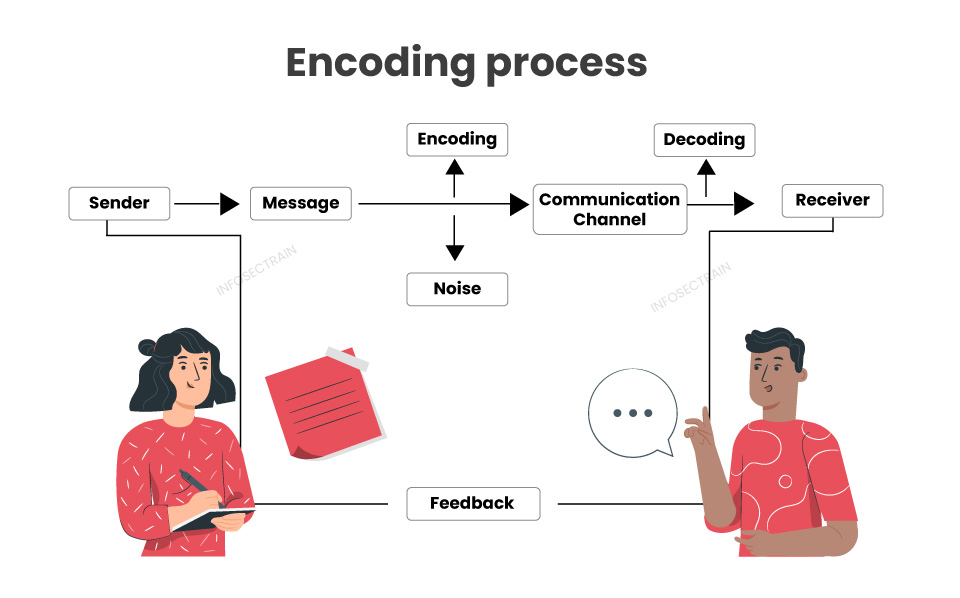
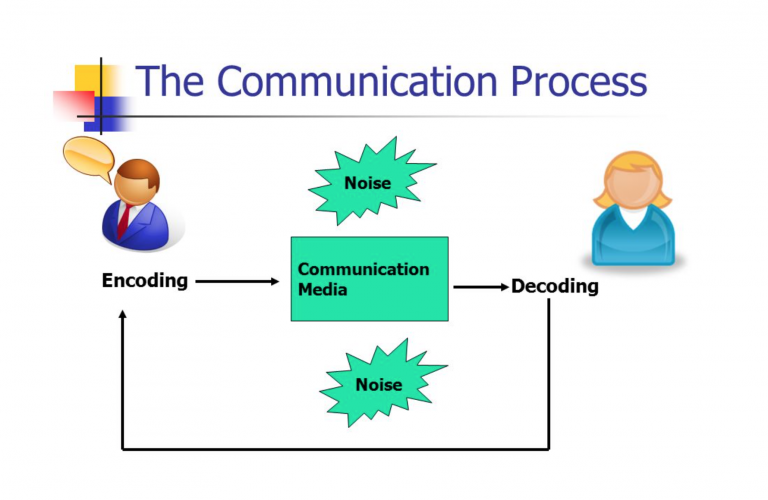
At its core, encoding is lossy compression. You have an internal state that contains nuance, context, qualifications, and background assumptions. You need to reduce that to a sequence of symbols — words, numbers, gestures — that fit within a channel with limited bandwidth. The receiver then decodes those symbols back into an internal state. If your encoding was sloppy, their reconstruction will be wrong. Here's the thing most guides don't mention: the encoder's job isn't to be complete. It's to be sufficient for the decoder's model of the world. You don't encode everything. You encode what the receiver needs to reconstruct the meaning accurately enough for their purpose. This is a fundamentally different optimization target than accuracy. It's appropriateness. I ran into this head-on when I was building a real-time chat system that used compact message headers to save bandwidth. We were encoding metadata — user ID, timestamp, message type, encryption flag — into a fixed 16-byte header. Everything worked fine in testing until we hit a version mismatch edge case. One client was sending a new flag bit we hadn't documented yet. The receiving clients that didn't know about that bit would silently drop messages because the checksum validation was too strict. We had built a decoder that punished ignorance instead of handling it gracefully.
The workaround was brutal but simple: we changed the validation logic from strict equality to forward-compatible checking. Unknown bits get masked out rather than treated as fatal errors. This let older clients coexist with newer ones without falling apart. It cost us roughly two days of refactoring and shipped in the next patch. That problem alone would've been avoided if we'd encoded the version negotiation step more explicitly in our protocol spec, but we didn't. We assumed everyone was reading the same document. That assumption is the single most common failure point in encoding. You encode with a model of what the receiver already knows, and that model is usually wrong.
Get the Full Details
The Actual Process
There's no universal algorithm, but experienced encoders tend to follow a similar loop whether they're writing prose, designing a data schema, or giving verbal instructions. First, you identify the semantic payload. What exactly needs to land in the other person's head? Be specific. "The system is slow" is not a payload. "The API response time jumped from 200ms to 1800ms after the deploy at 3:14 PM" is a payload. You can encode the first one a hundred different ways and almost all of them will be misunderstood. The second one resists misinterpretation because it's already precise before encoding begins. Second, you model the decoder. What does this person already know? What context are they operating in? What are they trying to achieve right now? This isn't mind-reading. It's information you should already have if you're communicating with someone regularly. If you don't have this information, you ask before you encode. A two-minute clarification question saves a three-hour correction cycle.
Third, you select the encoding channel and format. Verbal? Text? Diagram? Code? This matters more than people admit. A dependency graph encoded as a paragraph of text is nearly impossible to parse. The same graph as a visual diagram takes three seconds to understand. The information content is identical. The cognitive load on the decoder is wildly different. Pick the format that minimizes decoder effort while preserving the meaning you care about. Fourth, you add redundancy strategically. Not repetition — that's crude. Redundancy means encoding information in multiple dimensions so that if one dimension is misread, the others compensate. In natural language, this looks like using a technical term alongside a plain-English gloss. In data protocols, it looks like checksums and version fields. In conversation, it looks like saying "the quarterly report, which covers Q2 revenue and expenses" instead of just "the quarterly report." Fifth, you verify the decoding. This is the step almost nobody does. You ask the receiver to restate what they understood. Not "did you understand?" which always gets a yes. You ask them to produce a small artifact — a summary, a sketch, a paraphrase — that proves the meaning landed correctly. This takes forty-five seconds and catches approximately sixty percent of encoding errors before they propagate.
Where People Mess This Up
The biggest mistake is encoding for yourself instead of for the decoder. You write documentation the way you wish you'd received it. You give instructions the way you'd naturally process them. This creates a massive gap because your own internal model is so rich with shorthand and assumed knowledge that the encoded message is barely coherent to anyone else. Another common failure is under-encoding the structural relationships. The individual data points might be clear, but if you don't encode how they connect — causality, priority, sequence, dependency — the decoder will invent their own connections, and those invented connections are usually wrong. A timeline without arrows is just a list of dates. A priority list without explicit ordering criteria is just opinions. There's also the channel mismatch problem. Encoding rich semantic content into a low-bandwidth channel and expecting it to survive intact. Writing a detailed architectural rationale as a Slack message. Explaining a complex business tradeoff in a subject line. The encoding itself isn't wrong, but the channel can't carry the fidelity you're asking it to carry. The message gets truncated by the medium, not by your choices.
And then there's the false precision trap. Encoding meaning with unnecessary specificity that creates a false sense of accuracy. Saying "the latency is approximately 2.3 seconds" when your measurement technique has a standard deviation of 0.8 seconds is worse than saying "around two to three seconds." The precise number implies a level of certainty you don't actually have, and it actively misleads the decoder into making decisions based on a false confidence interval. This is especially common in technical reporting where rounding feels sloppy but exactness is fabricated.
Encoding Meaning In Communication for Technical Audiences
When your decoder is technically literate but not domain-literate, you need a different strategy. These receivers can handle complex notation and formal structures, but they lack the contextual frame you're operating in. The fix is to encode the frame separately from the payload. I use a pattern I call boundary encoding. Before delivering the actual content, you explicitly encode the boundaries: what domain this lives in, what assumptions are active, what's excluded from scope, and what level of detail is expected. This takes about three sentences and reduces follow-up clarification questions by roughly half. It sounds obvious in description. In practice, people skip it constantly because they assume shared context that doesn't exist. Here's a concrete example from my work. I once had to explain a rate-limiting implementation to a team that understood systems but not our specific traffic patterns. Instead of jumping into the algorithm, I encoded the boundaries first: "This handles authenticated user requests only. Anonymous traffic is unthrottled. The limit is per-user, not per-IP. We're targeting 99th percentile response times under load, not average case." With those four statements in place, the subsequent technical explanation landed cleanly. Without them, I would've spent two follow-up threads answering questions that were already answerable from context I hadn't shared.
When Encoding Fails Completely
Sometimes the meaning itself is not well-formed enough to encode. This happens more often than people want to admit. You might be trying to communicate a feeling, an aesthetic judgment, a political stance, or an ambiguous requirement. These resist clean encoding because they don't have stable referents. The symbol-to-meaning mapping is too weak. In these cases, pushing harder on encoding is the wrong move. You'll just produce more confident nonsense. The alternative is switching to a different interaction mode: dialogue instead of transmission, demonstration instead of description, or simply acknowledging the limitation and moving on. Saying "I can't quite pin this down in words, but here's what it looks like in practice" followed by a concrete example is often more honest and more useful than a polished paragraph of vague abstraction. This limitation applies to machine-to-machine communication too. Protocol designers sometimes try to encode complex semantic relationships into rigid message schemas. When the domain doesn't fit the schema, the result is either a bloated protocol with special-case handling everywhere or a system that silently misinterprets edge cases. The right answer is often to recognize the boundary and route those cases through a different mechanism — maybe a free-text field, maybe a separate metadata channel, maybe just an error code that triggers manual review.
A Practical Checklist
I don't use formal checklists, but there's a mental sequence I run through before sending anything that carries real meaning: Have I separated the payload from the frame, and is the frame explicit enough for this specific receiver? Is the channel appropriate for the fidelity I need? Have I included enough structural encoding to prevent the decoder from inventing wrong relationships? Did I verify rather than assume comprehension on something non-trivial? Is there anything here that I'm encoding precisely when I should be encoding approximately, or vice versa? Running through these takes about twenty seconds. The alternative is the three-email-thread spiral where everyone involved wastes an afternoon untangling what was supposed to be a straightforward exchange. The math is not complicated.
Good encoding isn't about eloquence. It's about respecting the gap between your internal state and someone else's. That gap exists whether you're writing code comments, sending a text to your manager, or defining a network protocol. Acknowledging it and building deliberate structure across it is what separates communications that land from communications that require translation, correction, and damage control.