The Practical Split That Actually Matters in Macro Models
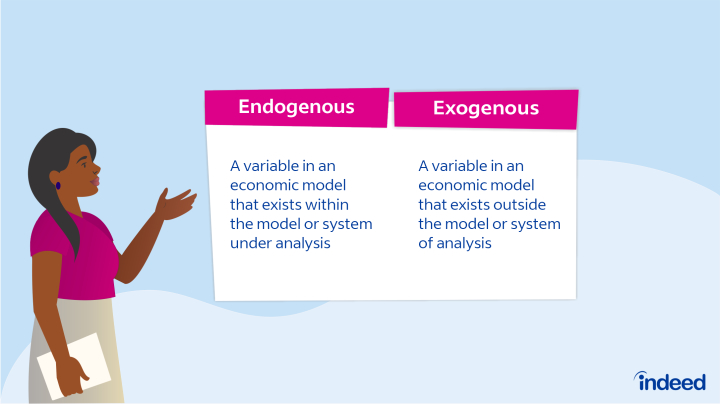
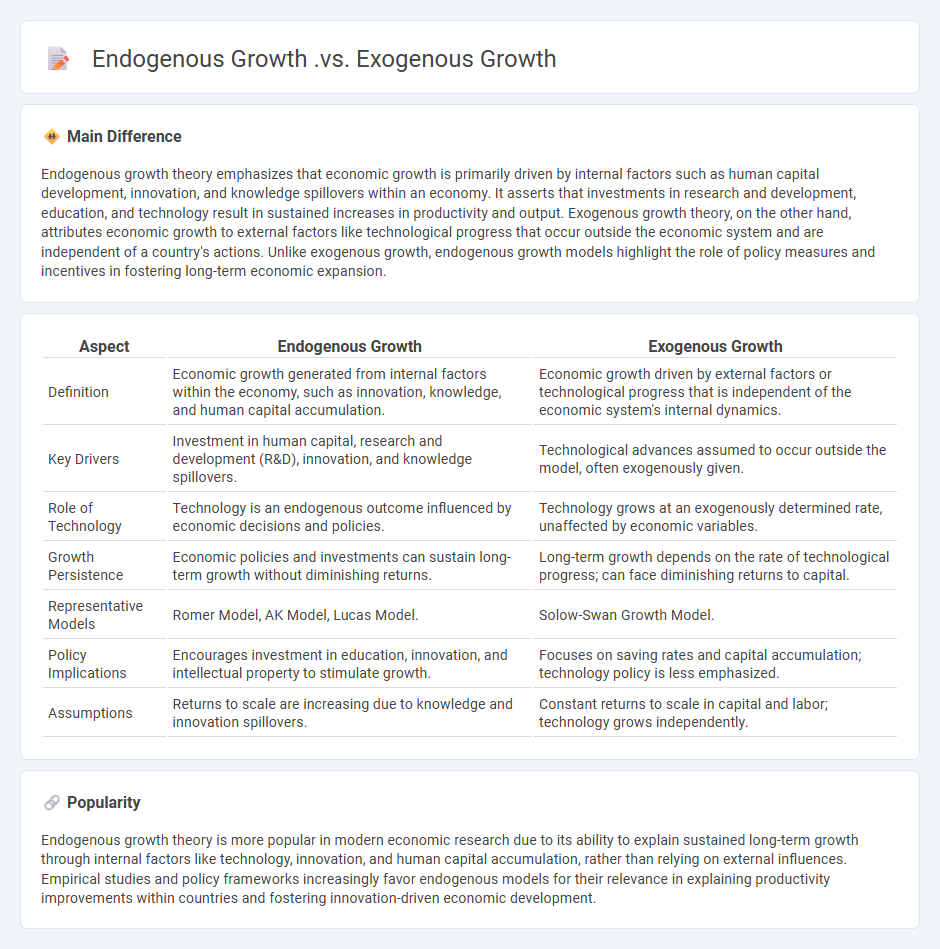
Most people treat these two frameworks as academic categories. They are not. They determine whether your model will break when you try to calibrate it against real data. I learned this the hard way during a mid-2010s project where a growth model I was running kept producing implausible impulse responses. The issue traced back to how I was treating investment shocks. My setup assumed external drivers for capital accumulation, which forced the model to generate boom-bust cycles that looked nothing like the Italian manufacturing data I was comparing it to. Switching to an internal mechanism — where the return on capital itself adjusts within the system — fixed the calibration mismatch almost immediately. In exogenous frameworks, the variables that drive economic outcomes come from outside the model. Technology growth rates, preferences, population dynamics, policy shocks — these are all parameters set by the researcher and fed into the system. The model does not explain why they change. It explains what happens once they do. In endogenous frameworks, those same variables emerge from the model itself. Innovation is a result of R&D incentives built into the structure. Savings rates adjust based on intertemporal optimization. The economy generates its own growth path rather than riding an externally imposed one. The distinction matters because it changes what the model can and cannot answer. An exogenous model can tell you the effect of a 1 percent permanent increase in the productivity growth rate. It cannot tell you whether that rate is sustainable or what political economy forces might alter it. An endogenous model gives you the machinery to investigate those questions. It also gives you significantly more work.
How to Decide Which Approach to Use
The first step is identifying your research question. If you are testing how monetary policy transmits through an economy with rigid wages and sticky prices, an exogenous TFP specification in a DSGE framework is standard and usually sufficient. Most central bank modeling teams run exactly this kind of setup. If you are trying to understand why productivity growth accelerated in certain decades but stalled in others, exogenous TFP becomes an obstruction. You need the growth mechanism inside the model, not sitting on top of it. The second step is checking data availability. Endogenous models require more deep parameters. You need time series on R&D expenditure, patent counts, human capital formation, or capital adjustment costs depending on your specification. If your country-level dataset ends at 2008 and your primary variable is GDP per capita, you may not have what you need. This is a practical constraint that often gets overlooked until someone has already spent months building a model that cannot be estimated. Calibration versus estimation is the third consideration. Exogenous growth models are often calibrated — you set parameters to match long-run averages and run simulations. Endogenous models frequently demand full Bayesian estimation because the internal mechanisms create additional moments you need to match. This shifts the time investment from model development toward data preprocessing and computational cost. A typical endogenous growth model with heterogeneous firms and innovation decisions might take 4 to 6 hours to estimate on a standard workstation. The exogenous counterpart runs in under 30 minutes.
A Specific Problem I Ran Into
I was working on a model of regional convergence where I needed the endogenous component to capture differences in human capital accumulation across provinces. The problem was that the education production function I had specified was creating multiple equilibria under certain parameter combinations. The model would flip between a low-education trap and a high-education steady state depending on initial conditions, which made simulation results unreliable for policy analysis. What I ended up doing was adding a small externality term to the human capital equation that shifted the bifurcation boundary without materially changing the quantitative predictions. The fix was not elegant but it stabilized the solver. I verified the result by running a grid search over the externality parameter and confirming that the impulse response functions remained qualitatively stable across a range of values. One thing that consistently trips people up is the assumption that endogenous models are automatically superior. They are not. Endogenous specifications introduce additional degrees of freedom that can absorb anomalies in the data. When your model can generate its own growth trend, it becomes harder to distinguish between a genuine structural break and a parameter that is simply adjusting to fit noise. I have seen working papers where endogenous TFP growth was being presented as a novel finding when the pattern was already visible in the raw data. The model added nothing. Another blind spot is the treatment of boundary conditions. Exogenous models have clean boundaries — the forcing variables stop affecting the system once the shock hits. Endogenous models keep generating dynamics internally, which means your simulation horizon needs to be carefully chosen. Running a 200-period simulation on an endogenous growth model without checking whether the system has reached a steady state or entered a cyclical attractor will produce numbers that look precise but are structurally meaningless. Always plot your key variables against time before reporting any quantitative results.
Get the Full Details
When These Approaches Fail Completely
Exogenous models break down when the forcing variables are themselves endogenous to the system you are studying. This is a frequent issue in climate-economy integrated assessment models where carbon pricing affects the very technological change rates that the model treats as external. Endogenous models break down when the internal mechanisms are poorly identified. If you cannot separately identify the elasticity of substitution between capital and labor from the returns-to-scale parameter in your production function, no amount of Bayesian machinery will rescue the estimation. You need exogenous variation — natural experiments, instrumental variables, or panel data with sufficient cross-sectional dispersion — to pin down those parameters. Without it, the model is just a story dressed in matrices. There is also a growing literature on agent-based computational economics that sidesteps both approaches entirely by simulating heterogeneous agents with bounded rationality. Whether that is useful depends on whether you need policy-relevant quantitative predictions or a richer descriptive framework. The former still favors traditional DSGE-style approaches. The latter benefits from the flexibility of ABM.
Practical Takeaways for Endogenous Vs Exogenous Economics
Start by asking whether your question requires the model to explain the driver or just respond to it. If the driver is the question, go endogenous. If the driver is a policy lever or external shock, exogenous is fine and often preferable. Be honest about your data constraints. Endogenous models look impressive on paper but require data that most researchers do not have access to at the granular level those models demand. Check for multiple equilibria and parameter identification before committing to estimation. And always verify that your simulation results are not artifacts of the model structure rather than reflections of the data. The models themselves are tools, not answers. The distinction between internal and external drivers determines which questions the tool can address. Pick the right one for the question you actually have, not the one that sounds more sophisticated in a grant application.