Building English Tests That Actually Work
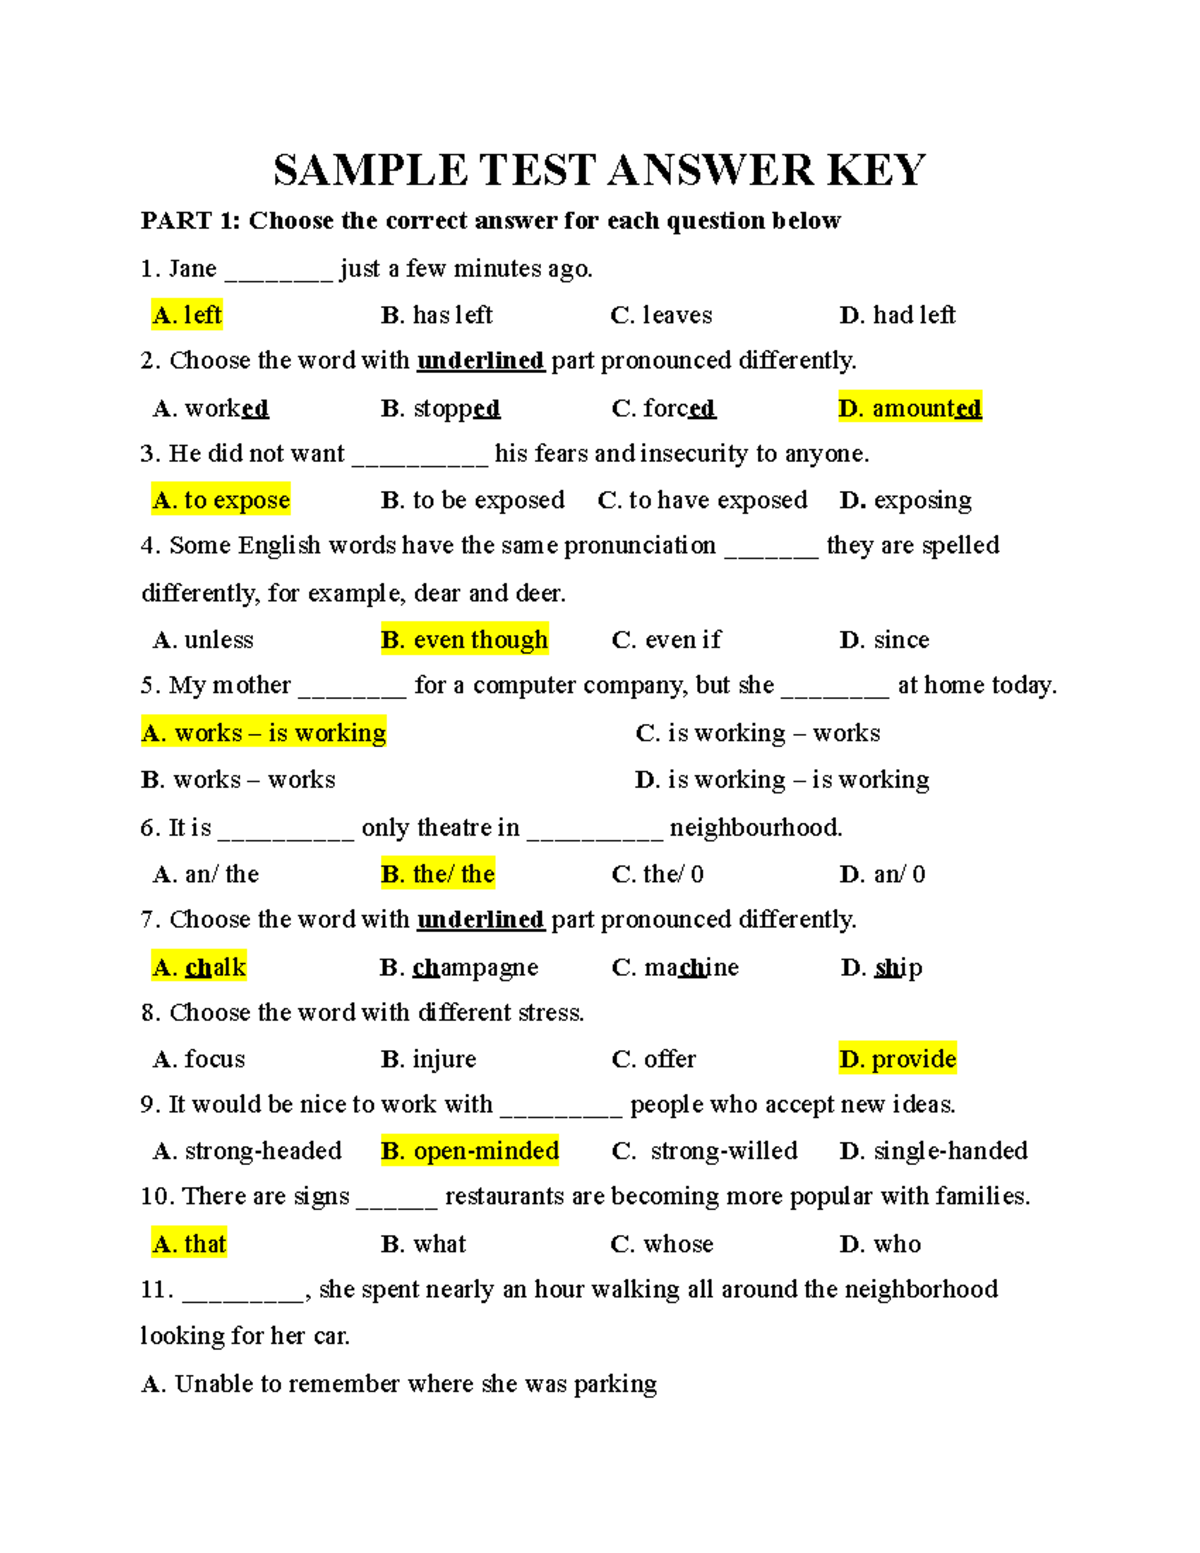
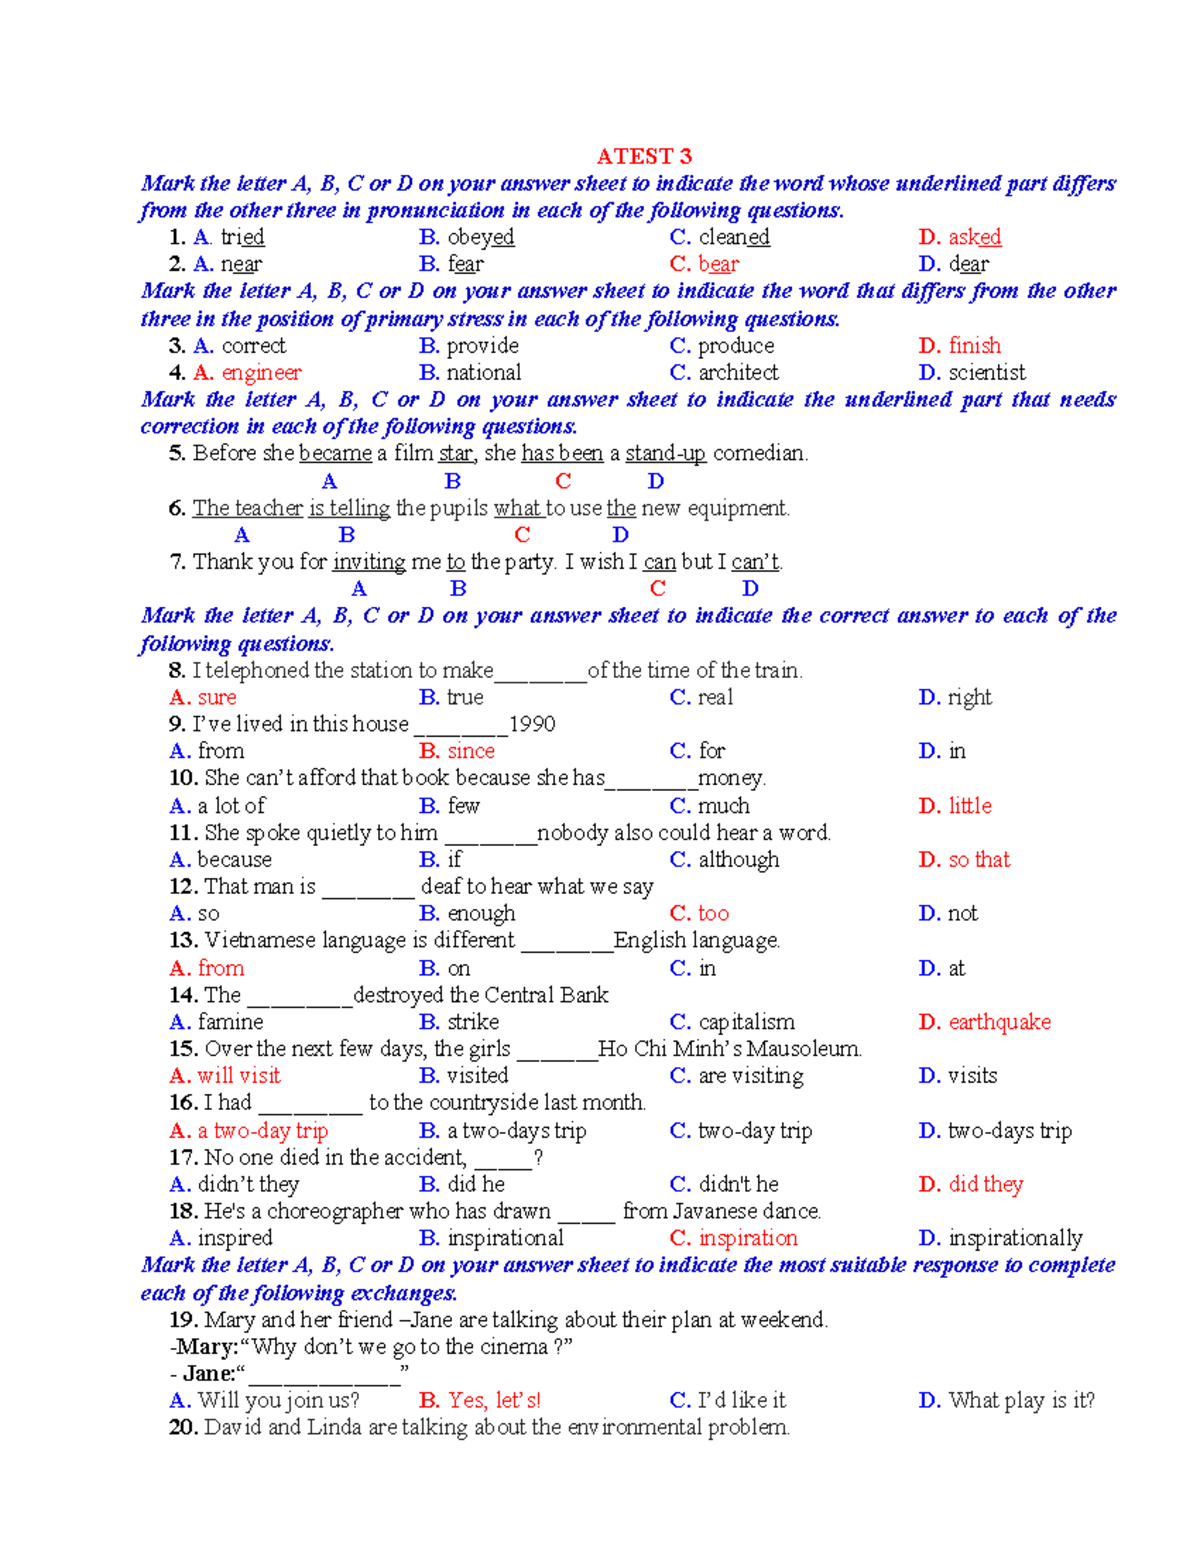
The hardest part of creating an English Test With Answer Key isn't writing the questions. It's making sure the answers are unambiguous, the distractors are plausible, and the whole thing doesn't look like it was generated by something that has never actually taught a class. I've been making these for about fourteen years, and I still find myself rewriting sections at 11 PM before a Monday morning test. Most people build a test around a theme they just covered in class last week. Reading about climate change. Vocabulary on food. It sounds reasonable until you realize the students who struggled with the reading passage are now being tested on whether they remember the word "sustain" rather than whether they can parse a complex sentence. You end up measuring reading stamina instead of reading comprehension, which is a different skill entirely. I switched to a skills-first approach around 2016 after watching my mid-term results flatten out. The variance collapsed because every question was tied to a specific micro-skill. Grammar, not vocabulary. Cohesion devices, not content knowledge. Listening for main idea versus listening for specific detail. When the test maps directly onto a skill matrix, the score becomes actionable. When it maps onto a chapter, the score is just noise.
How to Build Each Section Without Losing Your Mind
Multiple choice for grammar questions needs distractor analysis. A poorly designed wrong answer is worse than an easy wrong answer because it makes a student look confident when they are guessing. I once had a test where 73 percent of my class picked option C on a question about third conditional form, even though C was clearly wrong to anyone who had done the workbook exercise. The problem wasn't the students. The problem was that C matched the pattern from two exercises prior where the answer had been the past participle form, and the question stem was structured almost identically. Pattern recognition beat actual grammar knowledge. I removed that question and redesigned the distractors so each one corresponded to a real error students make, not a random plausible-looking construction. For listening sections, the script matters more than the audio quality. A clear recording of a boring or confusing passage is still a bad listening question. I use a simple rubric: does the passage contain at least two instances of reference resolution that require the student to track who did what, and does it include at least one instance of implied meaning that cannot be deduced from literal words alone? If the answer to either question is no, the test isn't measuring listening comprehension. It is measuring whether the student can follow along while simultaneously checking their phone.
Answer Keys Are Not Just Lists of Letters
Every answer key should include a brief explanation. Two sentences maximum. "Option B is correct because the sequence of events requires past perfect to establish that the action occurred before the narrative past tense verb." That level of specificity tells the student something. A bare "B" tells them nothing except that they were wrong. There is a real downside to writing detailed answer explanations, and it is time. Each explanation takes roughly three minutes to draft and another two to verify against the source material. A forty-question test with full explanations runs about two hours of pure writing time, not counting the question creation itself. For a single teacher this is manageable. For a department of twelve people building standardized assessments, it becomes a scheduling problem. The workaround I found was building a shared explanation bank. Once an explanation was written and approved for one test cycle, it could be reused with minor modifications for the next. Explanation reuse cut the total time down to about forty-five minutes per test cycle after the first pass.
Get the Full Details

Common Pitfalls That Make Tests Unusable
Time pressure is the first one. Students in my classes average between eleven and fourteen minutes per section depending on the mix of question types. If you assign a sixty-minute block for a section that genuinely requires seventy-five minutes of focused attention, you are not testing English ability. You are testing how fast someone can read under stress, which correlates weakly with actual language proficiency and strongly with how much caffeine they consumed that morning. The second pitfall is answer key dependency on visual formatting. I once graded a test where the correct answer for a reading comprehension question was the paragraph that began with a capital letter in the student copy but with a lowercase letter in the scantron version. Different printer. Different font rendering. Half the class marked the wrong option because the visual cue changed and the question relied on that cue implicitly rather than explicitly. The fix was to audit every visual element that could shift between print and digital versions before distributing the test. There is also the issue of cultural loading. A listening passage about Thanksgiving dinner or a reading text about college financial aid assumes a baseline of cultural familiarity that international students simply do not have. This does not make the passage inherently bad. It makes the question measure background knowledge rather than language ability, which violates the validity of the assessment. When in doubt, use neutral contexts. Everyday situations. Academic instructions. Workplace scenarios that exist across cultures.
A Practical Workflow That Doesn't Suck
Here is the process I actually use now. I start with a skill matrix. Columns are the specific competencies. Rows are the question types. I fill in the grid until every cell has at least one question, then I write the questions. After that comes the answer key with explanations. Then I run a draft through a fresh pair of eyes. A colleague who has not seen the material in six months catches about sixty percent of the errors I miss. The remaining errors are usually the ambiguous ones that I accept as a tradeoff. I schedule about two weeks between draft and final distribution. Week one is question writing and key creation. Week two is review, revision, and pilot administration if possible. A pilot with twenty students before final release takes an hour of their time and saves me four hours of post-test grading drama. Students ask fewer "why is this wrong" questions when the explanations are available at the time of the test rather than three days later in a forum thread. The final output is a single document containing the test, the answer key, and the explanations. Separate files create version drift. I have seen departments where the answer key circulated five days before the test went out and the student copy got updated afterward without anyone noticing. The key had the wrong question numbers. It happened twice in one semester. Never again.
Where This Approach Falls Apart
This method requires access to a reliable review cycle. If you are a solo teacher with no colleagues to run drafts through, the error rate climbs noticeably. Peer review is not optional in the workflow. It is the quality control layer. Without it, you are relying entirely on your own blind spots, and those accumulate over time. The second limitation is scale. Building high-quality skill-based tests at volume is slow. If your department needs ten variants of the same test per semester, this approach will not carry that load. In that scenario, a question bank system with automated item generation and calibrated difficulty curves becomes necessary. The tradeoff is that automated systems rarely produce the kind of nuanced distractors that real teachers write, and they struggle with open-ended response evaluation. There is no substitute for human judgment on the hard questions. My English Test With Answer Key documents usually run between forty and sixty questions across reading, listening, grammar, and writing sections. The total creation time for a clean, reviewable version is about six to eight hours spread across two weeks. The grading time drops dramatically afterward because the questions are less contentious and the answer explanations preempt most complaints. That is the actual return on investment. Not speed of production. Speed of post-test cleanup.