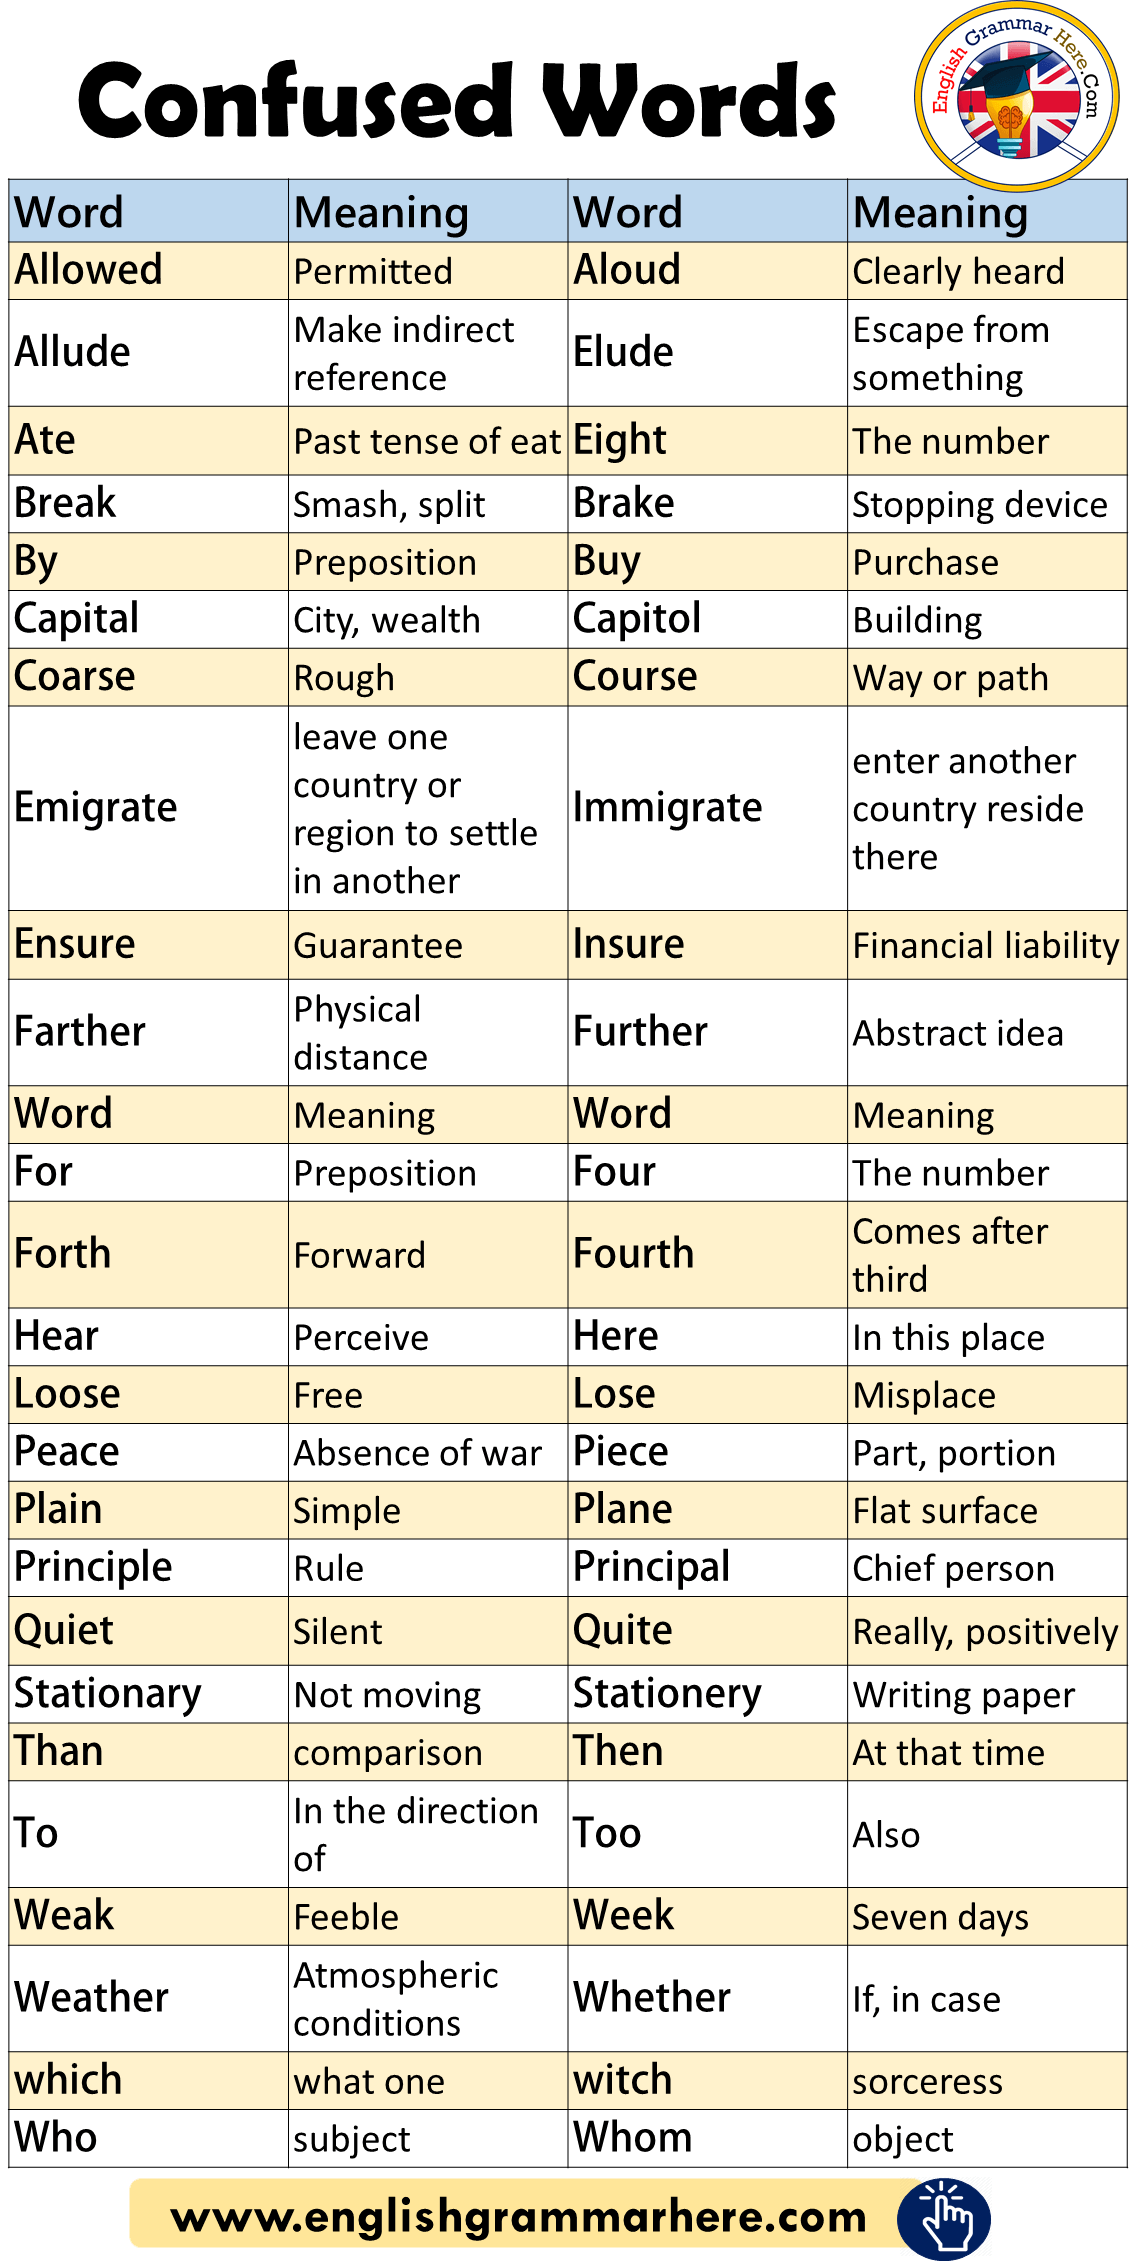
Building a Functional English Words List With Meaning
A lot of people treat word lists like they're just dictionaries cut down to size. They're not. A proper list needs structure, context tags, and pronunciation guides if you actually want to use it for anything beyond flashcards. I spent about three months building out a custom vocabulary reference for our localization team because the off-the-shelf options were either too academic or completely stripped of nuance. The core problem most people hit is that they compile words without recording how those words are actually used. You end up with a list that looks comprehensive but fails the moment someone tries to plug it into a real translation pipeline or a study tool. The workaround is simple enough but takes discipline: every entry needs at minimum a part-of-speech tag, a usage register note (formal, colloquial, technical), and one real-world example sentence pulled from actual text, not generated filler.
English Words List With Meaning
Here's how I structured mine. Each entry follows a flat format that's easy to parse programmatically but also readable by humans. The field order matters because once you have a thousand entries, you don't want to be hunting through inconsistent layouts. Word — the headword itself, normalized to lowercase standard spelling. No archaic forms unless the entry specifically covers historical usage. Phonetic — IPA transcription covering both General American and Received Pronunciation when they diverge. Part of speech — tagged as noun, verb, adjective, adverb, preposition, conjunction, or interjection, with subtags for count versus mass nouns where relevant. Definition — written in plain language without circularity. Never define a word using the same root. Register — labels like neutral, informal, slang, literary, medical, legal, or technical. Example — a sentence from a real source or constructed to match authentic collocation patterns. Common collocations — the top three word pairings this term appears with in natural text. Notes — disambiguation when a word has multiple unrelated meanings, or warnings about frequent misuse. One thing nobody tells you about compiling these lists is that homographs create hidden bugs in any automated system downstream. Words like "lead" (the metal) versus "lead" (to guide) or "tear" (rip) versus "tear" (from the eye) will silently corrupt your parsing if you only store the surface form. I ran into this when a colleague tried to feed a bare word list into a spaced repetition script, and the algorithm started mixing entirely different definitions into the same study queue. The fix was adding a sense identifier field — essentially a number suffix like lead-1 and lead-2 — and making sure every example sentence tagged which sense it was using.
Another counter-intuitive detail: frequency lists and semantic usefulness are not the same thing. A word might appear extremely often in a frequency corpus but be almost useless for someone learning practical communication because it's locked inside specialized domains. I learned this the hard way when someone on our team built a word list purely from the COCA frequency rankings and wondered why intermediate learners couldn't actually use any of it in conversation. The solution was cross-referencing frequency data against the New General Service List and the Academic Word List, then applying a domain relevance filter based on what the target learner actually needed. For the actual compilation process, I started with an open-source frequency corpus, filtered out function words and proper nouns, then enriched each remaining entry by pulling definitions and collocations from the British National Corpus and WordReft as secondary sources. The whole pipeline took roughly six hours for a set of about two thousand high-frequency content words. Manual verification of the examples and register tags added another four hours, mostly because auto-generated examples from corpora sometimes produced grammatically correct but pragmatically weird sentences. If you're building this yourself and want a starting point, the Oxford 3000 and 5000 lists are publicly available through Oxford University Press for educational use, and the BNC Web 1.1 release gives you the raw frequency data to build custom tiers. The main bottleneck with these approaches is that they're static snapshots — language changes, new terms enter usage, and colloquial registers shift faster than any published list can track. If you need something current, you're better off running your own frequency extraction over a live corpus and updating quarterly rather than relying on a fixed publication.
Get the Full Details
The format I settled on exports cleanly to CSV, which feeds directly into Anki, Memrise, or any custom tool you might wire together. The fields map naturally to import templates, and the sense disambiguation I mentioned earlier prevents the kind of confusion that makes spaced repetition tools generate nonsensical review cards. It's not a perfect system — the register tags are inherently subjective, and collocation data from corpora can be sparse for less common words — but it's functional and fast to maintain.