Getting Started with Epic Cadence
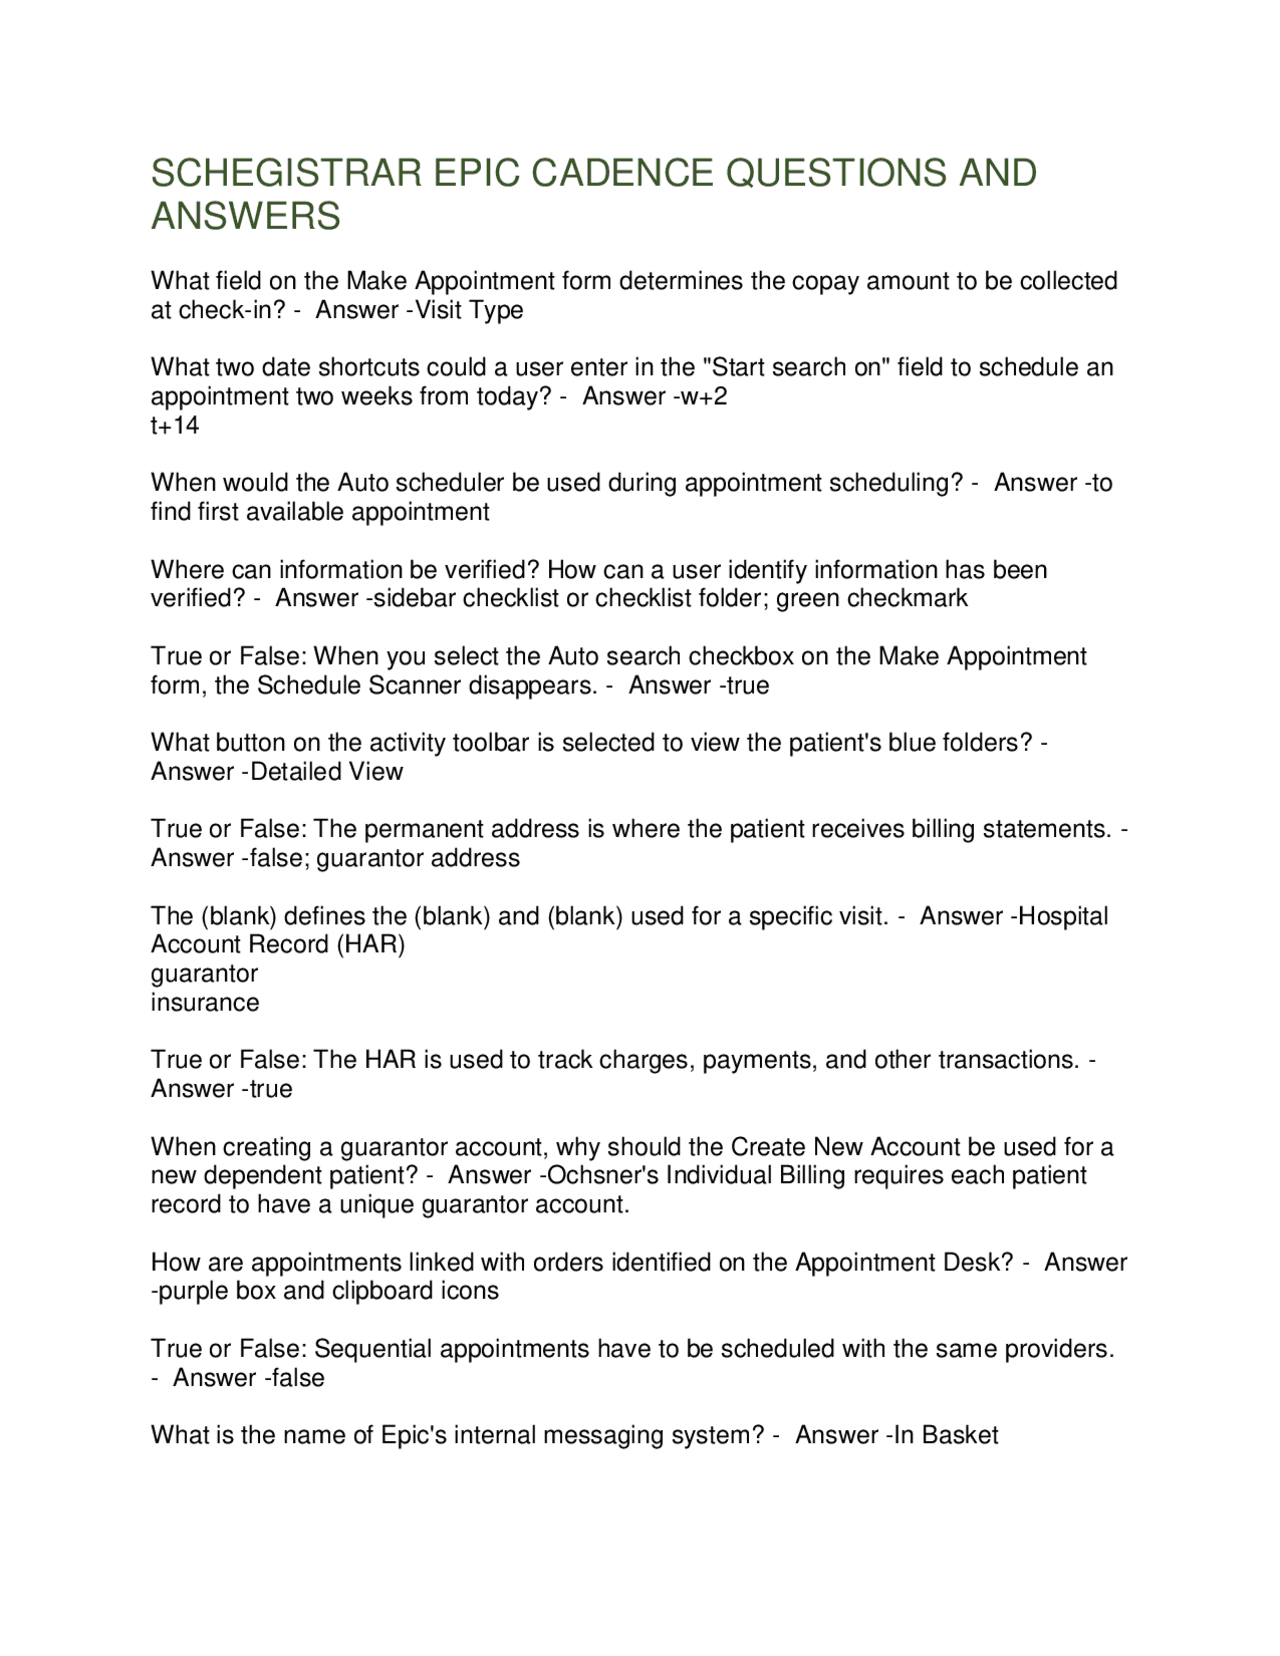
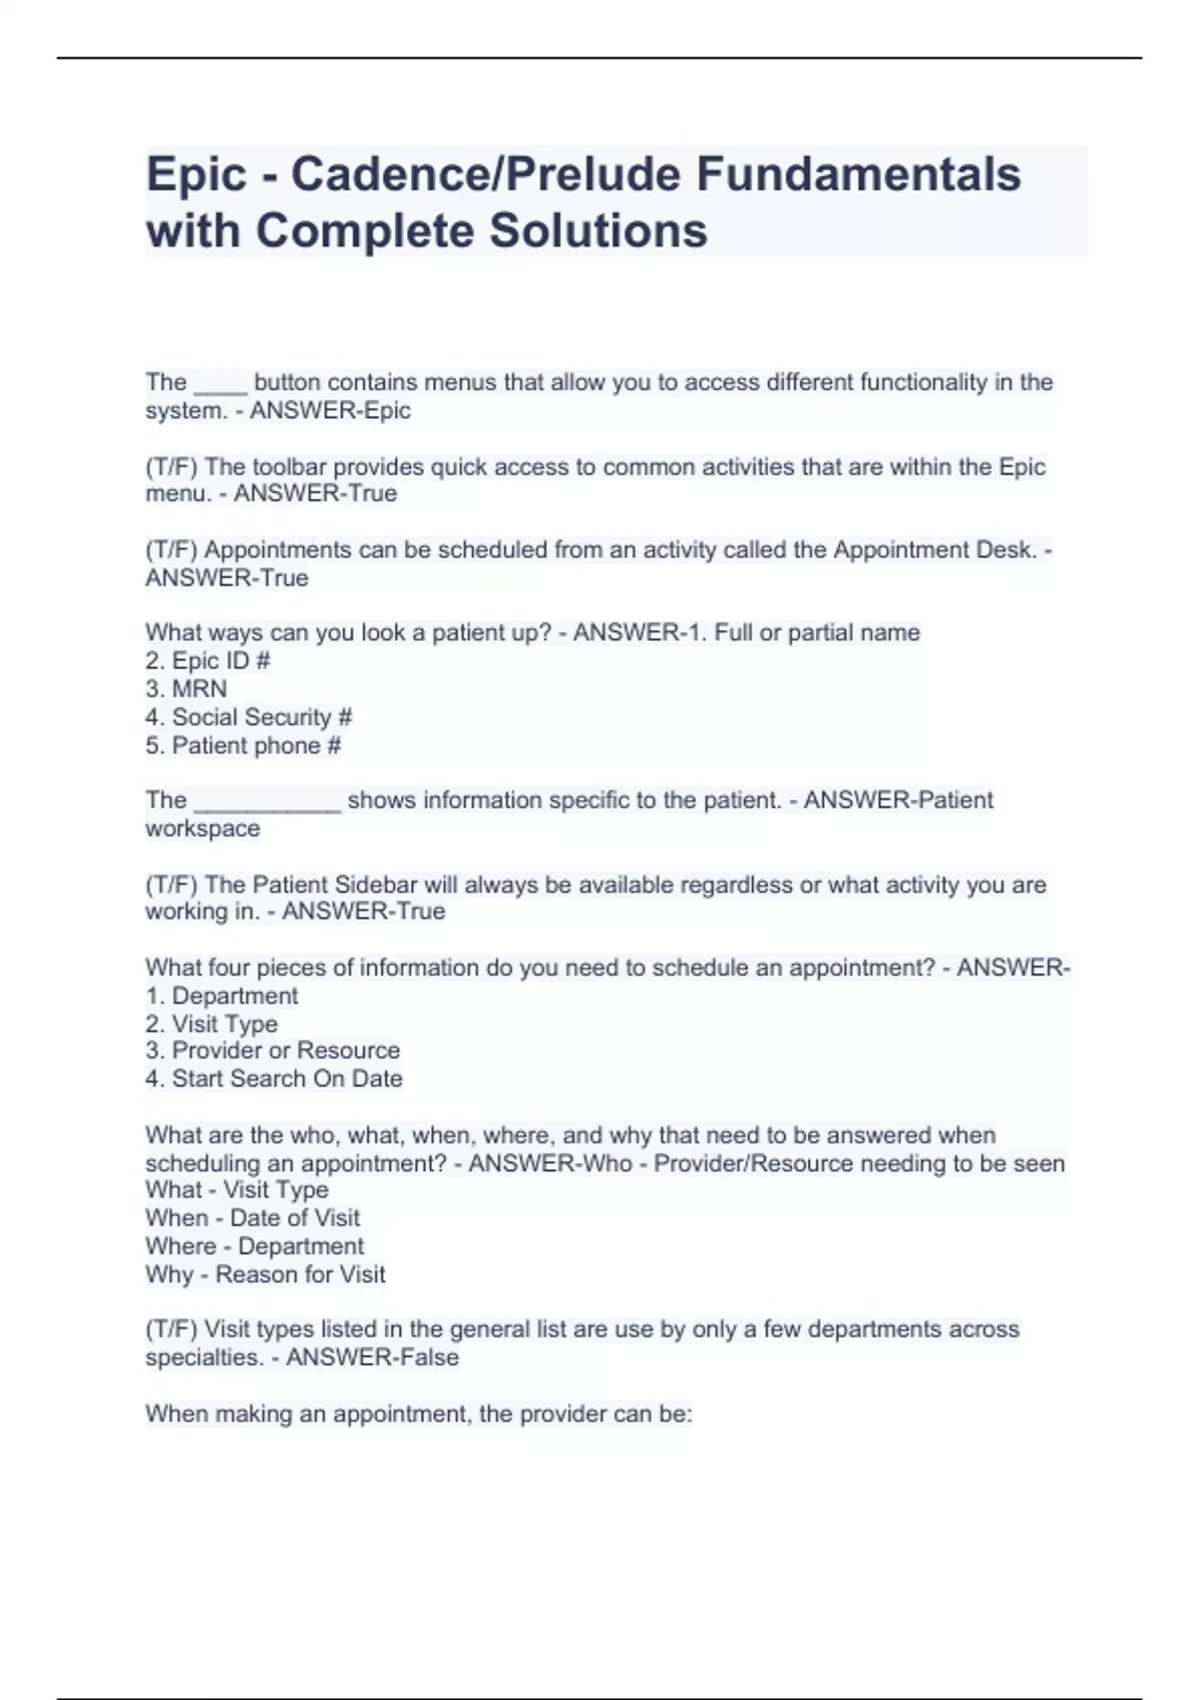
Epic Cadence is the data and analytics platform within the Epic Systems ecosystem. It pulls data from your EHR environment into a structured warehouse so you can run reports, build dashboards, and do population health work without putting pressure on your live clinical system. Most people find their first encounter with it during a go-live support window or when someone in analytics asks why the CPOE data doesn't match the reporting numbers. The training materials for Cadence are distributed through Epic's own portal system. If you're at an Epic customer site, you'll access them via MyChart or the internal helpdesk routing to Epic's learning management module. There isn't a single downloadable PDF you can find on Google. You need a valid Epic tenant ID and an account that's been flagged for analytics training. I've seen people waste three weeks trying to download a manual from a third party. That's not how it works. You either have Epic credentials or you don't. The core training track runs through Epic's self-paced learning modules. You'll start with the Cadence Foundation course, which covers the data model, the Clarity database structure, and how to navigate the reporting tools. From there you branch into Phrases, Trillium, and the newer Canvas dashboards. Each module has a knowledge check built in. Pass those, and you get a certificate that your Epic administrator can log in your personnel file. It's not optional if you plan to touch production reports.
Here's something beginners usually miss. The training manual treats every dataset as if you're starting from a clean install. Your environment almost certainly isn't clean. Someone in your organization renamed a column six months ago, or they pulled a custom extract for a grant and never documented it. The training won't warn you about that. I learned this the hard way when I was building a sepsis surveillance report and the training example pulled from a field called LACTATE_LEVEL while our database had it mapped as LACTATE_VAL under a different vocabulary set. The report ran without errors. The numbers were wrong. It took me four hours to trace it back to a mapping mismatch between the training data and our actual Clarity schema.
How the Training Actually Works
Epic Cadence Training Manual content is broken into sections that follow your daily workflow more than a textbook structure. You'll start with navigating the data dictionary. Then you move into pulling reports using the standard tools. After that comes the more advanced stuff like building your own phrases, understanding the wait times, and knowing when to escalate to an Epic analyst instead of burning your own query cycles. The hands-on exercises matter more than reading through the slides. I've watched people breeze through the video lessons and then completely freeze when they open the sandbox environment. The sandbox is your test bed. It has dummy patient data that looks real enough to practice with but won't mess up your production numbers if you run something backwards. Spend at least two hours there before you attempt anything against a live dataset. I usually tell new analysts to run the same report from the training module three separate ways in the sandbox. Once they can do that without checking the manual, they're ready to move forward. One thing the training materials don't emphasize enough is the difference between Clarity and Caboodle. Clarity is the real-time reporting database. Caboodle is the data warehouse layer with more history and some transformations applied. If you're pulling patient demographics or recent lab results, you usually want Clarity. If you're doing longitudinal analysis across years, Caboodle is where you look. Mix those up and your queries will either time out or return incomplete results. The training touches on this but doesn't drill into it the way you'd need for daily work.
Get the Full Details
Common Problems and Workarounds
Report timeouts are the most frequent complaint. They happen when you write a query that touches too many tables or pulls more rows than your session is allowed to process. The training manual shows you the basic WHERE clause filters. It doesn't always walk through why your date range filter isn't stopping the query from scanning millions of rows. The fix is usually adding an explicit date boundary on the encounter table before you join anything else. Start narrow, then expand. I once had a colleague who ran a simple medication reconciliation query that took forty minutes and generated a page count longer than a novella. He hadn't restricted the encounter date. Adding a single date range drop his runtime to under ninety seconds. Another issue is role-based access. You can complete all the training modules and still not be able to open certain datasets once you're in production. Your Epic administrator controls that. The training won't tell you which reports you'll actually have access to after you finish. That's a separate conversation with your site's analytics lead. I've had to turn people away from reports they thought they were trained for because their role didn't include that particular data domain. No amount of training bypasses the permission structure. Data latency is worth understanding early. Clarity isn't truly real-time. There's usually a lag between when an order enters the system and when it appears in the reporting database. Depending on your organization's extract schedule, that lag can range from fifteen minutes to several hours. If you're building a dashboard for clinical staff who need current information, you'll need to communicate that delay clearly. The training manual mentions it in passing. It's easy to overlook until someone complains that their report is showing yesterday's discharge list as today's.
What the Training Doesn't Cover
There are gaps. The Epic Cadence Training Manual gives you a solid foundation for standard reporting and basic analysis. It does not prepare you for custom data modeling, complex join logic across multiple Clarity and Caboodle tables, or integrating external data sources into your analytics pipeline. If your organization needs those capabilities, you're looking at additional specialized training or hiring someone who already has it. Phrases in particular require more than the introductory material. Once you move past the pre-built options and start writing your own, you'll run into syntax issues that aren't well documented in the standard curriculum. The Epic community forums help here, but they're not the same as formal training. I usually point people toward the Epic Discussion Forums and the vendor-specific communities where experienced analysts share working Phrase templates. The biggest limitation I'd flag is that Cadence is only as useful as your data quality. Clean training examples won't help if your source system has duplicate patient records, inconsistent coding practices, or fields that were left blank during data entry. I've spent entire projects cleaning mapping tables before I could even start building reports. No training manual fixes that. It's just part of working inside an Epic environment.
If you're serious about using this platform long term, budget time for ongoing learning rather than treating the initial training as a finish line. Epic updates their data model periodically. New fields get added. Old ones get deprecated. The training materials lag behind those changes by a few months at minimum. Your best approach is to complete the core modules, get comfortable in the sandbox, and then build a habit of checking the Epic release notes whenever your organization gets an upgrade notification. That's where the real learning happens after the certificate is on the wall.