Converting EPUB Files for Pure Text Reading
Most people hit a wall when they try to strip an EPUB down to clean prose. The files aren't simple text containers, and the formats you see online often break because they misunderstand the structure. I spent a long time dealing with this before I figured out a workflow that actually holds up. The core problem is that EPUB is a ZIP archive containing XHTML, CSS, fonts, images, and metadata. When people talk about Epub To Literature, they usually mean extracting the narrative content into a readable, reflowable format without all the code surrounding it. The literature aspect implies preserving paragraphs, chapter breaks, and proper typography while removing everything else. Here's what nobody tells you upfront: most converters treat an EPUB like a document-to-document transformation. That's wrong. It should be treated as a structural extraction problem. The text lives inside the .xhtml files, wrapped in tags that vary depending on how the publisher structured the original. Some use semantic markup. Some use nothing but presentational junk.
The workflow I actually use
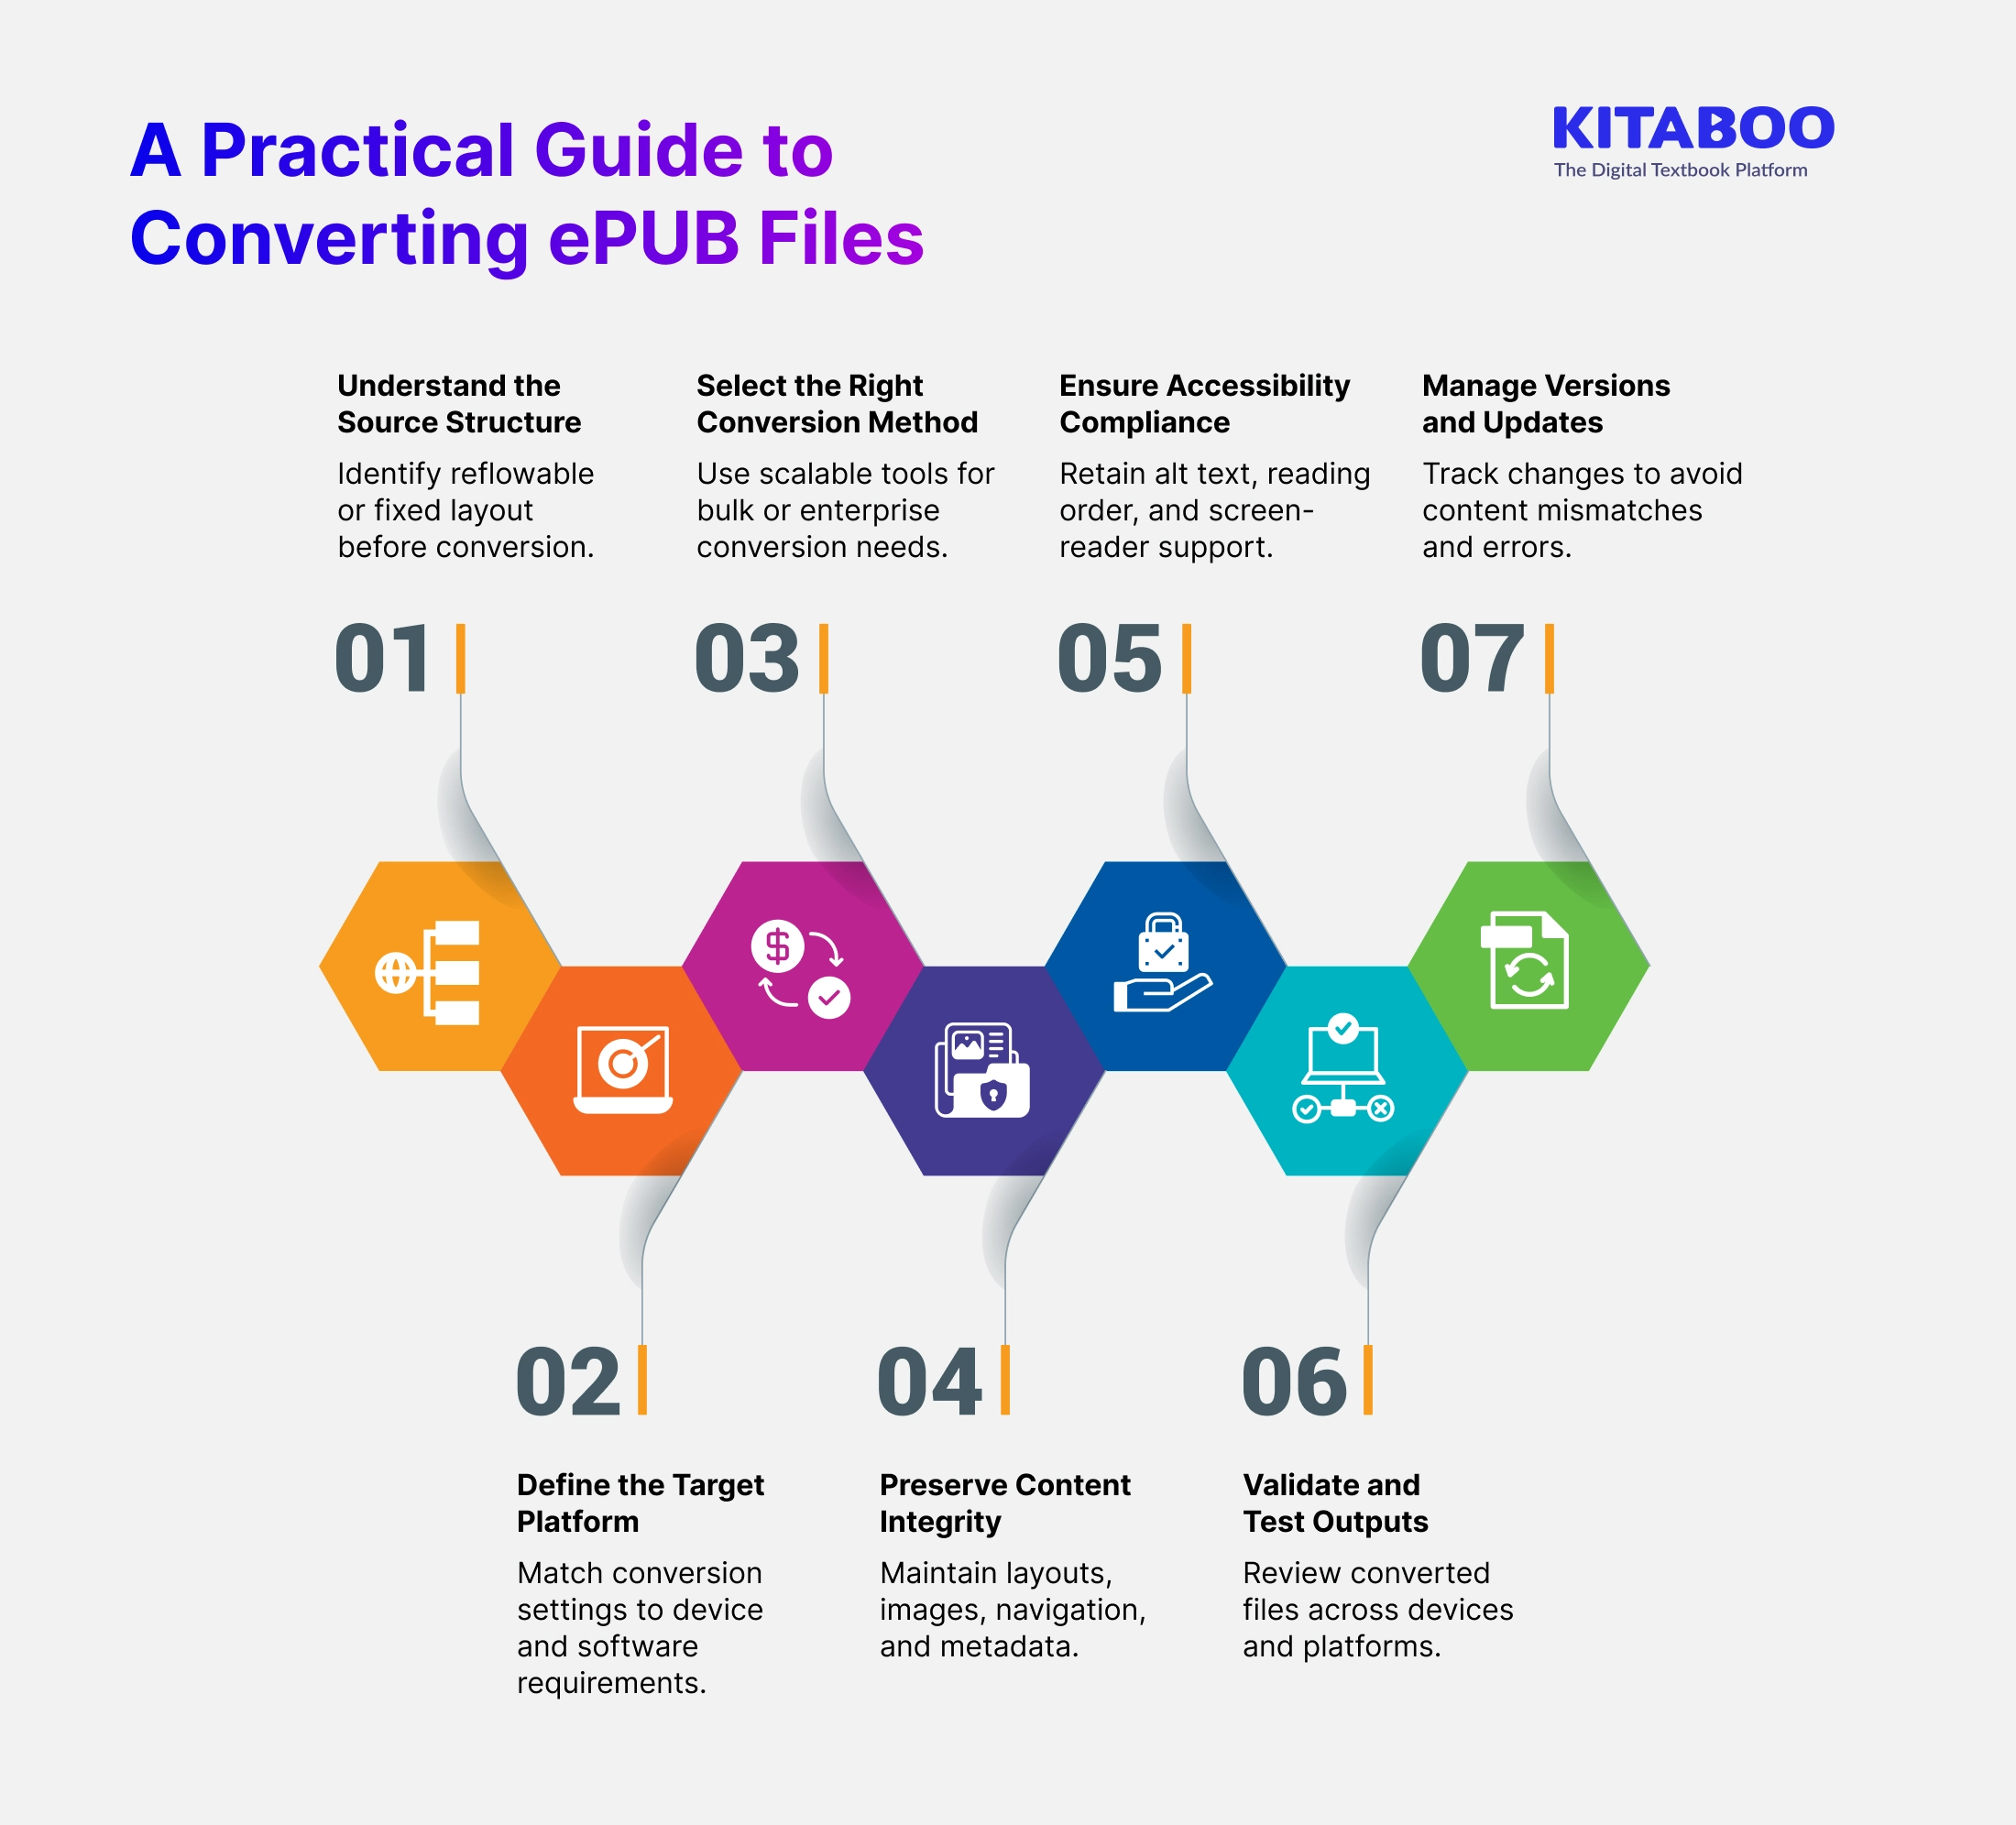
I start with Calibre. Not the GUI version for the whole thing, but specifically its conversion engine. Here's the sequence: First, run the EPUB through a cleanup pass. I use the "Tweaks" section and enable "Force use of auto-generated cover" if the metadata is broken, which it usually is. Then I add the option to "Preserve cover images" if you need them for archival purposes. This takes about two minutes. Second, I convert to MOBI or AZW3 format, not PDF. PDF destroys the reflowable nature entirely. The MOBI step acts as a filter that strips some of the heavier CSS baggage. I know that sounds counterintuitive, but Calibre's MOBI converter is surprisingly aggressive about cleaning up presentation elements. This step usually takes five to ten minutes for a standard novel.
Third, if I need pure plain text, I open the resulting MOBI in Calibre again and convert to TXT. But here's the part that matters: I set the "Remove spacing" option and enable "Strip document margins." Without these, you get massive empty gaps between paragraphs that make the output nearly unreadable.
Get the Full Details

A real edge case I ran into
I was processing a collection of public domain Victorian novels last year. The EPUBs had decorative chapter headers written as images rather than text. Every converter I tried either skipped those chapters entirely or rendered broken placeholders. The workaround was to use a Python script with the EbookLib library to read the raw content, extract any image-based headers, and replace them with placeholder text extracted from the filename or metadata. It took me about four hours to write the script, but it saved me from processing over two hundred files manually. The key insight there is that you should never assume chapter headers exist as actual text. In many commercial EPUBs, especially older ones that were OCR'd, decorative elements are images with zero textual content.
Common mistakes that wreck the output
The biggest issue I see is people using online converters. They're fast, yes, but they rarely handle embedded fonts, complex CSS grids, or multi-column layouts correctly. You'll get garbled text, missing characters, or sections that repeat. These tools are fine for quick conversions of simple books, but they fail on anything with real typographic detail. Another mistake is skipping the cleanup step. Raw EPUBs from publishers often contain style sheets that dictate font sizes, colors, and spacing that don't make sense outside the original rendering context. Running a CSS simplification pass in Calibre before final conversion removes most of this noise. It's a single checkbox.
When this approach doesn't work
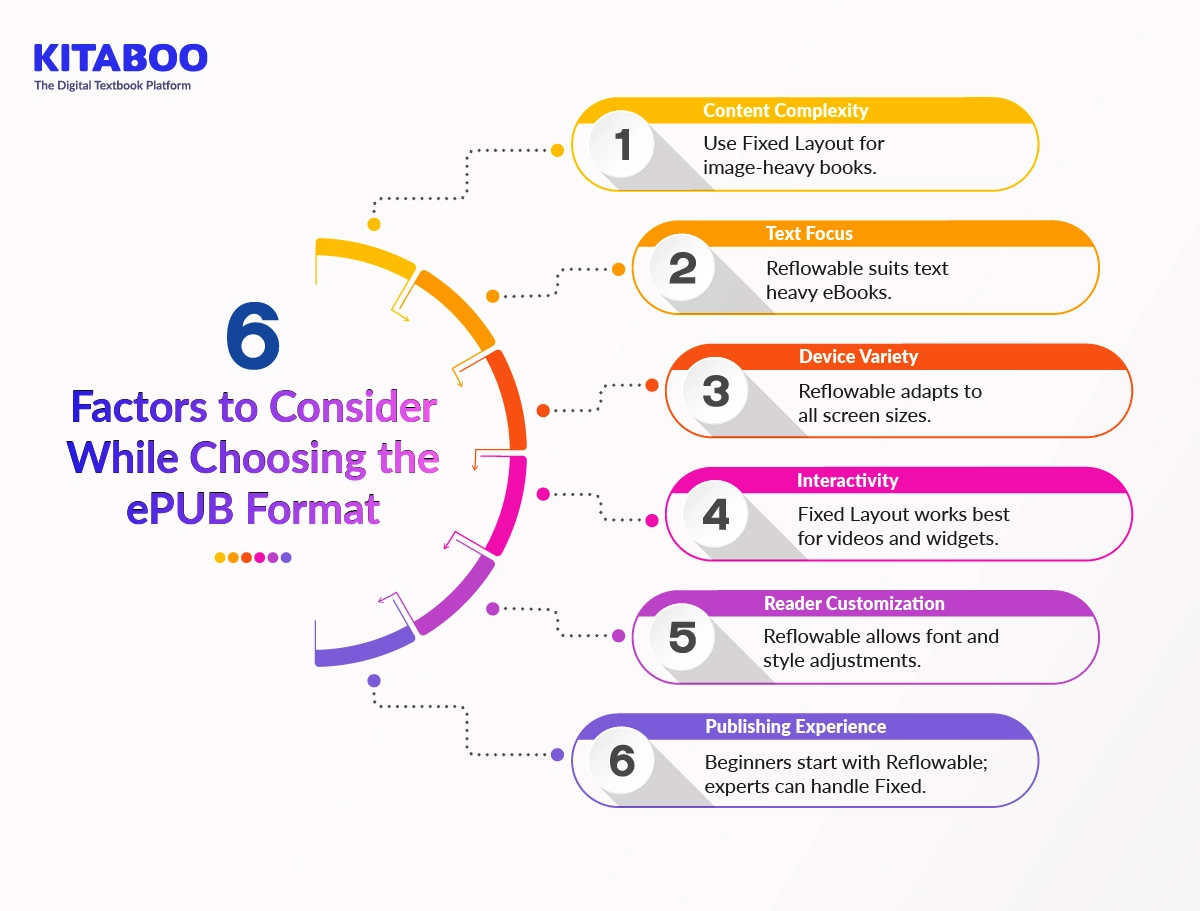
EPUBs built with complex interactive elements, JavaScript, or fixed-layout designs simply cannot be converted cleanly to plain literature format. Fixed-layout EPUBs are essentially images with text overlays. There's no meaningful extraction possible without specialized tools that most people don't have access to. If your source file has a fixed layout, you're better off using a dedicated accessibility tool or accepting that the content won't convert properly. Similarly, DRM-protected files are a non-starter. Calibre can't process them, and trying to strip DRM is both unreliable and illegal in many jurisdictions. Buy the right files or use library copies.

Getting started with Epub To Literature conversion
Download Calibre from calibre-ebook.com. It's free and available for Windows, Mac, and Linux. Start with a small test file, run through the steps I outlined above, and adjust the options based on your output quality. Once you understand what each conversion step does, you can process large batches efficiently. A typical 80,000-word novel goes through the full pipeline in under twenty minutes on most modern computers. The more files you process, the more you'll notice patterns in which publishers produce clean EPUBs and which produce garbage. You'll develop a sense for it. That's the only real expertise here.