The Equation For Standard Deviation
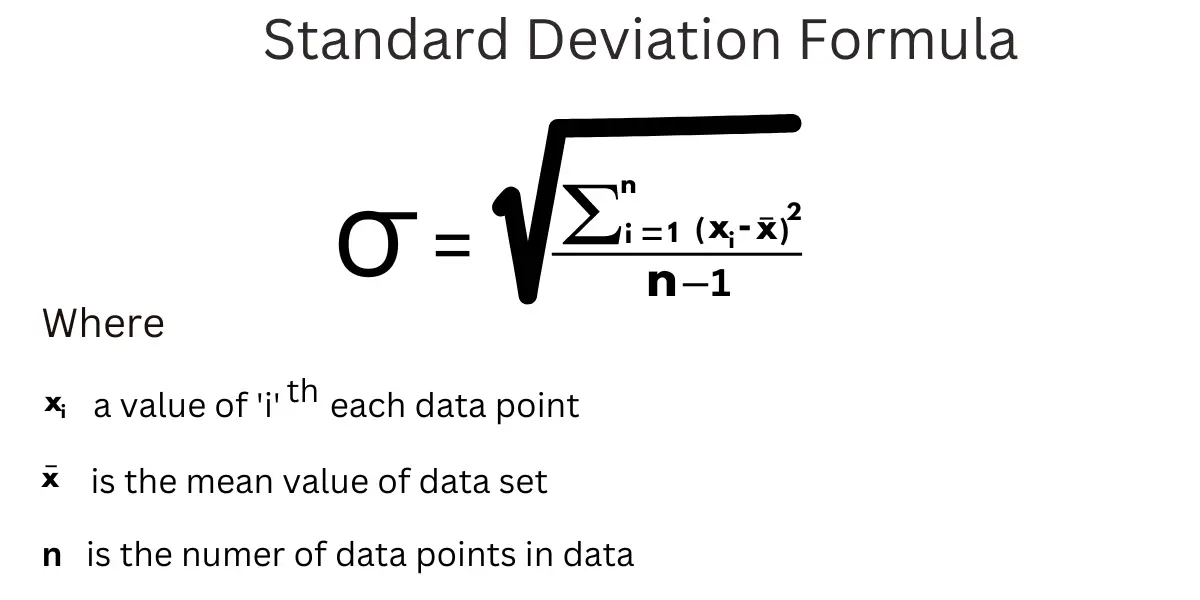
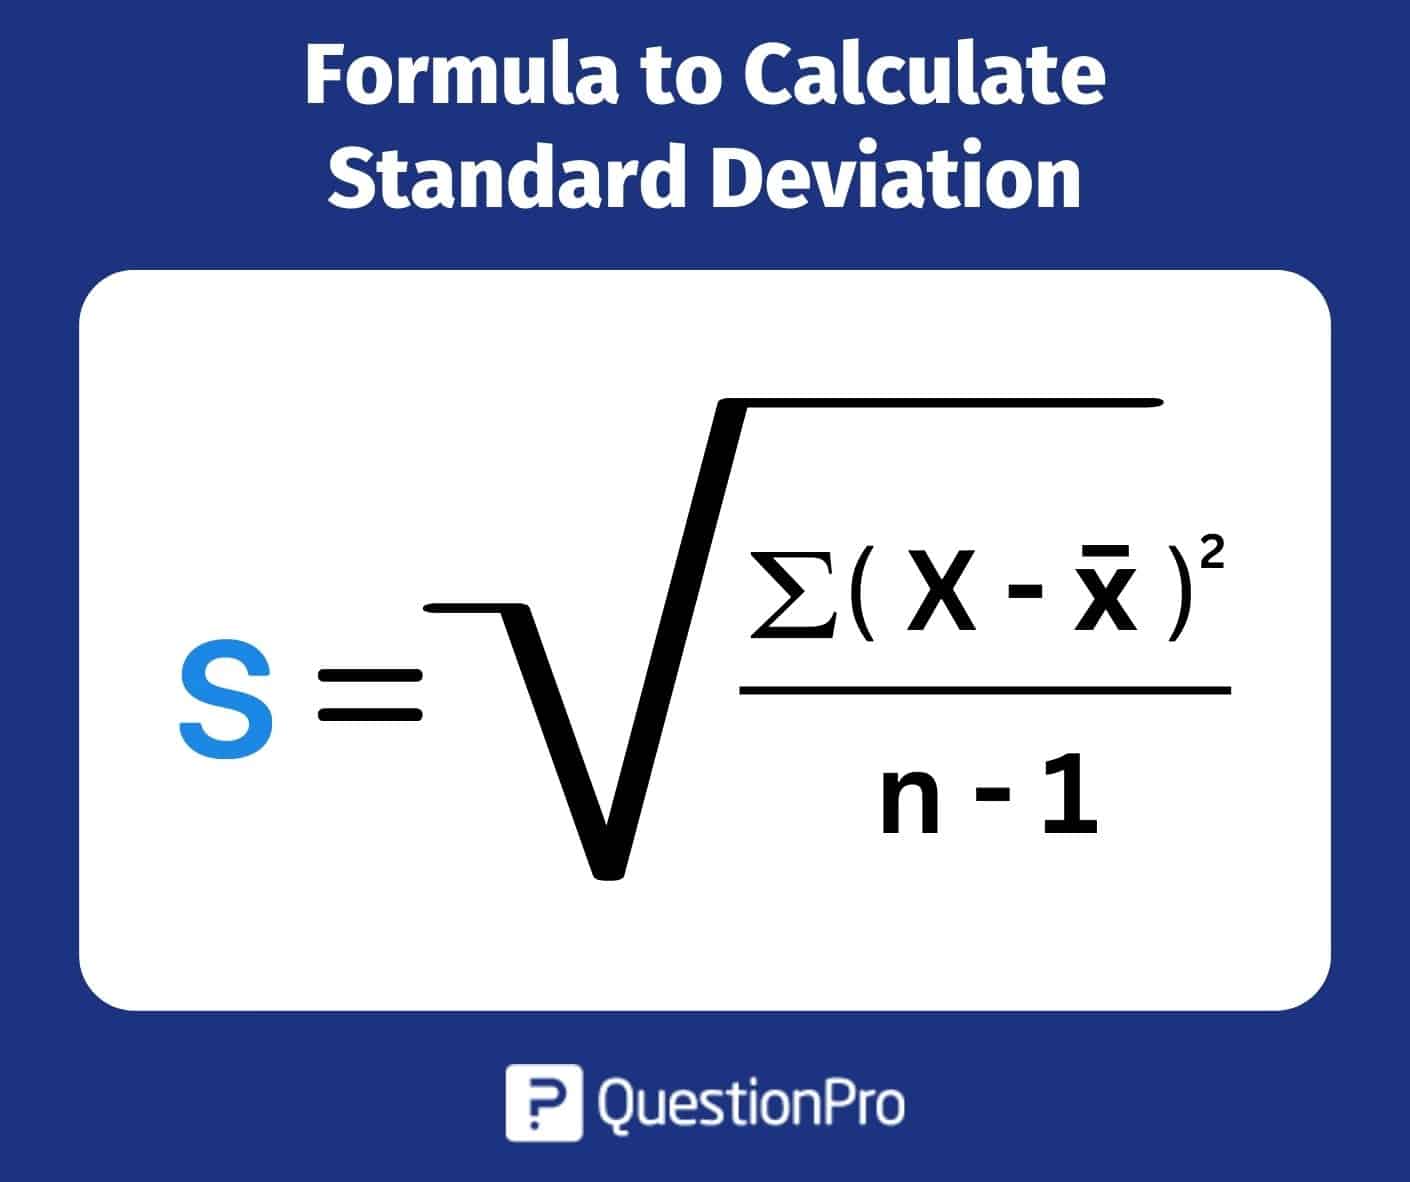
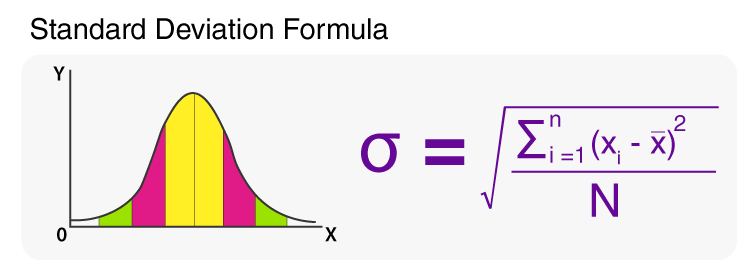
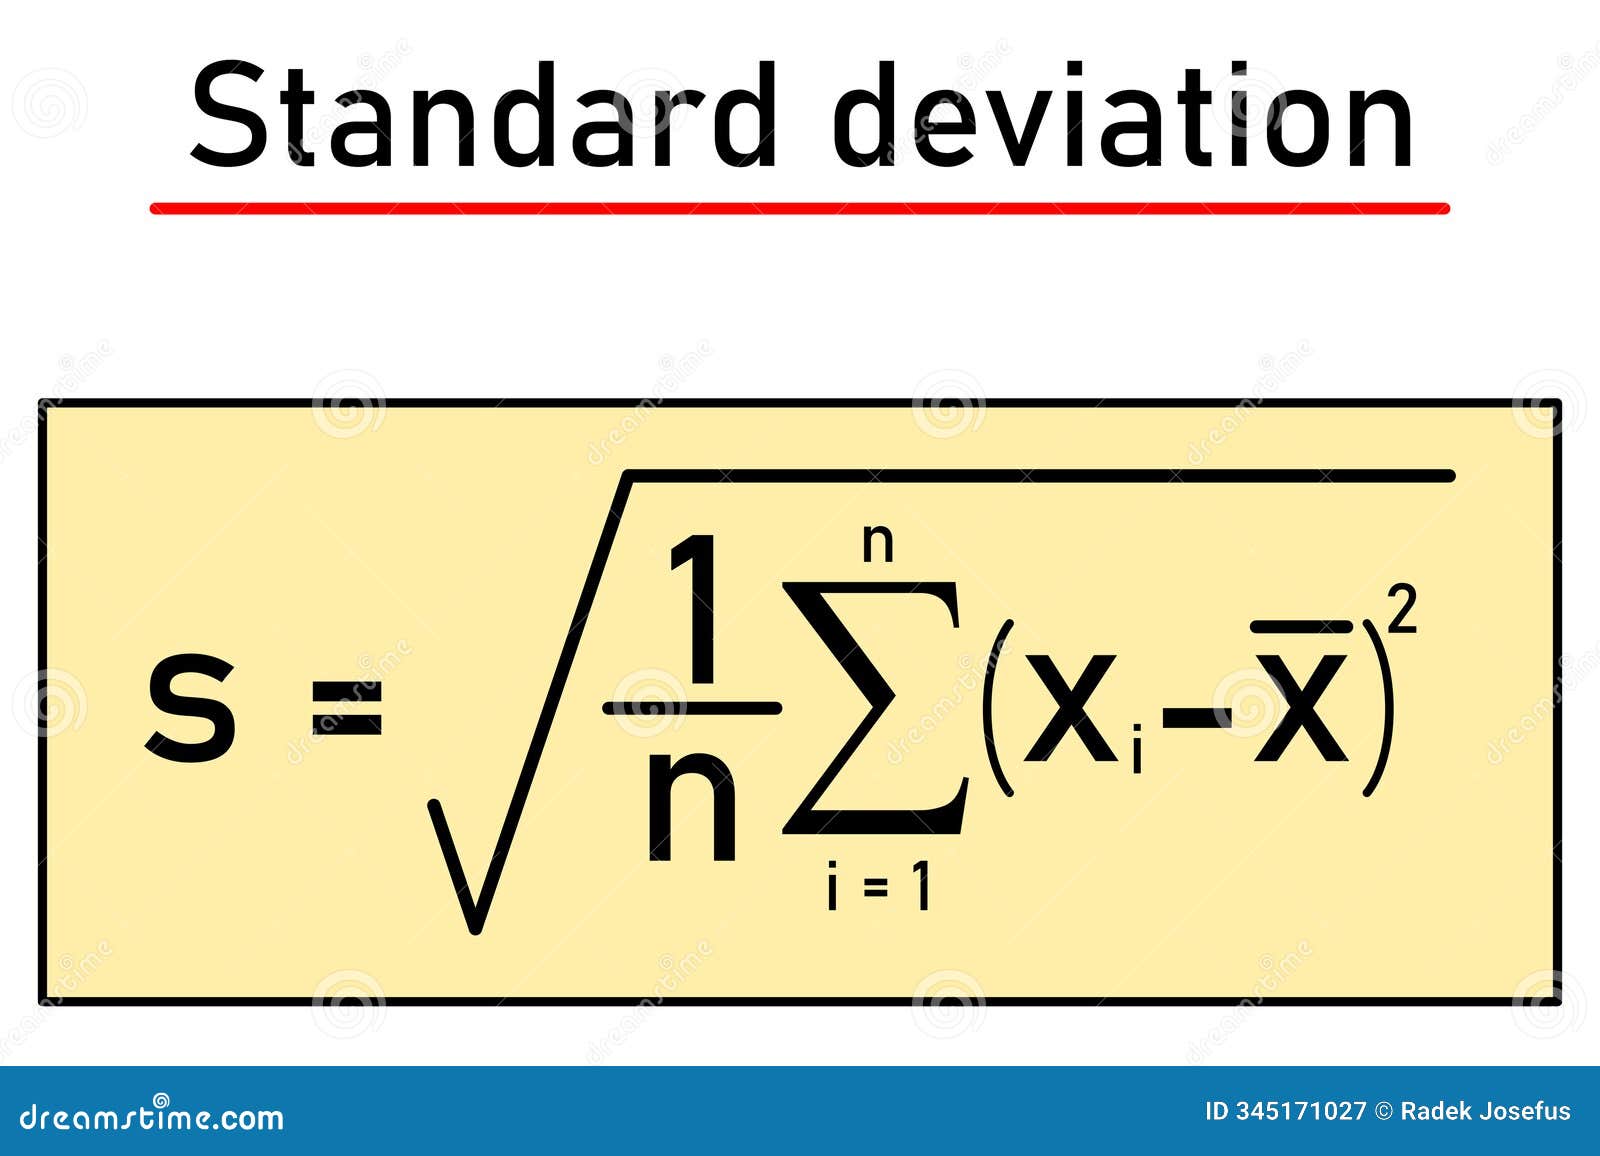
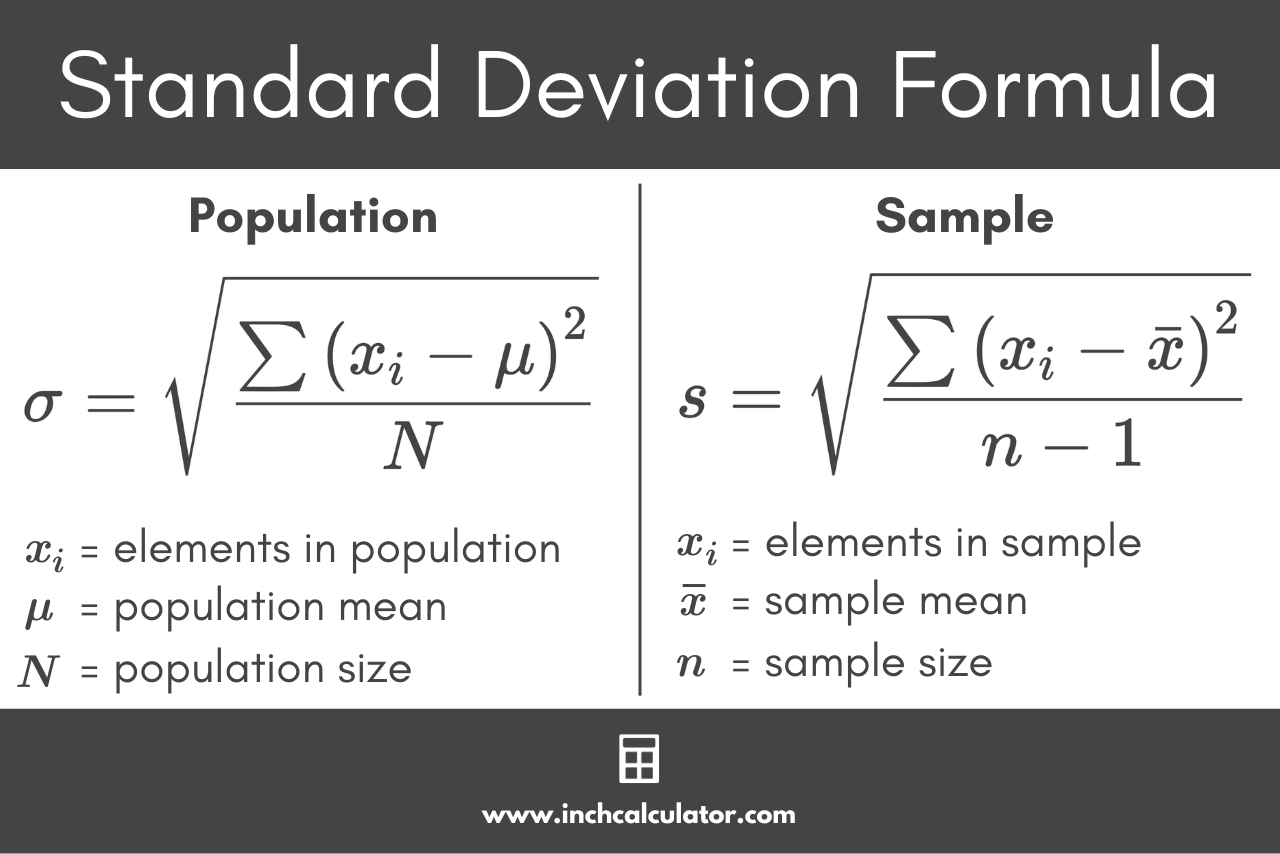
Most people look at the standard deviation formula and immediately zone out. It looks intimidating on paper because it's packed with Greek letters and exponents, but the concept itself is straightforward. You're essentially measuring how far data points spread away from the average. The formula I use in practice looks like this: = ((x - )² / N)
Breaking it down without dragging it out: you take each data point, subtract the mean, square that difference, add up all those squared values, divide by the count of data points, and then take the square root of whatever you get. The result is in the same units as your original data, which is important because it means you can actually interpret it.
Equation For Standard Deviation – Where People Go Wrong
The biggest mistake I see is mixing up sample standard deviation with population standard deviation. The population formula divides by N. The sample formula divides by N minus 1, known as Bessel's correction. If you're analyzing a dataset that represents your entire population, use N. If it's a sample from a larger population, use N-1. Using the wrong one will bias your result, usually making it too small when it should be slightly larger. Here's a specific case I ran into last year that caught me off guard. I was working with a dataset of manufacturing tolerances where most values clustered tightly around the target, but a handful of parts had extreme deviations due to a machine calibration error. The standard deviation came out to about 0.4 millimeters, which looked normal until I realized those few outliers were pulling the value up significantly. The fix was running a trimmed standard deviation calculation—excluding the top and bottom 5%—which gave me a much more representative number at 0.12 millimeters. If your data has obvious outliers, the standard deviation alone will mislead you about the actual spread of the bulk of your data. Another thing that trips people up is squaring the deviations before summing them. That's not arbitrary. Squaring penalizes larger deviations more heavily than smaller ones, which is exactly what you want because a value that's three standard deviations away from the mean is meaningfully more unusual than one that's one standard deviation away. The squaring step is what gives the standard deviation its sensitivity to outliers, which is both its strength and its weakness.
Get the Full Details
A Quirk You Should Know About
Standard deviation is not scale-invariant in a way that most people expect. If you multiply every value in your dataset by 10, the standard deviation also multiplies by 10. But if you add a constant to every value—say, converting Celsius to Fahrenheit by adding 32—the standard deviation stays exactly the same. Only scaling changes it, not shifting. This matters when you're comparing standard deviations across datasets measured in different units or with different baselines. There's also the edge case of zero-variance data. If every single value in your dataset is identical, the standard deviation is zero. That's mathematically clean but practically useless for anything beyond confirming perfect uniformity. In fields like quality control, a standard deviation of zero is actually suspicious—it often means you're rounding too aggressively or the measurement instrument lacks sufficient resolution, not that the process is truly flawless. If you need something more robust than standard deviation for datasets with heavy tails or significant outliers, consider the median absolute deviation. It's less sensitive to extreme values and gives you a clearer picture of central spread when your data isn't well-behaved. Standard deviation is the default for a reason, but it's not the answer for every situation.