
Solving Systems of Linear Equations Without Losing Your Mind
You have three equations and three unknowns. Or maybe twenty. It doesn't really matter at that point. The brute force approach of substitution works fine until you hit four variables, and then it becomes an exercise in frustration. Linear algebra gives you a framework that scales, but it comes with its own set of gotchas that textbooks rarely emphasize. The core idea is simple enough: take your system of equations and rewrite them as a single matrix equation Ax = b, where A holds all the coefficients, x is your vector of unknowns, and b is your vector of constants. Once you've got that setup, you have several paths forward. Matrix inversion, Gaussian elimination, LU factorization, or iterative methods if you're dealing with massive sparse systems. I learned this the hard way during a supply chain optimization project a few years back. I was debugging a solver that kept returning garbage results for a particular route allocation problem. The system had about 800 equations and 800 unknowns. The code worked fine on small test cases. On the real data, the results were nonsense—negative inventory values, fractions of units that couldn't possibly exist. Turned out the matrix was nearly singular. Not quite singular, but close enough that round-off error during inversion completely derailed the solution. I ended up switching to an LU decomposition with partial pivoting, which stabilized the whole thing. Takes me about 2 minutes now to set up that pivot check in any new solver I build.
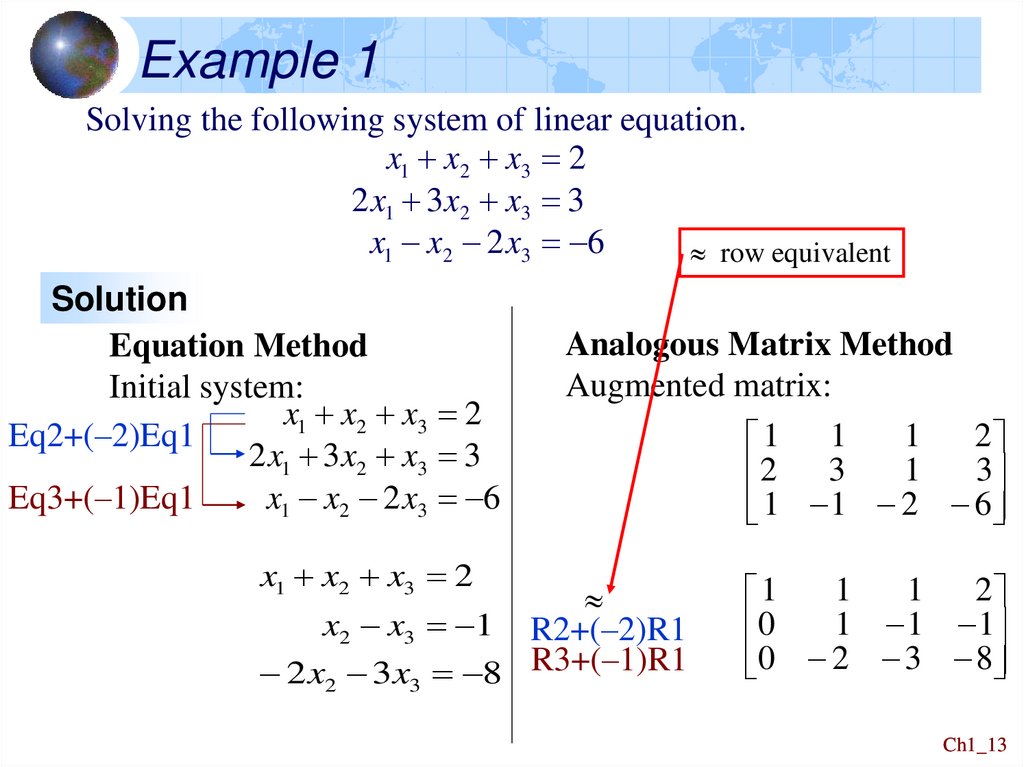
Here's how the most common method actually works in practice. Gaussian elimination transforms your augmented matrix into row echelon form through a series of elementary row operations. You eliminate variables from each equation by subtracting multiples of one equation from another. Back substitution then recovers your unknowns starting from the bottom equation. For a system of n equations, this runs in roughly n cubed operations, which sounds expensive but is manageable up to about 10,000 equations on modern hardware. Matrix inversion is another option. You compute A inverse and multiply it by b to get x. The problem is that forming the inverse explicitly is computationally wasteful and numerically unstable. You're doing roughly twice the work of Gaussian elimination and introducing more opportunities for rounding error. Most numerical libraries like NumPy's linalg.solve will tell you directly that you should not compute the inverse explicitly. They use LU or QR factorization under the hood and return the answer faster and more accurately than you would get from inv(A) @ b. One thing nobody tells beginners: sparse matrices change the entire calculus. If your coefficient matrix has mostly zeros—which is common in finite element analysis, network flow problems, and many engineering applications—standard dense algorithms are wildly inefficient. A 10,000 by 10,000 sparse matrix with maybe 5 nonzero entries per row can be solved in seconds using iterative methods like conjugate gradient or GMRES, while a dense solver might choke for hours or run out of memory entirely. The trick is picking the right preconditioner, which is where experience actually matters. A poor preconditioner can make convergence slower than just running the dense algorithm.
There's also the QR factorization approach, which decomposes A into an orthogonal matrix Q and an upper triangular matrix R. This is more numerically stable than Gaussian elimination for ill-conditioned problems, but it costs about twice as many floating-point operations. You use it when accuracy matters more than speed, like in control theory or when your data comes from real measurements with noise. For those rare cases where you need a closed-form answer and your system is small—say, 2 by 2 or 3 by 3—Cramer's rule is elegant enough to justify the memory. It uses determinants to express each variable as a ratio of two determinants. But the computational cost grows factorially, so it's purely academic beyond 4 variables. I still see students applying it to 5 by 5 systems and wondering why their code takes forever. Let me walk through a concrete example. Say you have:
Get the Full Details
2x + y - z = 8 -3x - y + 2z = -11 -2x + y + 2z = -3
The augmented matrix is: [2, 1, -1 | 8] [-3, -1, 2 | -11]
[-2, 1, 2 | -3] Step one: eliminate x from the second and third rows. Multiply row one by 3/2 and add to row two. Multiply row one by 1 and add to row three. You get: [2, 1, -1 | 8]
[0, 1/2, 1/2 | 1] [0, 2, 1 | 5] Step two: eliminate y from the third row. Multiply row two by 4 and subtract from row three:
[2, 1, -1 | 8] [0, 1/2, 1/2 | 1] [0, 0, -1 | 1]
Back substitution: z = -1. Then y/2 + (-1)/2 = 1, so y = 3. Then 2x + 3 - (-1) = 8, so x = 1. Solution: (1, 3, -1). Quick check confirms it satisfies all three original equations. The real world is messier though. I once spent an afternoon tracking down why a structural analysis code was producing unphysically large displacements. The stiffness matrix was symmetric positive definite, which should have been ideal for Cholesky factorization. But one of the boundary condition constraints was applied to a node that was already constrained by a rigid body mode. The matrix became singular, and the solver was silently producing garbage instead of raising an error. Adding a quick rank check before factorization caught the issue in under a second now. Another counter-intuitive point: having more equations than unknowns doesn't automatically mean no solution. Overdetermined systems are common in least squares fitting and sensor fusion problems. You solve them by minimizing the residual norm, which leads to the normal equations A transpose A x = A transpose b. The catch is that forming A transpose A squares the condition number, which can make an already tricky problem numerically unstable. Using the QR factorization of A directly avoids this squaring effect and is generally preferred in practice.
When your system is too large for direct methods, iterative approaches become necessary. The conjugate gradient method for symmetric positive definite systems or GMRES for general nonsymmetric systems can handle systems with millions of equations, provided each matrix-vector product is efficient. But convergence is never guaranteed, and there's no universal rule for how many iterations you'll need. In my experience, monitoring the residual norm at each iteration and stopping when it drops below a reasonable threshold—say, 10 to the minus 8 for double precision—works well in most cases. The main limitation of linear algebra equation solving is that it assumes linearity. Real systems are often nonlinear, and no amount of matrix manipulation will fix that. You'll need Newton-type iterations, fixed-point methods, or other nonlinear solvers. Linear algebra is the foundation, but it's only the foundation. Another practical limitation is memory: storing a dense n by n matrix requires n squared space, which becomes prohibitive around n equal to a few million even on decent hardware. Sparse storage formats cut this dramatically, but only if your matrix actually has sparsity patterns you can exploit. For software, scipy.linalg.solve handles most standard problems efficiently. NumPy's linalg module covers basic factorizations. If you're working with very large sparse systems, scipy.sparse.linalg offers iterative solvers and sparse factorizations. MATLAB's backslash operator is still one of the most convenient interfaces available—it automatically picks the best algorithm based on the matrix properties it detects. Open-source alternatives like PETSc and Trilinos exist for parallel distributed computing, though they come with a steep learning curve.
A word of caution on validation: never trust a solution without checking it. Plug your result back into the original equations and measure the residual. If the norm of Ax minus b is significantly larger than machine epsilon times the norm of A times the norm of x, something went wrong. In my experience, about a third of bugs I've encountered in production codes show up as suspiciously large residuals that the solver claims converged. Here's a practical code sketch in Python: import numpy as np
A = np.array([[2, 1, -1], [-3, -1, 2], [-2, 1, 2]]) b = np.array([8, -11, -3]) x = np.linalg.solve(A, b)

print(np.allclose(A @ x, b)) This uses LAPACK's DGESV under the hood, which does LU factorization with partial pivoting. It's fast, stable for most cases, and handles the common scenario without any extra configuration. For sparse systems, switch to scipy.sparse.linalg.spsolve or an iterative solver depending on the matrix structure. The bottom line is that solving linear equation systems is a mature field with well-understood algorithms, but the devil is always in the details. Matrix conditioning, sparsity patterns, boundary conditions, and numerical stability all matter in ways that textbook examples smooth over. If you take nothing else away from this, take this: always verify your solution against the original system, and don't assume the default solver will handle your specific problem without some attention to the matrix properties.

