Why Most People Never Actually Read Their Error Codes Manual
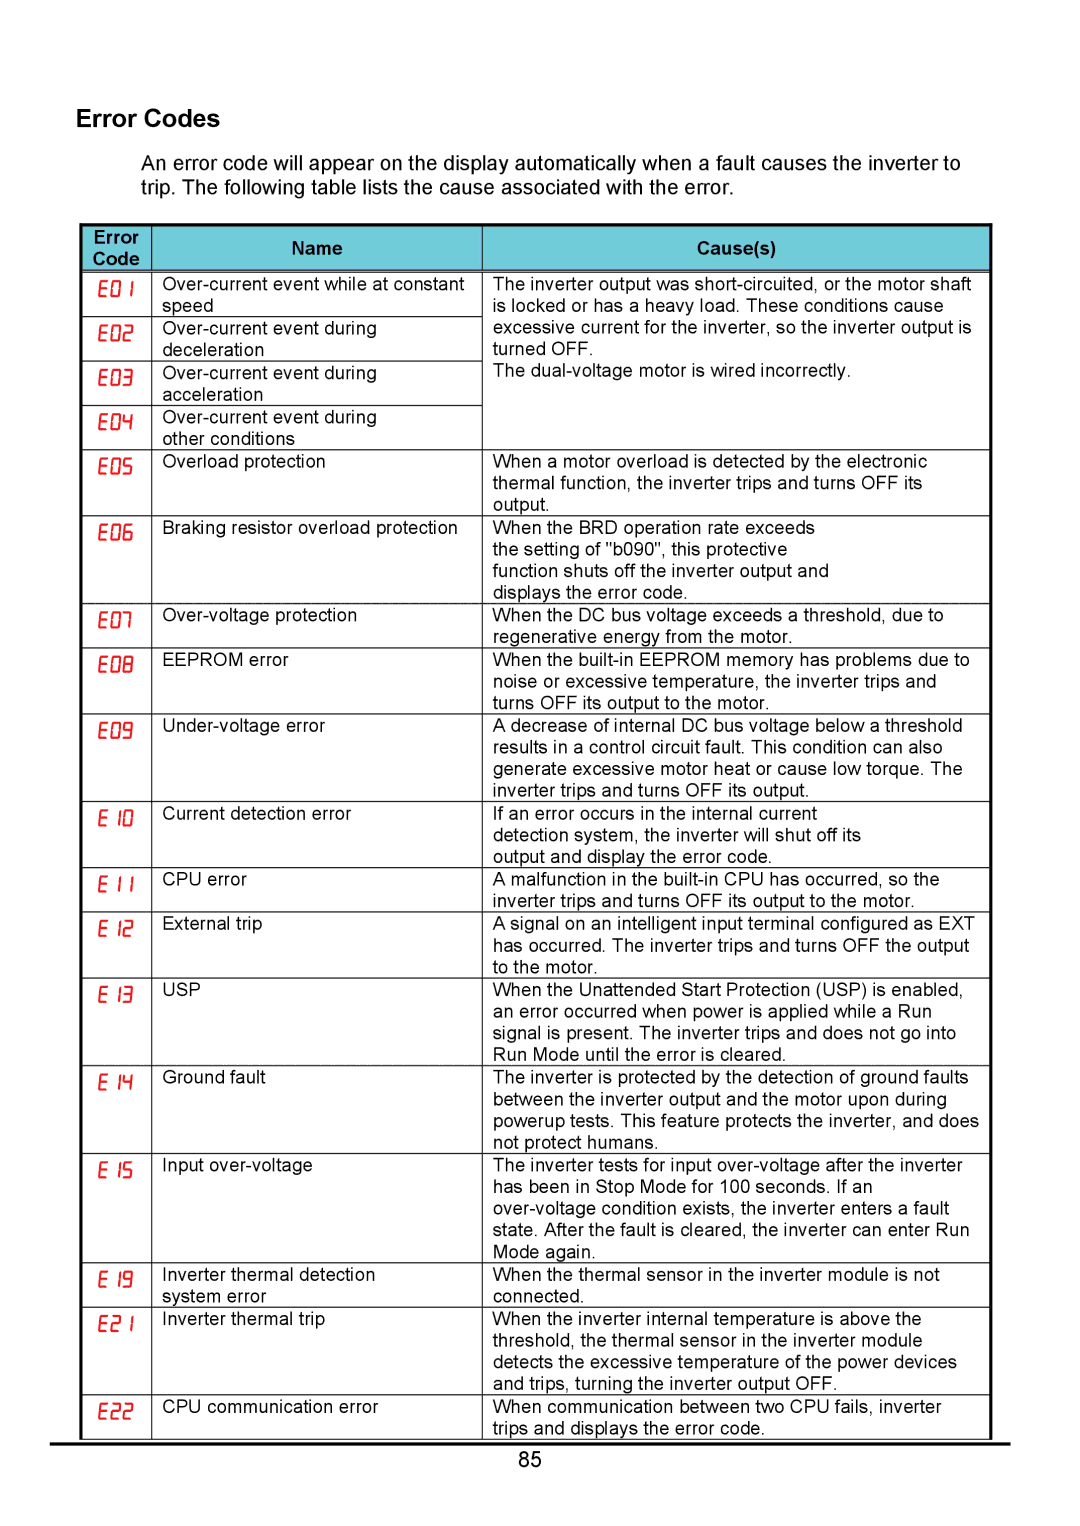
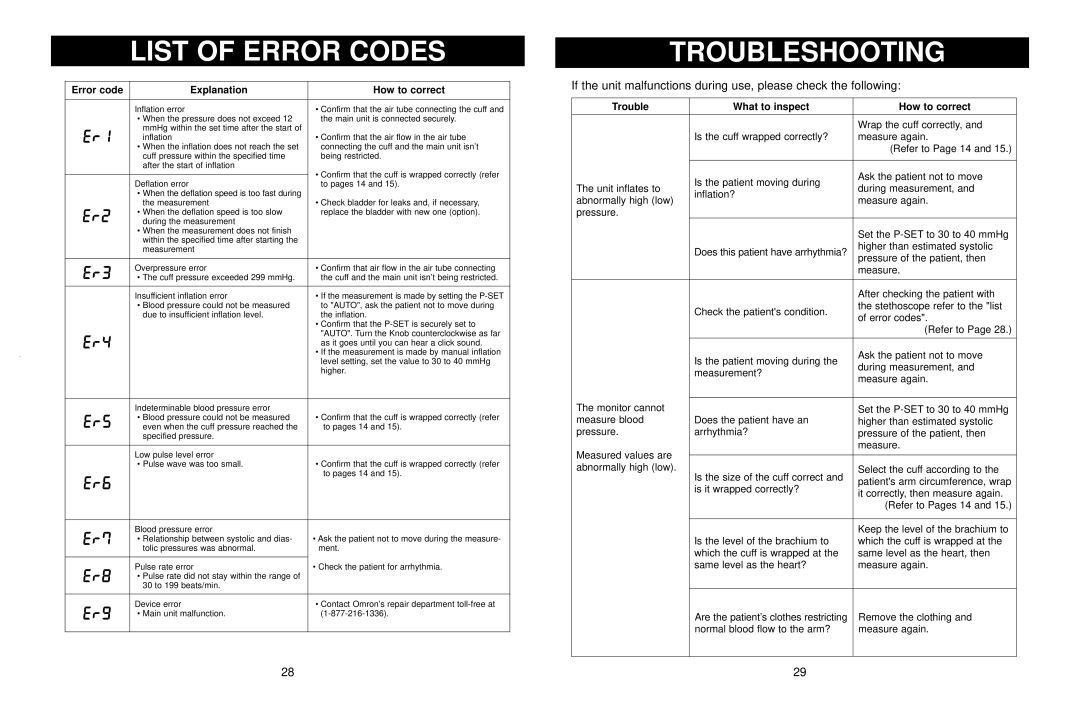
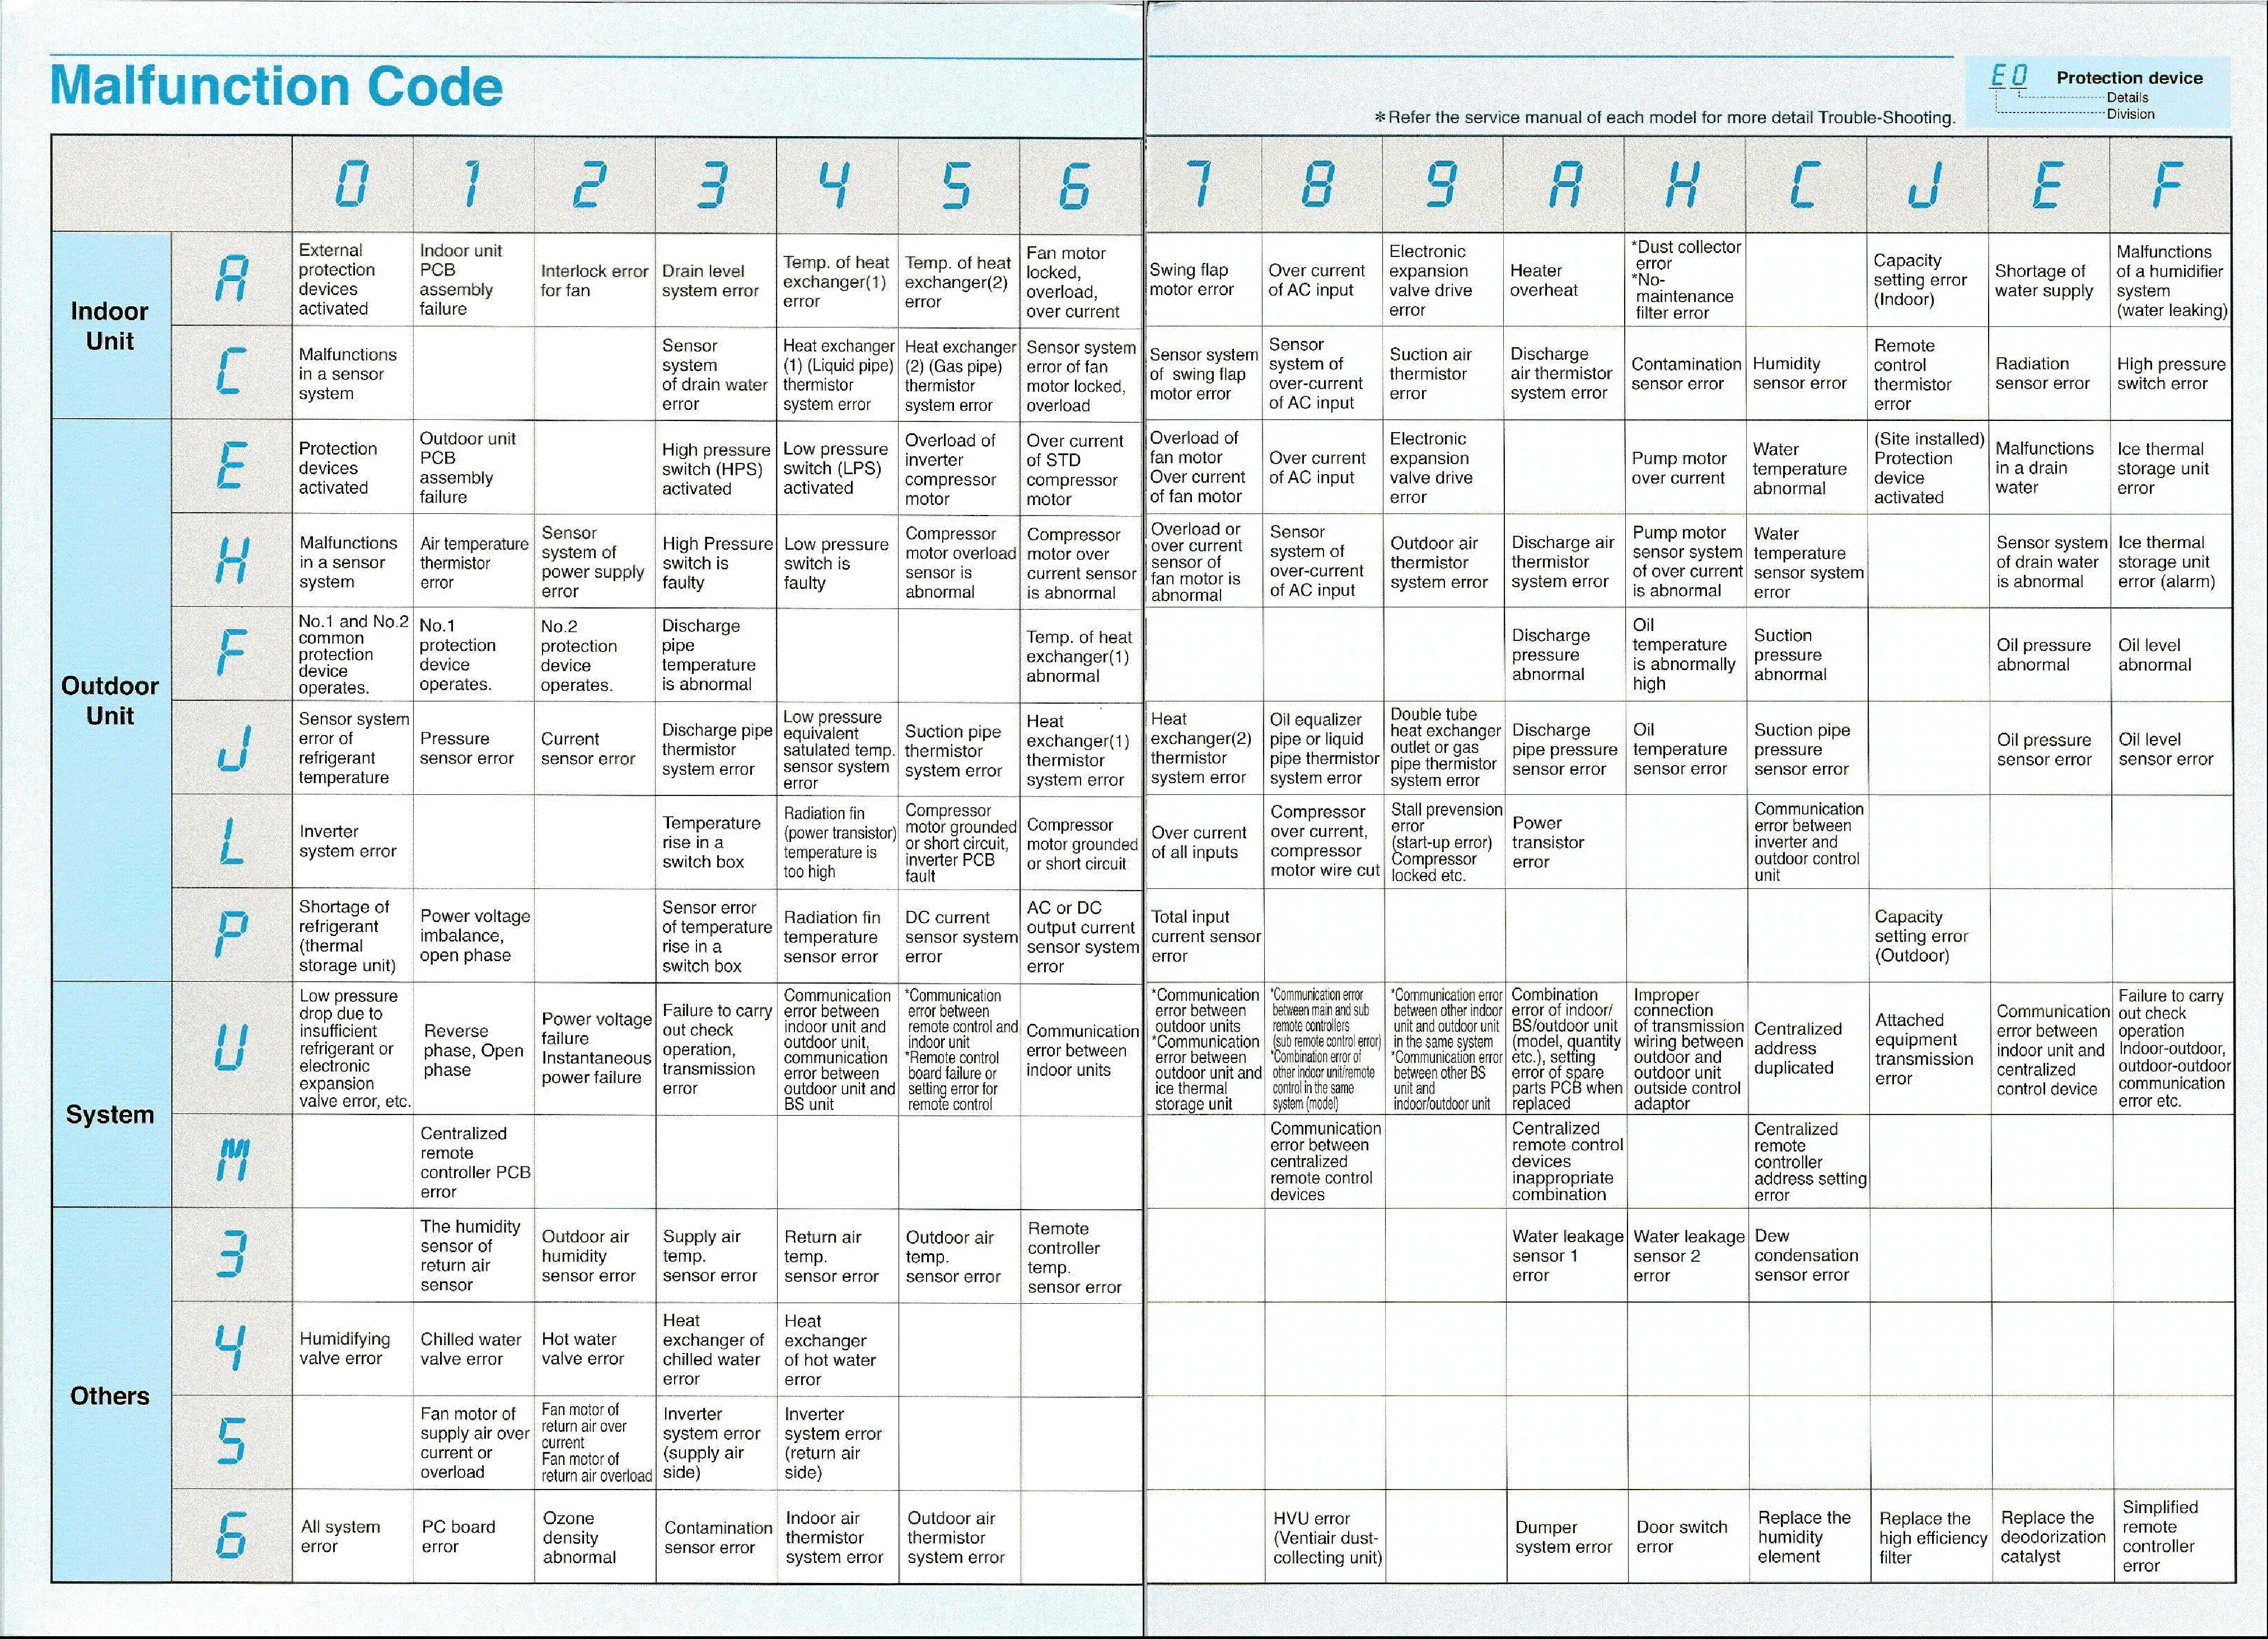
I spent three days chasing a silent failure on a production server last year. The logs showed code 0x80070005 appearing intermittently, nowhere near enough to get caught by automated monitoring. I spent hours going through every configuration file, restarting services, changing permissions. Turned out the solution was already documented in the Error Codes Manual that came with the software installation. I'd never opened it. This happens constantly, and not just in enterprise environments. Error codes are how systems communicate failures to humans who aren't machines. They exist because something went wrong, the program couldn't recover, and someone needed a way to tell you what happened without throwing an entire stack trace at your screen. The manuals that document these codes are usually an afterthought during development, rarely updated when new versions ship, and almost never designed with the person who's panicking at 2 AM in mind.
How to Read an Error Codes Manual Like Someone Who Has Fixed Real Systems
Start with the code itself. A hexadecimal code like 0xC000007B means something completely different from E_FAIL or ERR_CONNECTION_RESET just because of the prefix. The prefix tells you which subsystem generated it. Microsoft uses 0x8007 prefixes for system-level errors where the second half is actually a Windows error code wrapped in a generic failure container. Unix-style errors starting with E_ are POSIX compliant and generally more descriptive. When you see a proprietary prefix like ERR_ or CUSTOM_, assume the vendor owns the taxonomy and their documentation might be scattered across multiple pages. The trick most people miss is that error codes often have layered meanings. The base code tells you what category of failure occurred. The subcode tells you the specific condition. And the context, which nobody documents properly, tells you whether it's transient or permanent. I once saw a database replication error where the same code appeared with two different resolutions depending on whether it showed up during a bulk insert or a routine query. The manual listed it once with a single workaround that only worked for one scenario. I had to figure out the second scenario by testing, reading commit logs, and talking to a support engineer who'd been there six years. Here's a practical workflow I use now instead of guessing. First, grab the exact error code with its full prefix and any subcodes. Second, search the manual using the code as a literal string, not a keyword. Third, check the version number of whatever software produced the code against the manual's version. A lot of errors get renumbered between minor releases. Fourth, if the manual doesn't help, search for the code combined with the product name and the word "intermittent" or "random" because those are the ones people usually bother posting about on forums.
What Error Codes Manuals Get Wrong (And What to Do About It)
Most manuals list error codes in numerical order, which is useless when you're looking for something specific. Some list them alphabetically by description, which creates a different problem because the description might not match what you see on screen. The most useful manuals I've encountered organize by severity first, then by component, then by code within each section. If yours doesn't do this, you need to build your own cross-reference. I keep a simple spreadsheet with five columns: error code, description from the manual, actual symptom I observed, root cause, and resolution. It takes about twenty minutes to set up and saves me hours the next time the same code appears. I've filled this for three different enterprise platforms now, and the spreadsheet for my current job has over four hundred entries accumulated over eighteen months. About thirty percent of those codes never appeared in the official manual at all. The honest assessment here is that most Error Codes Manual documents are maintained by technical writers who aren't on-call engineers. They're accurate at release time and slowly drift out of sync as patches introduce new failure modes. The manual for version 3.2 of a common middleware product I work with listed approximately sixty percent of the errors we encountered in production during the first quarter after upgrade. That's not unusual. Budget time to verify the manual against your actual environment before you trust it for anything critical.
Get the Full Details

Download and Access
Official manuals are typically hosted on vendor portals behind login walls. Third-party aggregators sometimes scrape them, but those copies are frequently outdated and missing the errata sections that vendors patch independently. I recommend downloading the manual from the vendor directly and immediately checking for a separate errata or supplement document, which usually lives in the same download section but is labeled differently. The supplement is where the real production knowledge lives. If you're working with open-source tools, the manual might be embedded in the source repository under a docs or errors directory. These tend to be more current because contributors submit pull requests for new codes, but they're also less polished and sometimes inconsistent in formatting. Read the contribution guidelines to understand whether the error documentation follows a standard template before you start parsing it.
When the Manual Won't Help You
There are situations where the error code is correct but the manual's resolution is insufficient or outright wrong. This happens most often with permission-related errors in clustered environments where the failure origin is ambiguous. Code 0x80070005 is the classic example, but it can mean anything from a missing service account permission to an incorrectly configured firewall rule to a corrupted security descriptor on a registry key. The manual will tell you it's an access denied error and suggest checking permissions. That's accurate and completely useless if you don't know which permission to check. In cases like this, enable verbose logging for the specific subsystem that generated the code, reproduce the error in a controlled environment if possible, and compare the output between a known-good state and the failing state. The difference in the logs will almost always point to the actual failure point faster than any manual entry will. This approach took me from three days of diagnosis down to about forty minutes on that production server incident I mentioned earlier. The other common failure mode is when error codes are intentionally vague for security reasons. Some platforms return generic failure messages to external consumers while logging detailed codes internally. If you're an end user rather than a developer with access to internal logs, you may genuinely not have enough information from the manual alone to resolve the issue. In those cases, the only real option is to contact support with the exact code and timestamp, and to have your environment details ready including version numbers, OS patches, and any recent configuration changes. Support teams see the same codes repeatedly and their internal knowledge bases are usually more detailed than the public manual.