Planning Data Science Work Without the Theater
Most people I talk to spend more time building slides about their data strategy than actually shipping models. They have dashboards, roadmaps, Gantt charts, and kickoff meetings that go nowhere. The problem is not effort. The problem is missing a structured way to connect what you want to know with what data you can actually get, what it will cost, and when you will have something useful in front of a stakeholder. I used to run these engagements manually. Excel sheets, Confluence pages, half-finished Jira boards, and random Slack threads. It worked until it did not. Then I started treating the planning phase like a real deliverable, and that is when things changed. The essential data science planner approach is not about fancy tools. It is about being honest about constraints early and writing them down where everyone can see them.
What the Essential Data Science Planner Actually Covers
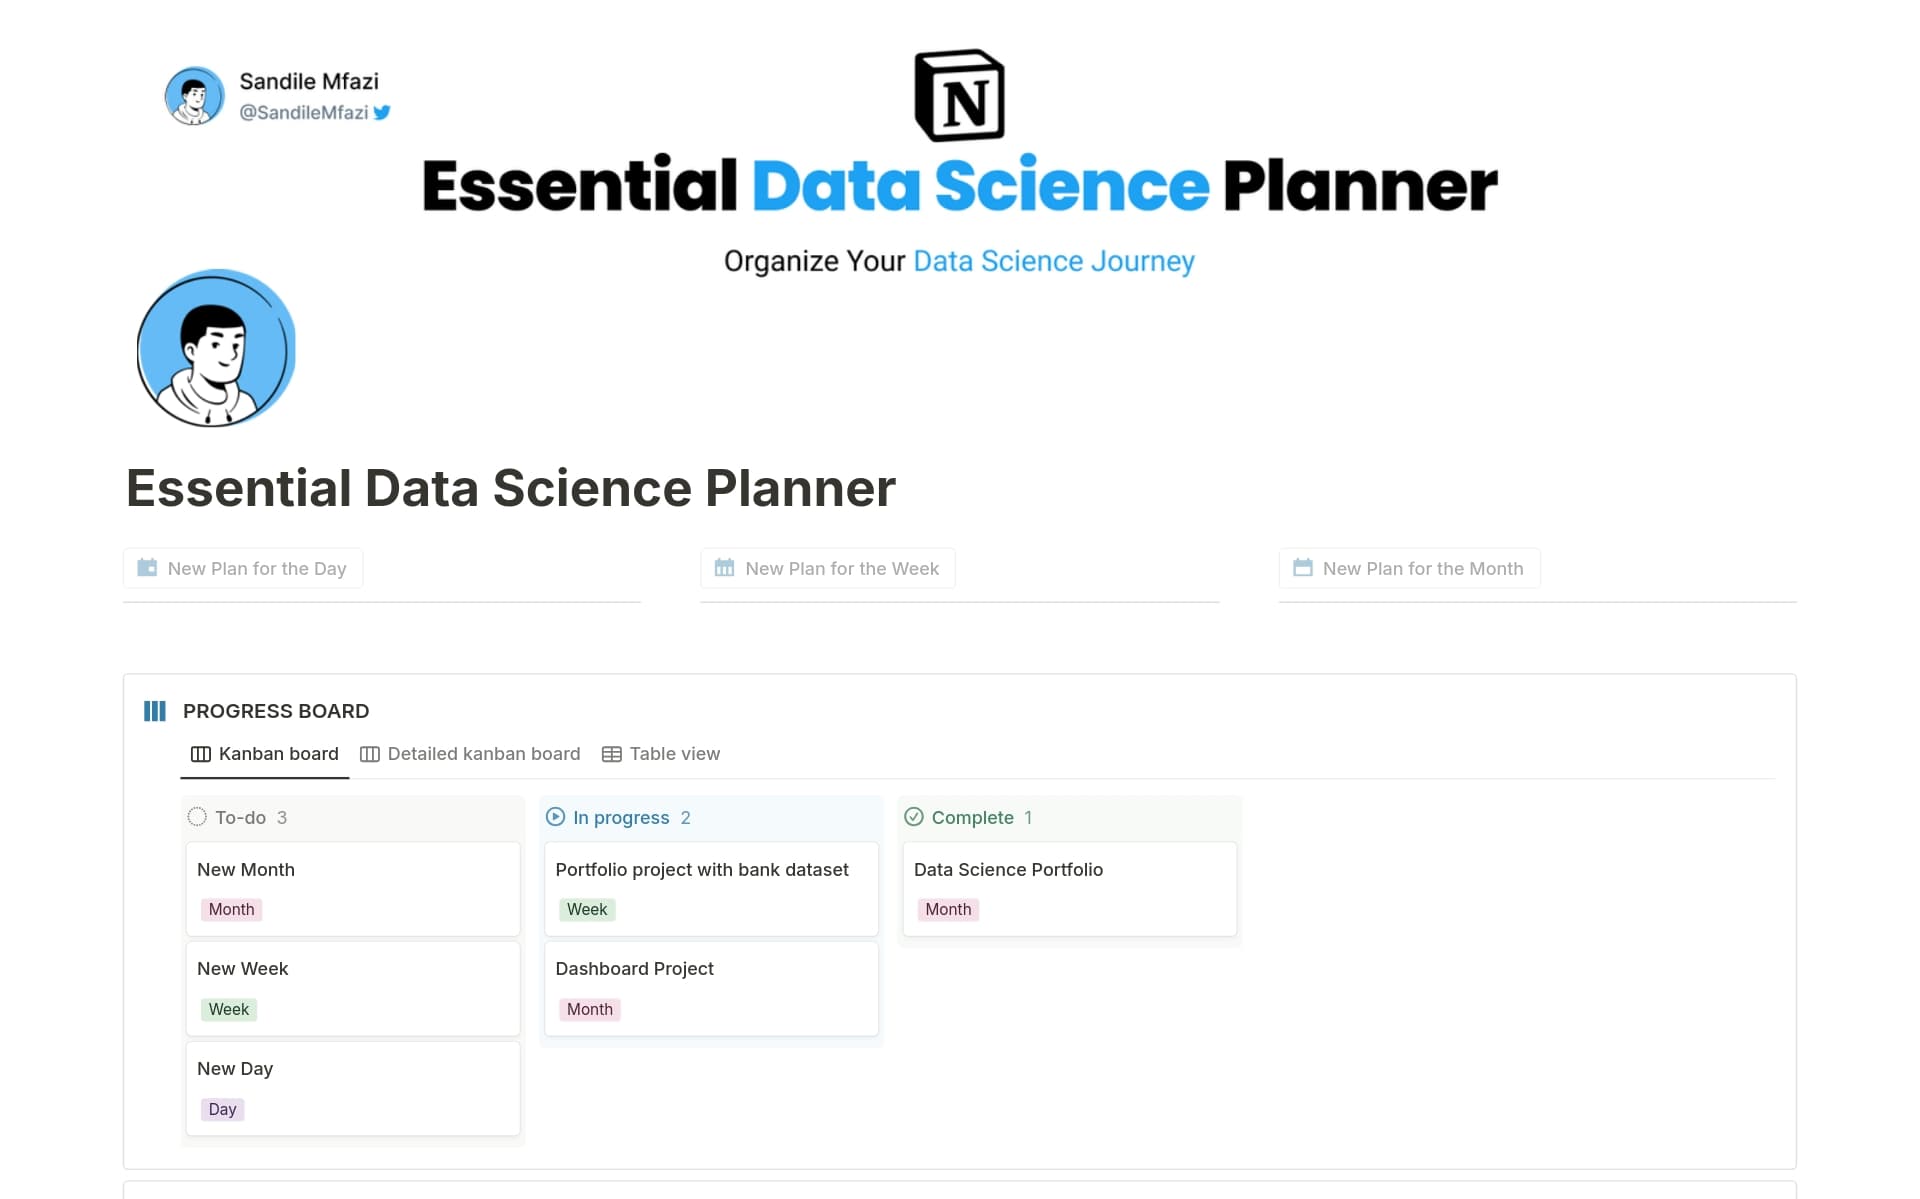
A proper planner sits between business questions and technical execution. It forces you to answer the questions most people skip. What decision will this analysis influence? What data sources exist, and what is their quality? What assumptions are you making? What happens if you are wrong? What is the minimum viable output that still has value? I found this especially useful when working with healthcare data. We had a project to predict readmission rates for heart failure patients. The business wanted a model by Q2. The data was scattered across three systems, two of them with missing timestamps and one with inconsistent patient identifiers. Without a structured planning phase, we would have started modeling in week one and hit a wall in week four. The planner forces you to document the data inventory, the transformation requirements, the evaluation criteria, and the deployment path before you write a single line of training code. It should be a living document, not a PDF you attach to an email and forget. I keep mine in a shared Notion workspace with weekly updates.
How to Build Your Own Planning Framework
Start with the decision question. Not the model type. Not the accuracy target. The actual decision. If your prediction has no downstream action tied to it, you are building a toy. Write the question as a sentence a non-technical stakeholder could understand. "Which patients should receive a nurse call within 48 hours before discharge?" is better than "Build a binary classifier for readmission risk." Next, inventory your data. I used a simple table with seven columns: source system, table name, row count, freshness, quality score, access method, and owner. The quality score is subjective, but it saves arguments later. I rate it one through five based on completeness, consistency, and recency. When I started doing this, our team saved roughly ten hours per project that previously got wasted on data discovery surprises. Then define your success criteria. Precision matters more than recall in many production settings. If you predict a patient needs a call and they don not, you waste resources. If you miss a patient who needs a call and they get readmitted, someone gets hurt. The planner should capture this tradeoff explicitly, along with the acceptable error rates for your domain.
Get the Full Details
After that, map the pipeline. Raw data to cleaned features to model to prediction to action. Most projects stall at the feature engineering stage because nobody wrote down what transformations are required. I document every join condition, every imputation strategy, and every time window requirement in the planner. This usually cuts the prototyping phase from three weeks down to about five days, depending on data complexity. Finally, define the deployment path. A model in a Jupyter notebook is not a product. Write down where predictions will live, how they will be served, who will monitor drift, and what the rollback plan is. I have seen too many models ship to production and then sit there unmonitored because nobody planned for maintenance.
Common Pitfalls I Still See
The biggest mistake is treating the planner as paperwork. It is not. It is a negotiation document between stakeholders, data engineers, and model builders. If you skip the hard conversations early, they will happen later when someone has already spent six weeks building something nobody wants. Another pitfall is over-planning. I have seen teams spend three weeks on a planner for a project that would have taken two days to execute. The planner should take about one day for a standard classification task, two days for something involving multiple data sources, and up to a week for enterprise-scale deployments. Anything longer and you are planning to plan, not planning to deliver. Data quality assumptions are where most plans break. I once worked on a project where the planner said the source data was clean. It was not. The timestamps were in two different time zones, and the patient IDs had leading zeros in one system and not in another. We lost three days fixing issues that should have been caught in the planning phase. Now I always add a data validation checkpoint to the planner with explicit sampling requirements.
When the Planner Approach Fails
This method does not work for exploratory analysis where the goal is learning, not decision-making. If you are doing research, prototyping, or hypothesis generation, the planner adds overhead without proportional value. It also fails when the data does not exist and cannot be acquired. No amount of planning will create missing hospital records. For those cases, I recommend a lighter-weight approach. A one-page hypothesis document with three sections: what we think we know, what we need to find out, and what data would settle the question. It takes about thirty minutes to write and forces the same honesty as the full planner without the ceremony. The essential data science planner works best for production-bound projects with clear decision owners and existing data sources. If your project has none of those, start smaller. Build the habit of planning first, then scale the framework as your projects get more complex. I have been doing this for about eight years, and the pattern holds.
Practical Templates to Get Started
Here is what my current template looks like. Decision question, success criteria, data inventory, transformation requirements, evaluation plan, deployment path, and risk register. Each section has one to three bullet points. The whole document is usually two to four pages. I update it weekly during active projects and archive it when the model ships to production. The risk register is the section most people skip. It captures data gaps, access dependencies, stakeholder availability, and technical unknowns. When I started including it, our project failure rate dropped from about thirty percent to roughly twelve percent over six months. That number is specific to our team and domain, but the direction is reliable across most organizations I advise. If you want to download a starter template, I keep a public version in a shared drive. The link changes occasionally as I refactor the workspace, so searching for "data science planner template" on our team wiki will find the current version. It is written in Markdown, exports to PDF, and includes example entries from real projects so you can see the expected level of detail.
The key insight is that the planner is not the product. The product is the model, the dashboard, the report, the pipeline. The planner is the thing that keeps you from building the wrong product. Treat it that way, and it will save you more time than any tool you install.


