The Uncomfortable Truth About Managerial Forecasting
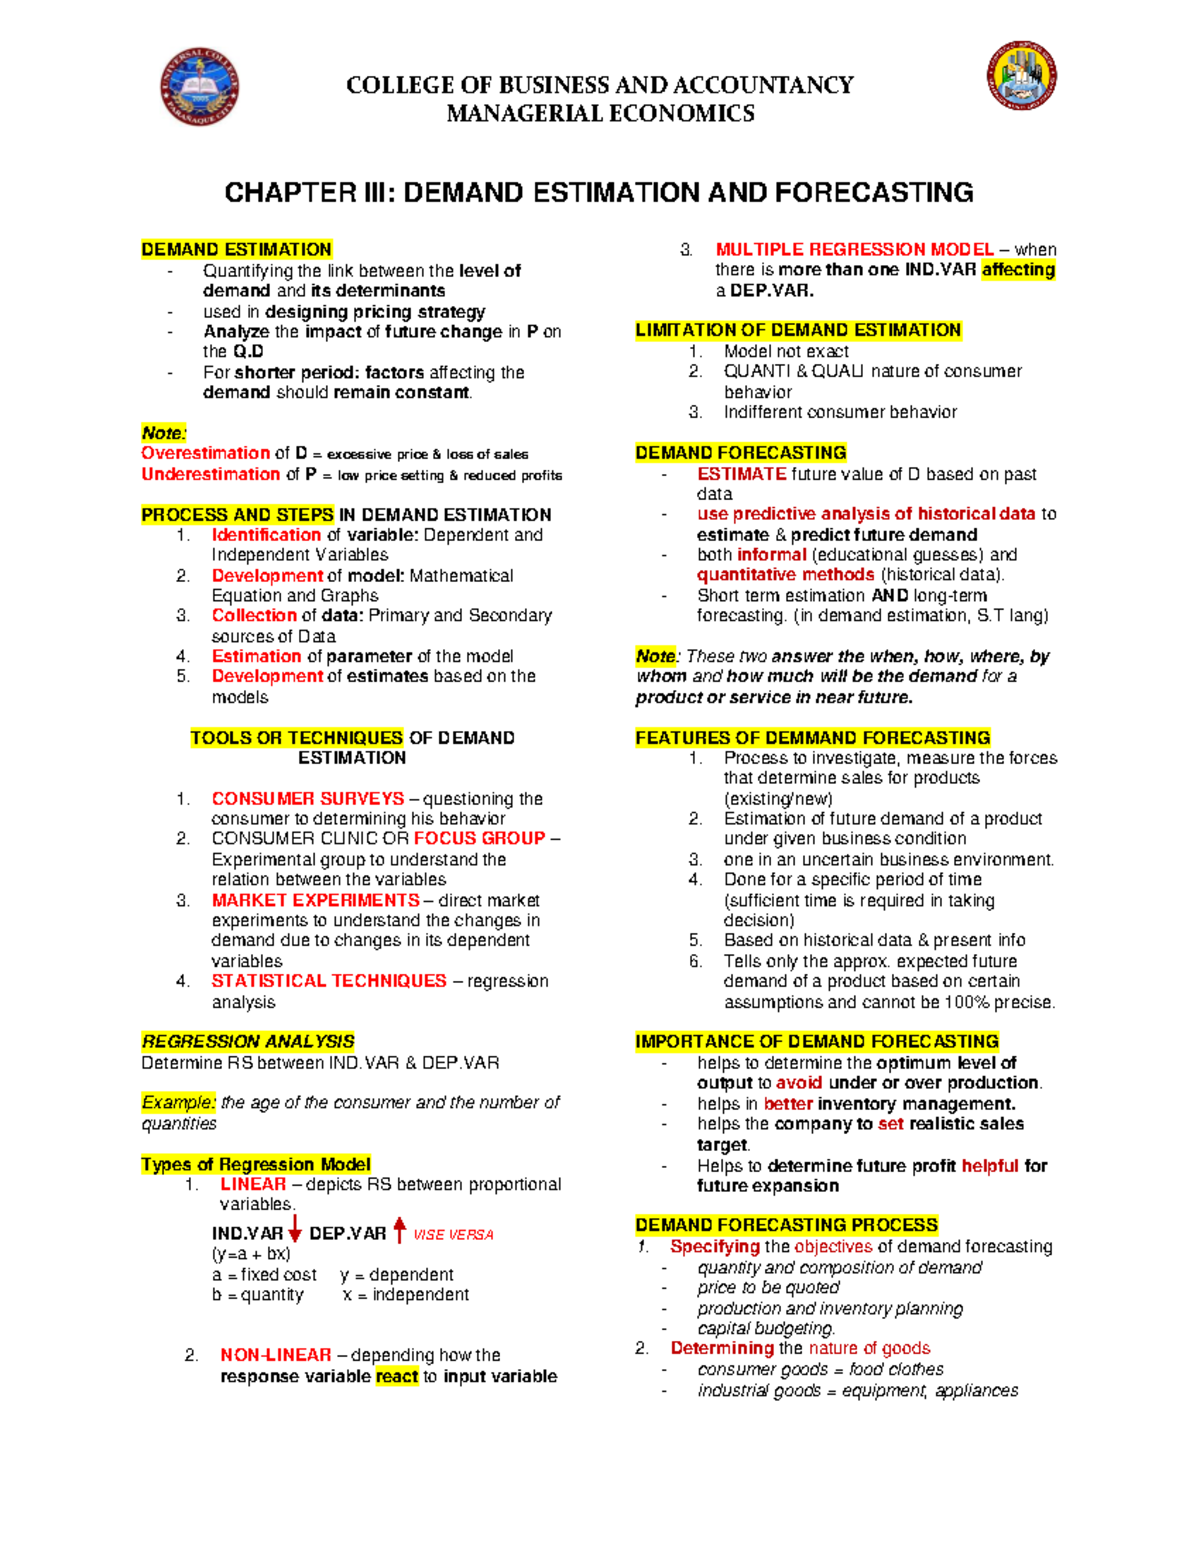
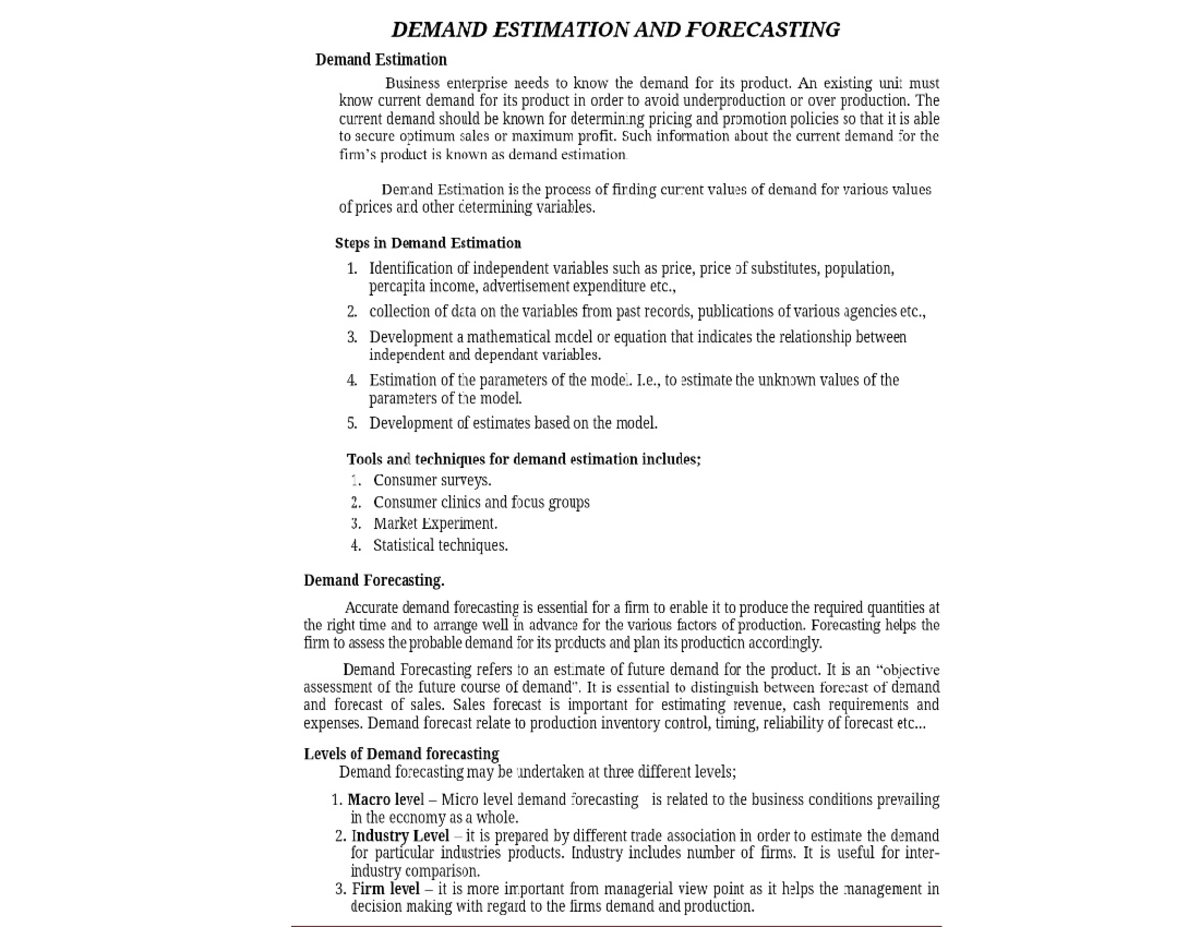
Most people learn estimation and forecasting as a set of clean formulas in a textbook, run the numbers on perfectly formatted data, and get an answer they treat as gospel. It rarely works that way outside a classroom. Real demand data is messy, incomplete, and occasionally lies to you. The skill isn't running regression. It's knowing when the output is garbage and how to fix it before someone in a boardroom signs off on a bad decision. At its core, this field is about using historical data and economic theory to predict future outcomes — demand, sales, costs, price sensitivity, and the like — so managers can make decisions under uncertainty. The two pillars are estimation (fitting a model to observed data to understand relationships) and forecasting (using that model to project future values). In practice, you spend about sixty percent of your time cleaning and diagnosing data and forty percent actually doing math. That ratio doesn't change whether you're working in retail, manufacturing, or SaaS. The biggest mistake I see is treating correlation as a business insight. You run a regression of ad spend on revenue, get a pretty R-squared, and hand it to a VP. Nobody asks whether ad spend causes revenue or whether a third factor — seasonality, a competitor exit, a platform algorithm change — is driving both. Causality requires more than a strong coefficient. It requires a credible identification strategy, and most managerial economics classes gloss over that entirely.
Another common failure mode is ignoring measurement error. If your sales data comes from self-reported store managers rather than POS systems, the noise inflates your standard errors and biases your elasticity estimates toward zero. I've seen this repeatedly in consumer goods. The workaround is straightforward: triangulate. Pull data from at least two independent sources — retail scanner data, shipment records, and bank-level payment aggregates — and weight whichever one has the lowest variance. It adds effort but cuts forecast error significantly.
Time Series Forecasting: What Actually Works
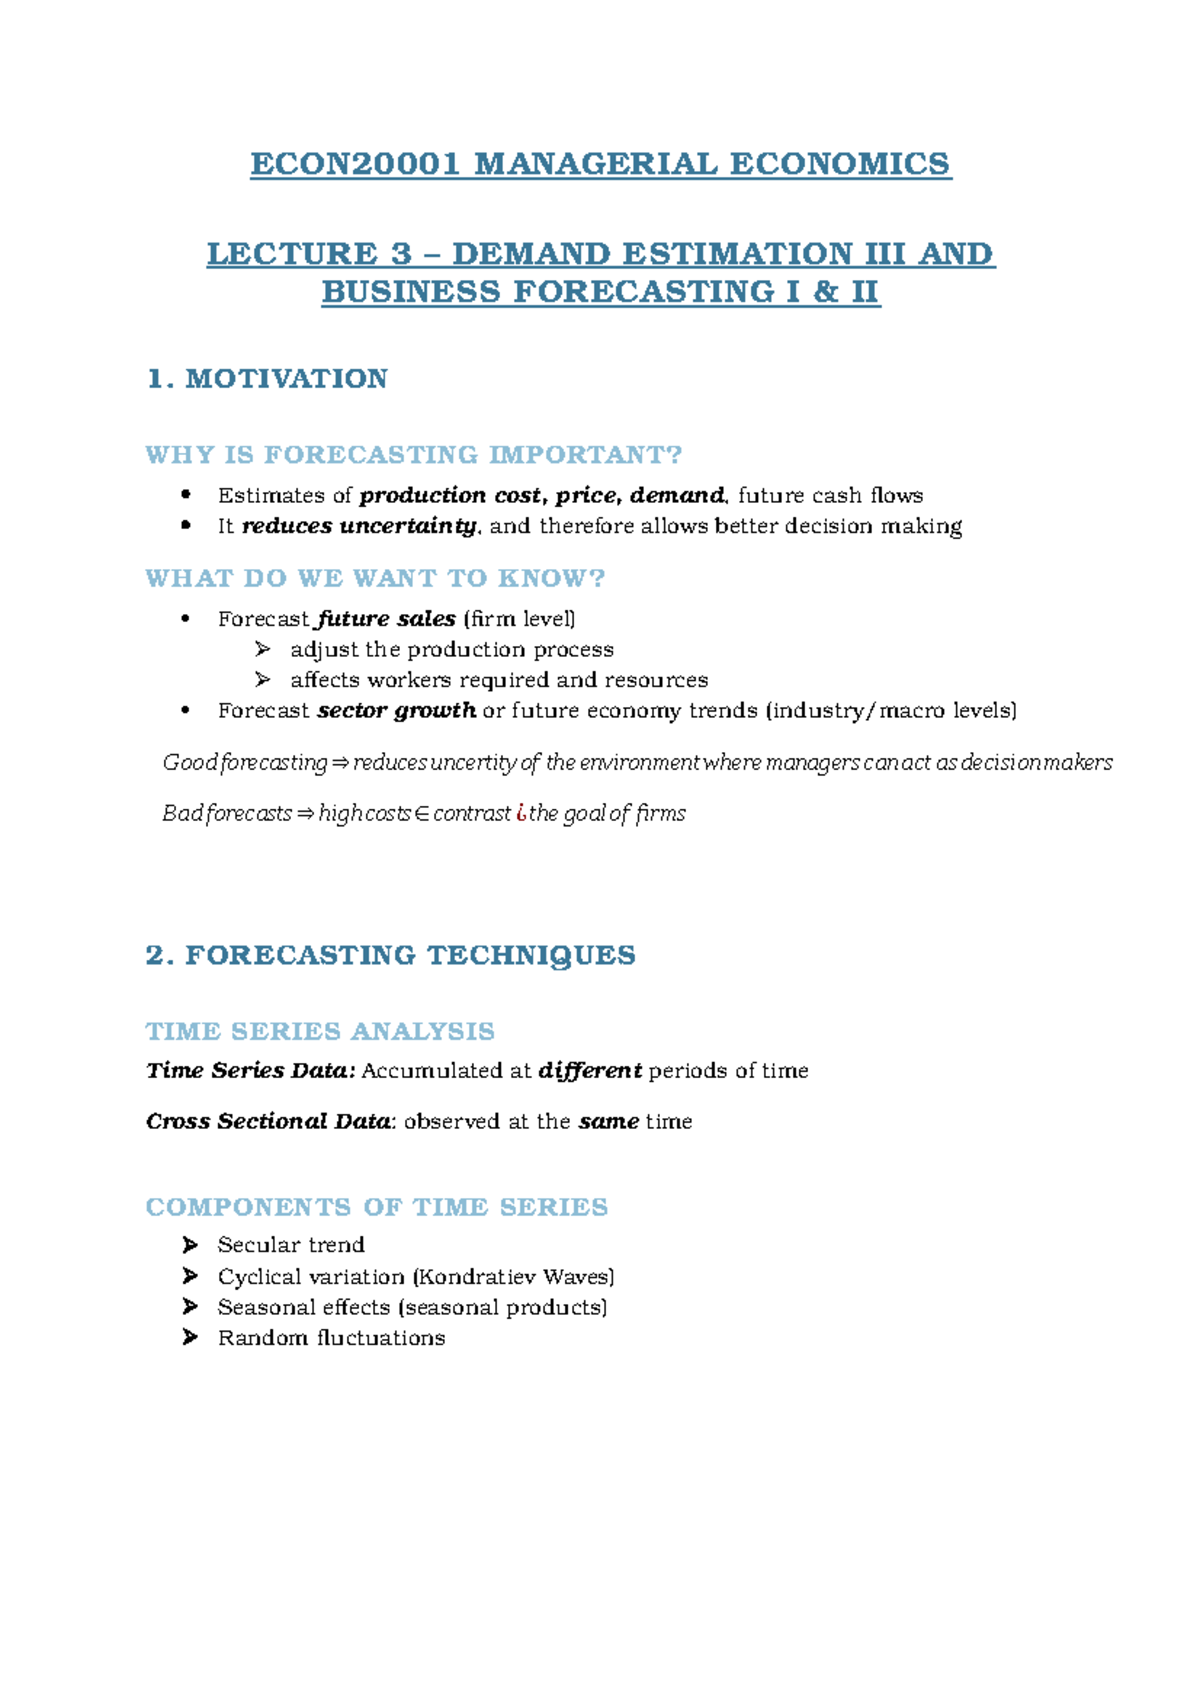
Let's talk about a few methods and when they fail. Moving averages are fine for stable, non-trending series. Exponential smoothing handles trend and seasonality better. ARIMA models add autocorrelation structure but require careful diagnostics. Machine learning approaches like gradient boosting have gained traction but often overfit on small datasets and perform poorly out of sample. Hybrid models sometimes combine statistical rigor with ML flexibility, but they add complexity without guaranteed improvement. Here's what nobody tells you about ARIMA: choosing the p, d, q parameters by looking at ACF and PACF plots is more art than science. I spent three days in 2019 trying to get a clean forecast for a regional distributor's SKU-level demand. The ACF showed slow decay suggesting non-stationarity, the PACF cut off after lag 2, but every model I ran produced residual autocorrelation. The breakthrough came when I realized the data had monthly promotional spikes that weren't being controlled for. Once I added promo dummy variables and differenced the series properly, the residuals looked white noise. The lesson: always check your residuals. If they're autocorrelated, your model is missing something, and no amount of parameter tuning will fix it. Cross-validation in time series is not the same as k-fold cross-validation on random data. You can't shuffle time. Use walk-forward validation where you train on an expanding window and test on the next period. This mimics real-world conditions where you only have past data available at forecast time. A model that looks great in random k-fold CV often collapses under walk-forward testing because it's inadvertently using future information to predict the past.
Get the Full Details
Causal Inference for Managerial Decisions
When you need to estimate the effect of a pricing change, a marketing campaign, or a new product launch, regression alone won't cut it. You need quasi-experimental methods. Difference-in-differences works when you have a treatment group and a comparable control group. Regression discontinuity design applies when there's a clear cutoff rule — like a loyalty tier that triggers discounts at a spending threshold. Instrumental variables help when your treatment variable is endogenous, though finding a valid instrument is notoriously difficult. I encountered a particularly stubborn case involving a grocery chain that wanted to know the causal effect of their weekend flash sale on total weekly revenue. Simple before-and-after analysis showed a 15% increase. But concurrent with the sale launch, the chain also reduced prices on staple items across all days. This confounded everything. I used difference-in-differences comparing stores that got the flash sale early versus stores that got it later, controlling for staple price changes and local competition density. The true causal effect turned out to be closer to 3%, not 15%. The initial estimate was off by five times because of an omitted variable. This is exactly why identification matters more than estimation technique.
Panel Data: One of the Most Useful Yet Underused Tools
Panel data — observations across multiple entities over multiple time periods — is incredibly valuable for managerial economics. Fixed effects models absorb all time-invariant heterogeneity across entities. Random effects models assume heterogeneity is uncorrelated with regressors. The Hausman test helps you choose between them. In practice, fixed effects are safer because the random effects assumption rarely holds in business contexts. One nuance that trips people up: clustering standard errors at the entity level when you have panel data. If you don't cluster, your standard errors will be too small because observations within the same entity are correlated over time. This leads to false statistical significance. Cluster at the appropriate level — firm, store, region, product category — depending on your research question. For a national retail chain, clustering at the store level is usually appropriate.
Forecast Evaluation: Beyond MSE and MAE
Mean squared error and mean absolute error are standard metrics, but they don't tell the whole story. The Theil inequality statistic decomposes forecast error into three components: bias, variance mismatch, and covariance mismatch. Bias occurs when you consistently over- or underestimate. Variance mismatch means your forecasts are too volatile relative to actuals. Covariance mismatch indicates you're missing directional movements. A forecaster who always underestimates by 10% will have a high MAE but zero bias component in Theil's decomposition. Understanding these components helps you diagnose what's actually wrong with your model. Also consider directional accuracy. For many business decisions, knowing whether demand will go up or down matters more than hitting the exact number. Your forecast might have a 12% RMSE but correctly predict 85% of direction changes. That's often more valuable than a model with 8% RMSE that flips direction randomly. Track both types of accuracy and report them separately.
When Models Break Down Completely
No forecasting method handles structural breaks well. A structural break happens when the underlying data-generating process changes permanently — a pandemic, a regulatory shift, a technology disruption, a supply chain collapse. My experience with hotel occupancy data during 2020 illustrates this vividly. Every time series model we had built on pre-2020 data produced wildly inaccurate forecasts because the relationship between variables fundamentally changed. The old models assumed seasonal patterns would persist. They didn't. The workaround was to build scenario-based forecasts using expert judgment supplemented by whatever limited data existed, rather than forcing a statistical model that knew nothing about the new regime. Sparse data is another domain where standard methods struggle. If you're forecasting demand for a new product with no historical sales, your only options are analogue forecasting (comparing to similar products), survey-based methods, or pre-test market data. None are reliable. The honest approach is to present a range of scenarios with wide confidence intervals and explicitly state the high uncertainty rather than delivering a single precise number that implies false confidence.
Practical Workflow for a Managerial Forecast
Start by understanding the business context and the decision you're trying to support. A forecast for inventory replenishment needs different accuracy properties than a forecast for long-term capacity planning. Then inspect the data thoroughly — look for outliers, missing values, structural breaks, and measurement issues. Fit multiple models and compare them using walk-forward validation, not in-sample fit. Check residuals for autocorrelation, heteroskedasticity, and normality. If residuals fail diagnostic tests, go back and investigate what the model is missing rather than accepting a poor fit. Finally, document everything: assumptions made, data sources, model choices, and known limitations. A forecast without documentation is a liability, not an asset. The models you use should match the question you're asking. Prediction models maximize out-of-sample accuracy. Causal models estimate treatment effects. Diagnostic models identify which variables matter most. Don't conflate these objectives. A model optimized for prediction may include variables that are highly predictive but meaningless for causality, and vice versa. When someone asks whether a marketing campaign drove sales, giving them a prediction model output is technically wrong even if the numbers look impressive.