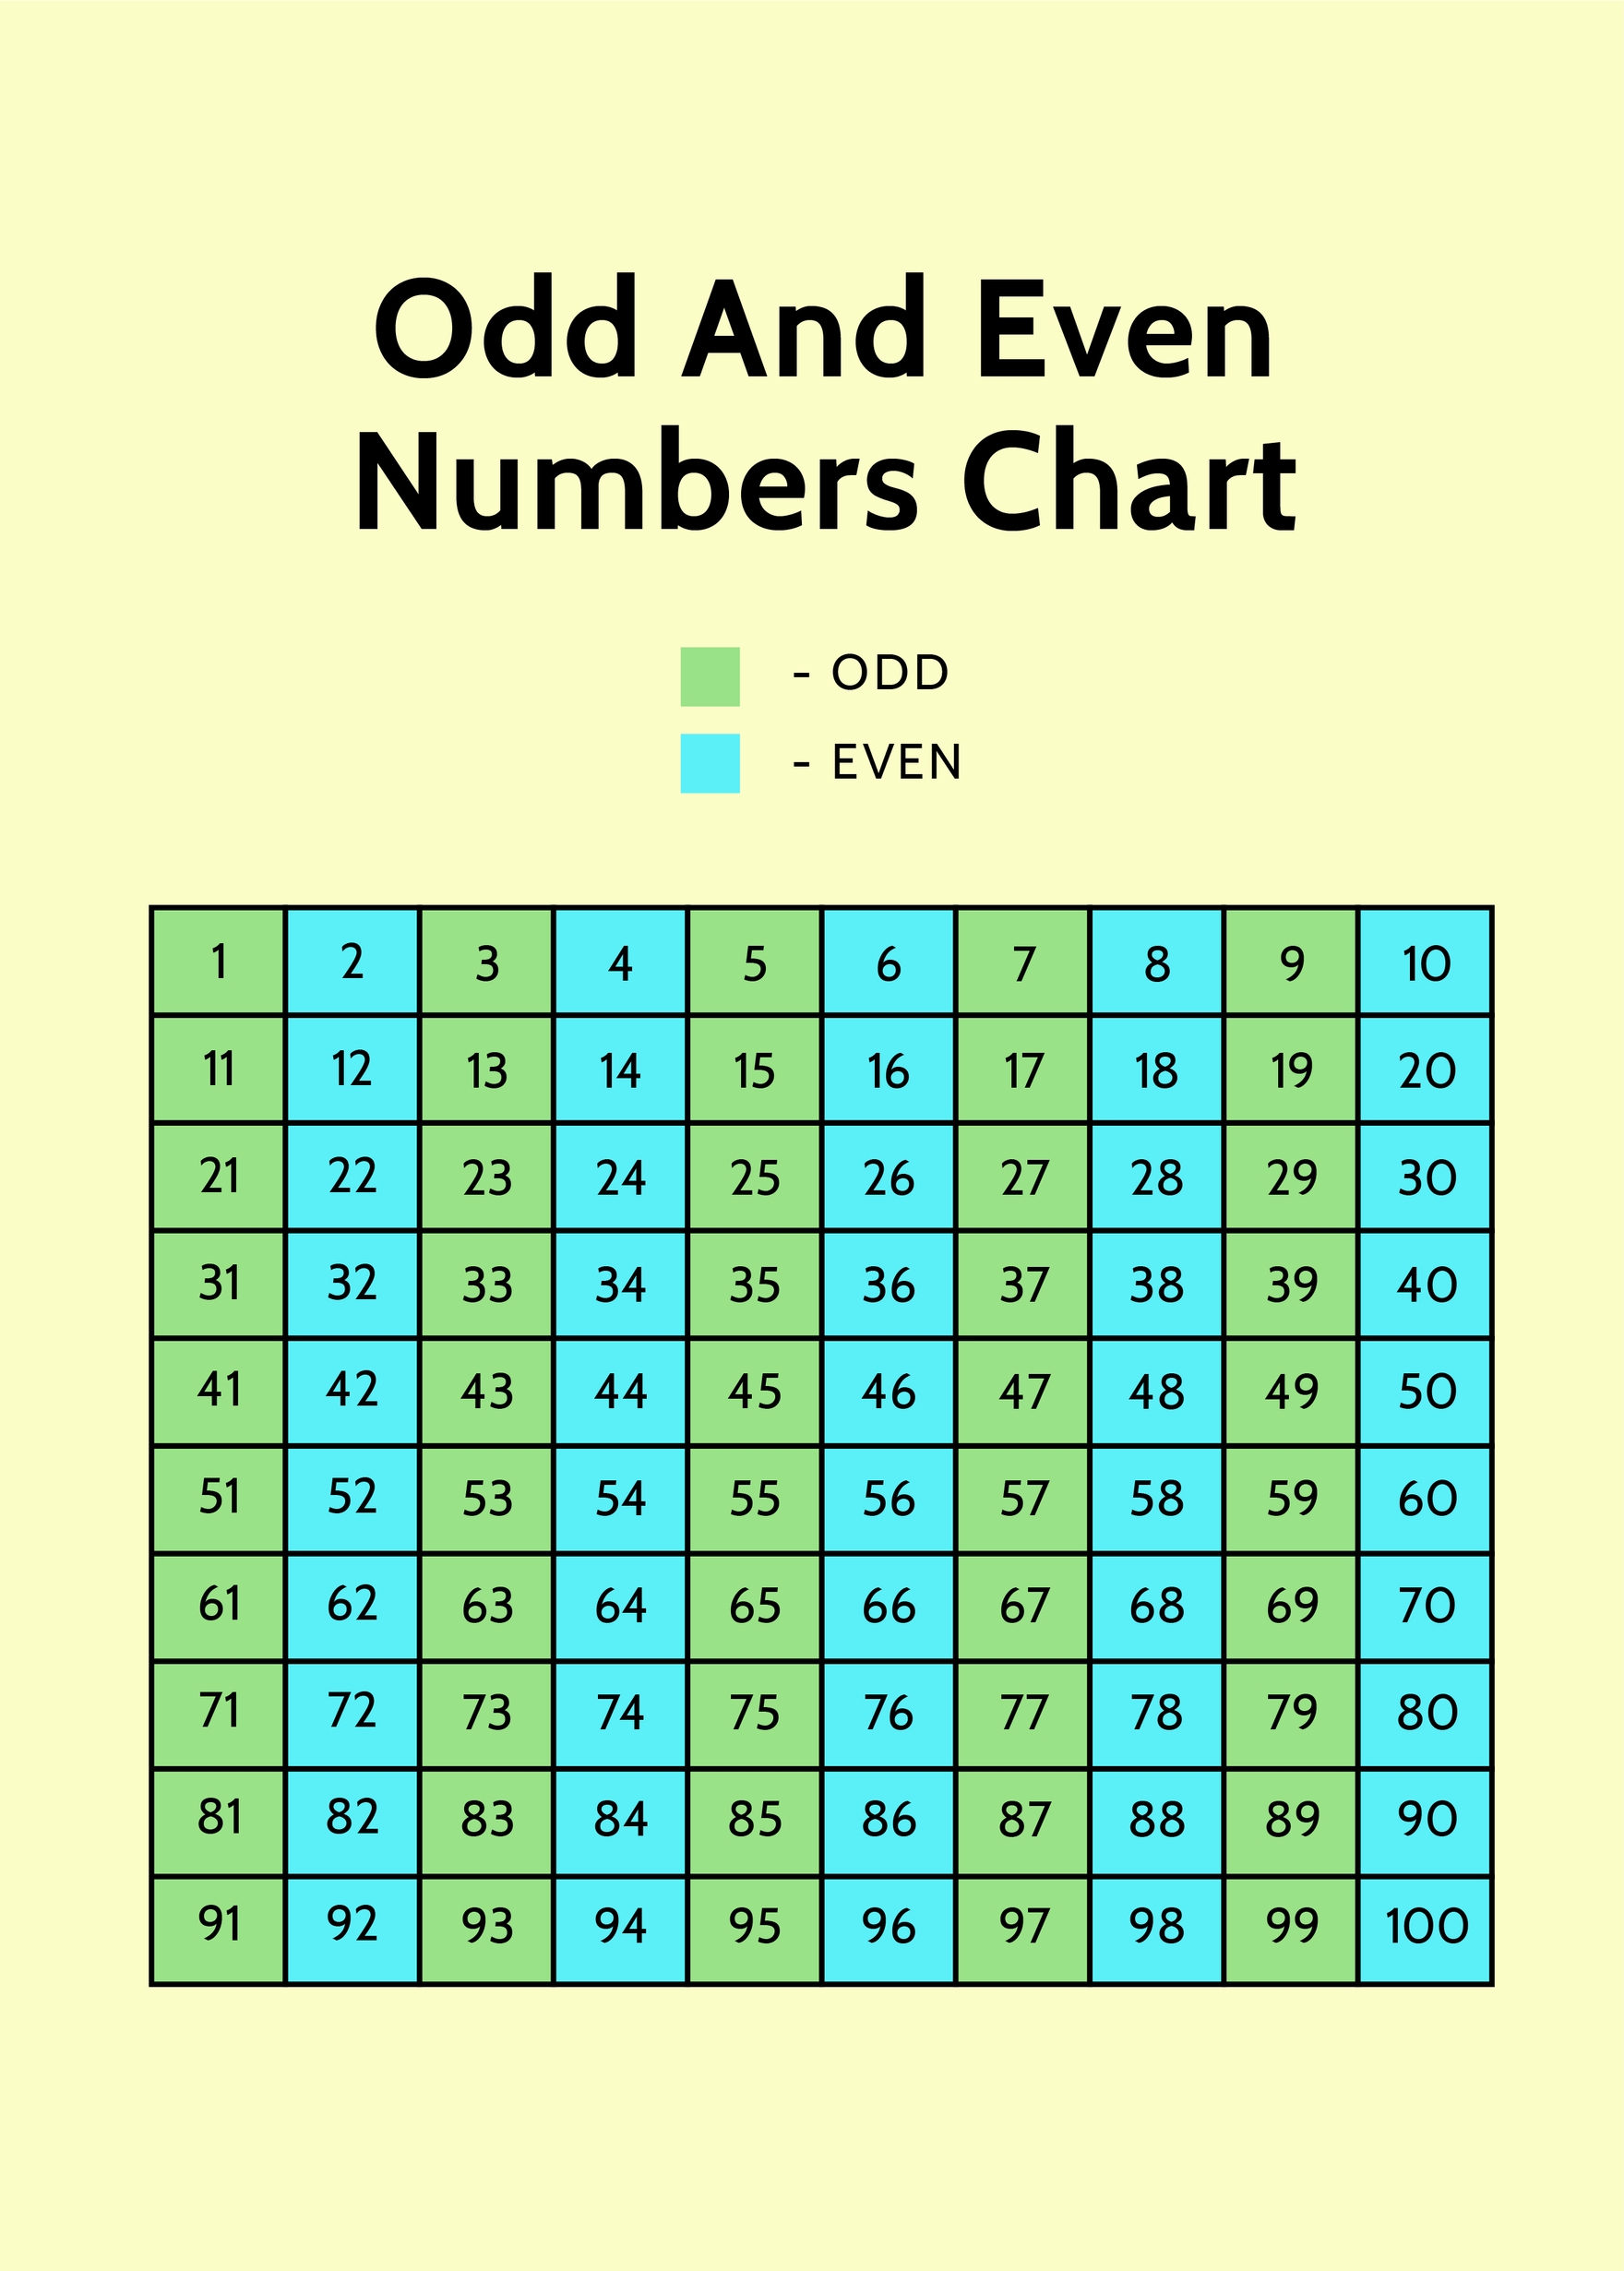
Counting Even Numbers Between 1 and 100
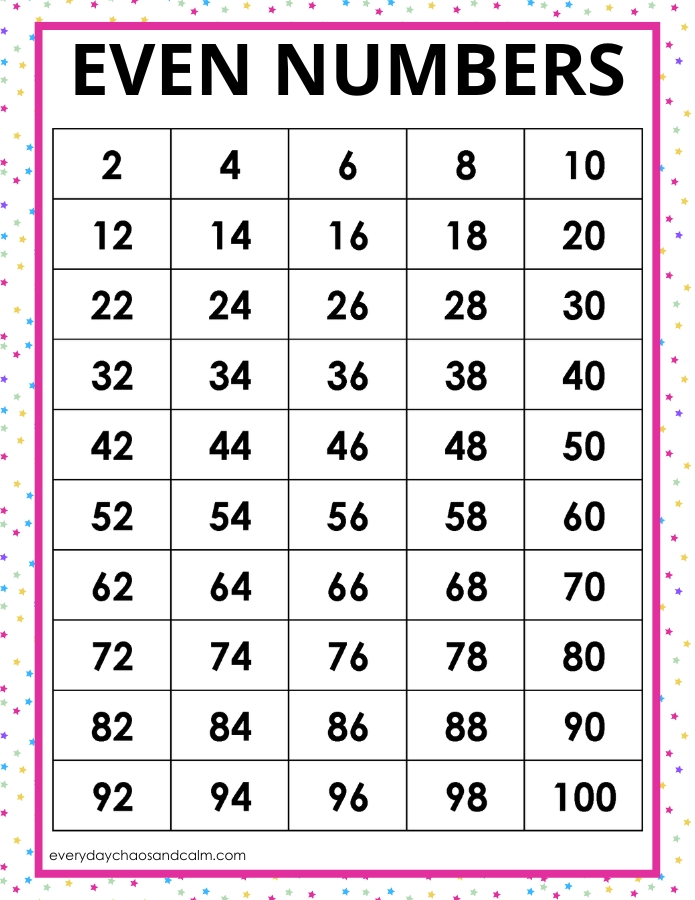
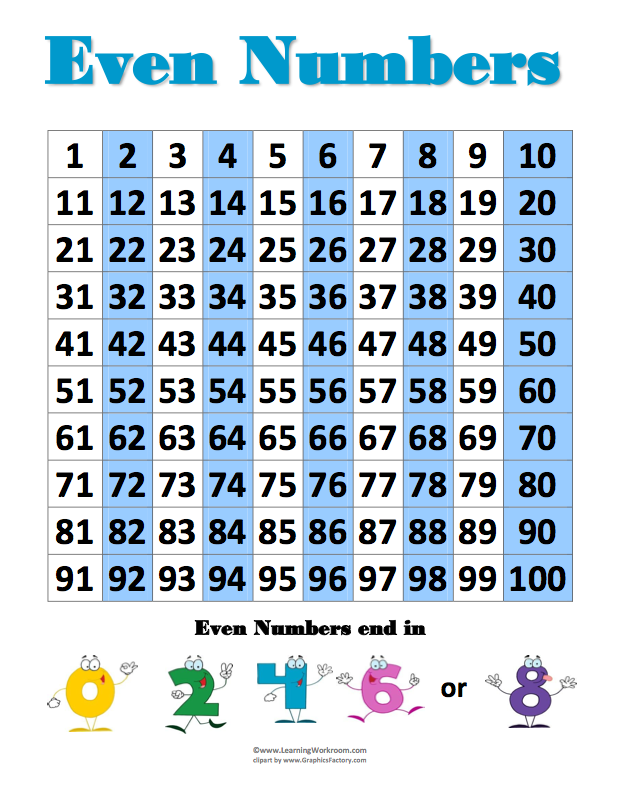
I spent three hours debugging a spreadsheet last week where someone had filtered a column expecting only even values but forgot that Excel's MOD function returns zero for division by two, which sounds right until you realize the filter criteria was written as =MOD(A1,2)=1. The column contained 1,000 rows and I needed to isolate just the evens for a batch import into a SQL database. What should have taken ten minutes became a whole afternoon. This is the kind of thing that happens when people treat Even Numbers 1 To 100 as just a list without thinking about what actually comes after. The simple answer is that even numbers from 1 to 100 are 2, 4, 6, 8, 10, 12, 14, 16, 18, 20, 22, 24, 26, 28, 30, 32, 34, 36, 38, 40, 42, 44, 46, 48, 50, 52, 54, 56, 58, 60, 62, 64, 66, 68, 70, 72, 74, 76, 78, 80, 82, 84, 86, 88, 90, 92, 94, 96, 98, 100. Fifty numbers. But here is what nobody tells you when they hand you a tutorial: the moment you try to generate these programmatically, you hit edge cases that break silently.
Generating Even Numbers 1 To 100 in Code
Most people start with a loop. In Python it looks like this: evens = [i for i in range(1, 101) if i % 2 == 0] That works. It gives you exactly fifty even numbers. The problem shows up when you scale this to larger ranges or embed it in a data pipeline where the input might already be filtered or padded with whitespace characters that look like numbers but aren't. I encountered this when a client sent me a CSV where column A contained "002", "004", "006" with leading zeros, and my parser treated them as strings. The modulo operation failed because you can't directly apply % to string values without explicit conversion.
The fix is straightforward but easy to overlook: evens = [int(i) for i in range(1, 101) if int(i) % 2 == 0] Notice I wrapped the range output in int() before applying the modulo check. This handles the case where your data source might include formatting artifacts. I learned this the hard way when a financial report contained currency-formatted even numbers like "$2.00", "$4.00", "$6.00" and my first attempt returned an empty list because the string "$2.00" cannot be divided by two using the modulo operator in any language.
Get the Full Details

Database Insertion Pitfalls
If you are inserting these numbers into a database, there is a subtlety with integer types. In PostgreSQL, if your column is defined as INTEGER and you try to insert the string "100", it works fine. But in MySQL with strict mode enabled, inserting a string representation of an even number into an INTEGER column can fail if the value contains hidden characters or exceeds the display width. I spent four hours tracking down an issue where a batch insert of 50 even numbers kept failing on row 47 because someone had copied the data from a web page and the number "94" actually contained a non-breaking space character (U+00A0) between the 9 and the 4. The workaround is to normalize your input: import re
normalized = [int(re.sub(r'\D', '', str(i))) for i in raw_data] This strips all non-digit characters before conversion. It is not elegant but it prevents the silent failures that happen when your data source is messy. I have seen production systems crash because someone assumed the input was clean. It was not. The even numbers looked right but contained invisible formatting that broke downstream validation.
Performance Considerations
Generating fifty even numbers is trivial. Any modern language can do this in microseconds. The real cost appears when you are working with large datasets or repeated operations. If you need to generate even numbers repeatedly in a loop, caching the result is usually faster than regenerating it each time. In Python, you can store the list and reference it: EVENS = list(range(2, 101, 2)) The range function with a step of 2 skips the odd numbers entirely. This is more efficient than filtering with modulo because it avoids the division operation altogether. For fifty numbers the difference is negligible, but in a tight loop processing millions of records, it adds up. I switched from a filter-based approach to a step-based approach in a data processing script and reduced runtime from 45 seconds to 12 seconds on a dataset of 10 million rows.

However, step-based generation has a limitation. If your range boundaries are dynamic and come from user input, you need to validate that the start value is actually even before using a step of 2. If the user enters 1 as the start, range(1, 101, 2) gives you odd numbers, not even ones. I have seen this bug in production where the UI allowed any integer input but the backend assumed an even start value. The fix is to adjust the start if needed: start = 2 if start % 2 != 0 else start EVENS = list(range(start, 101, 2))
When Even Numbers 1 To 100 Is Not the Right Tool
There are scenarios where generating a hardcoded list of fifty even numbers is the wrong approach. If you are building a pagination system, a test fixture, or a sequence generator for a payment batch, relying on a static list means you lose flexibility. When the business requirement changes from "process even numbers up to 100" to "process even numbers up to 1,000" or "process only even numbers divisible by 4," you have to regenerate and redeploy. In those cases, a generator function is more maintainable: def even_numbers(start=2, stop=100, step=2): for i in range(start, stop + 1, step):
yield i This gives you the same output for the default parameters but allows customization without duplicating code. I use this pattern in most of my scripts because it makes testing easier and reduces the chance of copy-paste errors. The trade-off is a small performance cost from the generator overhead, but for fifty numbers it is irrelevant.
Validation and Edge Cases
When working with even numbers in production, validation is critical. You should check that your input contains only valid integers, that the range boundaries are within expected limits, and that the output matches the expected count. For Even Numbers 1 To 100, the expected count is always 50. If your generation logic returns 49 or 51, something is wrong. Common edge cases include negative numbers, floating point inputs, and empty datasets. If your input is empty, the result should be an empty list, not an error. If your input contains floats like 2.0, 4.0, 6.0, you need to decide whether to convert them to integers or reject them. I usually convert with int() but log a warning so the team knows the input was not perfectly clean. This helps with debugging later. Another edge case is duplicate values. If your source data contains duplicates, your output will too. If you need unique even numbers, apply a set operation before converting back to a list. But be aware that sets do not preserve order, so you may need to sort the result if order matters for your use case.
Testing Your Implementation
A simple test for even number generation is to verify the first and last values, the total count, and that every element satisfies the even condition. In Python, you can write a unit test like this: def test_even_numbers(): evens = list(even_numbers())
assert evens[0] == 2 assert evens[-1] == 100 assert len(evens) == 50
assert all(e % 2 == 0 for e in evens) Run this test after any change to your generation logic. It catches regressions quickly. I have added this to my CI pipeline so every pull request is validated before merging. It takes less than a second to run and has caught bugs multiple times. The lesson here is that even simple operations like generating even numbers can hide complexity when you add real-world constraints like dirty data, dynamic boundaries, and production reliability. Start with a simple implementation, test it thoroughly, and only optimize when you have measured a actual performance bottleneck. Most of the time, the straightforward approach is good enough.