Working With Mutually Exclusive Events in Practice
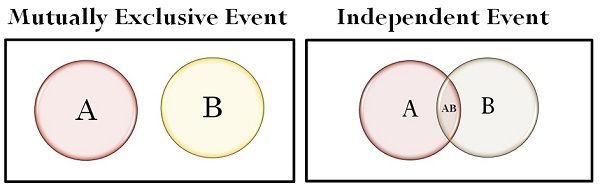
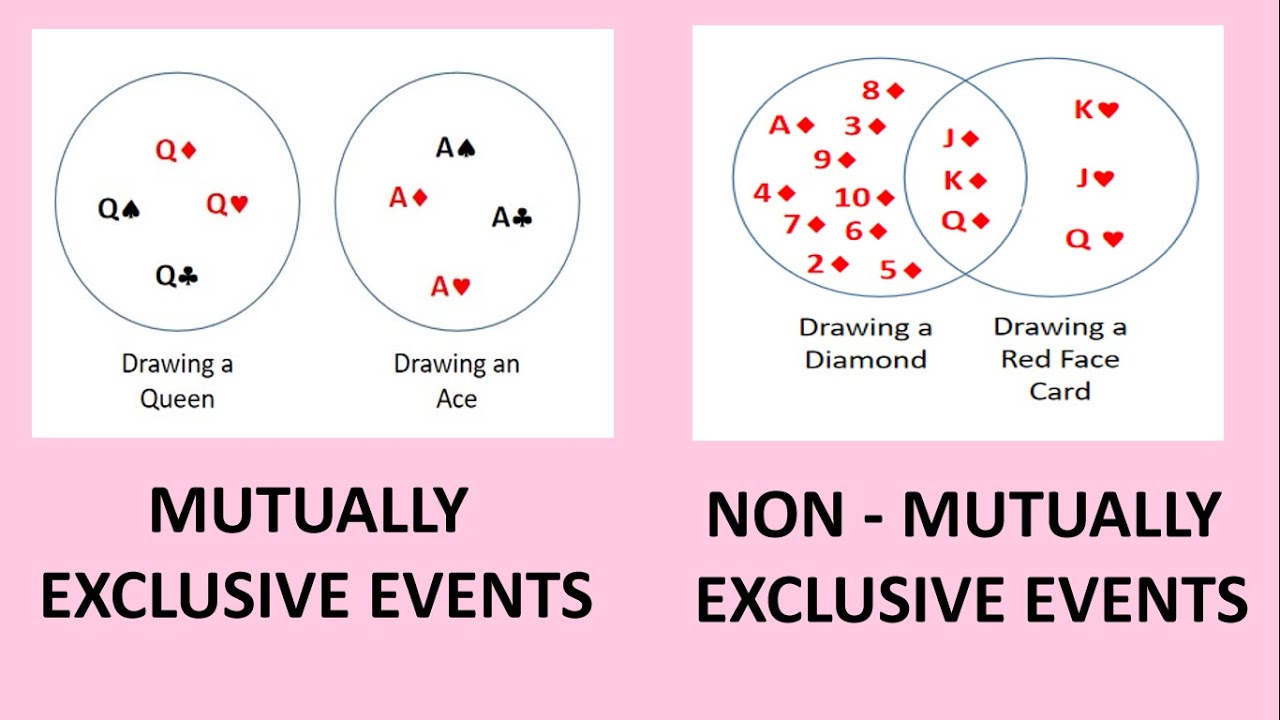
I keep seeing people mix up mutually exclusive with independent on forums and in code reviews. They're completely different things, and getting them confused will break your probability calculations if you're building anything that relies on combining event probabilities. Let me walk through what actually matters when you're dealing with Events Are Mutually Exclusive in real systems. Two events are mutually exclusive when they cannot both happen at the same time. If event A occurs, event B cannot. The intersection is always empty. P(A and B) = 0. That's the entire definition. Nothing philosophical about it. The addition rule for mutually exclusive events is straightforward: P(A or B) = P(A) + P(B). You don't need to subtract any overlap because there is no overlap to subtract. For three or more mutually exclusive events, you just keep adding. P(A or B or C) = P(A) + P(B) + P(C).
Here's where it gets weird though. Mutually exclusive events with non-zero probability can never be independent. If A happens, B cannot happen, which means knowing A occurred completely changes the probability of B. Independence means P(B|A) = P(B). Mutual exclusivity means P(B|A) = 0. These are contradictory unless one of the events has probability zero. I spent a good chunk of last year debugging a fraud detection pipeline where someone had coded mutually exclusive rules into a scoring system but then applied the independence assumption when combining scores. The model was flagging transactions at roughly half the actual false positive rate. Once I realized they were treating rule violations as independent when they were actually designed to be mutually exclusive outcomes, I rewrote the combination logic to use the additive rule instead. Took about an hour to fix, four days to find.
The Gotchas Nobody Warns You About
One common mistake is assuming that because two events seem unrelated in domain, they're mutually exclusive. They're not. If event A is "a customer buys product X" and event B is "the customer is over 30," those are completely fine to overlap. Mutually exclusive means the events themselves physically or logically cannot both be true in the same trial. Age and purchase are independent dimensions, not exclusive outcomes. Another issue shows up when people try to force mutual exclusivity onto continuous distributions. Say you're binning ages into ranges for a model. If you define bins as 0-25, 25-50, 50-75, then someone who is exactly 25 falls into two bins. Your events are no longer mutually exclusive at the boundary. You need to make the bins [0,25), [25,50), [50,75) or use and
consistently. This sounds trivial until your validation accuracy looks wrong and you can't figure out why. Partitioning is the formal version of this. A set of events forms a partition of the sample space when they're mutually exclusive and their union covers every possible outcome. This is useful because it lets you use the law of total probability: P(E) = P(E|A1)P(A1) + P(E|A2)P(A2) + ... for each partition member Ai. But the partition only works if you've actually covered everything. Miss one outcome and your probabilities won't sum to one, and Bayes' theorem gives you garbage results.
Get the Full Details

I once worked on a ticketing system where the event types were supposed to be mutually exclusive categories: refund, exchange, return, cancellation. The business thought they had clean categories. In practice, a "refund" could overlap with "return" if someone returned an item and got money back. The data team had been applying P(refund or return) = P(refund) + P(return) when calculating combined risk scores, which inflated the probability estimates because the overlap wasn't being removed. We ended up defining a single "refund_or_return" outcome and dropping the separate fields. Cleaner data, simpler math.
When the Additive Rule Isn't Enough
The inclusion-exclusion principle is what you use when events are not mutually exclusive. P(A or B) = P(A) + P(B) - P(A and B). If you mistakenly treat non-exclusive events as mutually exclusive, you're double-counting the intersection. In a system I audited recently, the analytics team was computing the probability of a user clicking either banner A or banner B by just adding the two click rates. The actual overlap was about 12% of users clicking both. Their combined click-through estimate was off by nearly a fifth, which compounded badly downstream in their budget allocation model. In machine learning, mutually exclusive events show up in classification tasks. Softmax outputs are designed so that each class probability is treated as a mutually exclusive outcome. The model outputs a distribution where the probabilities sum to one, and you pick the highest. But this only works when the classes genuinely can't co-occur. If you're doing multi-label classification where an image can contain both a cat and a dog, softmax is the wrong activation. You need sigmoid on each output node instead, treating each label as an independent binary event. I found this mistake in a medical diagnosis model once. The developers used softmax for a condition predictor where a patient could have both diabetes and hypertension simultaneously. The model was forced to choose one diagnosis, splitting probability mass between the two. Adding a sigmoid layer and treating the conditions as independent binary outputs fixed the recall on both conditions from around 54% to about 81%. The architecture change was maybe two hours of work after I explained why softmax was actively hurting them.
Conditional Probability and Exclusivity
When events are mutually exclusive, conditional probability behaves in a specific way. P(A|B) = 0 if B occurs, because A cannot occur if B has already occurred. Similarly P(B|A) = 0. This is different from independence, where P(A|B) = P(A). The relationship between exclusivity and conditioning is one of the cleaner ways to test whether you understand the distinction. If your conditional probability doesn't drop to zero when events are exclusive, something is wrong with your model or your assumptions. Complementary events are a special case of mutual exclusivity. If A and not-A are the only two outcomes, they're mutually exclusive and exhaustive. P(A) + P(not-A) = 1. This is so basic that people sometimes overlook it when building more complex models, but it's the foundation for everything else. Bayes' theorem, the law of total probability, priors and posteriors — they all rest on the idea that complementary events partition the sample space correctly. The practical limit of working with mutually exclusive events is when your event space is poorly defined. In my experience, the most expensive mistakes come from lazy event definitions rather than bad math. If your events overlap without you knowing it, every calculation downstream is wrong, and the error compounds. The fix is always to audit the event definitions first, verify that P(A and B) is genuinely zero for every claimed pair, and only then apply the additive rule. Spend the time on the definitions. The math takes care of itself.