Understanding Everyday Interactions Examples in Practice
Most people encounter this concept without realizing it. You are probably reading it right now as part of one. The formal framework around Everyday Interactions Examples isn't something you download or buy from a licensing portal — it is a classification methodology used primarily in UX research, conversational AI training, and service design. The idea is straightforward: categorize the smallest unit of human-to-system or human-to-human contact into patterns that can be studied, replicated, and improved.
The reason this matters is because most organizations treat routine interactions as invisible. They just happen. A support ticket closes. A button gets clicked. An email gets sent. Nobody tracks what actually occurred in those moments until something breaks. That is when teams realize they have no baseline for normal behavior.
I ran into this exact problem at a SaaS company a few years back. We had a churn rate spike that we couldn't explain through standard analytics. The funnel looked fine. Page views were stable. But people were leaving. What we eventually discovered was that our onboarding support chatbot was giving slightly wrong answers to everyday questions about plan limits. It wasn't catastrophic. It was the kind of error that happens maybe once per conversation, easily forgiven. But over three months, the accumulated friction pushed enough people to cancel. Once I mapped out every interaction category from the chatbot transcripts, the pattern was obvious. The fix took two days.
Everyday Interactions Examples That Matter Most
There are several recognized categories of interaction that get tracked in this framework. The most common ones include navigational interactions, where a user tries to move from point A to point B within a system. Informational interactions, where someone asks a question and expects an answer. Transactional interactions, which involve some form of exchange — a purchase, a form submission, a cancellation. And social interactions, which are the least documented but often the most impactful, like when a user vents or expresses frustration and the system has no protocol for handling it.
I usually recommend starting your classification by pulling raw logs. Not dashboards. Not aggregated reports. Raw conversation logs, click streams, support tickets. The aggregated data hides the edge cases. For example, in my earlier churn project, the dashboard showed chatbot resolution rates at 94 percent. That looked good. The raw transcripts revealed that 60 percent of those "resolved" conversations ended with the user saying thanks and then never logging back in. They weren't satisfied. They were just polite.
How to Build Your Own Framework
The process isn't complicated, but it is tedious. You need to collect at least three months of interaction data, though more is better if you can get it. Then you tag each interaction with a type from your classification system. You will need to train at least two people on the tagging to catch inter-rater variability. I have seen teams skip this step and end up with classifications that mean nothing because one person labeled a complaint as informational while another labeled the same complaint as social. That inconsistency makes the entire dataset useless for decision-making.
Once tagged, you look for frequency anomalies. Which interaction type appears most? Which ones correlate with drop-offs? Which ones consistently result in escalation to a human agent? This last point is important. If more than 12 percent of interactions in a single category end with a human handoff, that category probably needs a rewrite.
A tool I recommend for this is a simple spreadsheet combined with text analysis software like MonkeyLearn or even manual coding in Excel if you are working with under 5,000 interactions. Anything beyond that and the manual approach becomes unsustainable. One consultant I worked with used a Python script with basic sentiment analysis to pre-classify tickets before the human tagging step. That cut the initial sort time from about 40 hours to roughly six. The script wasn't perfect, so we spent two hours reviewing its misclassifications. Worth it.
Common Pitfalls
The biggest mistake I see is treating this as a one-time project. Interaction patterns shift. What looked normal in January will look different by June after a product update or a marketing campaign brings in a different user segment. I would schedule a reclassification review at minimum every quarter, and you should do it anytime the product changes significantly.
Another pitfall is over-classifying. Some teams create 20-plus categories and end up with such granular data that nothing is actionable. Eight to twelve well-defined categories is usually the sweet spot. You should also avoid mixing interaction types with outcomes. A complaint interaction and a cancellation are two different things. One is a type of contact. The other is a result. Keep them separate.
When This Approach Fails
Let me be clear about where this method breaks down. If you have fewer than 500 interactions per month, the statistical significance won't be there. You might find patterns, but you won't be able to trust them. In those cases, qualitative interviews with users are more useful than classification exercises. Also, if your product has fewer than three distinct user types, the framework adds overhead without much return. Not everything needs to be categorized.
There is also the issue of data privacy. If you are logging conversations, you need to be compliant with GDPR, CCPA, or whatever regulation applies to your region. I learned this the hard way when a European client's legal team flagged our transcript storage process. We had to delete three months of tagged data and rebuild with anonymized strings. It cost us about a week of work. Make sure your data handling is approved before you start collecting.
If classification isn't viable for your situation, a simpler alternative is the diary study method. Have a small group of users log their interactions manually over two weeks. It won't give you the volume, but it will give you context that raw logs cannot. People remember how they felt. Systems don't.
Gallery Everyday Interactions Examples
Premium Photo | Everyday Activities and Interactions of Diverse People
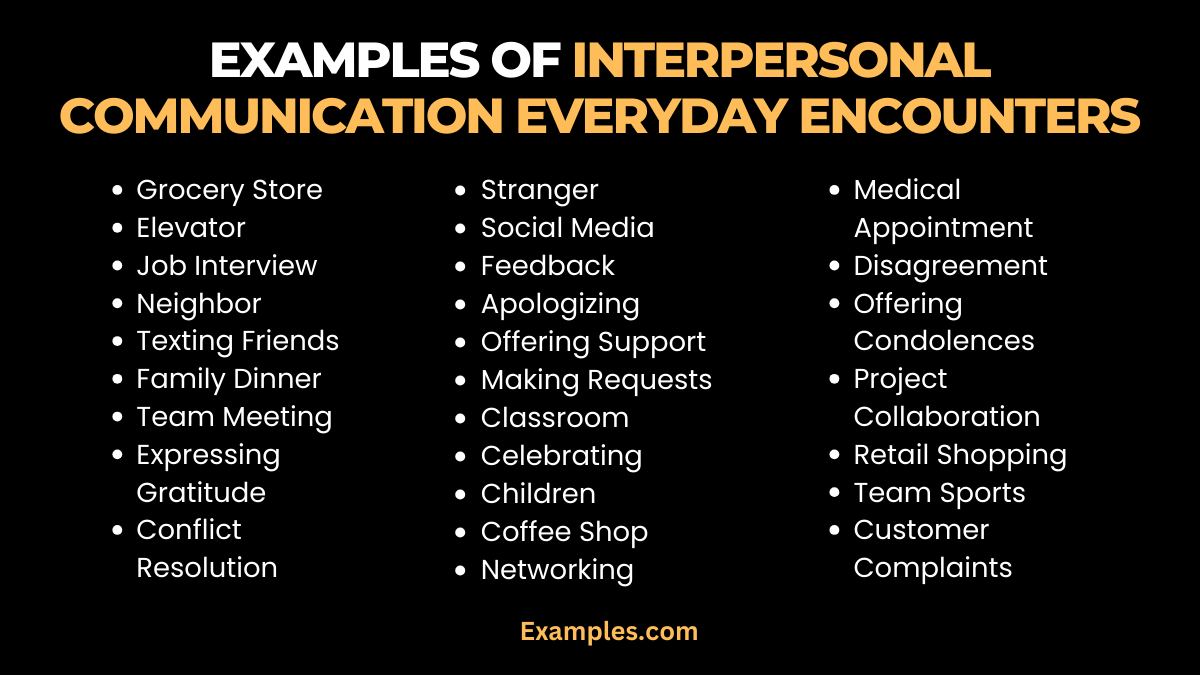
Interpersonal Communication Everyday Encounters - 29+ Examples
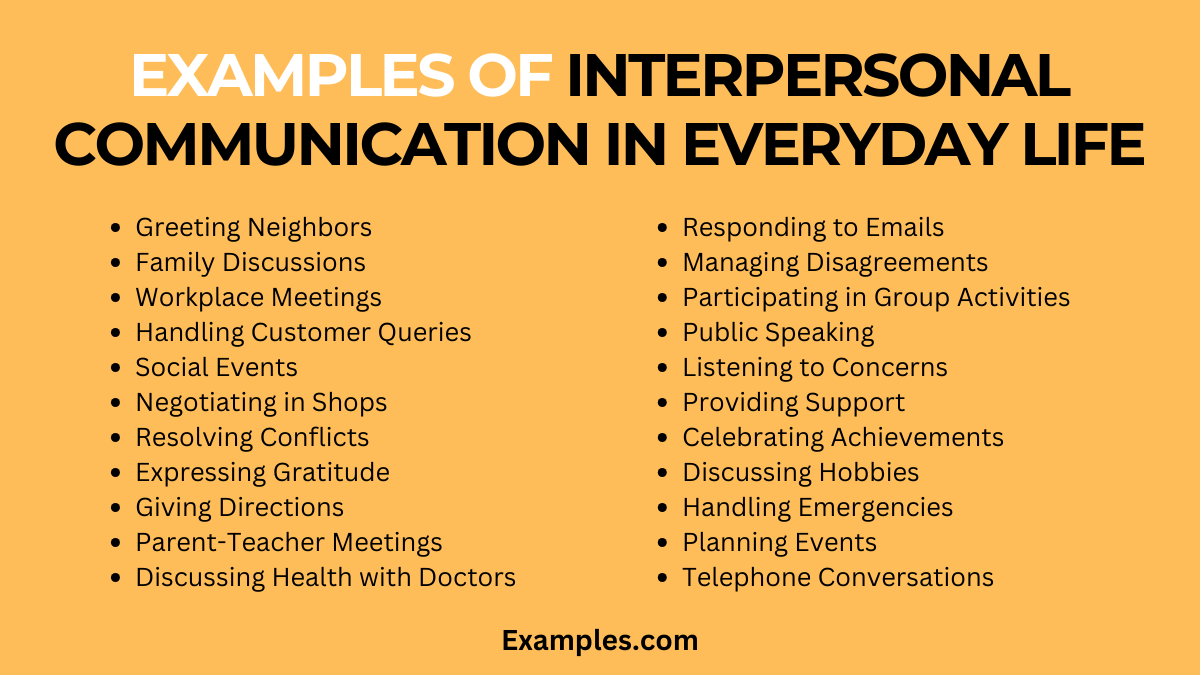
29+ Interpersonal Communication in Everyday Life Examples | Examples.com
Scenes of Everyday Interactions and Activities 71286792 Vector Art at ...
Diverse Collection of Relatable Everyday Moments and Interactions ...