What a Data Mapping Document Actually Looks Like in Practice
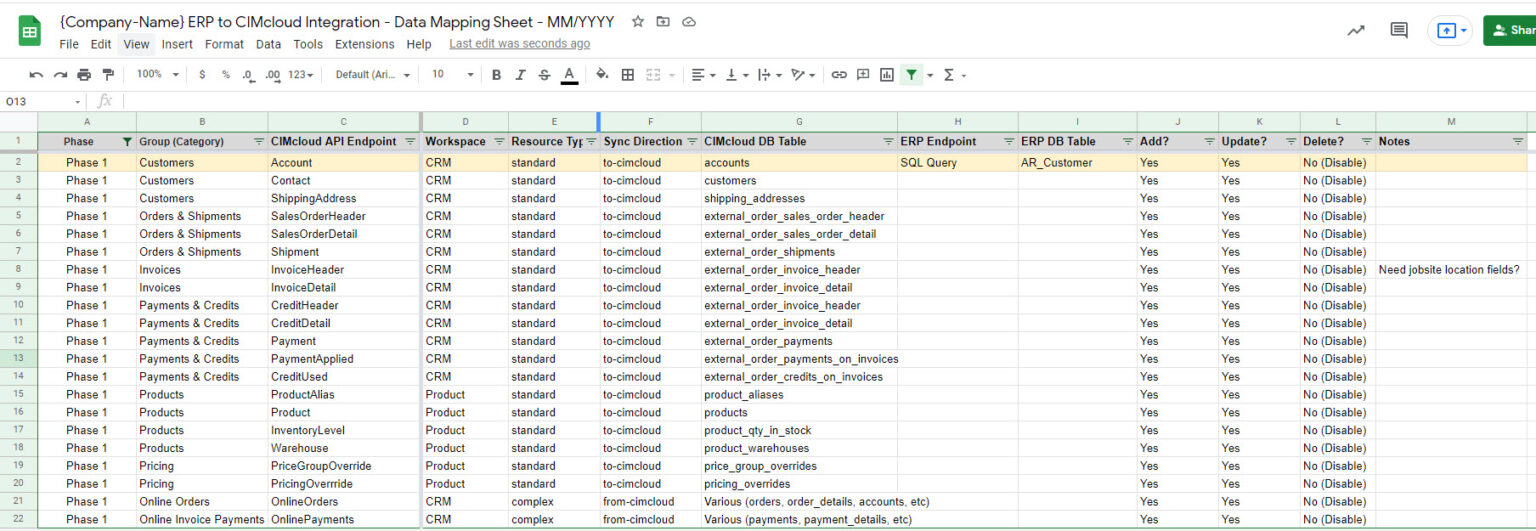
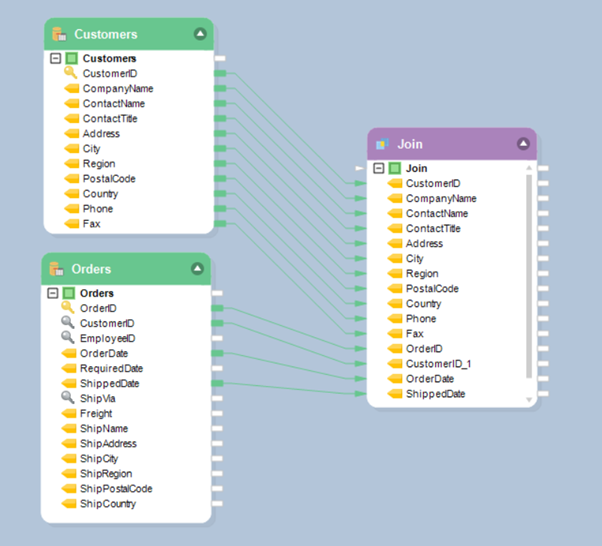
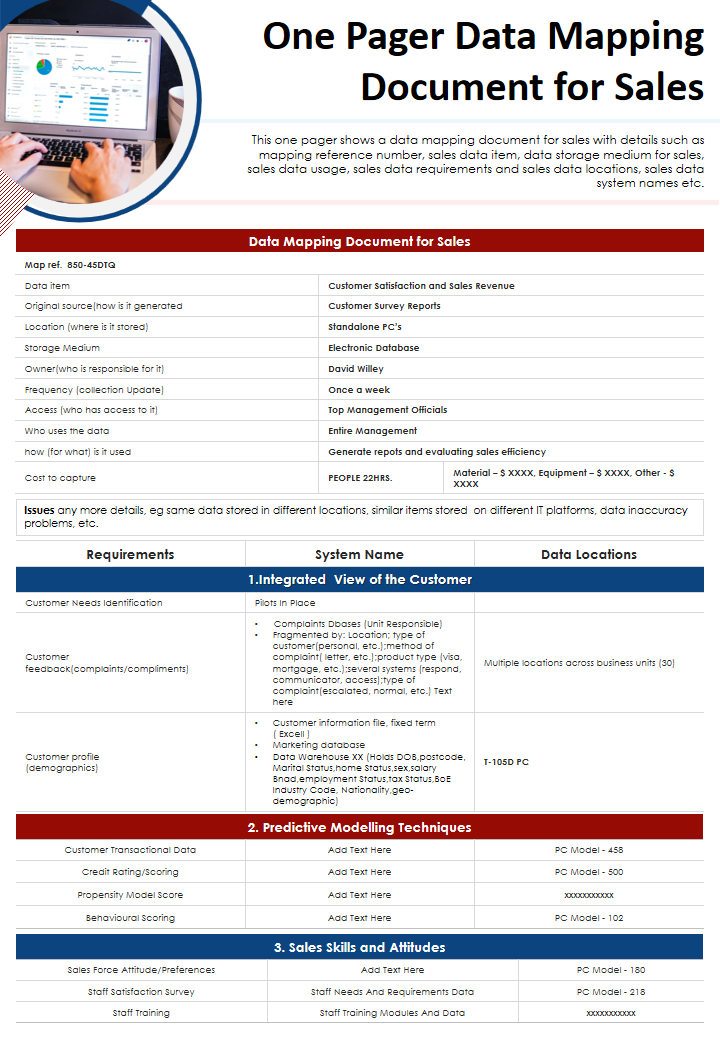
A data mapping document is simply a spreadsheet or table that pairs fields from one system with fields from another. It records the source field name, the target field name, the transformation logic, and any notes about edge cases. That's it. The confusion usually comes when people expect it to be more than a lookup table. I've spent years dealing with mappings between ERPs, CRMs, and legacy databases. You learn pretty quickly that the document is never finished by the time integration starts. Data quality issues, missing field conversions, and unexpected defaults pop up constantly. The mapping doc survives by being treated as a living file, not a deliverable.
How to Build a Working Example Data Mapping Document
Start with the target system. Go backward from the destination fields to figure out what source data can actually feed them. This reverses the instinct most people have, and it saves hours of wasted effort mapping fields that never get used. I learned this after spending three days mapping an entire CRM export that turned out to be completely irrelevant to the downstream warehouse management system. The project manager wanted a one-to-one map of every field. I showed her which ten fields actually drove the receiving workflow, and we cut two weeks off the timeline. For each field pair you need to record the following: Source system name and field identifier — include the exact API column name or database column. Team members often reference slightly different labels depending on whether they are looking at the UI, the schema, or the API response.
Target system name and field identifier — same requirement, but from the receiving side. Data type and constraints — a date field in the source might come through as a string in ISO format, while the target expects a Unix timestamp. You will need to note that conversion explicitly rather than assuming the engineer reads the schema. Transformation logic — this is where most mappings fail. If a source has an "Employment Status" field with values like Active, On Leave, and Terminated, but the target uses a numeric code, you have to document the exact mapping: Active equals 1, On Leave equals 2, Terminated equals 3. If there is no match, say so. Missing a null case causes runtime errors that are annoying to debug later.
Get the Full Details
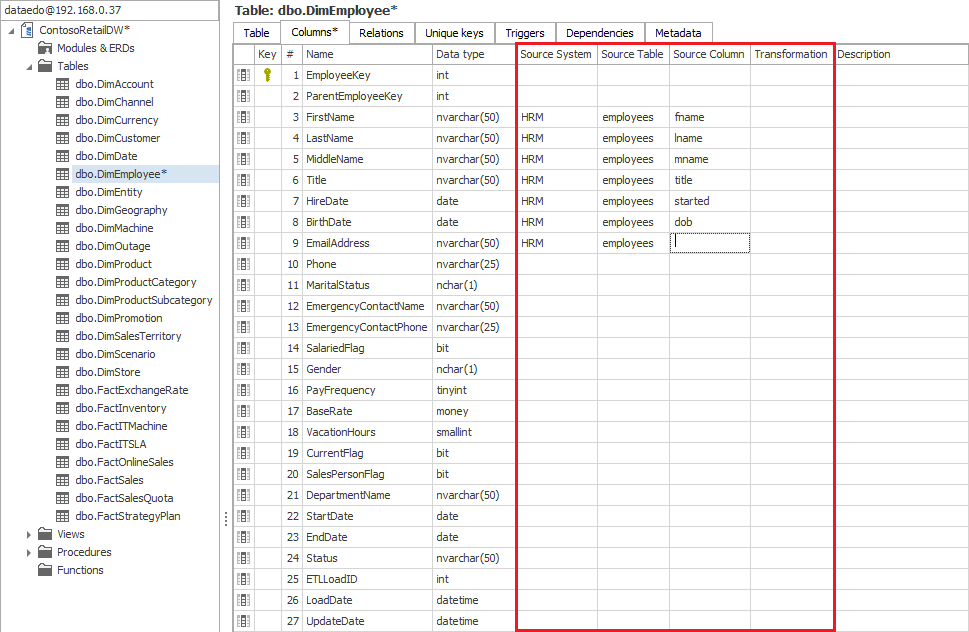
Default or fallback value — many integrations break because the source omits a required field. Write down what the target receives when the source is empty. Sometimes the default is zero, sometimes it is an empty string, sometimes it is a hard failure that stops the whole batch. Transformation notes — a free text column for things like, the source concatenates first and last name into a single FullName field and you need to split them before insertion. Or the target enforces a 50-character limit and you need to truncate with ellipsis. Keep the format flat. A single sheet per integration is easier to maintain than multiple tabs that drift out of sync. Add version history at the bottom, not as a separate document. I once spent a morning trying to trace which tab had the most recent mapping change because someone created a new sheet instead of updating the existing one.
Edge Cases You Will Encounter
One specific problem I ran into recently involved a customer address field. The source system stored the full address as a single line with no country code, and the target required a separate two-letter country field. The initial mapping looked straightforward. Then I realized that half the records used implicit countries based on the customer profile, and the other half were international shipments with no country stored anywhere in the address field. The workaround was to join the customer profile table to pull the default country, and flag any record missing both fields for manual review. I added a rejection reason column to the mapping doc to track those exceptions, and we built a separate queue for them instead of letting the integration silently drop or misroute the data. Another common issue is duplicate keys. If the source uses product SKUs and the target uses internal IDs, a single SKU can map to multiple IDs when products have been merged or retired. Document the behavior you expect: merge records, keep the latest, or reject duplicates. The target system's error handling depends entirely on which decision you make.
What People Miss When They Start
The first thing beginners get wrong is assuming a one-to-one mapping covers the whole job. In reality, only about sixty percent of fields map cleanly. The rest need transforms, splits, concatenations, or lookups. Building your document around that reality from the start prevents rework. The second mistake is skipping the null handling column. Every missing value somewhere becomes an unhandled exception, and that exception usually surfaces during the first production load. The third mistake is treating the mapping doc as a static artifact. Every schema change in either system requires an update, and stale mappings cause data drift that is very hard to catch retroactively. Example Data Mapping Document structures tend to work best when they are hosted in a shared spreadsheet or a plain CSV with clear headers. JSON or XML versions exist, but they add parsing overhead without solving the core problem. A tabular format lets any stakeholder read it, update it, and comment on it without tooling friction.
Limitations of This Approach
A static mapping document cannot handle dynamic schema evolution. If the source or target changes field names or types during the project, the document falls behind. It also does not replace unit testing of the actual integration. You can map every field perfectly and still fail when the data volume exceeds the target system's API rate limits. The mapping doc will not tell you that the target truncates text fields at 255 characters unless you write it in the notes column. If you are working with large scale transformations or schemas that change frequently, consider moving toward a data lineage tool or an integration platform that can auto-generate partial mappings from schema analysis. These tools reduce the manual documentation burden but introduce their own dependencies and licensing costs. For smaller integrations, a well-maintained spreadsheet remains the most practical solution.