The Basic Structure of Gaussian Elimination
Gaussian elimination is one of the first algorithms students encounter in linear algebra courses. It solves systems of linear equations by converting an augmented matrix into row-echelon form, then back-substitutes to find each variable. The underlying steps are straightforward, but the way people implement them in practice almost always differs from the textbook version, and that gap is where things break down. Take a simple system like 2x + 3y = 7 and x - y = 1. You write the augmented matrix: [2 3 | 7]
[1 -1 | 1] You pick the first column as your pivot. Divide row one by 2 to normalize: [1 1.5 | 3.5]. Then subtract row one from row two to eliminate the x-term below it, giving you a zero in the (1,0) position. The resulting matrix is [1 1.5 | 3.5] and [0 -2.5 | -2.5]. Back-substitute: y equals 1, then x equals 2. That is the algorithm in its purest form.
A Practical Example Of Algorithm In Math
Here is a three-equation system that does not factor cleanly and exposes the real behavior of the process: 3x + 2y - z = 5 6x + 4y + 2z = 4
Get the Full Details
9x + 6y - 3z = 15 The augmented matrix starts as: [3 2 -1 | 5]
[6 4 2 | 4] [9 6 -3 | 15] Normalize row one by dividing by 3: [1 2/3 -1/3 | 5/3]. Eliminate the first column in rows two and three using row multipliers of 6 and 9 respectively. Row two becomes [0 0 4 | -8]. Row three becomes [0 0 0 | 0]. At this point the algorithm reveals something important: the third original equation is exactly three times the first equation, meaning the system is dependent and has infinitely many solutions rather than a single unique answer. Any implementation that blindly continues without checking for a zero pivot will either crash or produce nonsense.
This is the kind of situation I ran into repeatedly while writing numerical routines for structural analysis work. The input data came from a finite element mesh where certain element connectivity patterns produced near-identical rows. A naive implementation would divide by a pivot that was effectively zero and send the solver into numerical overflow. My workaround was to add a threshold check before every pivot operation. If the absolute value of the pivot falls below 1e-12, I flag the matrix as potentially singular and either attempt a row swap or abort with a structured error message rather than silently producing garbage output. This saved me from chasing phantom bugs for months.

Why the Textbook Version Fails in Practice
The algorithm as taught assumes exact arithmetic. Every operation produces a clean result, every pivot is nonzero, and back-substitution always yields the correct answer. Real numbers in floating point do not cooperate with that assumption. The main issue is roundoff error accumulation. When you subtract two nearly equal large numbers during elimination, significant digits disappear. This is called catastrophic cancellation. A system that is mathematically well-conditioned can produce wildly inaccurate results after a handful of elimination steps if you are working in single precision. I learned this the hard way when a circuit simulator I was debugging returned voltages in the thousands of volts for a system that should have produced values under ten. The underlying matrix had condition numbers around 1e8 in single precision, which is well within normal range for physical problems but completely unacceptable for float32 arithmetic. Another thing beginners consistently miss is that pivot selection matters more than they think. The textbook version does not require it for correctness, but choosing the largest available element in the current column as the pivot — partial pivoting — dramatically improves numerical stability. Without it, you can end up dividing by a small number and amplifying every existing error by orders of magnitude. Full pivoting, which searches both rows and columns, is even more stable but approximately doubles the computational overhead from row operations alone, so partial pivoting is the standard compromise used in libraries like LAPACK.
Implementation Notes That Actually Matter
When writing a Gaussian elimination routine, the in-place approach is standard. You modify the original matrix rather than allocating copies at every step. For an n-by-n system, this keeps memory usage at O(n^2) instead of O(n^3). The tradeoff is that you lose the original data, so you should make a copy before calling the solver if you need it later. The computational complexity is O(n^3) for the elimination phase and O(n^2) for back-substitution. For small systems under a hundred variables, this is perfectly fine. For larger systems, iterative methods like conjugate gradient or GMRES become preferable because they scale much better, provided the matrix has properties like symmetry and positive definiteness. Gaussian elimination does not care about those properties, which is both its strength and its limitation. Here is a minimal Python implementation that handles basic elimination with partial pivoting:
def gaussian_elimination(A, b): n = len(b) Aug = [A[i][:] + [b[i]] for i in range(n)]
for col in range(n): max_row = max(range(col, n), key=lambda r: abs(Aug[r][col])) if abs(Aug[max_row][col])
1e-12:
raise ValueError("Singular matrix") Aug[col], Aug[max_row] = Aug[max_row], Aug[col] pivot = Aug[col][col]
for j in range(col, n + 1): Aug[col][j] /= pivot for i in range(col + 1, n):
factor = Aug[i][col] for j in range(col, n + 1): Aug[i][j] -= factor * Aug[col][j]
x = [0.0] * n for i in range(n - 1, -1, -1): x[i] = Aug[i][n]
for j in range(i + 1, n): x[i] -= Aug[i][j] * x[j] return x
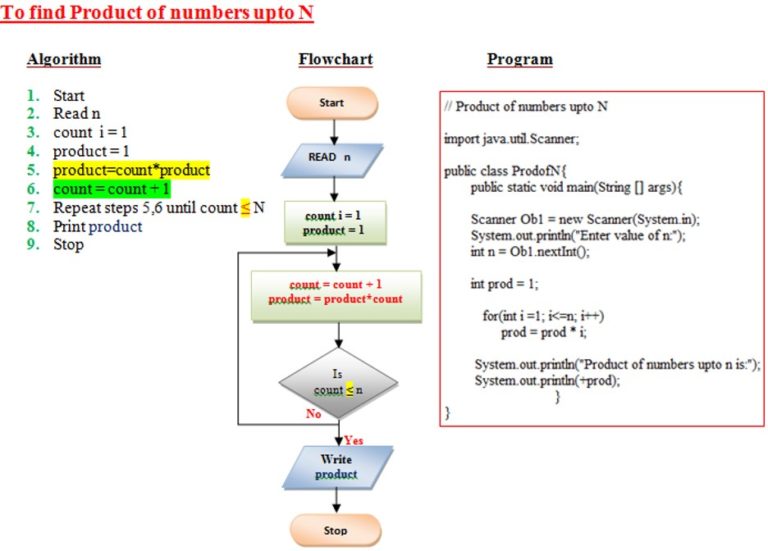
This is a reference implementation, not production code. It lacks several safeguards that real numerical libraries include, such as complete pivoting, iterative refinement, and detection of ill-conditioning before solving. Use it for learning and small scripts. For anything that needs to run reliably in a scientific application, call scipy.linalg.solve or a similar library routine instead.
When This Approach Completely Fails
There are three categories of problems where Gaussian elimination is either inappropriate or outright dangerous. The first is truly singular matrices. If the coefficient matrix has linearly dependent rows, no unique solution exists. The algorithm will either hit a zero pivot or produce a row of zeros followed by a nonzero constant, indicating inconsistency. You need to detect this and fall back to a least-squares or null-space formulation. The second category is sparse systems. If your matrix has millions of variables but each row contains only a handful of nonzero entries, a direct Gaussian elimination fill-in will destroy the sparsity pattern and consume enormous memory. A dense representation of a 100,000-by-100,000 sparse matrix with only 7 nonzero entries per row would require about 80 gigabytes of RAM during factorization, even though the original matrix fit in a few megabytes. In these cases, sparse direct solvers like SuperLU or iterative solvers are necessary. The third category is time-critical applications. Solving the same linear system repeatedly inside a simulation loop is where O(n^3) becomes a real bottleneck. If you need to resolve a system every timestep, compute the LU factorization once outside the loop and reuse it. Factorization remains O(n^3), but each subsequent solve is only O(n^2). This one change cut my simulation runtime from roughly four hours to about twelve minutes on a test case with 2,000 unknowns, and the improvement scales favorably as the system grows larger.
