Understanding Independent Variables in Mathematics
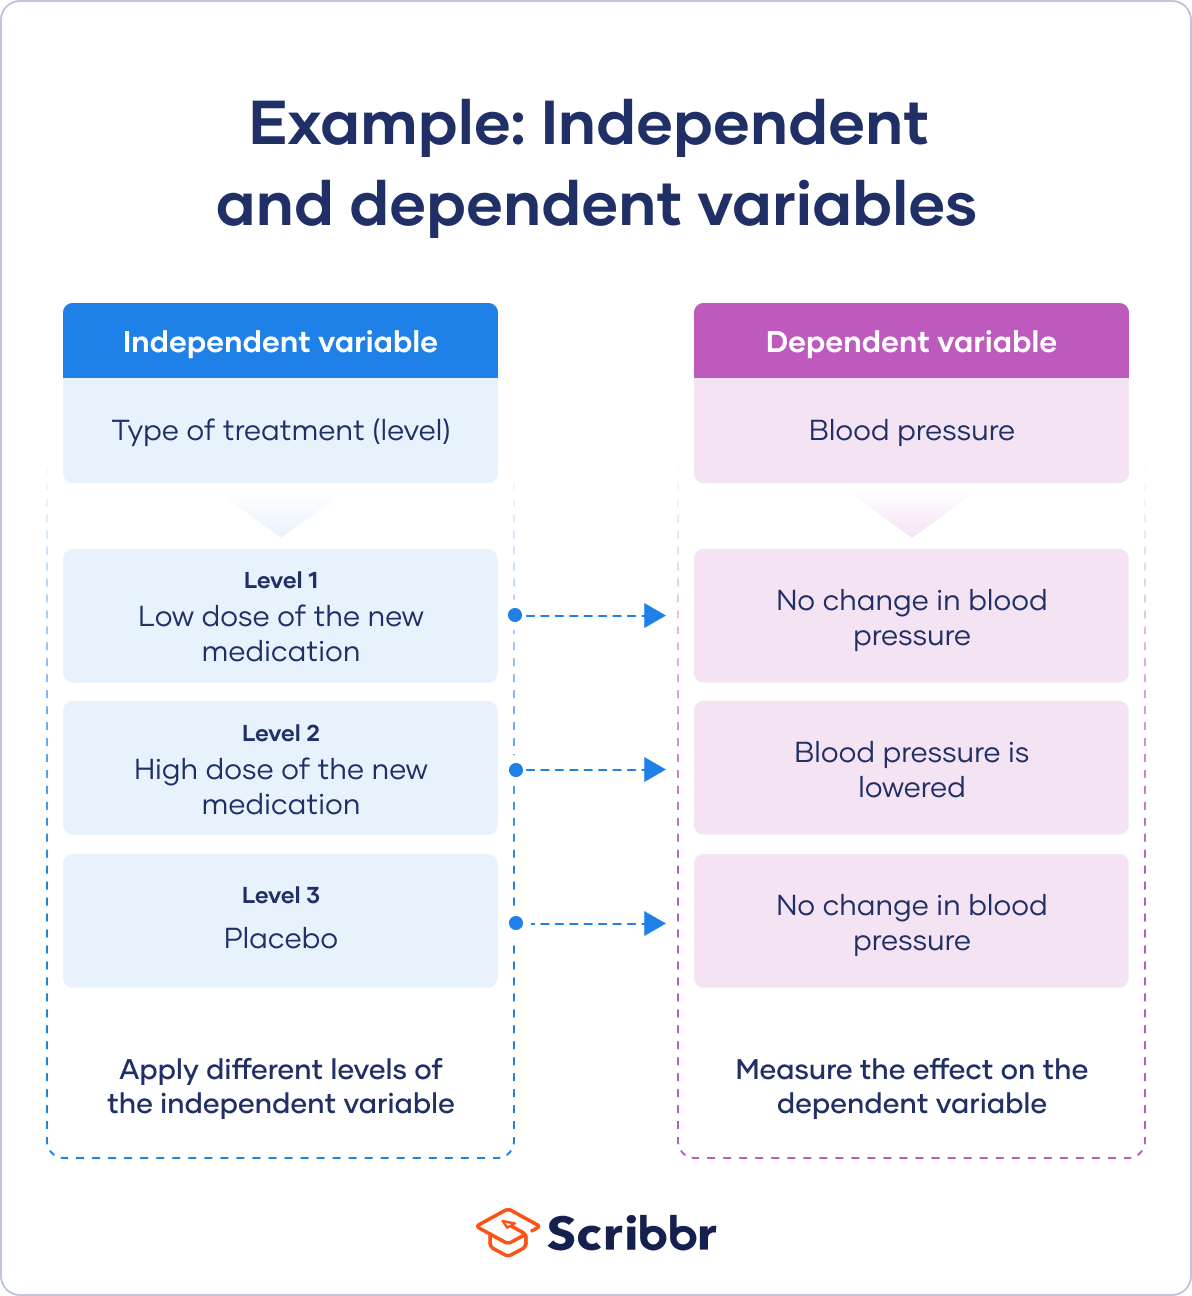
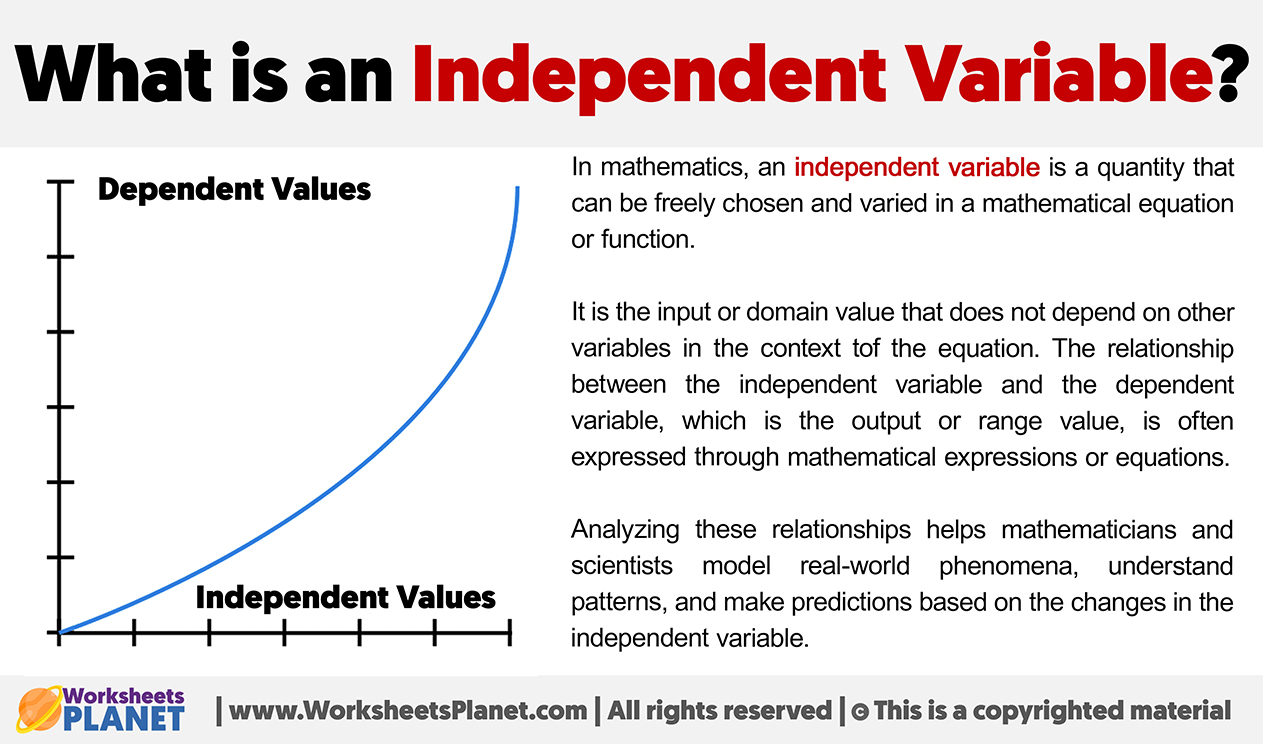
When you're graphing functions or running regression models, the independent variable is just the input you control. It's what changes on its own, and the dependent variable responds to it. That's basically it. The confusion starts when people mix up which is which, or try to apply this to situations where the relationship isn't clean. I've sat through more than a few grad student presentations where someone plotted their data and labeled the axes wrong. It's not a big deal in the grand scheme of things, but it can completely invalidate a whole analysis if you realize too late that your x and y got swapped. Happened to me once in 2019 with a climate dataset I was working on. I'd been treating temperature as the independent variable when actually my hypothesis required precipitation to drive the model. Didn't catch it until a colleague pointed out that the residuals looked nonsensical. Took me about ten minutes to flip the labels and rerun the regression, but that morning was wasted.
Example Of Independent Variable In Math
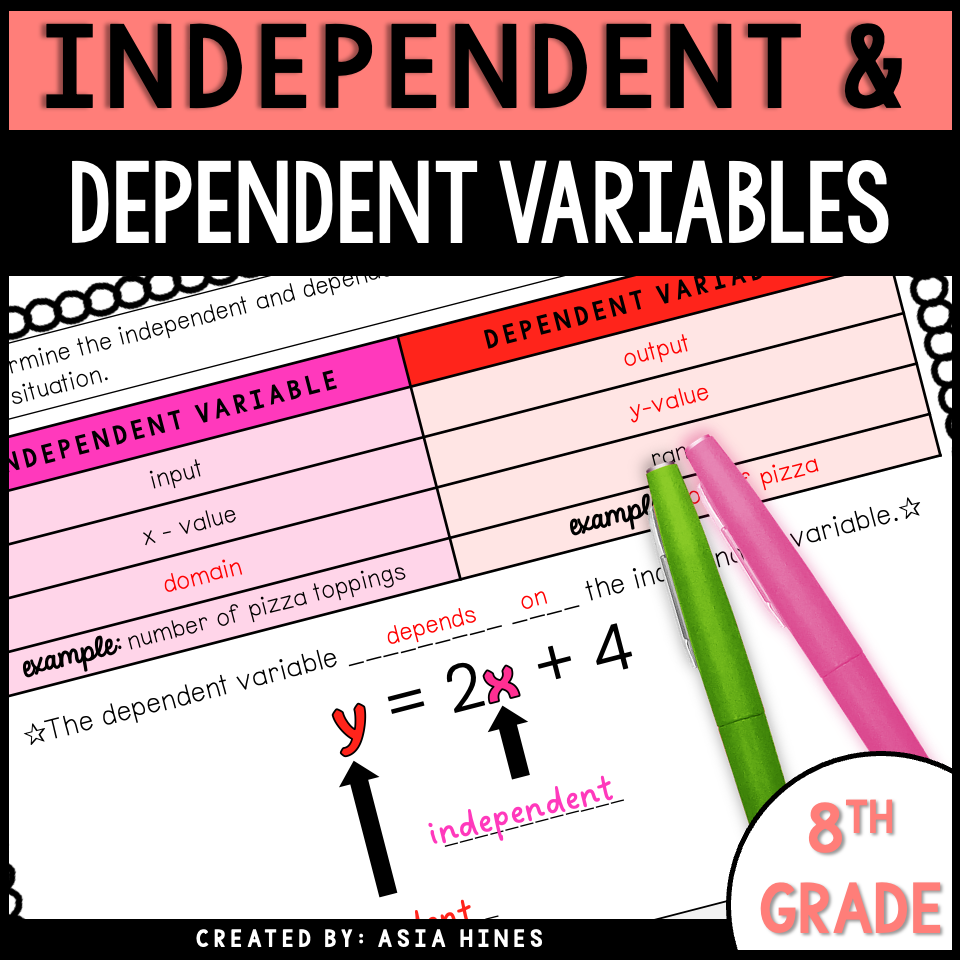
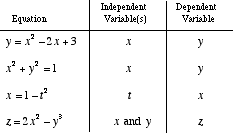
Here's a straightforward case. You're studying how the number of hours a student studies affects their exam score. Hours studied is the independent variable. Exam score is the dependent variable. You set the hours. The score follows. In equation form, that's y = f(x). x is independent. y depends on x. In a linear version: y = mx + b. You choose x values. The calculator gives you y values. Simple enough for a first-year algebra class. But math gets messier than that quickly. Consider an example like this: y = 3x² - 2x + 1. Here x is still the independent variable. You can plug in any real number and get a result. The shape of the parabola doesn't change that fact. What does change is understanding what x actually represents in context. If x is time in seconds, and y is distance in meters, then the independent variable has a physical meaning. If x is just a label for group membership (like 1 = control group, 2 = treatment group), you're dealing with a categorical independent variable, and you shouldn't be fitting a quadratic curve to it without a really good reason.
Another thing beginners miss: the independent variable isn't always the one on the horizontal axis. In physics, if you're measuring free fall, time is the independent variable and it goes on the x-axis. But in some economics papers, they plot price on the horizontal axis and quantity on the vertical, even though quantity depends on price. The convention in economics is to put the "cause" on the x-axis, which aligns with the math definition, but the visual layout can reverse the typical expectation. Just be aware of it so you don't get tripped up when reading someone else's work. There's also the issue of multiple independent variables. In a model like z = 2x + 4y - 3, both x and y are independent. You control both. The output z responds to changes in either. This is where partial derivatives come in, but that's calculus territory. The core idea stays the same: independent variables are the ones you manipulate or select values for. One practical tip that actually helps. When you're setting up an experiment or assigning values in a spreadsheet, always explicitly define which column or input is independent before you write any formulas. I keep a simple legend in the header row of my files. It takes three seconds and saves you from wondering later whether you accidentally made y the input in some intermediate calculation.
Get the Full Details
The bigger problem people face isn't identifying the independent variable. It's knowing when the relationship breaks down. If you're fitting a line through data where the independent variable has measurement error, ordinary least squares regression will give you biased results. This is called attenuation bias, and it shows up whenever your x values aren't exact. A quick fix is to use errors-in-variables regression or instrumental variable methods, but most introductory courses skip that entirely. You'll learn about it later if you stay in statistics. Also worth noting: discrete versus continuous independent variables matter more than students realize. If your independent variable can only take integer values, like the number of siblings someone has, you can't meaningfully talk about the derivative at x = 2.5. The function only exists at specific points. Some software will interpolate between them anyway, which looks smooth but is technically constructing data that isn't there. I've seen people publish results based on cubic spline interpolation of discrete independent variables and treat the output as if it were continuous. It's a gray area, but it's worth flagging if you're doing anything formal. If you need to explore this further, Khan Academy has a decent section on variables and functions. For something more hands-on, Desmos lets you play with sliders on the independent variable and watch the dependent variable shift in real time. It's not a substitute for understanding the underlying mechanics, but it builds intuition faster than staring at equations alone.
Quick reference for common cases
Linear function: y = 5x + 2. Independent variable is x. Quadratic function: y = x² - 4x + 7. Independent variable is x. Multivariable: z = 3a + 2b - c. Independent variables are a, b, and c.
Table data: when given a table of values, the first column is typically the independent variable unless the source says otherwise. Verify before you assume. Scatter plot: the variable you can predict from is independent. The variable you're trying to predict is dependent. The arrow of causation matters here, not just which axis sits where. That should cover the basics. The independent variable is the input you set or observe. Everything else flows from it. Get that right and the rest of the math follows. Get it wrong and you're debugging someone else's problem instead of solving your own.