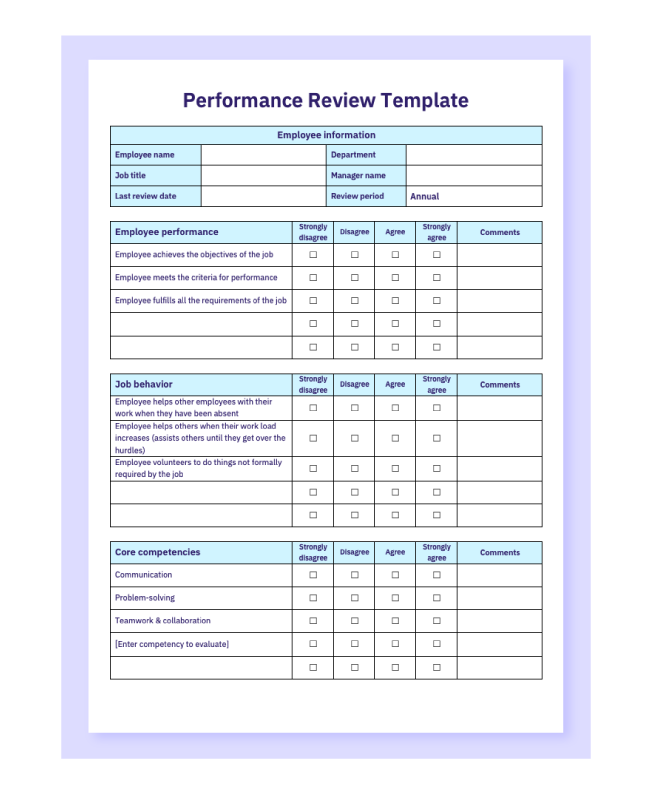
Performance Assessment That Doesn't Feel Like a Waste of Everyone's Time
Most companies do performance reviews wrong, and the results are predictable. People either inflate scores to avoid awkward conversations or slash ratings to make themselves look like decisive managers. Either way, the data comes back useless six months later when someone needs to decide who gets promoted or let go.
I spent three years building a system that actually survives contact with reality. The method started with a simple problem: our engineering team had twelve different rating scales depending on who was managing them. One manager used a five-point Likert scale, another used a percentage score, a third just wrote paragraphs and hoped for the best. You cannot compare apples, oranges, and a paragraph about someone's lunch habits when you're trying to identify high performers across a department.
Concrete Example Of Performance Assessment
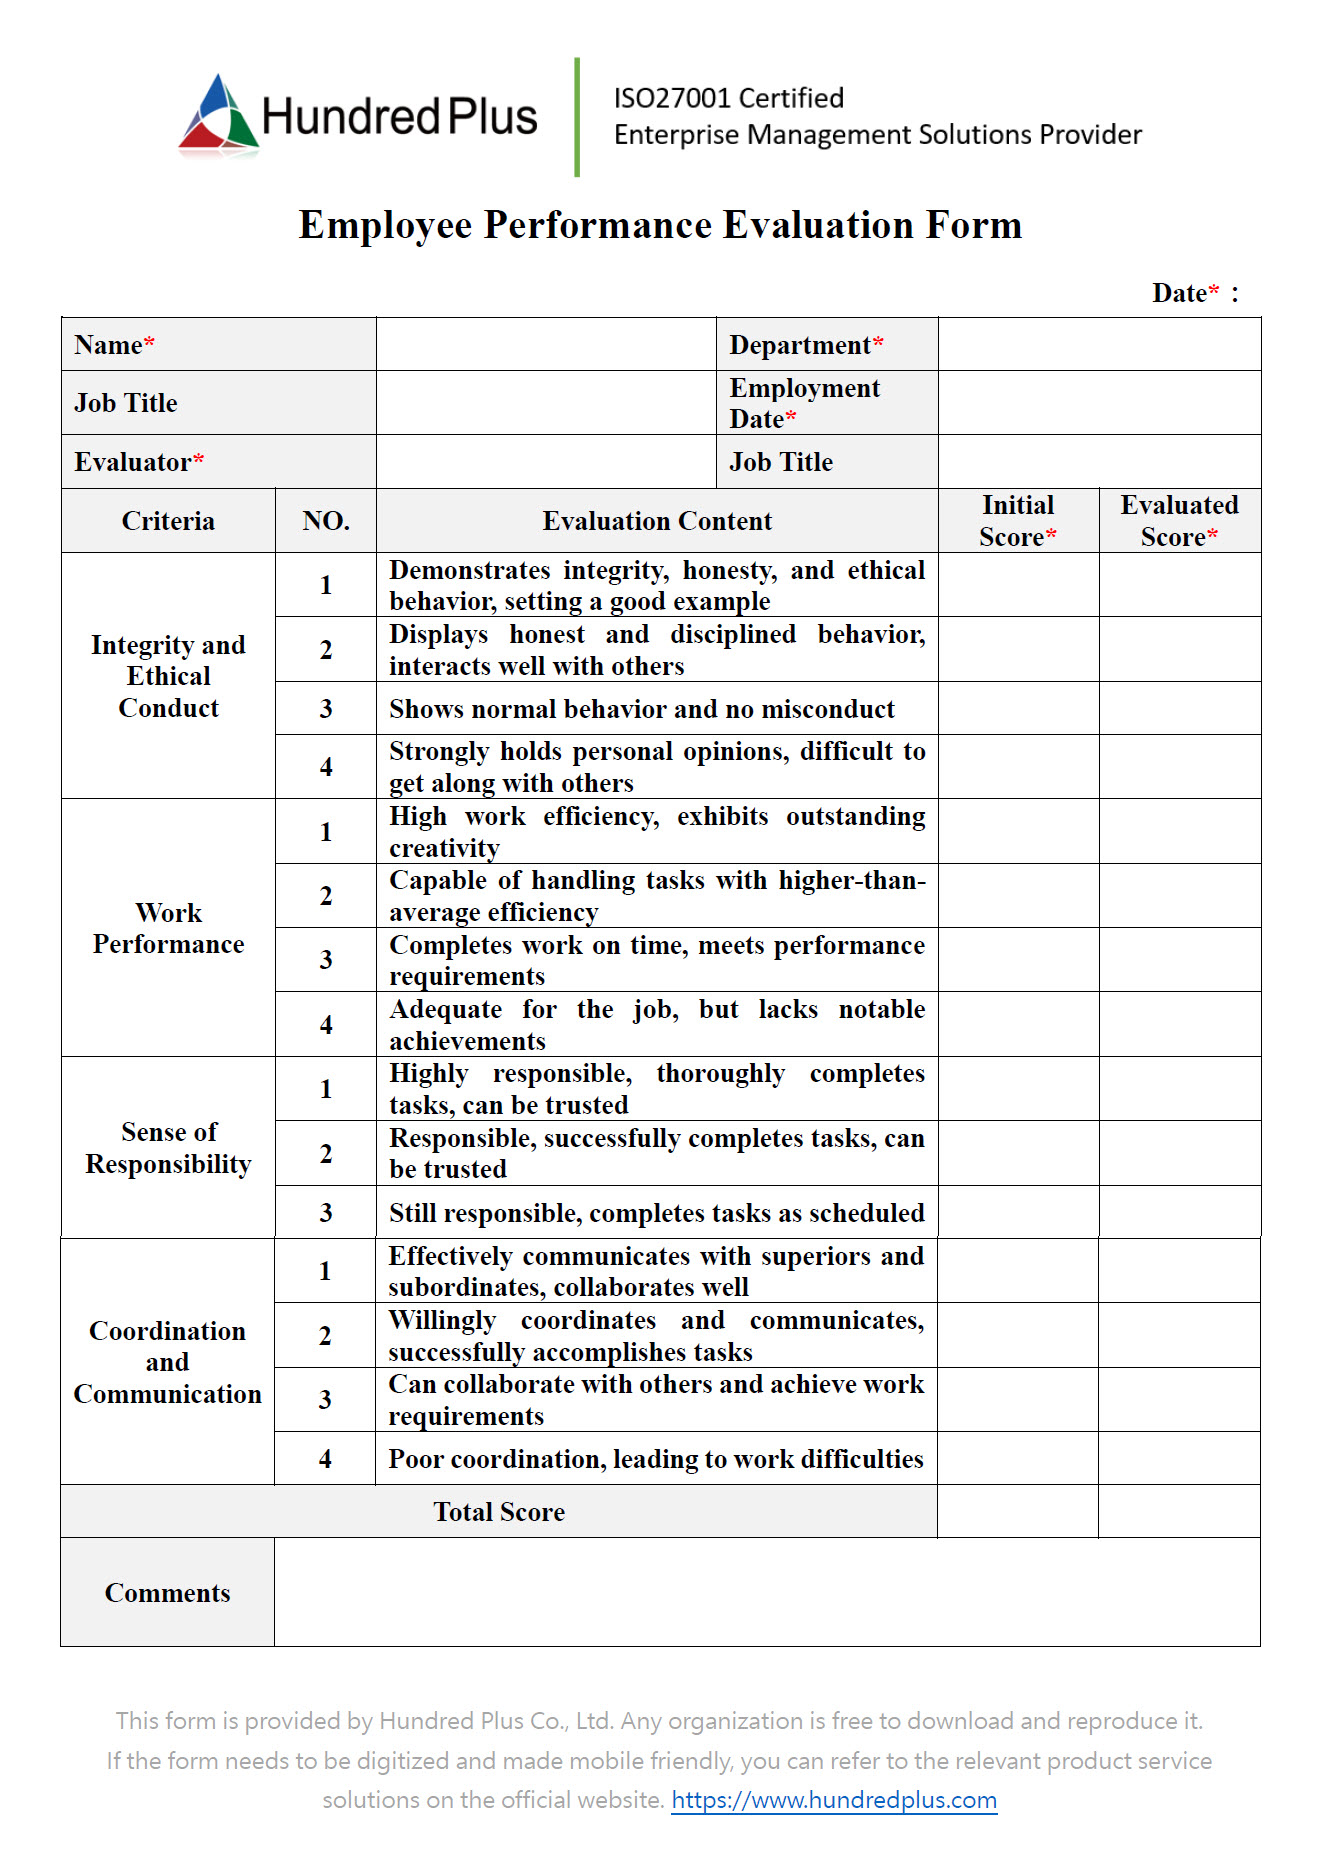
Here is what I consider a working model. Take a mid-level software engineer named Sarah. Her performance assessment would be structured around four dimensions, each with explicit behavioral anchors that leave zero room for vague interpretation.
Technical Execution: Measured by production incidents attributed to her work, code review turnaround time, and whether deliverables shipped within the estimated window. Not whether she wrote elegant code. Whether she shipped working code.
Collaboration Impact: This one always catches people off guard. It is measured by 360-degree feedback from at least five colleagues she worked with in the evaluation period, weighted by how frequently she interacted with each person. A single manager opinion accounts for no more than thirty percent of the total score.
Business Outcome: This is the dimension most managers mess up. It is not about how hard she worked. It is about whether the projects she touched moved the metric the business cared about. If Sarah built a feature that shipped on time but was never used, her score in this category is low. Period.
Growth Trajectory: Measured against her own baseline from six months prior, not against other people. Did she improve? By how much? What did she learn that she did not know before?
I will share a specific edge case that nearly broke this system for us. We had a senior engineer, Marcus, who consistently scored in the bottom percentile across three of the four dimensions. By the numbers, he looked like a poor performer. The problem was that Marcus operated almost entirely in the architecture review queue. He spent his days preventing disasters that never made it into production. His incident count was zero because he caught issues before anyone deployed them. He also mentored every junior engineer on the team, which was invisible to the business outcome metric since mentorship was not tracked.
The workaround was straightforward but required an additional fifth dimension: preventive impact. We measured it by counting the number of architectural review comments he made, the false positives he caught during design reviews, and the retention rate of engineers he mentored. This pushed his overall score into the middle range, which felt far more accurate. It also revealed a structural problem: Marcus was doing work the company did not have a standard metric for, and that is a management failure, not an employee failure.
The actual process takes about forty-five minutes per employee for their manager, plus another thirty for the calibration session where all managers sit together and compare notes. Without calibration, the inflation problem returns immediately. Managers who like everyone ends up with an average score of 4.3 out of 5, while the organization needs actual discrimination between levels. Calibration sessions typically take two hours for a department of twenty people, and that time is worth every minute.
Here is a practical caveat that nobody mentions in the HR textbooks. Performance assessment breaks down completely for roles where output is purely collaborative and indivisible. If you are on a small team shipping one product, you cannot isolate individual contribution with any accuracy. The numbers will look precise but they will be meaningless. In those cases, the assessment should shift from scoring to narrative documentation, and the calibration process becomes almost entirely qualitative. You can score a solo contributor. You can score a person whose work separates cleanly from others. You cannot score someone who co-authored a database migration with four other people and then handed it off.
Another counter-intuitive thing I learned: the more transparent you make your metrics, the more people will game them. After we published the incident count as a scoreable metric, two engineers deliberately avoided reviewing each other's code to reduce their own incident count. They shifted the risk onto the people who did not track metrics. Once we realized this was happening, we changed the approach and made incident data part of a confidential calibration document rather than a visible scoreboard. People still had feedback about it, but they could not optimize for the number.
The biggest limitation of any structured performance assessment is that it captures the past, not the potential. You can measure what someone did last quarter with reasonable accuracy. You can barely guess what they will do next quarter, and pretending otherwise is just corporate theater. I recommend pairing any quantitative assessment with a separate conversation about trajectory, skills the person wants to develop, and whether their current role still fits them. That conversation rarely appears in the written document, and that is fine. Some things should not be scored.
I have used versions of this system for eight years now, and the core insight remains the same: clarity beats comprehensiveness. Four dimensions with explicit definitions will outperform twelve dimensions with vague ones every single time. The goal is not to capture everything about an employee. The goal is to give the company enough signal to make a decision it can stand behind when someone inevitably asks why.
Gallery Example Of Performance Assessment
Performance Assessment Form Examples – YXIPX
19+ Performance Assessment Examples to Download | Examples.com
Employee Performance Report Example
Performance Appraisal Example
Employee Performance Review Examples | Employee performance review sample, How to write a ...