Understanding Populations in Ecology
A population is a group of individuals of the same species living in the same geographic area at the same time, and that definition sounds simple until you actually try to count them in the field. The tricky part is deciding what "same area" means. Are we talking about a forest, a pond, a watershed, or just the suitable habitat within a larger region? Your answer changes everything downstream. I spent three years studying Eastern Chipmunks in fragmented oak forests in central Pennsylvania, and the first problem I hit was that the standard mark-recapture method completely fell apart during wet springs. The traps worked fine, but the chipmunks shifted their home ranges dramatically after heavy rain events, meaning the assumption of a closed population between sampling sessions was violated. I ended up using a spatially explicit capture-recapture model instead of the classic Lincoln-Petersen estimator, which accounts for animal movement and home range overlap. It took about twice as long to process the data, but it gave me confidence intervals that actually meant something.
Example Of Population In Biology
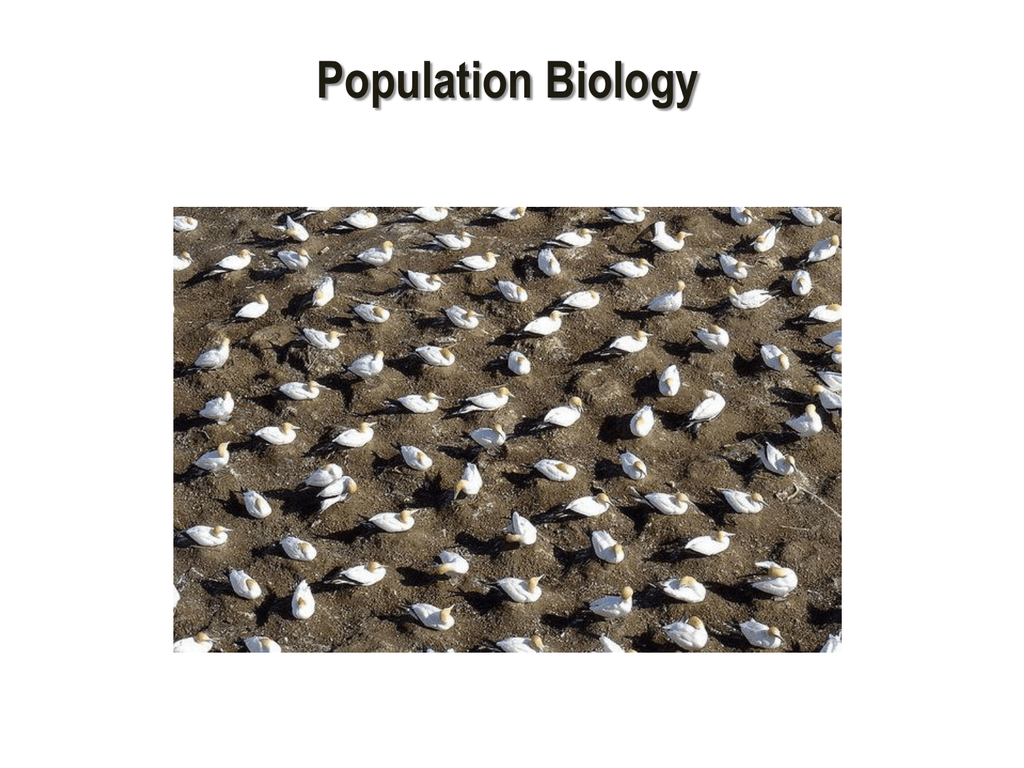
Here is a concrete Example Of Population In Biology that comes up constantly in introductory courses and field research alike. Consider a school of Atlantic Cod in the Gulf of Maine. All individuals belonging to the species Gadus morhua within that defined water mass, interacting and potentially interbreeding, constitute a single population. You could study their birth rate, death rate, age structure, and genetic diversity. That is the basic unit of ecological and evolutionary analysis. But the real work starts when you ask how you measure anything about that population. Population density is one of the first metrics you need, and it is also the one people get wrong most often. Density is not the same as abundance. Abundance is a raw count. Density is count divided by area or volume. A million insects in a square kilometer is a very different ecological situation than a million insects in a thousand square kilometers, even though the abundance number is identical. The methods for estimating population size fall into a few categories, and each has conditions where it works well and conditions where it quietly gives you garbage results. Direct counting through total enumeration only works for large, conspicuous organisms in small areas. You can count nesting penguins on a remote island or deer in an enclosed reserve. For anything mobile, cryptic, or spread across a large landscape, you need indirect estimation.
Mark-recapture is the standard approach for mobile animals, and the basic logic is straightforward. You capture a sample, mark them in a way that does not affect their survival or behavior, release them back into the population, then after some time capture another sample and record how many are already marked. The ratio of marked to unmarked in the second sample lets you estimate total population size. The formula is N equals M times C divided by R, where M is the number marked in the first sample, C is the total captured in the second sample, and R is the number of recaptured marked individuals. The problem is that this formula relies on five strict assumptions: the population is closed, marks are not lost, marked individuals mix randomly with unmarked ones, marking does not affect catchability, and sampling is random. In practice, at least one of these is almost always violated. Closed populations rarely exist in nature. Immigration and emigration happen. Marks fall off. Some animals learn to avoid traps after one bad experience, which biases the estimate downward. Others become trap-happy if the bait works well, biasing it upward. When I worked with amphibian populations in vernal pools, I encountered a situation where the assumption of equal catchability broke down completely because the breeding season creates a temporary aggregation. Males arrive first and defend territories, so they are caught at much higher rates than females or late-arriving males. If you just apply the Lincoln-Petersen estimator to that data, you will severely underestimate the true population size. The workaround is to use a robust design model that separates the demographic process from the observation process, or to sample across multiple periods and model detection probability explicitly using programs like MARK or R packages such as RPresence.
Get the Full Details
For plants and sessile organisms, quadrat sampling is the go-to method. You lay out frames of known area and count every individual inside them, then extrapolate. The key detail that beginners consistently mess up is random placement of quadrats. If you place them along a trail or in areas that look interesting, your density estimates are biased toward higher values. You need a proper random or systematic sampling design, and you need enough replicates to capture the natural heterogeneity of the habitat. Another approach that gets mentioned less but is valuable for certain systems is distance sampling. You walk transects and record the distance to each observed individual. The detection probability declines with distance from the transect line, and fitting a detection function to those distances lets you estimate density without needing to mark or recapture anything. This is widely used for birds, mammals, and marine organisms. The downside is that it requires a reasonably large sample of detections to fit the detection function reliably, and it assumes animals do not move in response to your approach, which is frequently not true for wary species. Population parameters extend beyond just size and density. Birth rate, death rate, immigration rate, and emigration rate together determine whether a population is growing, shrinking, or stable. The basic population growth equation is dN/dt equals r times N, where r is the intrinsic rate of increase and N is population size. When resources are unlimited, this produces exponential growth. When resources constrain the population, you get logistic growth, where the carrying capacity K slows growth as N approaches it.
The limitation of the logistic model is that real populations rarely track a smooth carrying capacity. Environmental stochasticity, delayed density dependence, and Allee effects at low densities all introduce deviations that the basic model does not capture. I have seen researchers fit logistic curves to population time series where the data clearly showed cyclic dynamics, probably driven by predator-prey interactions or resource pulses. The model looked decent in a visual sense but gave misleading projections because it ignored the underlying mechanism. Age or stage structure matters a lot for populations that reproduce iteratively or semelparously. A population of Douglas-fir trees and a population of annual weeds with the same total abundance have completely different growth trajectories because their age distributions are different. Matrix population models, like Leslie matrices for age-structured populations or Lefkovitch matrices for stage-structured populations, let you incorporate survival and fecundity at different life stages into projections. The dominant eigenvalue of the matrix gives you the asymptotic growth rate, and the corresponding eigenvector gives you the stable age distribution. Life table construction is another practical tool. You follow a cohort from birth to death and record age-specific survival and reproduction. The net reproductive rate R-zero tells you whether each female is replacing herself, and the generation time tells you how fast turnover occurs. These values feed directly into population viability analysis, which is the standard method for assessing extinction risk in endangered species.
PVA has its own set of problems. It requires good parameter estimates, which are often unavailable for rare or poorly studied species. It tends to overestimate extinction risk when demographic and environmental stochasticity are modeled independently, because in reality some forms of stochasticity are correlated. I once reviewed a PVA for a small mammal where the input survival rates came from a different geographic population with notably different predation pressure. The resulting extinction probability was entirely meaningless, and the authors had no way to know it until someone independently checked the source data. Genetic considerations also matter for population-level analysis. Effective population size, denoted Ne, is usually much smaller than the census population size N. The ratio Ne over N determines how quickly genetic drift erodes variation, and for most vertebrate populations it falls somewhere between 0.1 and 0.5. Small effective population sizes lead to inbreeding depression and reduced adaptive potential, which matters enormously for conservation decisions. The 50 over 500 rule, which suggests that Ne of 50 is needed to avoid short-term inbreeding and Ne of 500 for long-term evolutionary potential, is a useful shorthand but oversimplifies what we now know about genetic management. Modern tools have made population estimation more powerful but also more accessible to people who do not fully understand the underlying assumptions. Software like Program MARK, CAPWIRE, and various R packages can run sophisticated models with a few lines of code. The danger is that it is easy to run a complex model on poor-quality data and get a precise-looking answer that is wrong. I always recommend starting with simple descriptive statistics and checking whether your data meet the basic assumptions before reaching for anything complicated.
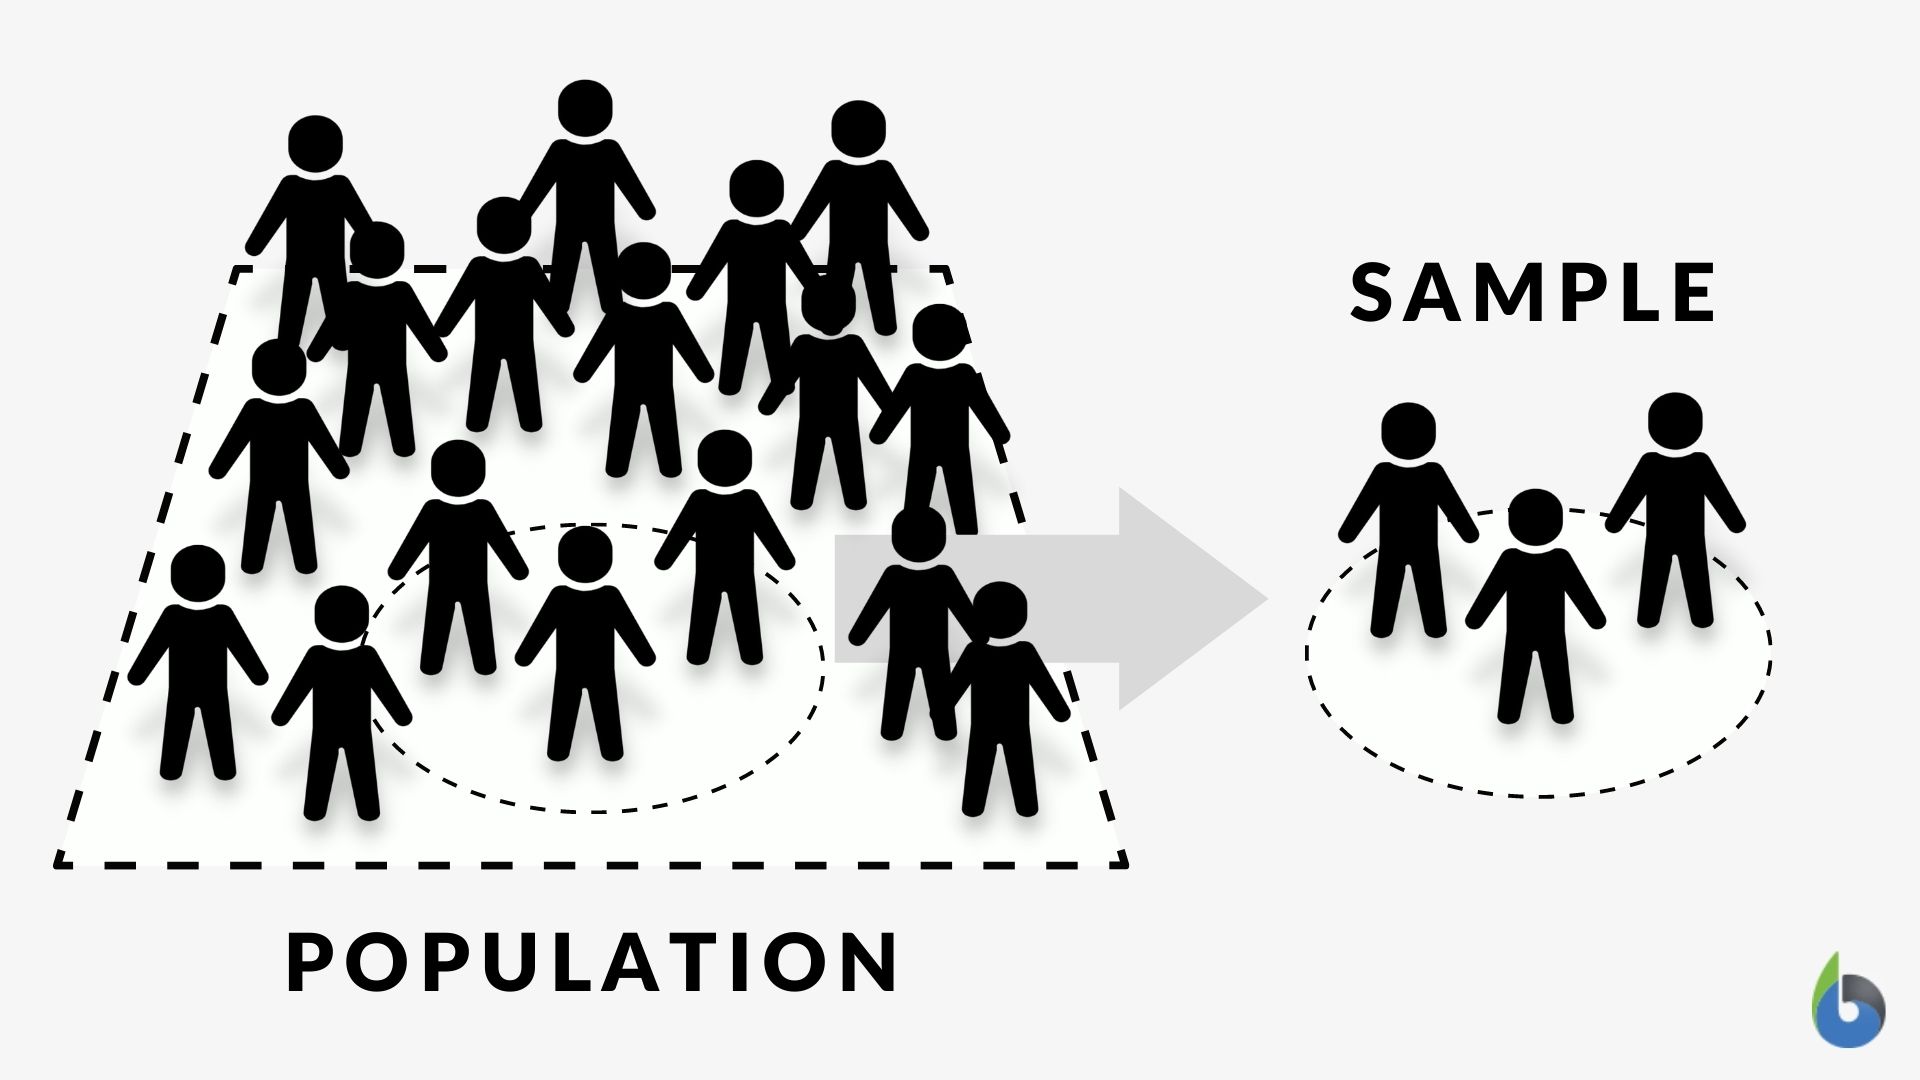
Another practical issue is the scale mismatch between what you can measure and what you need to know. You might estimate density in a hundred hectares of forest, but the relevant population for a management decision could span a thousand hectares across multiple ownerships. Local estimates do not automatically scale up, and assuming they do is a common source of error in both academic papers and agency reports. You need either a hierarchical sampling design or a clear statement of the spatial extent your conclusions apply to.
Common Pitfalls in Population Studies
Some mistakes happen repeatedly across different taxa and study systems. One is confusing the study population with the target population. Your sampling frame defines what you can measure, but your inference might need to apply to something broader. A bird count along roadside transects estimates abundance along roadsides, not abundance across the entire landscape, because birds respond differently to traffic noise and habitat edges. Another pitfall is ignoring detection probability entirely and treating raw counts as if they were absolute abundances. This is extremely common in citizen science datasets and opportunistic observations. A rising count does not necessarily mean a rising population. It might mean observers are looking harder, using better equipment, or the species is more visible during certain seasons. Habitat heterogeneity within your study area can also bias estimates if your sampling does not account for it. Stratified random sampling, where you divide the area into habitat types and sample proportionally within each, reduces this bias compared to purely random placement that might accidentally oversample one habitat type.
The bottom line is that estimating a population is never just a calculation. It is a series of decisions about what counts as the population, how you sample it, what assumptions you are willing to make, and how much uncertainty you need to report. The numbers matter, but the method behind them matters more.