What Actually Happens When a Test Question Is Biased
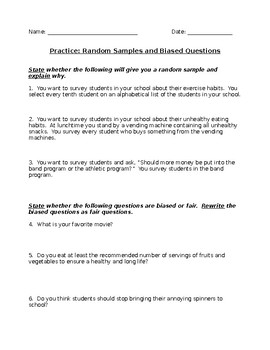
Test bias isn't usually some dramatic, intentional scheme. It's just a series of small, careless choices that pile up over months of question writing. You pick a scenario that assumes urban living, you reference a brand only people in a certain region know, you write a math word problem that requires understanding how American property taxes work before you can even solve the math. Anyone who hasn't lived that specific slice of life is now being tested on something that has nothing to do with what the question claims to measure. I've spent years reviewing exam items for state certification boards and internal corporate assessments. The worst part isn't finding the bias — it's realizing how much of it is completely invisible to the person who wrote it. You read your own question and it reads fine. It reads normal. The bias only shows up when you cross-reference the response data across demographic segments, and by then the test has already been administered twice.
Concrete Examples Of Biased Test Questions
Here are a handful of real patterns I've flagged, the mechanics behind why they're biased, and what a non-biased version looks like. Scenario 1: Cultural assumed knowledge A reading comprehension passage asks test-takers to interpret a scenario involving a "tailgate party." Someone who has never been to a North American college football tailgate may still understand the literal events described, but students raised in environments where that tradition doesn't exist have to expend extra cognitive load decoding a cultural reference point rather than demonstrating comprehension. The fix is straightforward: replace the scenario with a universally describable situation, or provide a neutral definition inline without drawing attention to the substitution.
Scenario 2: Gendered language in technical questions I once reviewed a certification exam where every plumbing question featured characters named "Mike" and "Steve" performing repairs, while the electrician questions used "Linda" and "Carol." The content difficulty was identical. The pattern was unconscious, not malicious. Still, it sends a subtle signal about who belongs in which trade. Removing the names entirely and using neutral descriptors like "the technician" eliminated the gendered framing without changing a single technical requirement. Scenario 3: Socioeconomic assumptions in math problems
Get the Full Details
A financial literacy question asked test-takers to calculate interest on a savings account that starts with $5,000 and requires understanding of 401(k) contribution limits. For students who have never had access to investment accounts or whose families don't discuss retirement planning, this tests background exposure, not mathematical ability. A version that uses a simpler borrowing-and-repayment scenario with clearly stated terms measures the same skill without the socioeconomic gatekeeping. Scenario 4: Accessibility through format, not content This one costs people their certifications. A nursing exam included a question with a diagram of an ECG reading where the lines were rendered in shades of red and green. Students with common forms of color vision deficiency couldn't distinguish the waveforms. The question tested ECG interpretation. Color blindness shouldn't be part of the construct. Switching to patterns and labels on the waveform — stippling for one line, solid for another — fixes this in about ten minutes and requires no content rewriting.
I want to pause here because most people stop at the examples and move on. The examples are the easy part. The hard part is building a process that catches these before they reach test-takers.
The Review Process That Actually Works
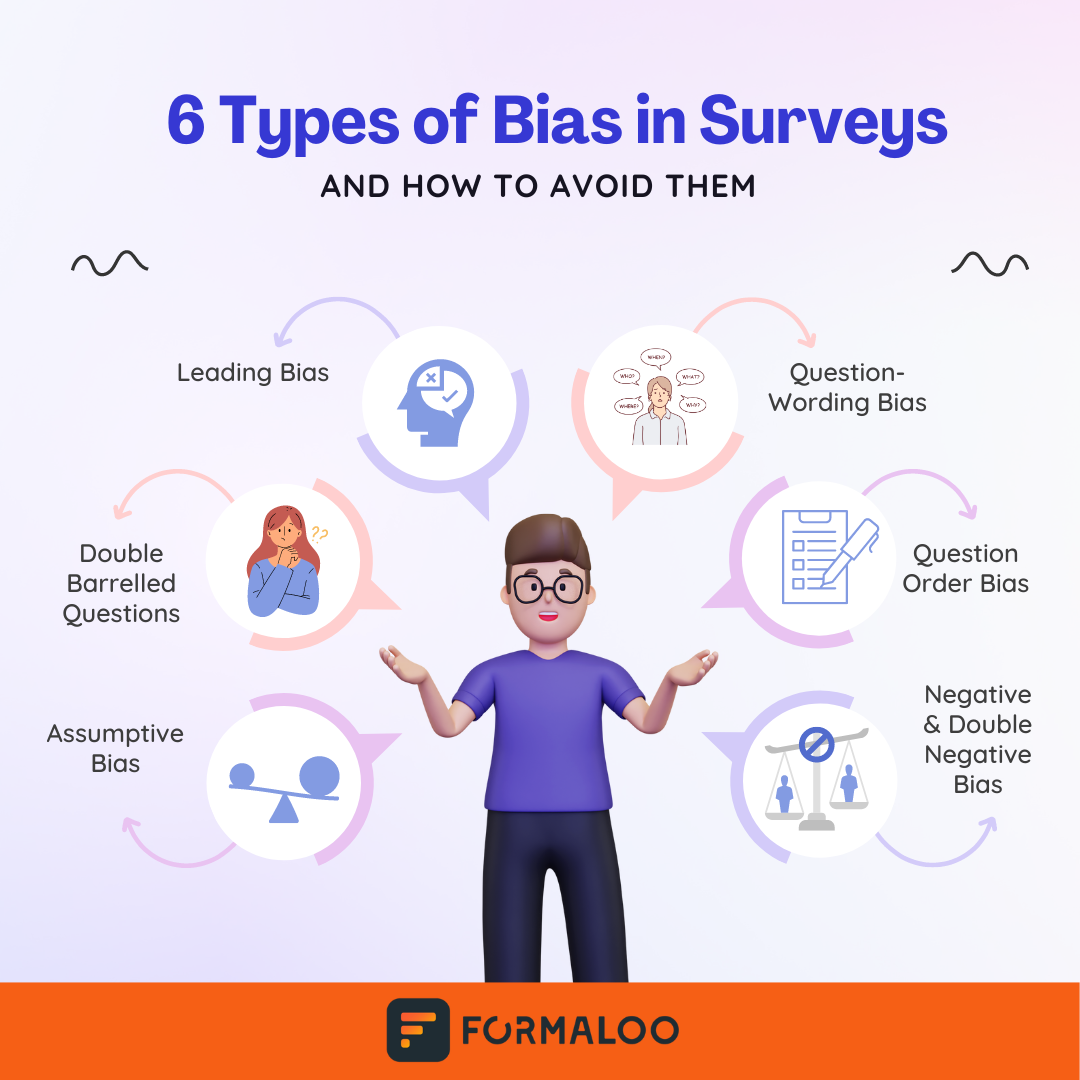
I used to rely on peer review, where two colleagues would read each other's questions and flag anything that felt off. That approach caught maybe thirty percent of bias issues. The rest slipped through because both reviewers shared the same cultural baseline, the same educational background, the same blind spots. It sounded rigorous. It wasn't. The method I switched to combines three layers. Layer one is a structured bias checklist applied to every question before it enters the pool. Layer two is differential item functioning analysis, or DIF, run on pilot data. Layer three is focus group review with people who match the demographic profile of the target population but aren't involved in question development. The checklist itself is boring and that's the point. Each question gets scored on a set of criteria: assumed cultural knowledge, gendered language, socioeconomic prerequisites, accessibility barriers, geographic specificity, and age-sensitive references. Any question scoring above a threshold on any single criterion gets flagged for revision or discard. This takes roughly five minutes per question on average once your team is trained on it. Before training, it takes about twenty because you're still learning what to look for.

DIF analysis is where the invisible bias becomes visible. You administer pilot items to a representative sample, then statistically compare performance between demographic groups who have the same overall ability level. If Group A consistently answers a question correctly at a rate significantly higher than Group B at the same ability level, that question has differential functioning. It's measuring something other than the intended construct. I've seen well-intentioned teams skip this step because it requires statistical software and a minimum sample size of about two hundred per demographic segment. That's a mistake that comes back to haunt you during an audit. The focus group layer is the one people resist because it's slow. You recruit eight to twelve people from the target population, give them the question set, and ask them to think aloud as they work through each item. You're not looking for wrong answers. You're looking for confusion that stems from something other than the tested material. When someone stops mid-question and says "wait, do I need to know how Airbnb pricing works for this?" you've found a bias point that no checklist or statistical analysis would have caught. I should be clear about what this process doesn't do. It won't eliminate all bias. It reduces it to a manageable level, which is different. There are edge cases where bias is so deeply embedded in a discipline's terminology that removing it fundamentally changes the question. Medical exams face this constantly — certain medical conditions are more prevalent in specific populations, and when clinical vignettes reflect real-world distribution patterns, minority groups may encounter scenarios they're less likely to have seen clinically. That's a tension between ecological validity and fairness that no review process fully resolves. The best answer is transparency: document which questions carry that risk and monitor outcome data continuously.
Another limitation: DIF analysis detects bias after the fact, not before. You need administered data. If you're building a new exam from scratch with no historical data, your DIF analysis will be weak or nonexistent for the first administration cycle. The checklist and focus groups are your only defenses in that scenario, and they're less reliable than statistical confirmation. Plan for a second iteration after you've collected pilot data. If your organization can't run DIF analysis or conduct focus groups, start with the checklist alone. It's better than nothing, and it's faster to implement than most people expect. A spreadsheet with columns for each bias criterion and a simple pass-fail column per question gets you from zero to a functional review system in about a week of setup time. The bottom line is that biased test questions are almost never the result of bad faith. They're the result of unexamined assumptions. The people writing these questions are good at their jobs. They've just never had to look at their work through someone else's eyes. The process I described forces that perspective shift systematically rather than hoping individual reviewers will catch what they might miss. That's the difference between wishing your exam is fair and verifying it.