Cluster Analysis Actually Works Like This
I've spent more years than I care to count pushing clustering algorithms into production environments where nobody asked for them. The first thing you need to understand is that cluster analysis is not a magic bullet. It's a way of grouping things that share characteristics, and the moment you treat it as a black box, it will quietly give you garbage results and look confident about it. Let me start with a specific problem I ran into last year that most tutorials won't tell you about. We were segmenting customer data using K-means on roughly 40 features. The algorithm returned six clusters. They looked clean. The within-cluster sum of squares was reasonable. We presented the findings to the marketing team and they immediately flagged one cluster as impossible — it contained roughly 12% of customers who had zero purchase history but appeared in a cluster defined by high average order value and frequent purchases. What happened is the feature engineering step had included recency scores, and a large group of dormant customers all scored near zero across dozens of behavioral features. K-means lumped them together because their distance from each other was smaller than their distance from active customers. They weren't a real segment. They were the empty space in the feature vector. The fix was brutal but simple. We dropped the low-variance features entirely, ran PCA to compress the remaining space down to 8 principal components, then re-ran K-means. The dormant artifact cluster disappeared because the variance structure changed completely. You can't rely on your raw feature set blindly. Most people skip that step and wonder why their clusters make no sense.
Examples Of Cluster Analysis You'll Actually Encounter
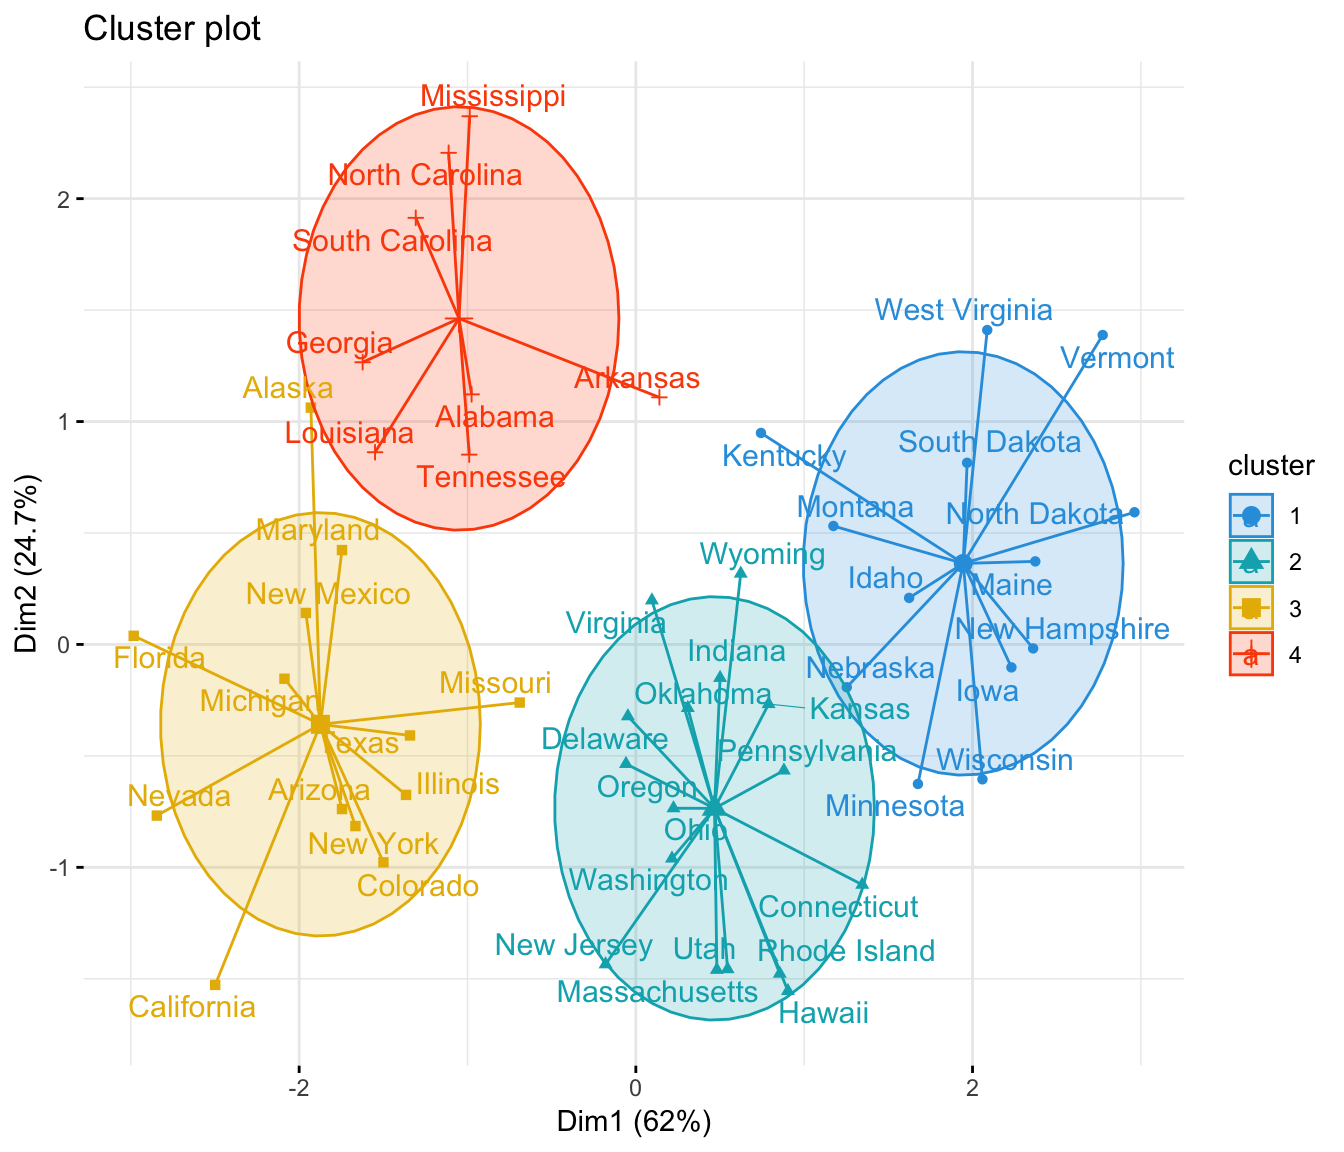
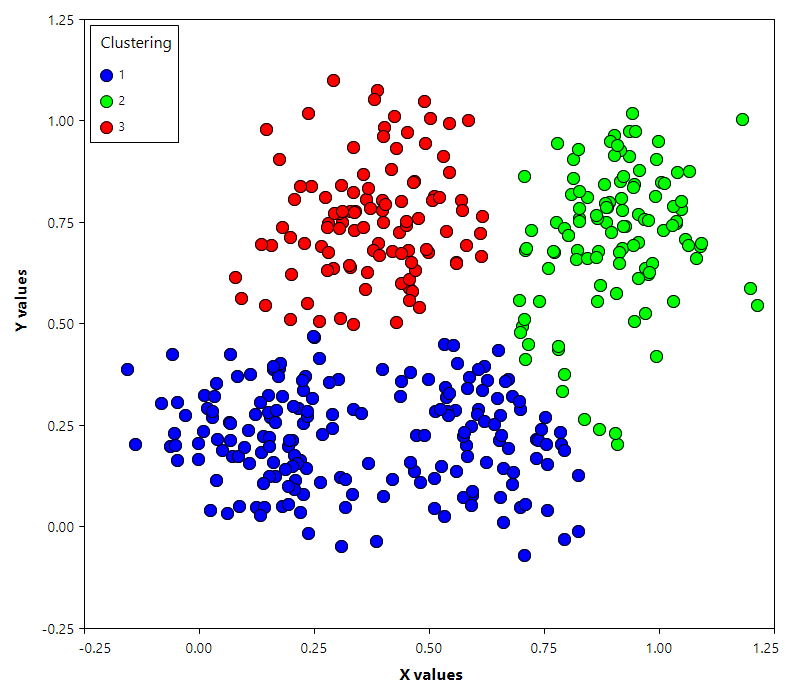
Let's move through some real examples. The most common one is customer segmentation. You pull transaction data, normalize the features, pick a distance metric, and run whatever clustering algorithm fits your constraints. K-means is the default because it's fast and most people have already seen it in a tutorial. It partitions your data into k clusters by minimizing the variance within each group. The catch is that you have to specify k beforehand, and picking the wrong k means either splitting natural groups apart or merging distinct populations together. For image segmentation, you're typically clustering pixel values. Each pixel becomes a point in color space, and algorithms like K-means or Gaussian Mixture Models group similar colors together. This is how basic object detection works in computer vision pipelines before you get into deep learning. The limitation here is that spatial context gets ignored. Two pixels might have the same color but belong to completely different objects because they're far apart in the image. A better approach for that is Mean Shift or spectral clustering, which incorporate spatial proximity into the grouping logic. Gene expression clustering is another area where this comes up constantly. Researchers use hierarchical clustering with a dendrogram to see how different genes group based on expression patterns across conditions. It's slow for large datasets but gives you a visual structure that flat clustering methods can't provide. The problem is that hierarchical clustering scales poorly. Once you hit around 50,000 samples, it starts taking minutes instead of seconds, and the memory usage becomes a real constraint.
Document clustering follows a similar pattern to image work but with text representations instead of pixels. You convert documents to TF-IDF vectors or embeddings, then apply clustering to find topics without labeled training data. This is unsupervised topic modeling territory. The downside is that document vectors are extremely sparse and high-dimensional. K-means struggles in that space because the notion of distance breaks down. Every point ends up roughly equidistant from every other point. This is the curse of dimensionality and it's the reason most people reach for DBSCAN or HDBSCAN for text data instead. HDBSCAN is probably the most underrated tool in this space. It doesn't require you to specify the number of clusters. It identifies core points within a density threshold and merges clusters based on hierarchy. It handles noise natively. Points that don't belong to any dense region just get labeled as noise instead of being force-assigned into the wrong group. I switched my entire pipeline to HDBSCAN after spending three weeks debugging why K-means kept splitting a single natural group into two clusters depending on the random seed.
Get the Full Details

How to Actually Do This Without Wasting Three Days
Start by cleaning your data. I know that sounds obvious but most people don't do it properly. Handle missing values. Normalize or standardize your features depending on whether your variables share the same scale. If you're working with mixed data types, you'll need Gower distance or some kind of conversion step. Don't skip that. Pick your algorithm based on what you know about your data, not what's trending. K-means for well-separated, roughly spherical clusters with a known number of groups. Hierarchical when you want a dendrogram and your dataset is small enough. DBSCAN or HDBSCAN when your data has noise, irregular shapes, and you don't know how many clusters exist. Gaussian Mixture Models when you believe the underlying distribution is actually multimodal and you want probabilistic cluster membership instead of hard assignments. Choosing k is where most people fall apart. The elbow method is a starting point at best. You plot the within-cluster sum of squares against different values of k and look for the bend. The bend is almost always subjective. Someone looking at the same graph can pick two different values. Silhouette analysis is more rigorous. It measures how similar each point is to its own cluster compared to the nearest alternative cluster. Values range from -1 to 1. Higher is better. But even silhouette scores can be misleading when clusters have very different densities or sizes.
I combine three approaches before committing to a final k. Elbow method for the rough range, silhouette scores for the quantitative comparison, and domain validation where I actually inspect the resulting clusters against what I know about the data. If the clusters don't map to anything recognizable in the business context, the math doesn't matter. You have the wrong k or the wrong features, possibly both. Validation is the step everyone skips because it's tedious. Once you have your clusters, you need to check them. Look at the distribution of your original features within each cluster. Do they actually differ? Are the differences meaningful? Run a downstream task like classification using cluster labels as features and see if the model performs better than random. If your clusters are indistinguishable from noise, you're done. Go back and rethink your preprocessing or try a different algorithm.
What Nobody Tells You About Implementation
K-means initialization matters more than you think. The default behavior uses k-means++ in most libraries now, which is better than random initialization but still not guaranteed to find the global optimum. Run the algorithm multiple times with different seeds and compare the results. If you get substantially different clusterings, your data might not have a clear cluster structure at all, or your features need work. Scaling is another silent killer. I once spent two days debugging a clustering result where one feature had values in the millions and another had values between zero and one. The high-magnitude feature dominated the distance calculations entirely. Standardization fixes this, but people forget to check whether their features are on comparable scales before running anything. For large datasets, Mini-Batch K-Means is worth using. It updates cluster centers using random subsets of the data rather than the full dataset each iteration. The trade-off is slightly less accurate centers, but the speed difference is usually dramatic. I've seen it cut runtime from several hours down to under thirty minutes on datasets with millions of rows.
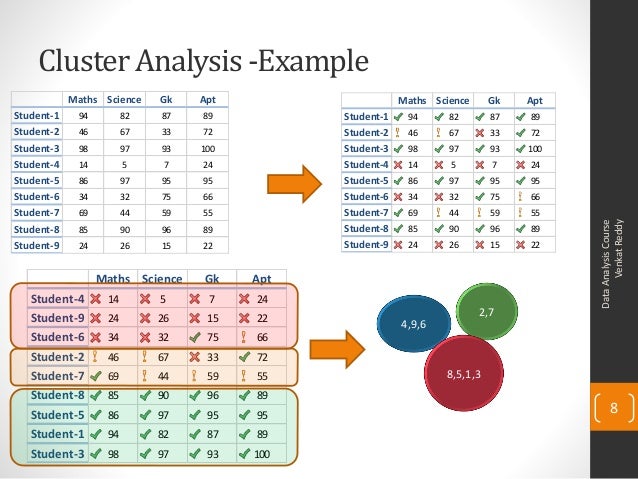
There's no single best algorithm. There's no perfect number of clusters. There's only the cluster structure your data happens to contain and how well your method can recover it. The people who get good at this are the ones who treat every result as a hypothesis to test, not a conclusion to present. Your clusters are wrong until you prove them right, and proving them right usually means doing more work than you expected.