How Variable Relationships Actually Work In Practice
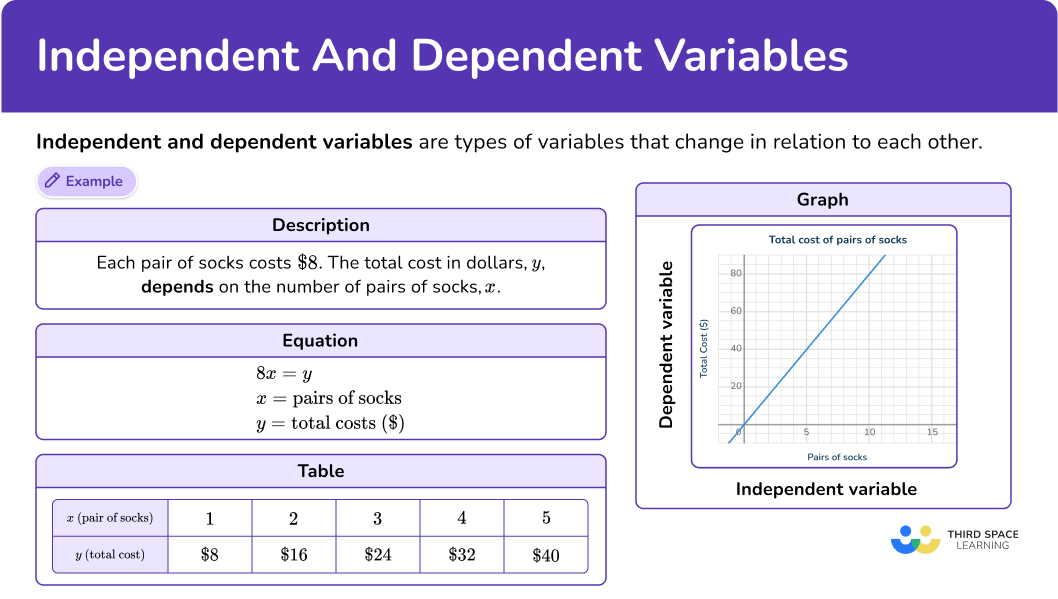
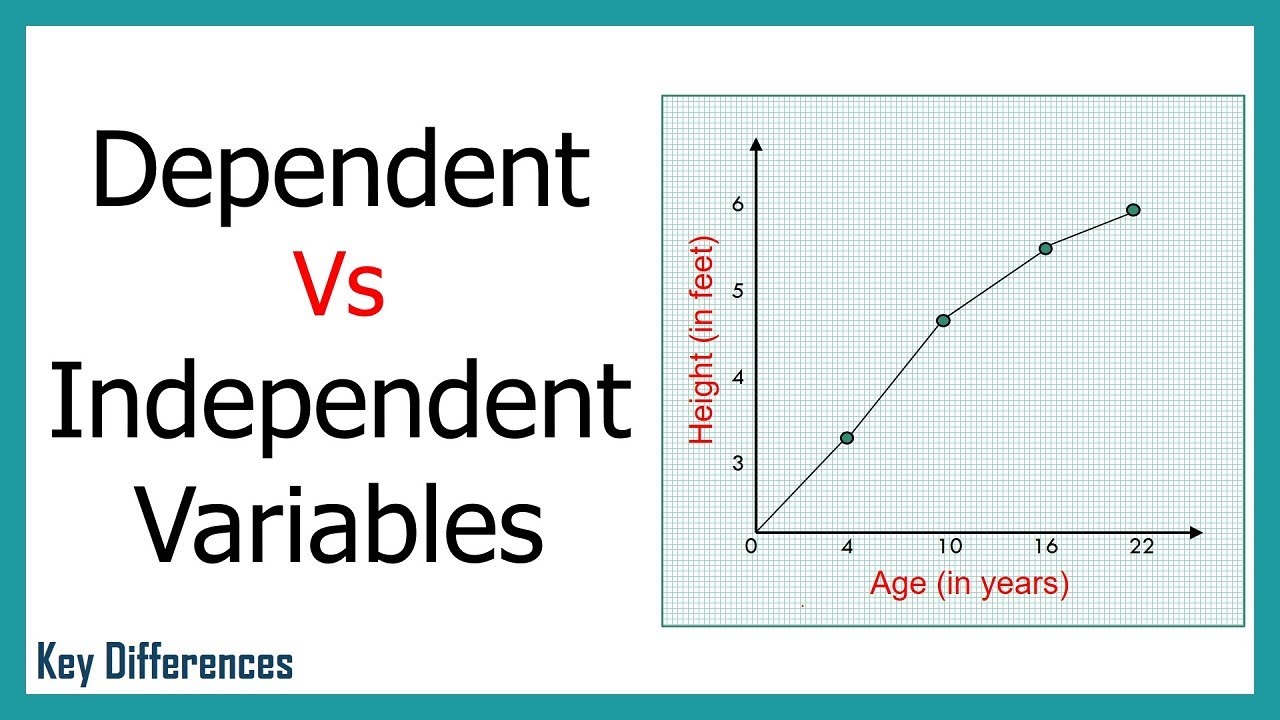
When you are building any kind of equation or regression model, the first thing you need to sort out is what drives what. The independent variable is the input you control or observe changing on its own. The dependent variable is the output that responds to that change. That sounds obvious until you actually try to map it onto a messy real-world problem, and that is where most people fumble.
I have seen students treat every number in a word problem as potentially dependent, which makes setting up even basic algebraic equations feel like guessing. The trick is not memorizing definitions. It is asking one question: which value changes because of the other? If changing x causes y to shift, x is independent and y is dependent. That simple causal chain is the foundation of everything else in math and science.
Examples Of Independent And Dependent Variables In Math
Example 1 — Linear function: y = 3x + 7. Here x is independent because you plug in whatever value you want. y is dependent because its result depends entirely on the x you chose. Example 2 — Distance over time: d = rt. If you are tracking how far a car travels, time is your independent variable. Distance is your dependent variable. Drive it longer, distance goes up. Change the rate instead, and the model shifts. Example 3 — Cost calculation: C = 5n + 20. Buying notebooks at $5 each with a $20 delivery fee. The number of notebooks (n) is independent. The total cost (C) depends on how many you order.
Example 4 — Projectile motion: h(t) = -4.9t² + 20t + 2. Time is independent. Height is dependent. This gets interesting fast because time moves forward whether you want it to or not, and height responds to it in a predictable curve. Example 5 — Compound interest: A = P(1 + r)^t. The time period t is independent. The accumulated amount A is dependent. But notice something most textbooks skip: if you solve for t instead using logarithms, t becomes the dependent variable and A becomes independent. The labels shift depending on what you are trying to find.
How To Identify Variables Without Getting Confused
The most common mistake I see people make is assuming the variable written first in an equation is always independent. That is not reliable. In a physics lab, you might measure temperature as time passes, but your data table could list temperature in the first column. Column order does not determine dependency. Causation does.
Here is a method that actually works. Write down the scenario in plain English first. Then circle the factor you can freely choose or that naturally progresses. That is your independent variable. Everything that reacts to it is dependent. When you translate that into symbols, put the independent variable into the function slot and let the dependent variable take the result.
I ran into a case a few years back where someone was modeling the relationship between study hours and test scores across different schools. At first glance, study hours looks independent. Test scores look dependent. But when I looked closer, schools with stricter attendance policies also required longer study sessions, and those same schools had better resources overall. So study hours and test scores were both responding to school policy as a hidden third variable. Neither was cleanly driving the other. I ended up adding school type as a control variable in a multiple regression model instead of treating it as a simple bivariate relationship. That changed the entire interpretation of the results.
Advanced Cases Where The Labels Break Down
Some problems are genuinely ambiguous and that is worth acknowledging. In systems with feedback loops, like a thermostat controlling room temperature, temperature affects heater output and heater output affects temperature simultaneously. You cannot cleanly separate which is independent and which is dependent without freezing the system into a static snapshot. Control theory handles this with state-space models, but for standard algebra and statistics classes, you usually pick one direction based on how the experiment is designed.
Another edge case is when both variables are observed rather than manipulated. In observational studies, correlation does not imply causation. Income and education level are classic examples. Which one is driving which? Neither, really. They influence each other and both respond to socioeconomic background. When you encounter these situations, the honest answer is often that the variable framework itself is insufficient and you need a structural equation model or a randomized experiment to untangle it.
Common Pitfalls To Avoid
Do not confuse the dependent variable with the output of a calculation just because it appears on the left side of an equals sign. In y = mx + b, y is dependent. But if you rearrange to solve for x, x becomes the dependent variable of that new operation even though it was independent in the original setup. The role is defined by the experimental or functional intent, not by notation position.
Do not assume time is always independent. In a study where you measure heart rate at specific ages, age is independent. But in a study measuring how long it takes someone to run a fixed distance, the time is the outcome and the distance is fixed, so the relationship flips depending on what you are measuring against.
Do not ignore units. Writing y = 2x looks clean, but if x is in meters and y is in seconds, the slope carries the unit 2 seconds per meter, which tells you something specific about the rate of change. Dropping units during variable identification is a fast way to produce nonsensical models.
When The Standard Approach Fails Completely
Implicit relationships do not play nice with the independent-dependent framework. Consider x² + y² = 25. This is a circle. For a single x value, there can be two y values. You can solve for y as a function of x, but only by splitting it into y = (25 - x²) and y = -(25 - x²). The original equation treats both variables symmetrically, and neither is truly dependent. If you force one to be dependent, you lose half the solution set. In those cases, parametric forms or implicit differentiation are more appropriate than labeling one variable as dependent.
Differential equations are another area where the standard labeling gets murky. In dy/dx = x + y, is y dependent on x? Formally yes, but the equation describes how the rate of change of y relates to both variables simultaneously. The dependency is baked into the derivative itself, and solving it requires integrating factors or numerical methods, not just plugging in x values.
Practical Tips For Building Your Own Examples
Start with a physical or measurable situation. Pick something you can change deliberately, like adjusting the amount of fertilizer on a plant, and something you can measure as a result, like plant height. That gives you a clean independent-dependent pair. Then write the relationship in words before you write it in symbols. The words keep you honest about causality.
If you are doing this for a class assignment, check the context clues. Phrases like "depends on," "is determined by," "results from," and "because of" all point toward dependency. Words like "given," "for each," and "as a function of" signal the independent side. These linguistic markers are not foolproof, but they help you avoid the most obvious mislabeling errors.
One thing I wish I had learned earlier is that the independent-dependent distinction matters most when you are designing an experiment or choosing a statistical model. In pure math, functions can be written either way through inversion, so the distinction is mostly pedagogical. In applied math and statistics, getting it wrong means your model structure is backwards, your residuals are misinterpreted, and your conclusions are unreliable. Take the time to get it right before you run any analysis.