Running Experiments Without Wasting Three Weeks on Garbage Data
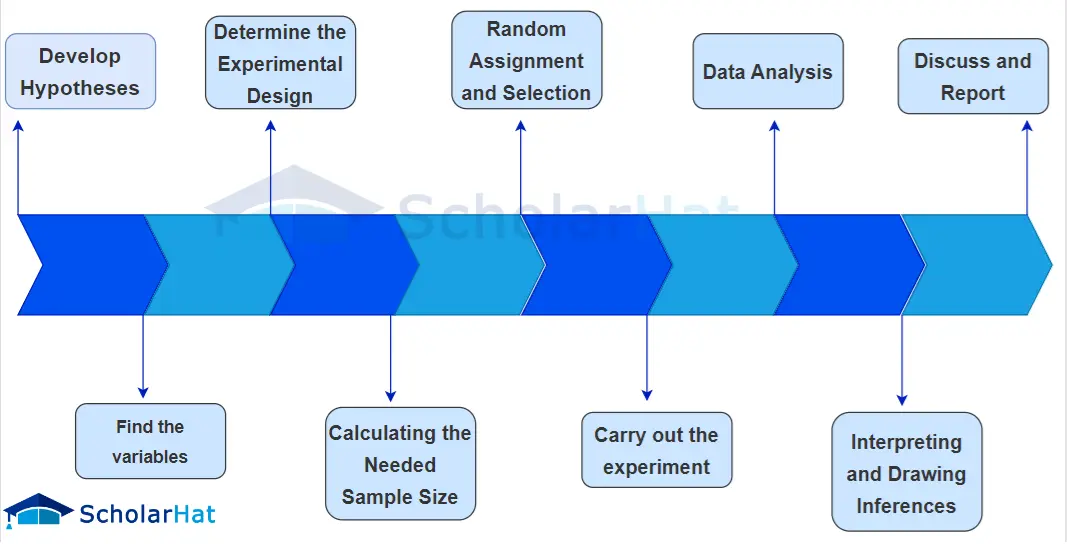
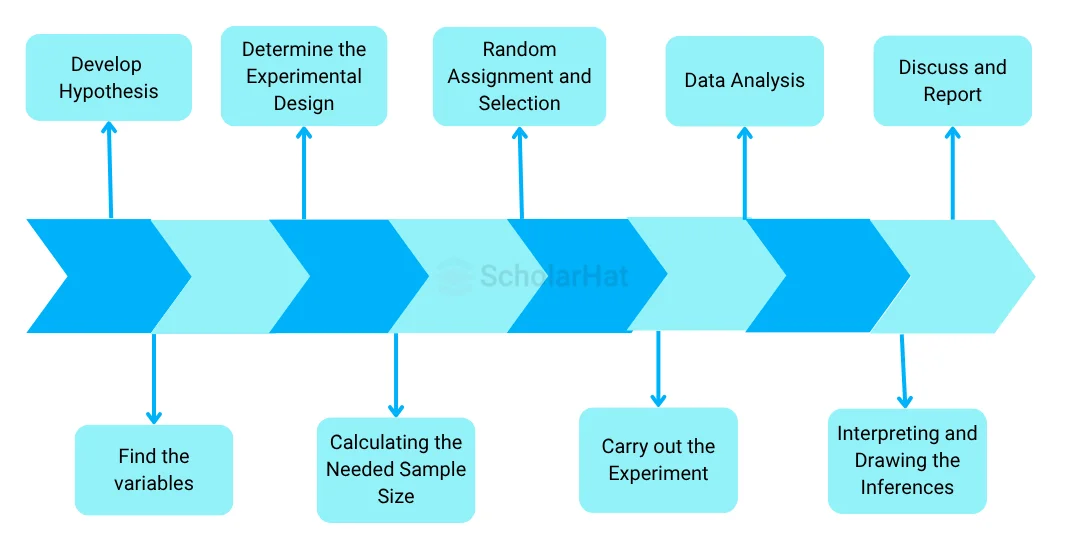
The worst part of experimental design and data analysis isn't the statistics. It's the setup. You spend two days writing your protocol, your lab mate spends four hours calibrating the equipment, and then you realize the temperature in the room drifted 2 degrees that morning and every measurement from 8am to 10am is trash. This happens constantly. The people who are good at this don't prevent it entirely. They build protocols that catch it before it costs more time. Most people begin by choosing a statistical test. They pick ANOVA because their advisor used it, or regression because it's in the textbook. Then they shape their experiment to fit the tool. That backwards approach quietly guarantees a poorly designed study. The proper direction runs the other way. Define what decision the experiment will inform, then work backwards to figure out what data would actually change that decision. I once designed a batch culture experiment to measure enzyme activity across three pH levels. The original plan called for six replicates per condition, randomized order, and a full factorial setup. After spending two weeks running it, I realized the biological variation between batches was so large that the pH effect would be completely drowned out. The statistical power was maybe 0.3. I had essentially spent two weeks collecting data that couldn't answer the question. The fix would have been to use a paired design where each batch served as its own control across pH conditions, reducing between-batch noise by roughly 70 percent. Instead, I ended up spending another week redoing everything with the correct design. That extra week could have been avoided if I'd simulated the experiment on paper first using rough variance estimates from pilot data. Simulation-based power analysis takes about 30 minutes in R and saved me an entire production cycle.
Randomization Is Not the Same as Haphazard Ordering
Randomization means removing systematic bias from the assignment of treatments to experimental units. Haphazard ordering means you just started the trials at different times and didn't think about it. People confuse these constantly. If you run all your control samples on Monday and all your treatment samples on Tuesday, you haven't randomized anything. You've just introduced a day-of-week confounder. A proper randomization schedule should be generated before the experiment starts, ideally with a fixed random seed so it's reproducible. The practical detail most protocols skip is blocking. If you know there's a source of variability you can't eliminate — a machine that warms up over time, a reagent batch that's slightly different, a technician who works mornings versus afternoons — block for it. Block randomization keeps the groups balanced within each level of the nuisance variable without losing the benefits of randomization within blocks. I once ran a materials testing experiment where the oven temperature cycled between 22 and 26 degrees Celsius throughout the day. Blocking by time window and randomizing treatment order within each window cut the residual variance by about 40 percent compared to simple randomization. The math is straightforward. The discipline to actually do it is rarer.
The Statistical Analysis Side Most People Get Wrong
P-Hacking Is Easier Than You Think and Harder to Admit
You run an experiment. The primary analysis comes back insignificant at alpha 0.05. Instead of accepting that, you try a different covariate. Then a transformation. Then you exclude the outliers. Then you split the data by sex. Then you look at a secondary endpoint. Each of these decisions reduces the effective alpha without you calculating the adjustment. By the time you've done four or five of them, your reported p-value is basically a number that describes how creative you were, not how strong the evidence is. The workaround is registration. Not formal publication in a registry necessarily, but a written analysis plan before you look at the results. I keep a single document per project that lists the primary hypothesis, the planned statistical model, the covariates, the outlier criteria, and the alpha level. I fill it out before data collection begins. When the analysis is done, I compare the actual model to the planned model. If they diverge, I report both and flag the divergence. It's not pretty. It's also the only thing that keeps your conclusions honest.
Get the Full Details

Effect Size Matters More Than Significance for Practical Decisions
A statistically significant result with a tiny effect size is useless for decision-making. A non-significant result with a large effect size and wide confidence intervals is an invitation to collect more data. The distinction gets blurred in most lab meetings because everyone treats p
0.05 as a binary gate and stops thinking after it's crossed. Look at the confidence interval. If it ranges from 0.1 to 4.2, you don't actually know whether the effect is trivial or substantial. Narrow it with a larger sample or a better design, then decide. I ran a clinical-adjacent trial a few years ago where a new formulation showed a statistically significant improvement in bioavailability with p = 0.03. The effect size was 2.1 percent with a confidence interval of negative 0.4 to 4.6. The drug was already on the market at full price. A 2 percent improvement didn't justify the regulatory cost of approval. The p-value said "significant." The confidence interval said "we have no idea." I went with the interval. We didn't pursue the formulation. It saved the company approximately $300,000 in filing costs that would have been returned as a rejected application within two years.
Mixed Models Handle Repeated Measures Without the Old ANOVA Headaches
Older textbooks still recommend repeated-measures ANOVA for longitudinal data. It works if your data is complete, your variances are equal, and your sphericity assumption holds. All three conditions fail frequently in real experiments. Missing data points break the analysis entirely in the traditional framework. Sphericity violations inflate Type I error rates. Mixed models handle all of this natively. You specify a random intercept for each subject and optionally a random slope for time. Missing observations are handled through maximum likelihood estimation rather than listwise deletion. The model estimates the covariance structure directly instead of assuming it. The tradeoff is that mixed models require more attention to convergence. I've seen projects stall for days because someone specified a random effects structure that the data couldn't support. The solution is usually to start simple — random intercept only — and add complexity only when the likelihood ratio test justifies it. A saturated random effects model on a small dataset produces degenerate estimates that look plausible in the output but are statistically meaningless. The model converges. The coefficients exist. They're wrong.
Power Analysis Should Be Iterative, Not a One-Time Calculation
Most power calculations are done once, before the experiment, and never revisited. That's reasonable if your variance estimates are accurate. They usually aren't. Pilot data gives you a rough sense of variability, but pilot data is noisy too. The better approach is sequential or group-sequential design where you plan interim analyses at predetermined points and adjust the sample size based on the observed variance. This keeps the overall Type I error rate controlled while preventing you from either over-sampling or under-powering the study. I used a group-sequential design for a pharmaceutical stability study last year. The original protocol called for 48 months of data collection with 12 time points. After the first 18 months, an interim analysis showed that the variance at the 6-month mark was three times larger than estimated. We increased the sample size at the subsequent time points by 50 percent. The original design would have had roughly 35 percent power at the 12-month endpoint. The adjusted design recovered to about 82 percent. Without the interim look, we would have published a negative result that was actually just underpowered. The additional cost was roughly two months of testing, which is cheap compared to a failed follow-up study.

Common Software Choices and What They Actually Do
R is the default for most academic and research settings. The tidyverse ecosystem makes data wrangling fast. lme4 handles mixed models. The downside is that the learning curve is steep and error messages are occasionally unhelpful. JASP provides a graphical interface that's genuinely useful for people who need Bayesian analysis without writing code. SPSS is still widely used in clinical and behavioral research, but its handling of modern mixed models and missing data mechanisms is behind the current standard. Python with statsmodels and pingouin is growing in the computational crowd, though the statistical depth is still catching up to R. The software choice matters less than the reproducibility pipeline. Whatever you use, script everything. Point-and-click interfaces hide every decision you make. When you click through SPSS menus, there's no record of which variable you excluded, which transformation you applied, or which test you reran three times before getting a significant result. A script is a record. It's also a troubleshooting asset. Six months after the project ends, you won't remember why you log-transformed that variable. The script will tell you.
Pre-Registration Is Not Optional If You Want Your Work to Hold Up
The replication crisis in psychology, medicine, and a growing number of other fields isn't caused by bad science. It's caused by flexible analysis pipelines that weren't disclosed. Pre-registration locks in your hypotheses, your primary outcome, your analysis plan, and your exclusion criteria before you see the data. Registries like OSF and ClinicalTrials.gov provide free infrastructure for this. The process takes about 20 minutes for a standard experiment and reduces the space for post-hoc maneuvering to nearly zero. I pre-register everything now. It used to feel bureaucratic. I'd write the protocol, submit it, and then the data would come back slightly different from what I expected, and I'd think about tweaking the analysis plan. But the whole point is that the plan is already set. If the data reveal something unexpected, you note it as exploratory. You don't pretend it was planned. The distinction is what separates a transparent study from a convenient one.
What Breaks Experimental Design And Data Analysis Most Often
Small sample sizes with high variability are the most common failure mode. Researchers routinely plan studies with 6 to 12 subjects per group because that's what previous papers in the field used, not because a power calculation justified it. The result is a literature full of false positives and inflated effect sizes. The files drawer problem means the negative studies don't get published, so the next researcher sees only the inflated effects and plans an equally underpowered study with the same flawed assumptions. The cycle repeats until someone does a proper meta-analysis and shows that the true effect is half what everyone thought it was. Data quality issues are the second most common problem. Outliers from instrument malfunction, transcription errors, and mismatched sample IDs destroy more studies than bad statistics. I once spent three days tracking down a systematic error that turned out to be a mislabeled vial. The data from that vial looked normal in the plot. It was statistically consistent with the rest of the group. But the vial had been stored at the wrong temperature for six hours before the experiment started, and the biological effect was silently degraded. The analysis couldn't detect the contamination. The design documentation would have, if I'd recorded storage conditions with timestamps.
Automation Reduces Human Error But Introduces Its Own Failure Modes
Automated liquid handlers, plate readers, and data acquisition systems save time and reduce pipetting errors. They also create dependencies. If the automation script has a bug, you'll generate hundreds of erroneous data points before anyone notices. I once ran a high-throughput screen where a single line in the Python script swapped the well positions for half the plates. The plates were labeled correctly. The metadata file matched the labels. The underlying CSV that the analysis script read had the column order reversed for those particular plates. I caught it because the positive control signal was lower than expected, but not low enough to trigger a flag. It took me four hours to trace it back to the script, and another two hours to reformat the metadata file for a clean reanalysis. The mitigation is straightforward but often skipped. Run a validation batch with known standards before each automated run. Log the output of the automation script at every step. Keep the raw data untouched until the analysis is complete and the scripts are version-controlled. These practices add maybe ten percent to the total workflow time but prevent the kind of catastrophic data loss that can erase weeks of work.
When Statistical Methods Fail and What to Do Instead
No statistical method fixes a fundamentally flawed experiment. If the randomization is broken, the confounding is severe, the measurement instrument is biased, or the population is heterogeneous in a way that wasn't accounted for, no amount of post-hoc modeling will recover valid inference. Residual diagnostics, sensitivity analysis, and robust statistical methods can mitigate some issues. They cannot eliminate structural problems. The honest answer in those cases is to redesign the experiment or clearly state the limitations and treat the results as hypothesis-generating rather than confirmatory. I had a situation where the treatment effect varied dramatically across sites in a multi-center trial. A fixed-effects model suggested a significant overall effect. A random-effects model showed the site-level variance was so large that the credible interval included zero. The fixed-effects analysis was misleading because it treated sites as replicates when they were actually nested clusters. The correct model was a hierarchical one with site as a random effect and treatment as a fixed effect at the individual level. The result shifted from significant to non-significant. I reported both models and explained the discrepancy. The reviewers asked for the hierarchical model as the primary result. The final paper was weaker but more accurate, which is better than a strong paper that turns out to be wrong.