Getting Your Experiments to Actually Work
Most biology grad students hit a wall somewhere around month six when their first major experiment produces garbage data. They've been following protocols from papers that were published five years ago, using cell lines that have drifted genetically, and wondering why nothing replicates. The problem rarely has anything to do with the technique itself. It's almost always a design flaw that wasn't caught before pipettes touched anything. I spent three years troubleshooting exactly this kind of failure across multiple labs, mostly working with mammalian cell culture and mouse models. You learn pretty quickly that Experimental Design In Biology isn't about fancy statistics or choosing the right software. It's about constraining variables so tightly that when something goes wrong, you actually know which one went wrong. Most people skip that part because it's tedious, and then they spend six months paying for it.
What Experimental Design In Biology Actually Means
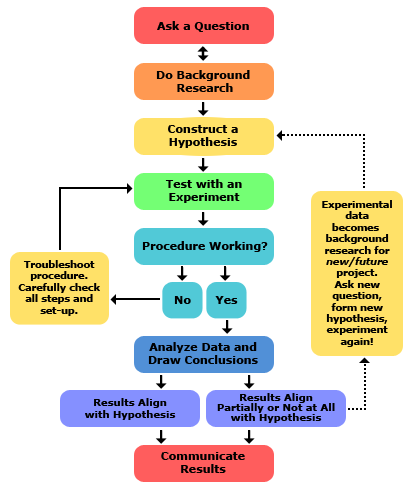
At its core, experimental design is the process of structuring a study so that you can draw a valid conclusion from the data you collect. That sounds simple until you realize that every decision you make before you touch a single sample locks in what you'll be able to conclude afterward. If you don't randomize properly, your conclusions are vulnerable to batch effects. If your sample size is underpowered, you'll waste time chasing false positives. These aren't edge cases. They happen constantly in published work. Let me give you a concrete example from my own work. I was running a CRISPR knockout screen in HEK293 cells three years ago, and the results were clean but biologically implausible. Every gene I thought would affect proliferation showed no phenotype. I had followed the protocol exactly. The breakthrough came when I realized I'd designed the experiment as a single large batch — transducing all plates on the same day, using the same media prep, the same reagent lot. When the screen came back negative, I had no way to tell whether the result was real or whether something about that single batch was systematically suppressing the phenotype. I redesigned the entire screen with a block randomized layout across four separate days with independent media batches. The second run produced clear, reproducible hits within two weeks. The first run had been a ghost experiment — the data looked fine, but it told you nothing.
The Practical Framework
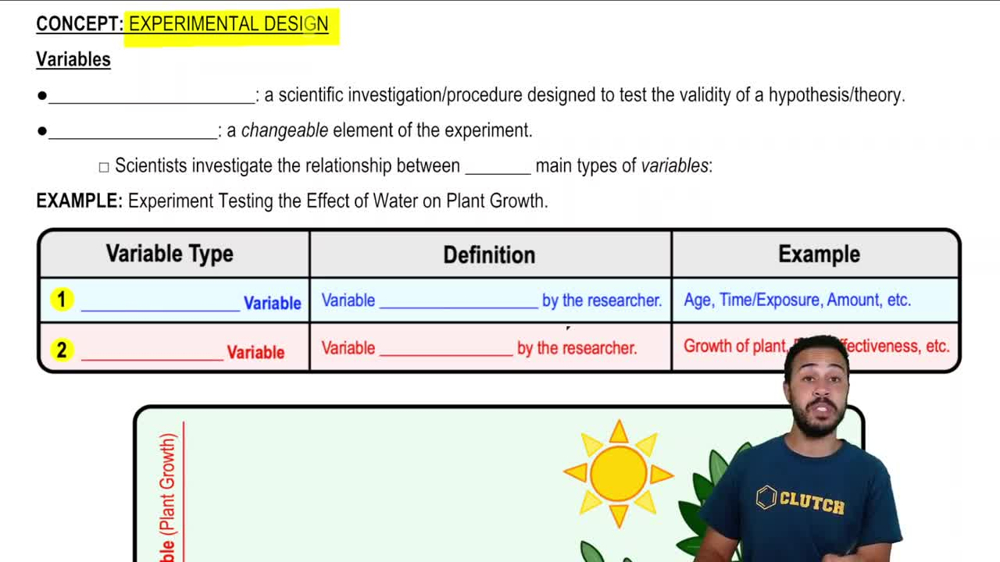
Start by writing down your hypothesis in a single sentence that specifies the exact comparison you're making. Not "gene X affects cell growth." Something like "Knockout of gene X in MCF7 cells reduces proliferation rate by at least 30% compared to non-targeting control after 72 hours, measured by resazurin assay." That level of specificity forces you to commit to things most people avoid committing to until it's too late. What organism, what cell line, what timepoint, what magnitude of effect you expect, and how you'll measure it. Next, identify your experimental unit. This is the thing that gets randomly assigned to a treatment. It's not the well in the plate. It's the culture flask. It's not the mouse tail blood sample. It's the mouse. When you treat each well as an independent data point but all wells in a plate share the same condition, you've committed pseudoreplication and your p-values mean absolutely nothing. I see this error in maybe half of the papers I review for journals, and it's usually a formatting issue rather than intentional manipulation. People just don't think about it. Define your control conditions before you write a single primer. Negative controls, positive controls, vehicle controls, and if you're doing anything with antibodies, isotype controls. A positive control tells you your assay actually works. Without it, a negative result is indistinguishable from a failed experiment. I once ran a Western blot that showed complete loss of a protein after treatment. I had no positive control lane. I had to go back and redo the entire gel because I couldn't prove the antibody was even functioning in that context. One extra lane would have saved me two days.
Get the Full Details
Power Analysis and Sample Size
This is where most people cut corners because power calculations feel like bureaucratic overhead. They aren't. Running an underpowered experiment is the single most common way to produce irreproducible biology. A typical RNA-seq experiment with n=3 per group has about 50-60% power to detect a 2-fold change with standard significance thresholds. That means roughly half the truly differentially expressed genes you'd expect to find won't show up as significant, and the ones that do cross the threshold will be inflated in their estimated effect sizes. This is the winner's curse, and it's why so many follow-up studies fail to replicate. For most cell-based assays, I aim for a minimum of n=6 biological replicates. That's six independent cultures prepared from separate passages, not six wells from the same flask. The difference matters enormously. Technical replicates — multiple reads from the same sample — tell you about measurement precision. Biological replicates tell you about biological variation. You need the latter to make any claim about what's happening in the system. Power calculations using G*Power or R's pwr package take about fifteen minutes and will tell you exactly how many replicates you need for the effect size you're targeting. Skip it and you're guessing, and biology doesn't care about your guesses.
Randomization and Blinding
Randomization eliminates systematic bias. If you always process your treatment group first and your control group second, any drift in reagent activity, instrument performance, or operator fatigue becomes confounded with your treatment effect. Generate your randomization scheme with a simple script or even Excel's RAND function before you begin. Write down the scheme. Don't decide on the fly. Blinding is harder to implement consistently but it's equally important. If you know which sample is which while you're measuring outcomes, your expectations subtly influence how you read results, how you threshold images, how you decide whether an outlier is "real." I started blinding my quantification work about two years ago after a colleague pointed out that my "obvious" treatment effects were disappearing when I had no idea which group I was looking at. Turns out I'd been interpreting ambiguous bands and borderline colony counts in a way that confirmed my expectations. It wasn't deliberate. It was just how human perception works.
A Note on Factorial Designs
Most biology students design one-factor-at-a-time experiments because that's what they were taught. Factorial designs — where you vary two or more factors simultaneously — are more efficient and often reveal interactions you'd completely miss otherwise. Testing drug A and drug B separately tells you what each does alone. Testing them together in a 2x2 factorial tells you whether they interact synergistically, additively, or antagonistically. The number of experimental groups grows slowly (four groups instead of three), but the information gain is substantial. The tradeoff is that analysis is slightly more complex, usually requiring two-way ANOVA rather than a simple t-test. Conflating correlation with mechanism. Knocking down a gene and seeing a phenotype doesn't mean the gene causes the phenotype through the pathway you hypothesize. The gene could have an entirely different primary function that indirectly produces the observed effect. I ran a clean RNAi screen that pointed to a kinase as essential for migration. Follow-up experiments showed the kinase wasn't involved in cytoskeletal regulation at all — it was maintaining mitochondrial function, and the migration defect was secondary to energy crisis. The initial experiment was technically valid. The inference was wrong because I never designed a control to distinguish direct from indirect effects. Ignoring batch structure in analysis. Even if you randomize properly during the experiment, if you analyze your data without accounting for batch effects, you're throwing away the protection randomization gave you. Batch effects are real and measurable. Include batch as a covariate in your statistical model, or use tools like ComBat for sequencing data. Don't just pool everything and run a standard test.
P-hacking through optional stopping. Running an experiment, seeing marginal results, deciding to add more replicates, running it again, and only reporting the combined data. This is not standard practice and it inflates your false positive rate substantially. Pre-register your analysis plan or at minimum decide on your stopping rules before you collect data. If you find yourself doing post-hoc power calculations to justify a sample size you already chose, stop and rethink the experiment.
Tools and Templates
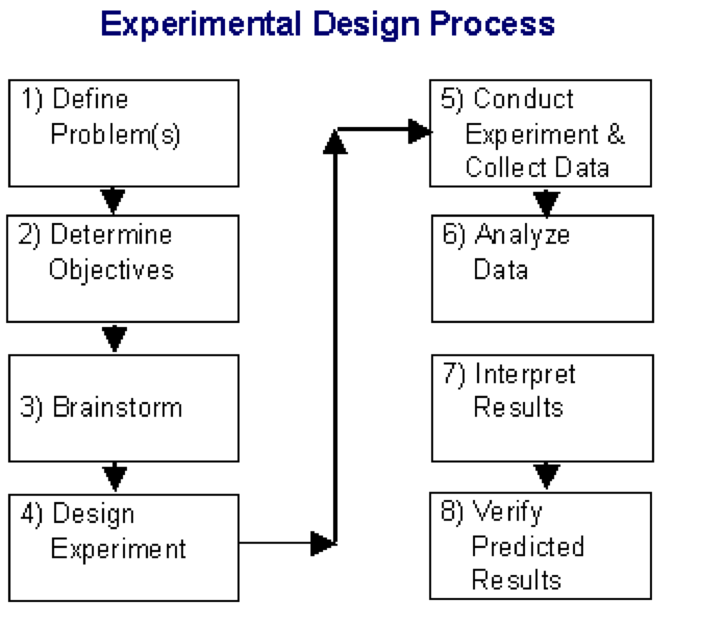
I keep a standard experimental design template that I fill out before every project. It covers hypothesis statement, experimental unit, randomization scheme, control conditions, sample size justification, primary outcome measure, secondary outcomes, statistical test planned, and criteria for excluding data points. Filling it out takes about twenty minutes. It has prevented more bad experiments than any method I've adopted. The template lives in a shared spreadsheet my lab uses, and I require everyone to have it signed off before we order reagents or schedule instrument time. For statistical analysis, R with the lme4 package handles mixed models well when you need to account for nested experimental units. Python's statsmodels works fine for simpler designs. GraphPad Prism is adequate for basic ANOVA and t-tests but doesn't handle more complex designs gracefully. For power analysis, G*Power is free and covers most common tests. For RNA-seq specifically, the EdgeR and DESeq2 packages have built-in power estimation functions that are more appropriate than generic tools.
When Experimental Design Can't Save You
No amount of careful design fixes a fundamentally flawed biological system. If your cell line is mycoplasma-contaminated, your knockouts are incomplete, or your antibody cross-reacts with an unrelated protein, your elegant randomization scheme won't produce meaningful data. I stopped assuming my cell lines were clean about four years ago after a contamination issue invalidated three months of work. Now I test every new batch and re-archive early passage vials before starting any long project. It adds about two days to setup but has saved me countless weeks of wasted effort. Similarly, validating every antibody with a knockout or knockdown control before committing to an experiment costs maybe an afternoon and eliminates a whole category of failure modes. Design matters more than execution in biology, but neither matters without verification of your tools and systems. Treat both with equal seriousness from day one.