Why Your Experimental Design Keeps Failing Before You Even Collect Data
I spent three semesters trying to teach undergraduate research methods using the Jones Bartlett Learning materials on experimental design, and honestly the biggest problem isn't the textbook. It's that students treat the diagrams like recipes instead of frameworks. The Campbell and Stanley framework that Jones & Bartlett Learning structures around in their research methods titles is solid, but it only works if you actually understand what threatens your internal validity before you recruit a single participant. The most common mistake I see is people starting with the analysis and working backward. They decide they want an independent t-test, then retrofit a design to justify it. This produces garbage. You should start with your hypothesis about causation and work forward to whatever design minimizes the plausible alternative explanations for your specific context.
Experimental Research Designs Jones Bartlett Learning
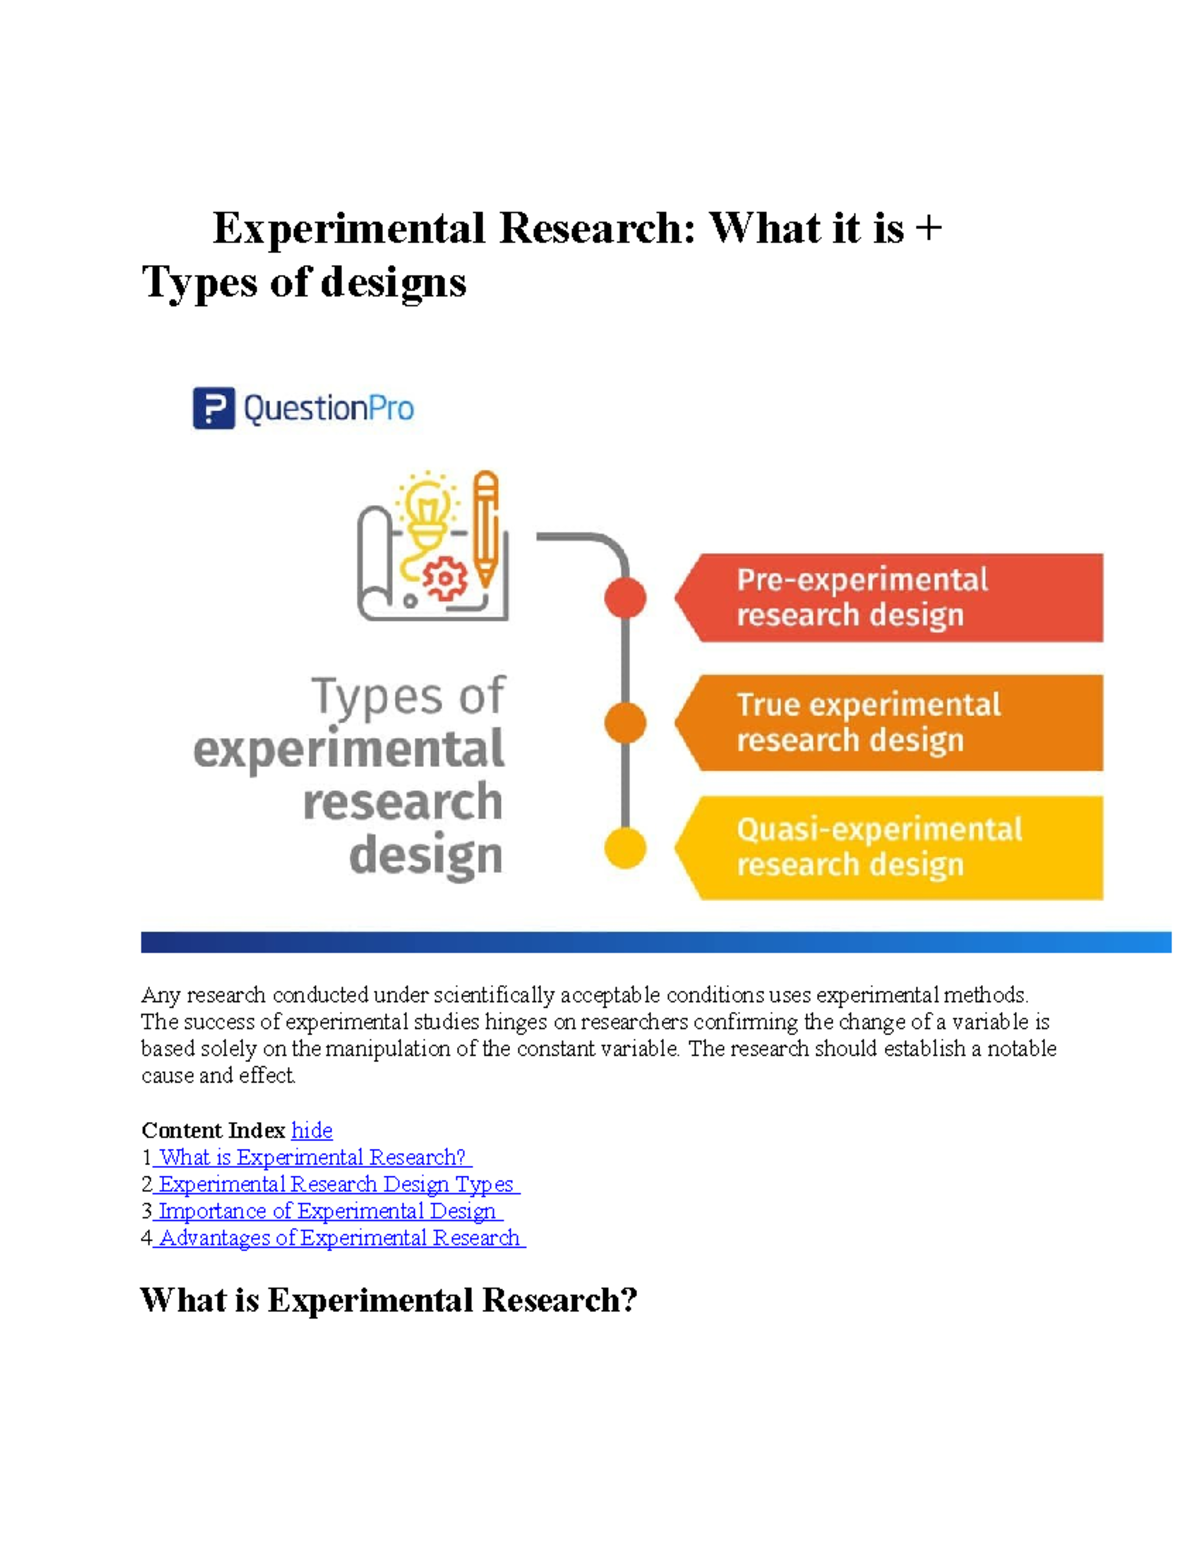
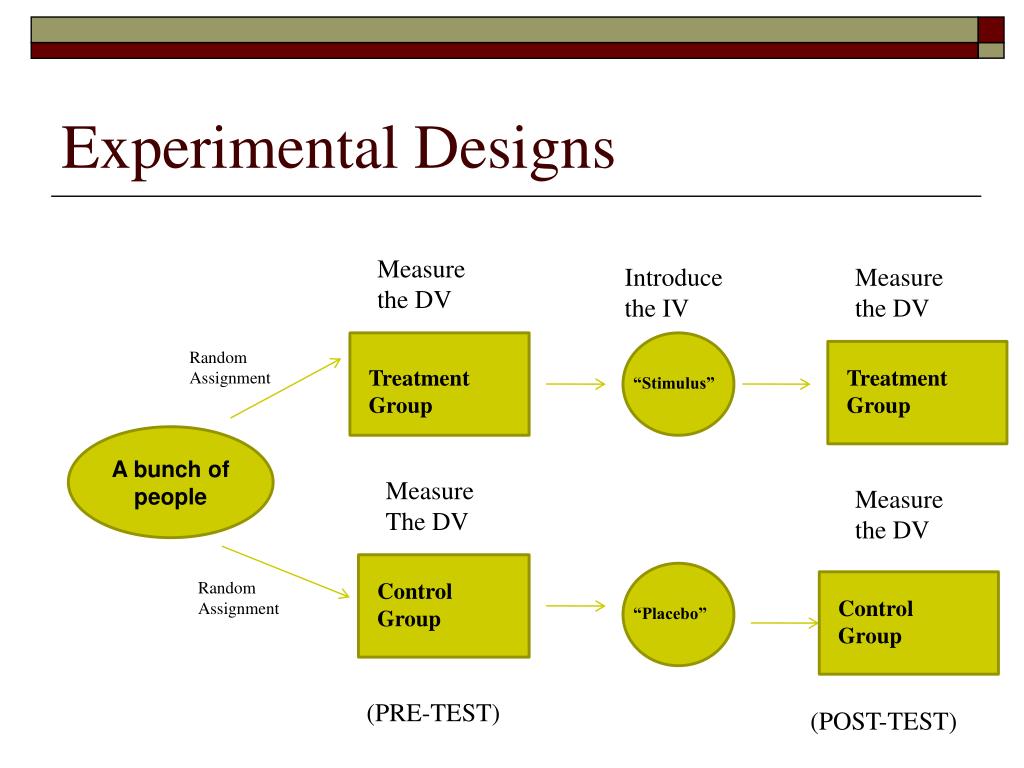
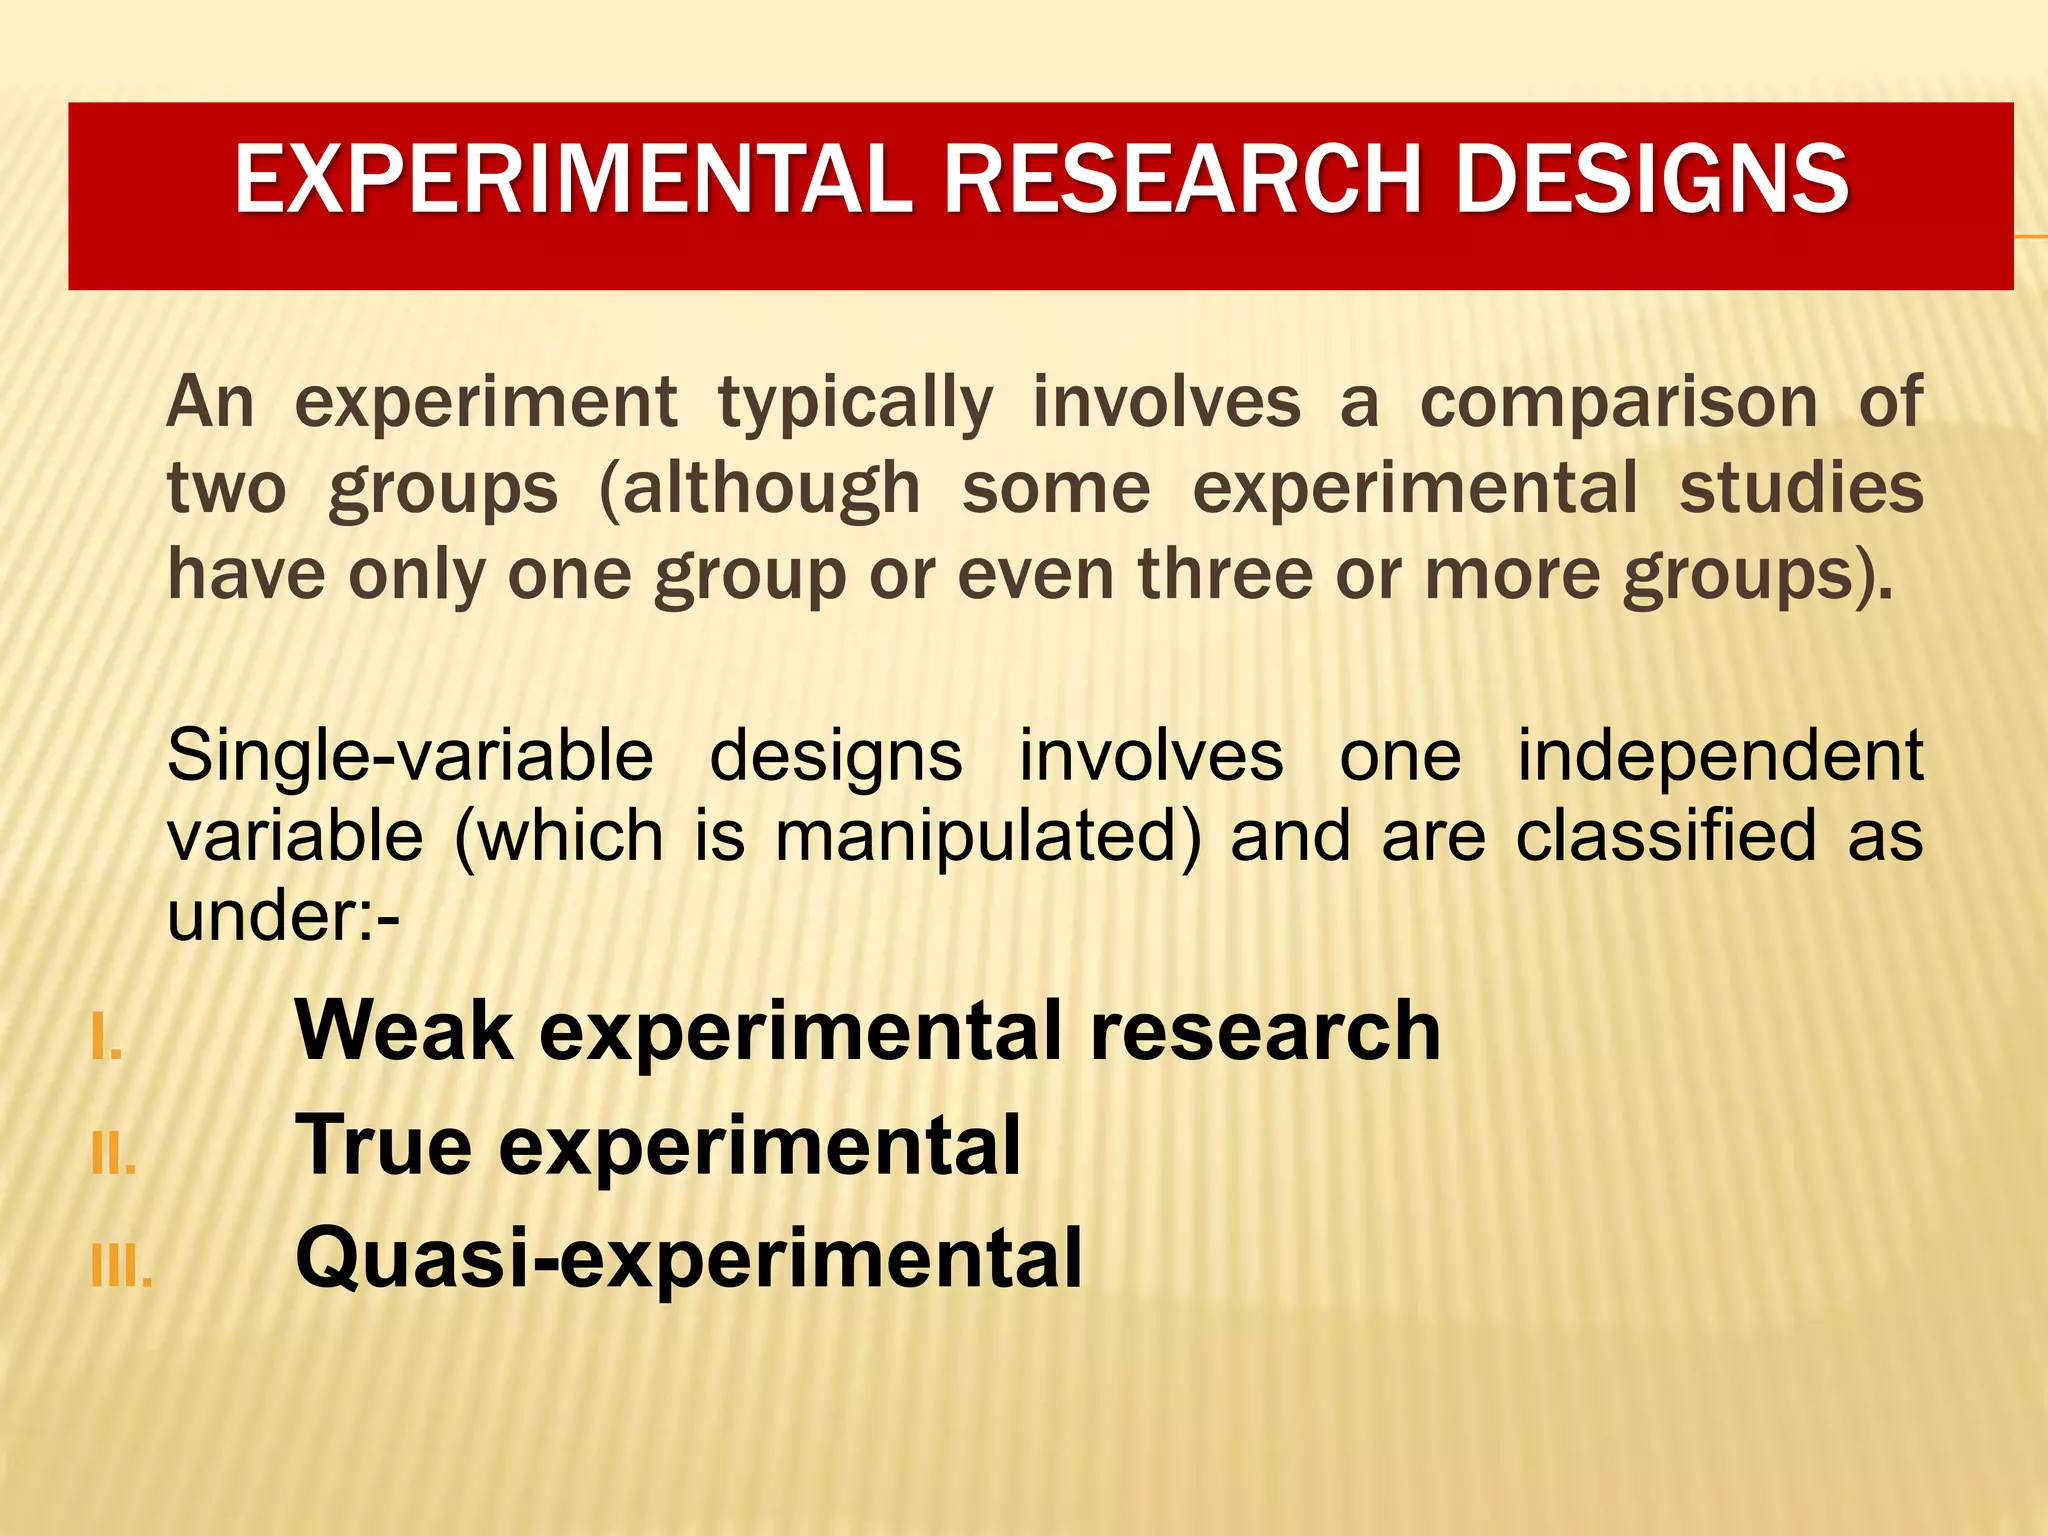
Here is how the core designs actually work when you stop treating them like abstract categories. Pre-experimental designs are the simplest but also the most dangerous because they look plausible to beginners. One-group posttest-only is the classic example: you have a treatment, you measure afterward, and you call it evidence. There is no control group, no random assignment, no baseline measurement. The only thing you can reasonably conclude is that something happened after the intervention, which is almost never useful. I once saw a graduate student publish a study claiming a training module improved employee performance using this design. The pre-existing differences between departments alone could explain the entire effect. Don't do this unless you are doing exploratory pilot work and you explicitly label it as such. Quasi-experimental designs are where real research lives. Random assignment is usually impossible outside of a lab because you cannot randomly assign people to demographics, existing programs, or organizational structures. The nonequivalent control group design is the workhorse here. You take two already-existing groups, expose one to the treatment, and compare outcomes. The critical threat is selection bias. The groups may differ systematically before the intervention even starts. The workaround is to measure the outcome before the treatment (a pretest) and use analysis of covariance or difference scores to adjust for baseline differences. This does not fully solve the problem, but it is the best you can do when randomization is off the table.
True experimental designs with random assignment remain the gold standard, and the reason is straightforward. Randomization distributes both known and unknown confounding variables across conditions roughly equally, at least in large enough samples. The simple posttest-only control group design requires only two groups and one measurement after the intervention. Surprisingly, you do not always need a pretest in a true experiment because randomization handles the equivalence concern. Adding a pretest when you already have random assignment can sometimes introduce testing effects that contaminate your results, though this is rare and depends heavily on your domain. The Solomon four-group design resolves the pretest threat problem entirely by crossing randomization with pretest presence. You get four groups: pretest-treatment, pretest-control, no-pretest-treatment, and no-pretest-control. This tells you whether the act of pretesting interacts with your treatment. It is rigorous but expensive in terms of participants. You need roughly double the sample size of a standard two-group design to run it properly. I recommend it only when you suspect pretesting is likely to sensitize participants in a way that changes how they respond to the treatment. For factorial work, completely randomized designs and randomized block designs are your main options. Factorial designs let you test multiple independent variables simultaneously and, crucially, their interaction effects. Most students skip interaction effects because they are harder to interpret, but interaction effects are often where the actual discovery lives. A treatment that works for one subgroup but not another is not a null result, it is a boundary condition. Blocking is useful when you have a known nuisance variable, like prior knowledge or site location, that you want to hold constant across conditions rather than hoping randomization will average it out.
Get the Full Details
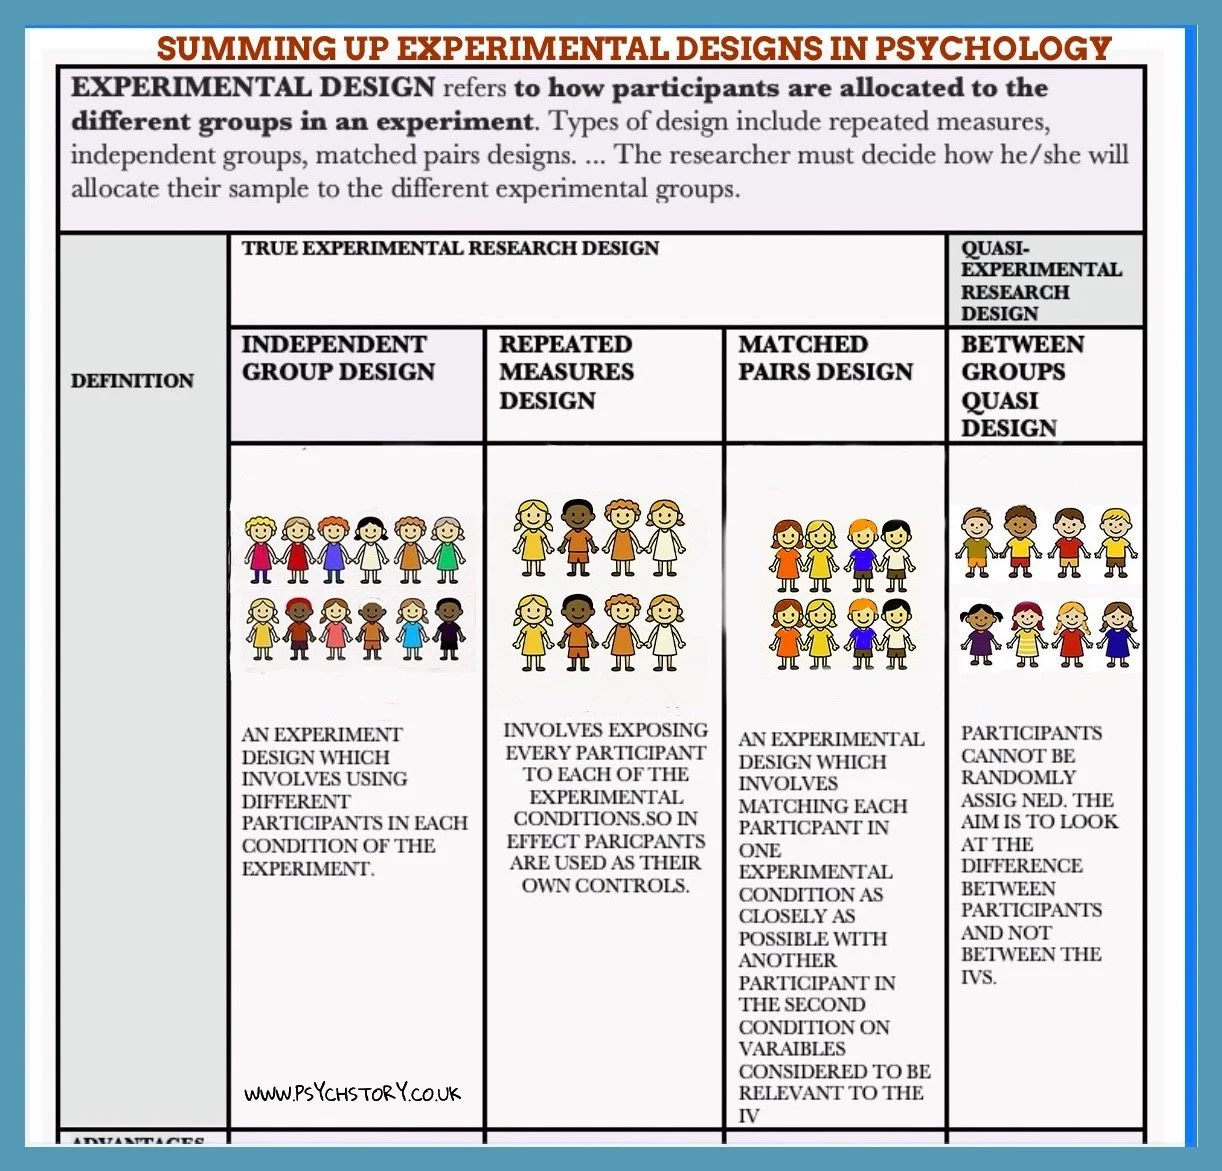
Latin square designs handle order effects in within-subjects experiments by rotating the sequence of conditions so each condition appears once in each position. This is essential when you cannot avoid measuring the same participants under multiple treatments. The tradeoff is that you need at least as many participants as conditions, and the design becomes unwieldy quickly once you go beyond three or four conditions. One edge case that tripped me up for a long time involves carryover effects in within-subjects designs where the treatment has a lasting impact. I ran a cognitive training study where the treatment group showed improvement that persisted across sessions, making the control condition during the same session contaminated by the earlier treatment exposure. The workaround was a washout period between conditions, but the washout had to be long enough to be effective and short enough that participants did not drop out from boredom. I ended up using a 48-hour gap between sessions with a filler task in between, which reduced but never fully eliminated the carryover concern. That is just the reality of within-subjects designs: you manage threats, you do not eliminate them. Another thing beginners consistently get wrong is power. A design looks elegant on paper until you realize your sample size gives you 30% power to detect the effect you care about. Power analysis is not a formality, it is a design decision. Using G*Power or an equivalent tool before you commit to a design saves months of work. If your planned study has low power, you either increase N, increase your expected effect size by tightening your manipulation, or drop the study and measure something more sensitive. Running an underpowered experiment is worse than running no experiment at all because it produces non-replicable noise.
The biggest limitation of experimental designs, especially the true experimental kind, is external validity. A tightly controlled lab experiment with random assignment tells you very little about how the treatment works in the real world where countless uncontrolled variables are operating simultaneously. Field experiments and randomized controlled trials in natural settings help bridge this gap, but they introduce their own complications: compliance issues, attrition, and contamination between treatment and control groups that you cannot fully prevent. If your question is about whether a treatment works in practice, not just in theory, you should plan for a field design from the start rather than retrofitting one after a lab study fails to generalize. When experimental designs are not the right tool, correlational designs, case studies, and longitudinal observational studies may serve you better. None of them establish causation the way random assignment does, but they are often the only feasible approach for questions about rare populations, ethical constraints, or complex real-world systems where manipulation is impractical or harmful.