Running Experiments and Comparing Them to What Should Happen
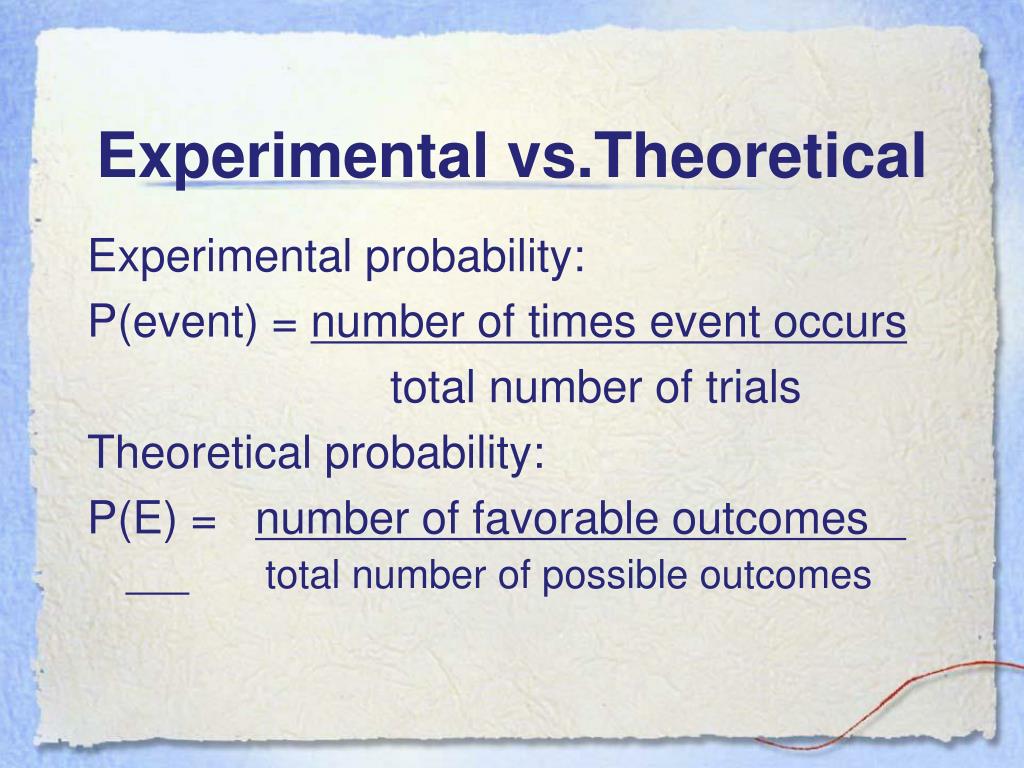
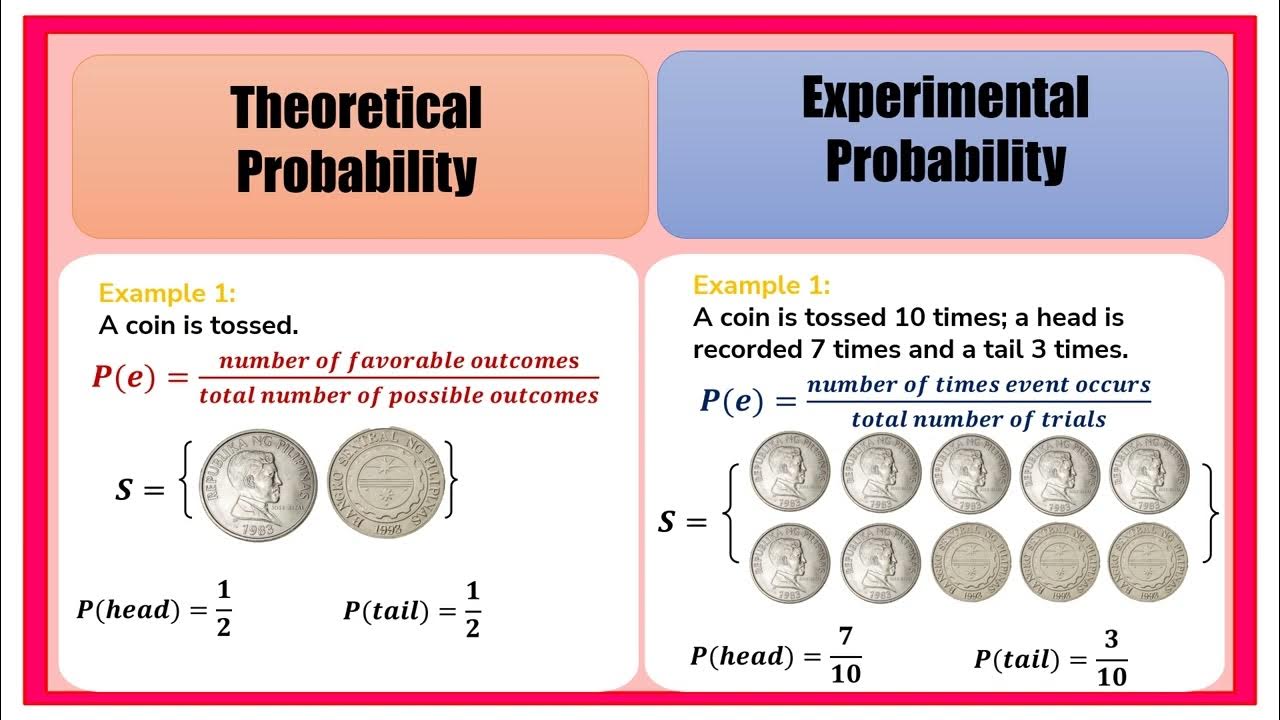
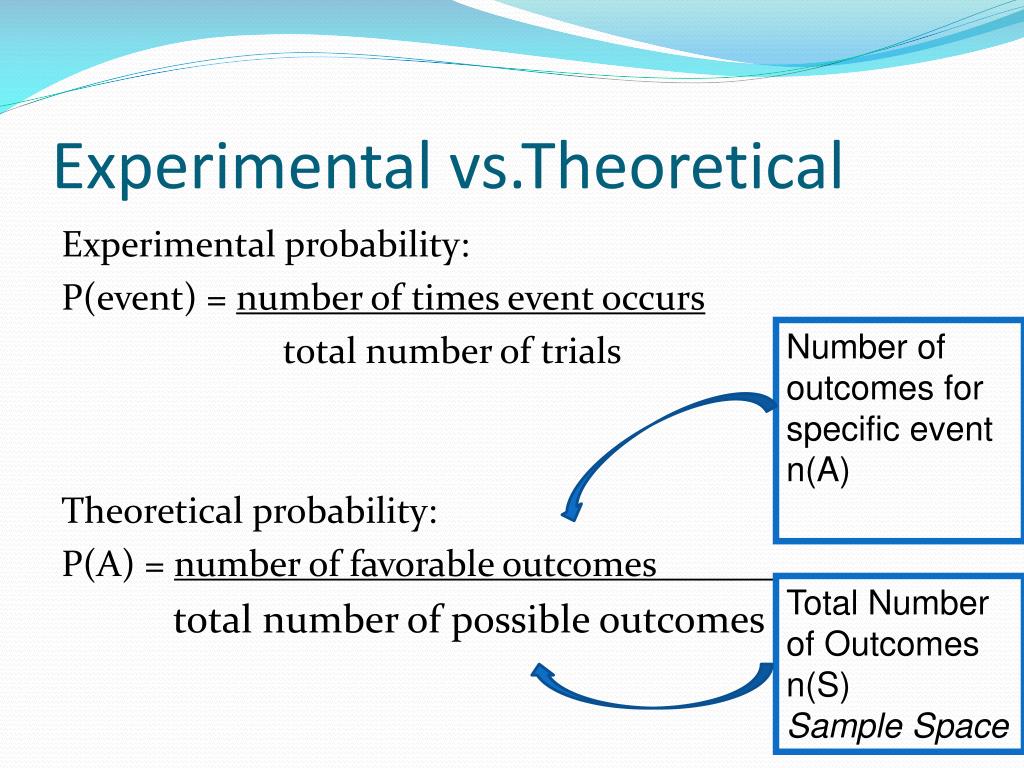
The core distinction is straightforward enough, but the gap between the two is where things get messy in practice. Theoretical probability comes from pure math. You count the possible outcomes and divide favorable ones by total ones. If you flip a fair coin, the theoretical probability of heads is 1/2 because there are two equally likely outcomes and one of them is heads. There is no flipping involved. Experimental probability comes from actually doing the thing. You flip a coin fifty times, count how many times it lands on heads, and divide by fifty. That ratio is your experimental probability. It will rarely be exactly 0.5. That is normal. It is not a mistake. It is just variability, and it never fully goes away unless you have an infinite number of trials.
Experimental Vs Theoretical Probability: What Actually Matters
The law of large numbers tells us that as trials increase, experimental probability converges toward theoretical probability. This is true, but beginners treat it like a switch that flips at some arbitrary sample size. It does not. The convergence is gradual, uneven, and stubborn. In my experience, running even a thousand trials on a simulated coin flip will usually land somewhere between 0.47 and 0.53. That range looks wide until you remember that each individual trial is binary and high-variance. Here is a concrete edge case I ran into recently that most tutorial-level advice glosses over. I was analyzing a loaded die problem for a quality control client. The theoretical model assumed a standard six-sided die where each face had a 1/6 probability. The experimental data showed face 3 coming up roughly 22 percent of the time across 2,000 rolls. A naive reading would suggest the die was biased, which it was. But the deeper issue was that the manufacturer's specification allowed a tolerance of ±3 percent on each face. Face 3 was well outside that band, but faces 1 and 6 were sitting at about 14 percent and 15 percent respectively, which looked suspicious but fell within the manufacturing tolerance. I had to explain to the client that statistical significance and practical significance are different things. The deviation on face 3 was statistically significant at p
0.01, but the client needed to know whether it mattered for their assembly line, which it did not. They adjusted their acceptance criteria rather than rejecting the entire batch. That example shows why the comparison between experimental and theoretical matters more than either number alone. The theoretical model gives you a baseline. The experimental result gives you reality. The space between them is where decisions actually happen.
How to Actually Compute and Compare Both
Start with the theoretical side. Define your sample space completely before you run any trials. A common error is assuming equiprobability when the outcomes are not actually equally likely. Consider drawing cards from a deck without replacement. The probability of drawing an ace on the first draw is 4/52. The probability on the second draw is not simply 4/51 if you do not know the first card. Conditional probability changes everything. I see this mistake constantly in introductory courses where students compute sequential probabilities as if each draw is independent. For the experimental side, your procedure needs to be repeatable and your sample size needs to be large enough to make the comparison meaningful. There is no universal rule for what counts as large enough. It depends entirely on the variance of your underlying distribution and the precision you need. A rough heuristic used in introductory stats is at least 30 trials, but that is a minimum for central limit theorem applications, not a magic threshold for probability estimation. For binary outcomes with probabilities near 0.5, you typically want a few hundred trials before the experimental value stabilizes to within a couple percentage points of the theoretical value. For rarer events, you need thousands or tens of thousands. Compute the experimental probability by dividing the number of observed successes by the total number of trials. Then compare it to the theoretical value. The difference is your error term. Report it. Do not just say they are close. Say how close, in absolute terms and relative terms, and whether the gap is plausible given your sample size.
Get the Full Details

Where This Approach Breaks Down
Experimental probability cannot help you when you cannot run the experiment. Some events are one-off or irreversible. Estimating the probability of a specific bridge failing under a novel stress condition requires simulation and modeling, not repeated trials. In those cases, theoretical probability combined with Monte Carlo methods fills the gap, but you are now depending on the quality of your model assumptions rather than empirical data. Another failure mode is when the theoretical model itself is wrong. If you assume a fair coin and then use theoretical probability of 0.5 as your benchmark, your experimental comparison will always flag bias even when the coin is fine, simply because real-world conditions introduce tiny systematic deviations. Air currents, thumb pressure, landing surface. A coin flipped by machine in a vacuum will behave closer to the theoretical model, and most people do not have access to that kind of control. I learned this the hard way during a classroom demo where students spent an hour flipping coins and got results consistently skewed toward tails. The coins were not biased. The counting method was. They were inconsistently recording landings on slightly uneven tables, and the coin would sometimes roll and settle on a different face than intended. The theoretical model was correct. The experimental setup was flawed. Identifying which one was the problem took longer than the experiment itself. A third limitation is that theoretical probability assumes well-defined sample spaces. Real-world problems often have ill-defined or unbounded sample spaces. What is the theoretical probability that a randomly selected person in a city earns more than a certain amount? The sample space is not discrete. It is continuous and shaped by socioeconomic factors that shift over time. Theoretical probability approaches here rely on distributions and approximations, and the gap between experimental and theoretical becomes a measure of model fit rather than simple accuracy.
Practical Workflow for a Reliable Comparison
Write down your theoretical model first, including every assumption. State clearly what independence means in your context and whether outcomes are truly equally likely. Then design your experiment to match those assumptions as closely as possible. Randomization is non-negotiable. If your trials are not random, neither number is trustworthy. Run enough trials to make the comparison useful. Track the running experimental probability after each trial or batch of trials. Watch how it moves. If it is oscillating wildly, you need more data. If it has settled into a narrow band, you have enough. Compute the theoretical value from your model. Calculate the absolute difference. If the difference exceeds what your sample size should reasonably produce, revisit your experimental procedure before you revise your model. Most of the time the experiment is the weaker link. For the die quality control case I mentioned earlier, the workaround was to switch from a single long experiment to repeated shorter runs. Ten runs of two hundred trials each gave a distribution of experimental probabilities that let me calculate a confidence interval. The 22 percent figure on face 3 was statistically distinguishable from 1/6, and the variation across runs was small enough to confirm that the bias was systematic, not a fluke of one unlucky session. That approach takes more coordination but it is far more informative than a single aggregate number.
The Experimental Vs Theoretical Probability comparison is a tool, not a theorem. It works well when your model is sound and your data is clean. It fails or misleads when either side is poorly specified. Treat both numbers with equal skepticism and let the distance between them guide your next decision rather than your final conclusion.