EDA Doesn't Look Like the Tutorials Show You
The version of Exploratory Data Analysis you see in most blog posts has clean data, sensible distributions, and a clear narrative arc that leads straight to a model. That is not what happens in production. Your first week on any real dataset will involve discovering that the timestamp column is actually a string, that the "continuous" feature is mostly a single repeated value with a few catastrophic outliers, and that the target variable was coded as 0 and 1 in one file but as "no" and "yes" in another. Exploratory Data Analysis is simply the structured process of asking your data what it is before you try to do anything with it. That sounds obvious until you've spent three hours building a pipeline only to realize the model was trained on a feature that contains 94% nulls and the remaining values are all zeros. The goal of EDA is to catch those things before they become expensive mistakes. It is also the place where most projects stall because people treat it like a checkbox exercise instead of an investigation.
Getting Started with Exploratory Data Analysis on a Real Dataset
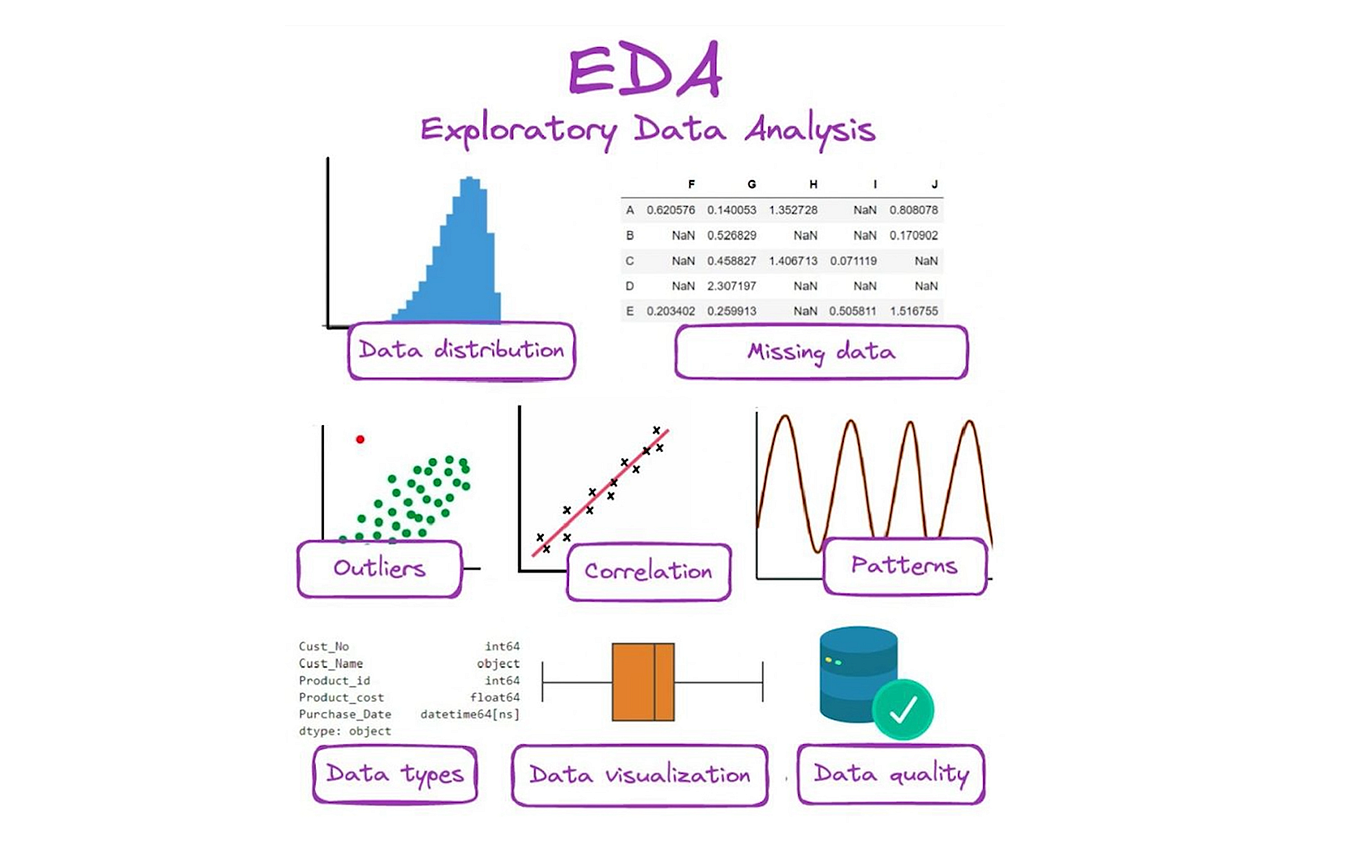
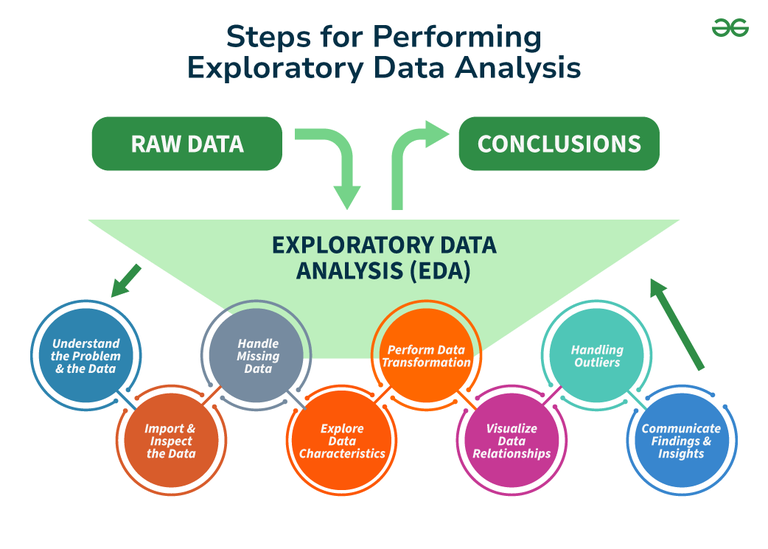
Load the data, check the shape, print the first five rows, then immediately call the describe method and dtypes together. Do not skip dtypes. The describe output will lie to you about object columns and it will silently summarize boolean columns as if they were numbers. Here is the practical checklist I run through on every project, usually in a Jupyter notebook but sometimes in a quick script when I am just trying to orient myself: Step one: Shape and missingness. Get the row and column count. Then compute the null percentage for every column. A column with under 5% missing data often does not need special handling. A column with 60% missing is either a noise variable or a signal you need to understand differently. I once dropped a column at 42% missing on a fraud detection dataset because I assumed it was low priority, then spent two weeks debugging why the model performance had dropped off a cliff. That column, "merchant_category_code", was actually the single strongest predictor for a subset of fraud types. The workaround was to split the analysis by missingness pattern itself, treating the absence of a value as its own category rather than deleting it. Step two: Data types and basic sanity checks. Verify that dates are actually datetime objects. Check that numeric columns contain only numbers and no sneaky string values hiding in there. Look at unique value counts for categorical variables. A column with 14,000 unique values labeled as categorical probably needs to be reclassified or is being used incorrectly.
Step three: Distributions and outliers. Plot histograms or kernel density estimates for continuous features. Look at box plots for outlier detection. The important part here is that you look at each feature individually and also in relation to the target variable. A distribution that looks normal in isolation might be completely bimodal when you color by churn status. That tells you something the aggregate statistics will never show you. Step four: Correlations and relationships. Compute a correlation matrix for numeric features. Look for pairs above 0.8 or below negative 0.8. High correlations between features do not automatically mean you should drop one, but they do mean you need to understand which one carries the predictive signal and which one is redundant. For tree-based models, redundancy matters less. For linear models with regularization, it matters a lot. Step five: Target analysis. If you have a supervised learning setup, break down the target variable immediately. Check class balance. Plot the target against the top five features you identified. This step alone will save you from building a model that achieves 99% accuracy by predicting the majority class every time.
Get the Full Details
I used to run all of this manually, which took anywhere from four to six hours on a typical dataset of moderate size. Now I use a combination of pandas profiling and custom scripts that automate the boring parts while leaving the interesting parts for manual inspection. Tools like ydata-profiling or pdpbox will generate a full report in about twenty minutes on a dataset with up to fifty thousand rows and a few dozen features. On larger datasets, the report generation time scales poorly and can take over an hour. The tradeoff is that automated reports tend to repeat the same visualizations without context, so I always end up spending additional time going back into the raw output to dig into whatever looked weird.
What Beginners Miss About EDA
The biggest mistake people make is treating Exploratory Data Analysis as something you do once at the beginning and then forget about. It is not a one-time task. When you engineer a new feature or split the data for cross-validation, you should run a quick EDA pass on the transformed version. Features derived from other features inherit their parent's problems, and sometimes they introduce new ones. I had a case where a log transformation created a massive cluster of near-zero values that looked fine in a histogram but revealed a severe skew when I plotted the same data on a logarithmic scale. That discovery changed the entire preprocessing strategy for that feature. Another thing that beginners consistently get wrong is relying too heavily on summary statistics. The mean and standard deviation will tell you very little about the actual structure of your data. A dataset can have a mean of zero and a standard deviation of one and still be completely useless for modeling because half the values are zeros and the other half are uniformly distributed between negative two and positive two. Look at the actual data. Plot it. Trust the visualizations more than the numbers. There are also edge cases where standard EDA techniques fail entirely. I worked on a geospatial dataset where the features were encoded as coordinate pairs stored in a single string column. The correlation matrix was meaningless because the relationship was spatial, not linear. I had to extract latitude and longitude separately, create distance calculations from key points, and then visualize the data on an actual map. No amount of standard Exploratory Data Analysis would have caught that without physically looking at the geographic distribution of the samples.
The downside of investing heavily in EDA is that it can consume a disproportionate amount of project time without producing a deliverable anyone else can see. Stakeholders want models. They do not want to hear about how you spent three days understanding the data. The pragmatic approach is to timebox your exploration. Spend the first few hours on the initial pass to catch deal-breakers, then move into iterative refinement alongside model development. If a feature is clearly uninformative, drop it early. If a pattern emerges that affects your approach, document it and adjust. Do not let perfect be the enemy of shipped.

Practical Tools and Workflow
For the core workflow, pandas, numpy, matplotlib, and seaborn cover most needs. If you are working with larger datasets, switch to Polars or DuckDB for the initial inspection phase. Reading a ten-million-row CSV into a pandas DataFrame can take upwards of thirty seconds and consume a significant amount of RAM, which slows down the iterative exploration process considerably. DuckDB handles that same file in under two seconds and uses columnar storage to make aggregation queries much faster. I also keep a small personal library of functions for common checks. A function that prints missingness percentages with color coding, a function that flags columns where the unique value ratio exceeds a threshold, a function that compares train and test distributions to catch data leakage before it happens. These are not sophisticated tools. They are just convenience wrappers that save me from rewriting the same boilerplate on every project. The time savings add up. A routine that normally takes twenty minutes of typing and debugging gets reduced to a single function call. When the dataset is large enough that loading it into memory is impractical, use sampling. Draw a random subset of fifty thousand to one hundred thousand rows and run your EDA on that. The distributions and relationships you identify will generally hold across the full dataset. This is not a perfect approximation, but it is orders of magnitude faster than waiting for full-data computations, and it catches the vast majority of issues that matter at this stage.
One specific scenario where I recommend a different tool entirely is when you are dealing with high-dimensional categorical data. Standard correlation matrices become unreadable with more than twenty or thirty categorical features. In those cases, I use association rule mining or chi-squared tests to identify which categorical combinations actually relate to the target. It is a different kind of exploration, but it serves the same purpose and it scales better than trying to force a heatmap to display three hundred categories. The reality of working with real data is that the data will surprise you. The EDA process exists to make sure you are surprised by the right things at the right time, rather than discovering a fundamental problem during model evaluation when fixing it requires going back to square one. Spend the time upfront. It will save you time later.