EDA is mostly just looking at data until something looks wrong
I get this question a lot, and honestly the answer is simpler than most tutorials make it sound. You load your data, you check what it looks like, and you figure out which columns are going to cause problems later. That's it. But doing it properly takes some discipline because the defaults are not your friend. Pandas is the workhorse. It handles loading, filtering, reshaping, and basic statistics. Pandas alone covers maybe 70 percent of what you need on a typical project. For the remaining 30 percent, seaborn and matplotlib give you visualizations, and pandas-profiling generates full HTML reports automatically. If you're working with big datasets where a full profiling report would crash your machine, ydata-profiling is the same tool with better memory handling. The basic workflow starts with loading data. A CSV file is the most common starting point, though in production you'll more often be pulling from databases or cloud storage. The command is straightforward. You read the file, you check the shape, you look at dtypes, you scan for nulls. These four steps take about 30 seconds for any dataset under a hundred columns.
import pandas as pd

df = pd.read_csv('data.csv')
print(df.shape)
print(df.dtypes)
print(df.isnull().sum())
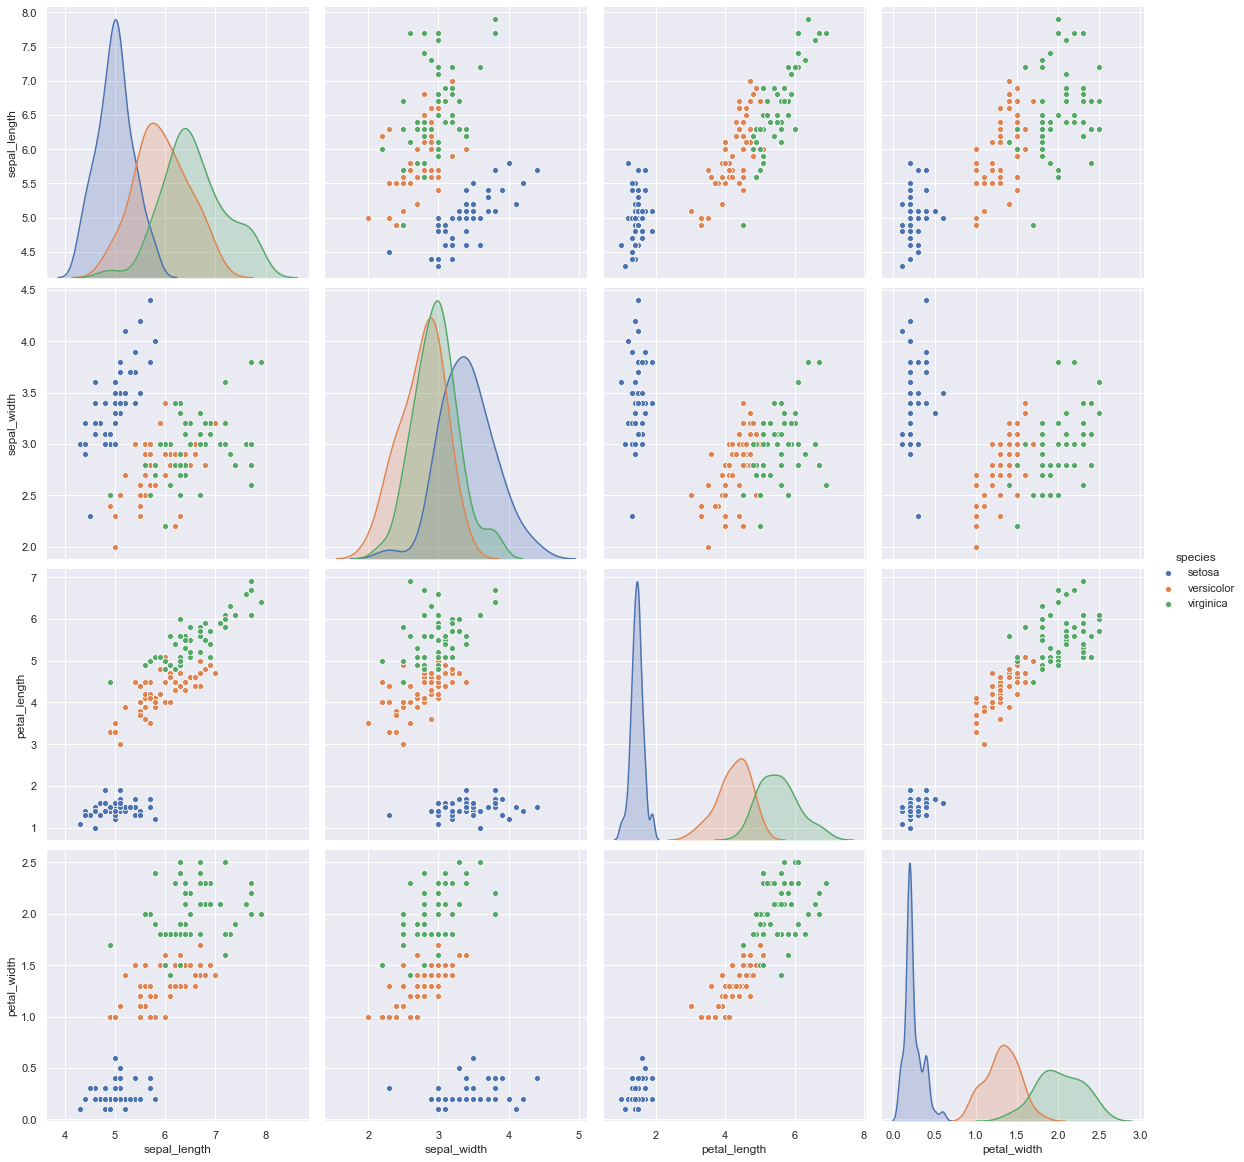
After the initial scan, you look at summaries. describe() gives you counts, means, standard deviations, quartiles. It's useful but it hides a lot. The standard deviation assumes a normal distribution, and most real data is not normally distributed. If your data is heavily skewed, the mean and standard deviation from describe() are basically decorative. In those cases, rely on the percentiles instead. The 10th and 90th percentiles tell you more about your data than the mean does. Visualization is where people waste the most time. The temptation is to plot everything immediately. Don't. Plot the distribution of each numerical column first. That's your most important view. Histograms and density plots show you skewness, outliers, and multimodal distributions. You'll often spot data entry errors or encoding issues that don't show up in summary statistics. A column that looks perfectly clean in describe() can have a massive spike at zero or an impossible value range when you actually plot it. For categorical columns, count plots matter more than bar charts of averages. If you're building a model later, knowing the class distribution is critical. A feature with 98 percent one value and 2 percent another is essentially a constant. It will not help your model and it might hurt it by adding noise.
Relationships between columns are the next step. Scatter plots for two numerical variables, box plots for a numerical versus a categorical variable, and correlation heatmaps for quick scans of many columns. The heatmap is fast but it only captures linear relationships. Spearman correlation is better if you suspect monotonic but nonlinear patterns. Both are available in pandas and take one line of code. Here's a part that almost nobody mentions until they've already spent hours debugging. Missing data patterns. df.isnull().sum() tells you how many values are missing per column. It does not tell you whether the missingness is random or structured. If 40 percent of values in a column are missing but they're all concentrated in a single date range, that's a data collection issue, not random noise. You need to cross-reference missing values with other columns to detect this. I spent three days on a project once because I treated a completely broken sensor reading as random missing data. The fix was spotting that every row with a null in that column had a timestamp during a specific outage window. Once I knew that, I could either impute from adjacent timestamps or drop that entire time range before modeling. Another thing people miss: duplicate rows. They rarely appear in isnull() output. You have to explicitly check for them.
Get the Full Details

df[df.duplicated()]
Duplicates are common in ETL pipelines where jobs run twice, or when data is merged from multiple sources. If you don't catch them before analysis, your summary statistics will be wrong and your models will overfit to the duplicated records. The fix is usually dropping them after confirming they're truly redundant. Sometimes duplicates carry meaning though. In transaction data, repeated entries might indicate legitimate activity. You need to decide case by case. Memory optimization is another quiet time sink. Pandas loads integer columns as int64 by default, which uses 8 bytes per value. If your values fit in 8-bit or 16-bit integers, converting them down to int8 or int16 can cut memory usage significantly on large datasets. The same applies to floats. float32 is often sufficient and halves your memory compared to float64. Categorical data with repeated string values should be converted to the categorical dtype instead of staying as object strings. These conversions happen in pandas.read_csv() with the dtype parameter or through df.convert_dtypes() for a quick automatic pass. When datasets get above a few hundred thousand rows, pandas starts to slow down noticeably for certain operations. Groupby operations and merges are the most affected. At that point, switching to Polars or cuDF for GPU acceleration can give you five to ten times faster execution on aggregations and joins. Polars is particularly worth considering because the API is nearly identical to pandas. You can often swap them with minimal code changes.
One counter-intuitive thing about EDA: the more you explore, the more likely you are to find patterns that are real artifacts of your data collection process rather than meaningful signals. A strong correlation between two features might just mean both are driven by a third hidden variable, or by the way the data was sampled. Always ask which variables were recorded and how. Data that comes from logging systems, surveys, or automated sensors each has different failure modes. Log data has truncation issues. Survey data has response bias. Sensor data has calibration drift. Knowing your data source changes how you interpret every pattern you find. There's also a practical limit to EDA reports. pandas-profiling generates a full HTML report in about 30 seconds for a dataset with a few thousand rows and fifty columns. For a million rows, it can take twenty minutes or more and may crash your browser when you try to open the report. In those cases, generate the report on a subset first to validate the workflow, then run it on the full data in a headless environment if needed. Finally, save your EDA findings somewhere. I've seen too many people do thorough exploration and then lose track of what they found because they never documented it. A simple text file or notebook section with key observations, decisions about missing values, and notes on feature transformations is enough. Your future self will thank you when you come back to the project six months later.