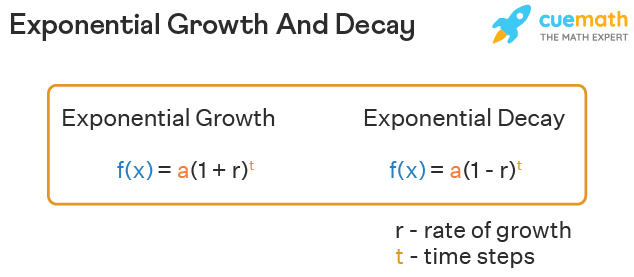Working With Exponential Decay in Real Data
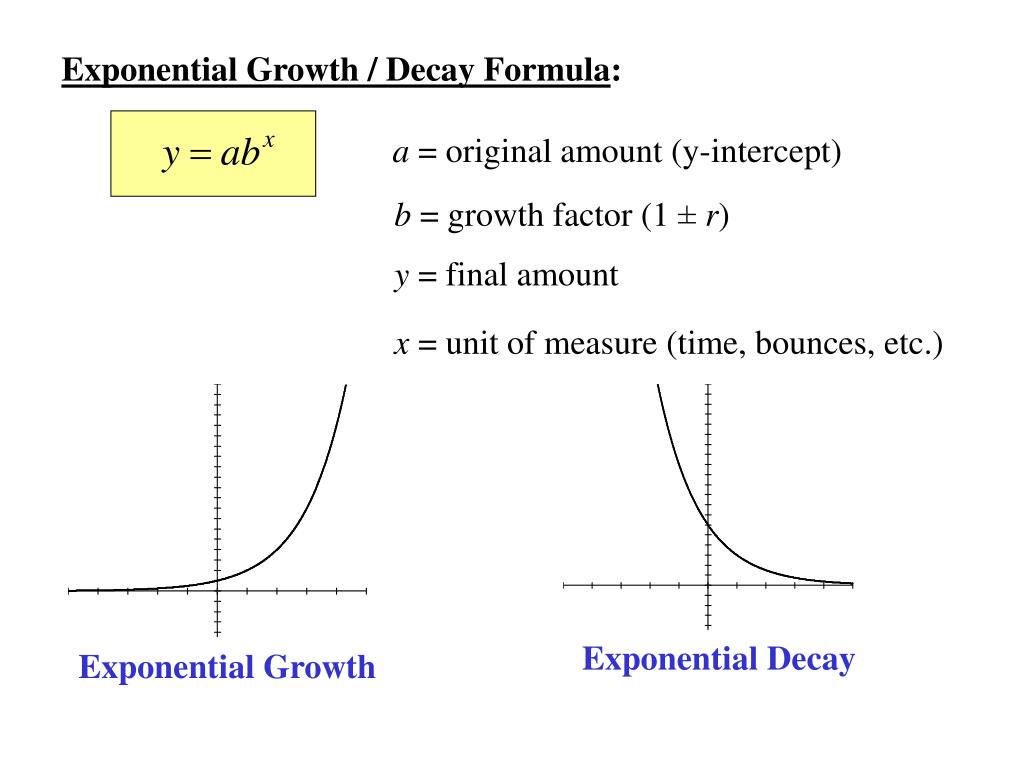
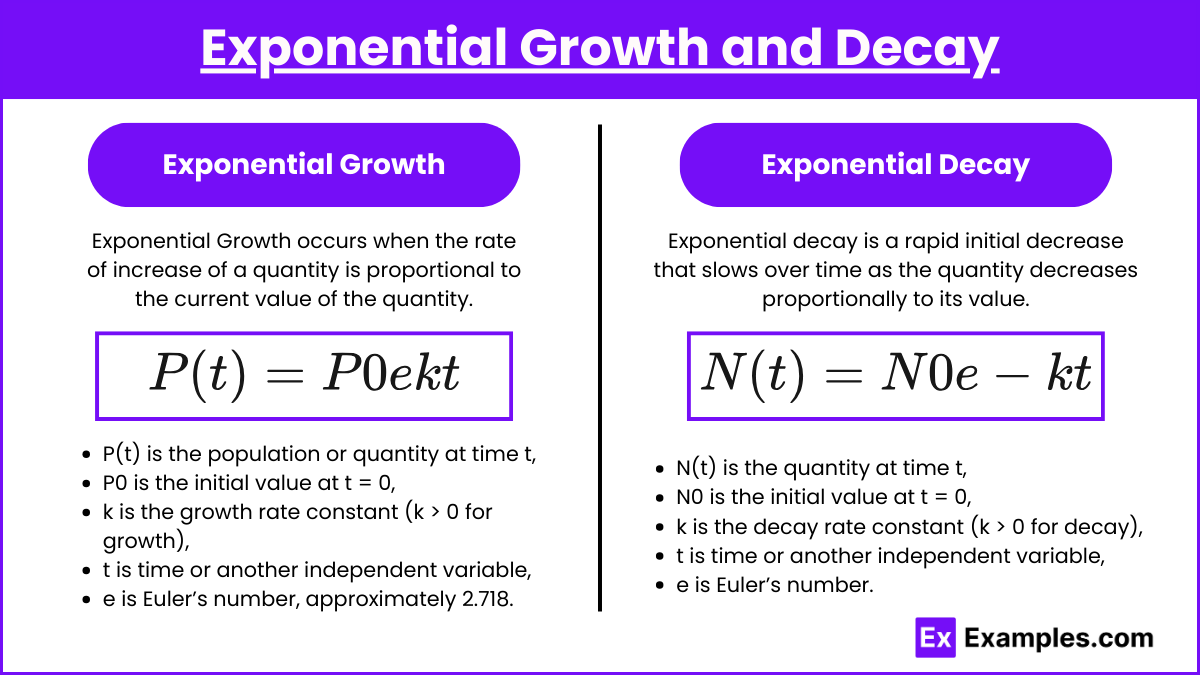
I spent about three weeks debugging a decay curve that refused to behave. The model kept overshooting on the tail end, and I couldn't figure out why until I realized the issue wasn't with the solver—it was with the initial guess. Starting values for the amplitude parameter completely changed the convergence path. That's the kind of thing that eats days off your life if you don't catch it early. The basic form is straightforward: N(t) = N × e^(-t) for decay, and N(t) = N × e^(+t) for growth. N is your starting quantity, is the rate constant, and t is time. But writing that down on paper is nothing like fitting it to actual data. What people miss is that this formula assumes a closed system with no external input. If you're modeling something like drug clearance from the bloodstream, radionuclide decay, or even subscriber churn on a SaaS product, you've got to verify that assumption first. I had a dataset where the decay looked perfect for the first 48 hours, then flattened out. Turned out there was a secondary absorption phase kicking in—basically the body holding onto the compound longer than the model allowed for. The workaround was switching to a biexponential model: two decay constants instead of one. Same mathematical structure, just layered. Took me about ten minutes once I knew what to look for.
Another counter-intuitive thing: taking the natural log of both sides to linearize the equation works beautifully in theory. In practice, it biases your least-squares fit toward the low-value points because the transformation compresses the scale. If you're doing manual fitting instead of using a non-linear optimizer, you'll get systematically wrong rate constants. I learned that the hard way when my half-life estimates were consistently 15 percent too short compared to the published literature. The trick is to fit the raw equation directly without linearizing. Most modern toolkits handle this fine—SciPy's curve_fit, even Excel's Solver if you're stuck there. The fitting time barely changes, but the accuracy does. Non-linear fitting on a clean dataset with good initial guesses usually converges in under a second on any reasonable hardware. Half-life is just ln(2)/, which most people know. What's less obvious is that the decay constant has units of inverse time, so it's only meaningful relative to whatever time unit you're measuring in. Reporting = 0.034 without stating "per hour" is useless. I've seen this mistake in peer-reviewed papers, which should tell you something.
When your data has noise near zero, exponential decay becomes numerically unstable. The algorithm tries to push N higher and lower to accommodate the floor effect, and you end up with garbage parameters. A practical fix is to exclude points below your detection threshold entirely rather than including them as censored data unless you're doing survival analysis properly. There's also the issue of overfitting when you add extra exponentials. A single decay term gives you three parameters: N, , and potentially an offset. Two terms give you six. With noisy experimental data, that's enough degrees of freedom to fit random fluctuations. The rule of thumb I use is that each additional exponential term should reduce the residual sum of squares by at least 20 percent to justify its cost. Otherwise you're just chasing noise. For those looking to implement this from scratch, the essential piece is just computing e raised to a power. Every programming language has this built in. The harder part is getting the fitting right, which is why libraries exist. Don't write your own Levenberg-Marquardt optimizer unless you enjoy debugging numerical edge cases at 2 AM.
Get the Full Details

The exponential decay model breaks down when the underlying process isn't memoryless. If a system's decay rate changes depending on how long it's already been decaying—like certain chemical reactions with autocatalytic steps or battery capacity fade that accelerates after a threshold—then no amount of tweaking will make this formula fit well. That's not a limitation of the math, it's a limitation of the model choice. You'd need a power law or a stretched exponential at that point. I keep a simple reference table for common conversions: half-life to decay constant, decay constant to mean lifetime ( = 1/), and the relationship between the two. It saves me from re-deriving things I already know. Mean lifetime is often more useful than half-life in physics contexts because it appears directly in the differential equation dN/dt = -N/. If you need a working implementation, the standard approach is using scipy.optimize.curve_fit with the model function defined as n0 * np.exp(-lambda_val * t). Set bounds on lambda to be positive, and you can usually get away with n0 as unbounded. Initial guesses of n0 equal to your first data point and lambda equal to 1 over the time it takes to drop to about 37 percent of n0 tend to work well as starting points. Convergence is typically achieved in fewer than 20 iterations for clean data.
The model has real constraints that nobody mentions in textbooks. It cannot handle systems with production and decay happening simultaneously—that's a different differential equation entirely. It assumes the rate is proportional to the current amount at every instant, which sounds simple but excludes a lot of real-world processes where the rate depends on something else entirely. And it is wildly sensitive to outliers in the early time points because those dominate the curvature that determines . When I need something faster than a full non-linear fit for quick-and-dirty estimates, I use the two-point method: pick any two data points, solve for algebraically, and check whether the implied N matches your actual starting value. If they agree within 10 percent, you have a reasonable estimate without running any optimization. It's not rigorous, but it catches gross errors in seconds and tells you whether the data is even compatible with exponential decay before you waste time on a full fit. The takeaway is that the formula itself is elementary, but using it correctly requires checking assumptions, choosing the right fitting method, and knowing when the model has run out of road. Most failures come from applying it to processes that don't actually follow exponential dynamics, not from mistakes in the mathematics.