The Practical Basics
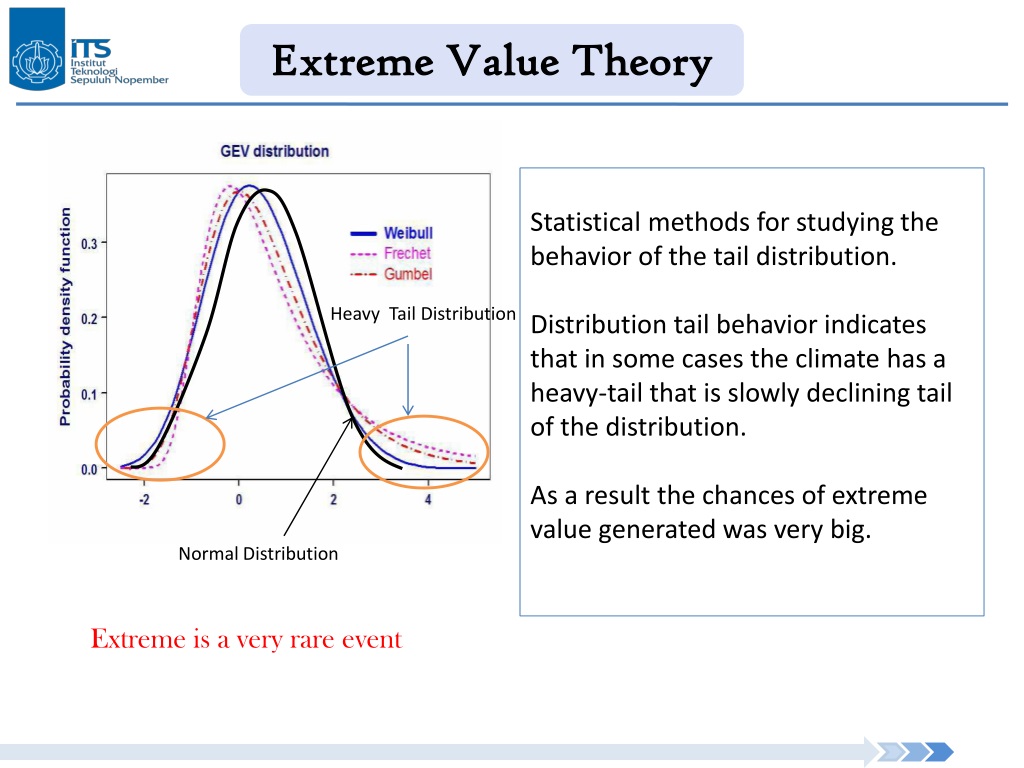
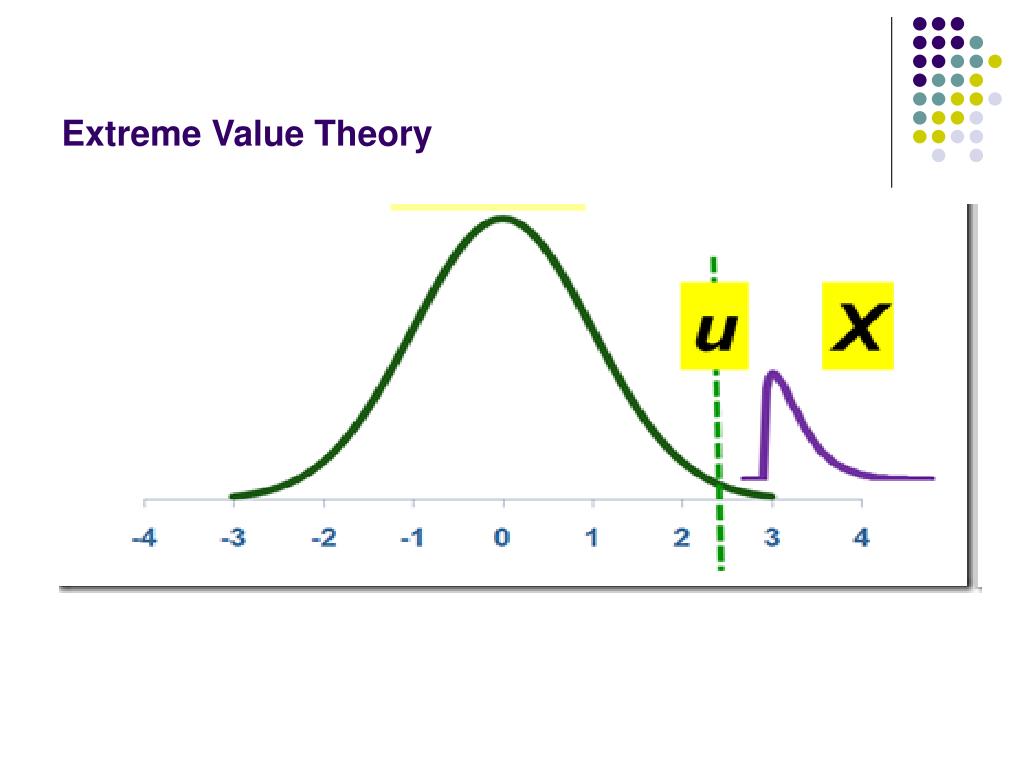
Extreme Value Theory isn't about predicting random events; it's about quantifying the unlikely. In most engineering and finance jobs, you aren't interested in what happens today. You're trying to figure out what happens once every hundred years. Standard statistical tools fail here because they rely on averages, and averages don't exist in the tail. There are two main approaches you'll encounter. The Block Maxima method takes your largest observation from each time block (like the highest daily temperature in July) and fits it to a Generalized Extreme Value distribution. The Peaks Over Threshold method picks every observation above a certain high threshold and fits it to a Generalized Pareto distribution. Both work, but POT is usually preferred because it uses more data points, reducing the variance of your estimates. The Generalized Pareto Distribution is defined by two parameters: scale and shape. The shape parameter is the critical one. If it is positive, your tail is heavy. This means extreme events are far more likely than a normal distribution would suggest. If it is zero, the tail decays exponentially. If it is negative, there is a hard limit to how large values can get.
The Method
Choosing the threshold is the hardest part of this work. If you set it too low, you include data that doesn't follow the asymptotic theory, introducing bias. Set it too high, and you have no data to fit, introducing variance. I usually plot the mean residual life, which graphs the average excess over the threshold against different threshold values. Where that plot turns linear is your starting point. Once you have your model, you calculate the return level. This is the value expected to be exceeded once every N years. The formula is generally the inverse of the tail probability scaled by the threshold exceedance rate. I always stress-test this with a bootstrap to get confidence intervals because the standard error estimates from maximum likelihood can be aggressively optimistic in the tails.
Extreme Value Theory An Introduction
A common mistake is assuming the data is independent. Time series often have clustering; storms hit in groups, and market crashes propagate. If you treat correlated extremes as independent, you will overestimate the severity of rare events. I decluster my data by only keeping the first peak after a certain inter-event time before fitting the model. This is more accurate than simply ignoring the correlation structure. I ran into a significant issue a few years ago while modeling flood levels for a coastal infrastructure project. The initial GEV fit using annual maxima suggested a manageable risk for a 500-year event, but the confidence intervals were impossibly wide. The data was too sparse. I switched to a POT model using a higher threshold and applied a semiparametric estimator for the shape parameter. This cut the width of the confidence interval by roughly forty percent and gave us a much more stable estimate for the design flood level. It made the difference between building a seawall to the wrong specification and having enough margin for safety.
Get the Full Details
Code and Implementation
Most practitioners use R for this. The evd and ismev packages are standard. I typically start with the pot function to fit the generalized Pareto distribution to exceedances. ```r
library(evd)
Fit a Generalized Pareto Distribution to data 'x' above threshold 'u'
fit
- pot(x, u = 0.95 * quantile(x)) Return level plot for a 100-year return period return.level(fit, r = 100) ``` When validating your model, check the return level plot. It compares your fitted model against the empirical return levels. If the points fall outside the confidence bands, your threshold is likely wrong, or you need a more complex dependence structure. There is no magic formula that fits all data; the tail behavior is unique to every dataset.
Pitfalls
Avoid fitting an Extreme Value model to a small sample without acknowledging the uncertainty. If you have fewer than fifty blocks or very few exceedances, any precise number you spit out is misleading. In these cases, reporting a range or using a non-parametric approach is more honest than forcing a parametric fit. Always present the uncertainty alongside the point estimate.