Getting Factorial ANOVA Actually Right
You run a factorial design when you need to know whether two or more categorical independent variables interact with each other while affecting a continuous outcome. The most basic version is a 2x2 setup. You have two independent variables, each at two levels. Treatment versus placebo. High temperature versus low temperature. Something like that. One dependent variable measured at the interval or ratio level. You want main effects for each factor, but the interaction term is usually the thing you actually care about. I spent three days last year debugging a 2x3x2 Factorial Analysis Of Variance because the interaction p-value kept shifting depending on whether I used Type II or Type III sums of squares. The dataset had unbalanced cell sizes, which is common in real research where some participants drop out or data gets lost. SPSS defaults to Type III, but if your design is unbalanced, Type III tests each effect after all others, including interactions. That means the main effect results depend on which interactions are in the model. In balanced designs, all the types give identical answers. In unbalanced ones, they diverge. My workaround was straightforward: I re-ran everything with Type II SS, which tests each effect after the lower-order terms that contain it. For main effects in an unbalanced factorial, Type II is more appropriate. I also ran a restricted maximum likelihood mixed model in R as a sanity check and compared the F-values. They matched within rounding error. It took about twenty minutes to validate, but it saved me from publishing incorrect conclusions.
When Factorial Analysis Of Variance Is the Right Tool and When It Isn't
The model partitions the total sum of squares into components attributable to each main effect, each interaction, and the residual error. With a 2x2 design you get four pieces: SSA, SSB, SSAB, and SSE. Each gets divided by its degrees of freedom to produce a mean square. The F-statistic is just the ratio of a mean square effect to the mean square error. If the effect mean square is substantially larger than the error mean square, the factor or interaction likely has a real influence. Nothing magical about it. It is algebra. Here is the part most tutorials skip. Homogeneity of variance matters more in factorial designs than in one-way ANOVA because imbalance compounds the problem. When you have unequal sample sizes across cells and the variances are also unequal, you get the Behrens-Fisher problem multiplied across combinations. The standard ANOVA F-test becomes unreliable. I once had a design where the largest cell had a variance four times that of the smallest cell, and the sample sizes were inversely related. The omnibus F was significant at p = 0.03, but Welch's version and Brown-Forsythe corrections both eliminated significance. I reported the Welch result and flagged the violation in the methods section. Most reviewers accept that if you catch it yourself. Another thing people get wrong is the assumption of normality. The residuals need to be approximately normal, not the raw data. With moderate sample sizes per cell, the central limit theorem does enough work that minor skew is acceptable. But with small n and heavy skew, the Type I error rate inflates noticeably. I typically run Shapiro-Wilk on residuals and check Q-Q plots. If n is below about ten per cell and the distribution is skewed, I switch to a rank-based approach or bootstrapped confidence intervals rather than pretend the parametric test is fine.
Power in factorial designs behaves in an unintuitive way. Adding a second factor can increase or decrease power for the first factor depending on how much variance the second factor explains and whether the two factors are correlated through the experimental design. In a completely randomized factorial, they are orthogonal by construction, so adding a factor always reduces the residual degrees of freedom and slightly reduces power for everything else. But if one factor explains a large chunk of variance, the residual mean square shrinks, and power for the remaining effects can actually improve. I have seen main effects go from marginal to highly significant simply because an interaction term absorbed noise that was previously sitting in the error term. Post-hoc analysis after a significant interaction is where most mistakes happen. You do not simply run Tukey's HSD on the main effects. When an interaction is significant, the main effects are often uninterpretable in isolation. You need simple effects analysis. Test the effect of one factor at each level of the other factor. Adjust for multiple comparisons within each set of simple effects, but do not apply a broad Bonferroni correction across all possible comparisons unless you really mean it. I usually set alpha at 0.05 for each simple effect family and report the adjusted p-values with Cohen's d or partial eta squared for effect size. Partial eta squared is the default output in most software, but it overestimates the population effect when the design is unbalanced. Omega squared or generalized eta squared is more conservative and more honest about what the effect actually is. There are hard limits to this method. Factorial ANOVA cannot handle repeated measures on all factors unless you use the repeated measures variant. It assumes independent observations. If you have clustered data, hierarchical structures, or subjects measured multiple times, you need linear mixed models. A 2x2 between-subjects ANOVA on data with ten measurements per subject is fundamentally the wrong analysis. I have seen this mistake in grant reports and even in published papers. The remedy is not a correction factor. It is a different model entirely. Generalized linear mixed models with the appropriate link function handle non-normal outcomes and random effects without forcing you into transformation gymnastics that distort interpretation.
Get the Full Details

Computational issues are rare but real. If any cell is completely empty, the design is singular. Some software drops terms silently. Others throw errors. A missing cell in a 2x2 design means you cannot estimate the interaction independently of the main effects. You either collect data to fill the gap or you reduce the model to additive effects only and acknowledge the limitation. There is no statistical trick that recovers an estimable interaction from a structurally empty cell. The same applies to near-empty cells with one or two observations. They create extreme leverage points that can dominate the sums of squares. I routinely check cell sizes before running the analysis and flag any cell below five observations.
Practical Execution Notes
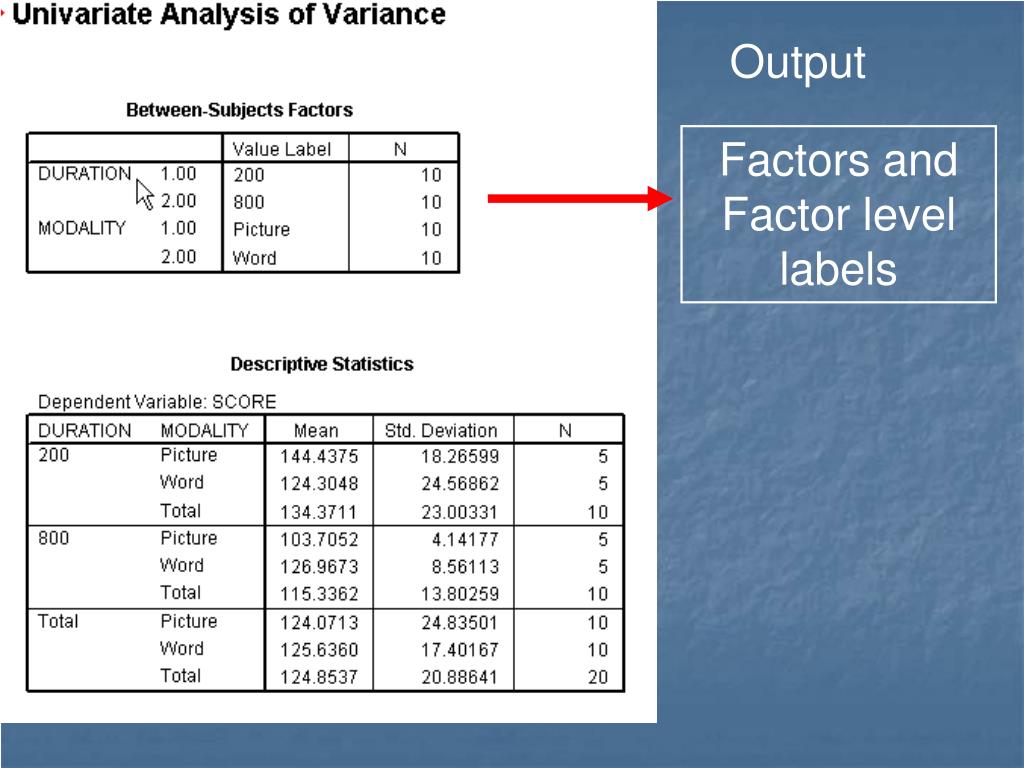
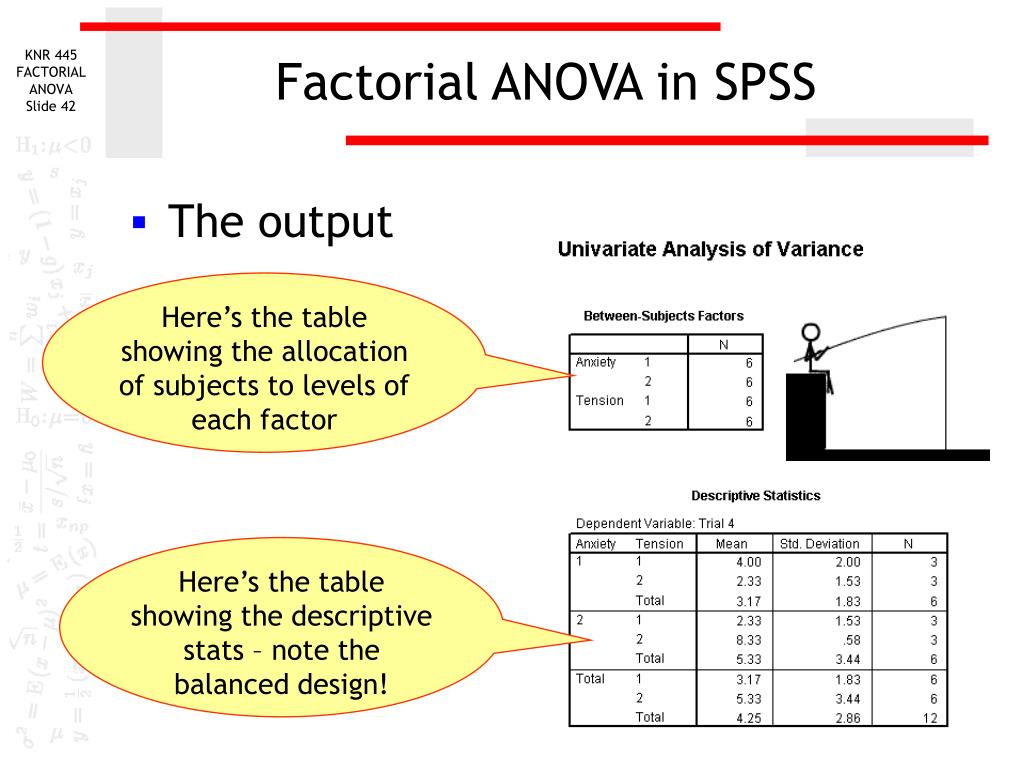
Most researchers use SPSS, JASP, R, or Python's statsmodels. In SPSS, the GLM command handles factorial designs. In R, aov() works for balanced designs and lm() with car::Anova() handles unbalanced ones with different Type SS options. In Python, statsmodels.api.OLS combined with statsmodels.formula.api with Type II or III SS gives you the same partitioning. The outputs are numerically equivalent across platforms when specified correctly. I check all three when the analysis is high-stakes. Sample size planning for factorial designs requires specifying the smallest interaction effect you consider meaningful. G*Power has a built-in option for F-tests with multiple groups and covariates, which covers factorial ANOVA. For a 2x2 with a small interaction effect size of f = 0.15, alpha = 0.05, and power = 0.80, you need roughly 176 total participants. That is 44 per cell. If you expect a medium interaction of f = 0.25, you drop to about 64 total. These numbers assume a between-subjects design. Within-subjects or mixed designs require fewer participants because the within-subject correlation reduces error variance. I usually power for the interaction specifically because that is the effect most likely to be missed with inadequate sample sizes. The method remains one of the most useful tools in the experimental statistics toolkit. It is not a universal solution. It fails when assumptions are badly violated and the data cannot be salvaged through transformation or robust alternatives. It fails with nested or hierarchical structures. It fails when you have more factors than you can reasonably interpret. But when the design is clean, the assumptions are met, and the question is about main effects and interactions in a controlled experiment, factorial ANOVA gives you a direct, interpretable answer without requiring the computational overhead or convergence diagnostics that more complex models demand.