What the Phrase Actually Means in Practice
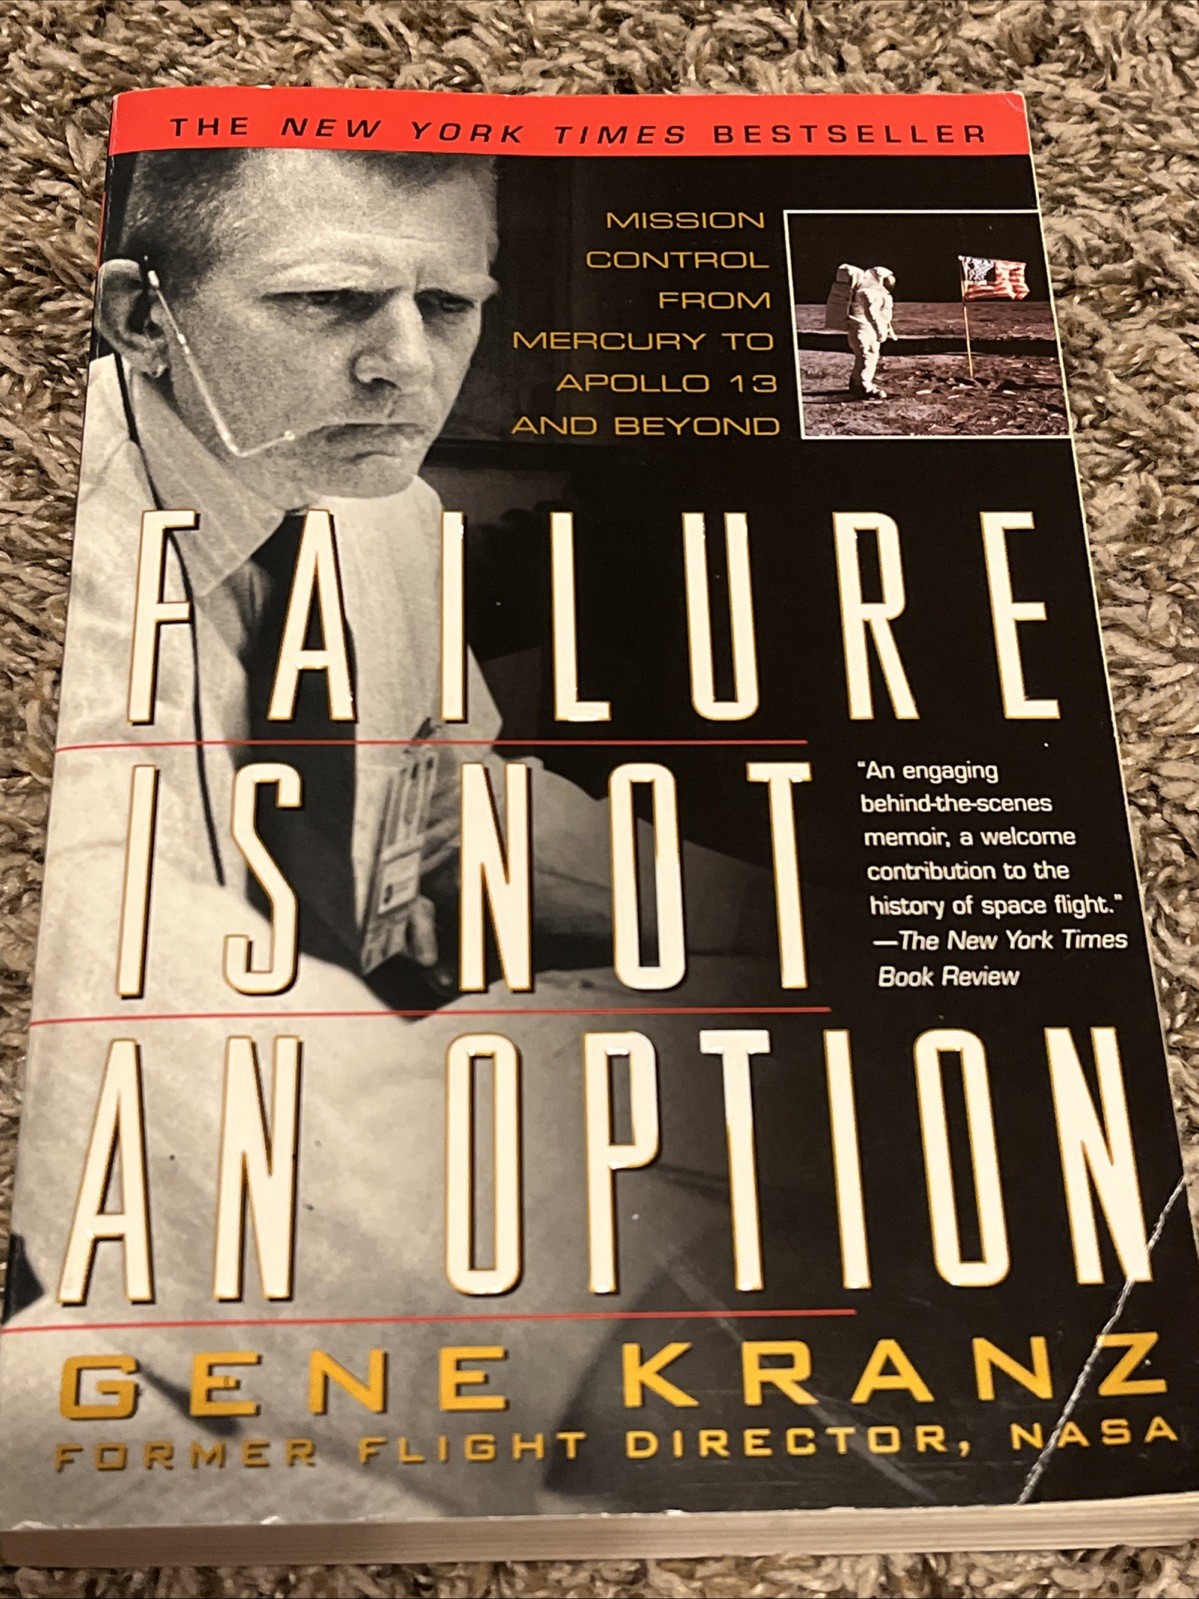
The expression Failure Is Not An Option Nasa originated from the Mercury program, specifically from flight director Chris Kraft, who reportedly used similar language during early training sessions. It became widely publicized later through the Apollo 13 account, but the underlying concept existed long before the film made it pop culture shorthand. In actual engineering terms, it refers to a design philosophy where system redundancy, fault detection, and procedural discipline make single-point failures structurally impossible rather than merely unlikely. Most people treat it as a motivational slogan. That misses the entire mechanism. The concept only works when backed by quantified redundancy margins and documented failure mode analysis. Without those artifacts, you are just chanting words at a system that will fail at the weakest link.
The actual Failure Is Not An Option Nasa methodology
The approach breaks down into a few concrete practices. Fault tree analysis is the foundation. You map every possible failure path for a subsystem, starting from component level and working upward. Each branch gets a probability assignment. Then you identify the combination of failures that produces an unacceptable outcome. After that, you add redundancy or isolating mechanisms until the combined probability drops below your acceptance threshold. That threshold varies by program, but for crewed spacecraft it is typically around 1e-4 per mission hour for any single catastrophic failure mode. Redundancy in this context does not mean stacking identical components and hoping one survives. It means diverse redundancy. If your primary guidance computer runs a particular algorithm, your backup should not run the same algorithm on different hardware. Common mode failures will take out both. I worked on a project where we installed triple-redundant IMU packages running the same calibration routine. Two failed identically within the first week of testing because the calibration code had a latent precision issue that only showed up under thermal cycling. We ended up rewriting the calibration routine with a different numerical approach for the backup path, then the backup held. That is the kind of edge case no textbook covers.
Where the Philosophy Breaks Down
The biggest trap is treating the motto as a cultural mandate rather than an engineering target. When teams interpret "failure is not an option" as "admitting failure is unacceptable," they suppress reporting. I saw this firsthand on a systems integration review where a subcontractor knew their power distribution unit had a marginal solder joint under vibration load. They did not flag it because the program culture rewarded clean test reports. The joint failed during environmental testing three months later, delaying the campaign by six weeks. The real cost was not the repair. It was the schedule slip and the erosion of trust across the team. Another limitation is cost scaling. Achieving the kind of reliability the phrase implies requires exponential investment. Going from 99 percent reliability to 99.999 percent is not a linear cost increase. It is often ten to fifty times more expensive per additional nines. For many commercial applications, that return on investment does not exist. You have to decide whether the mission profile justifies the expenditure or whether a different reliability strategy, like graceful degradation, makes more sense.
Get the Full Details
How to Actually Implement This Mindset
Start with a formal failure modes and effects analysis. Do not skip to redundancy without it. FMEA forces you to enumerate what can go wrong before you design around it. Use a structured severity-occurrence-detection scoring system. The detection score is where most programs cheat. They give high scores to things that are easy to see on a screen and low scores to things that only reveal themselves under specific combinations of conditions. That bias creates blind spots. Next, build your redundancy with diversity in mind. If you duplicate a system, verify that the duplication does not share a common vulnerability. That includes software, firmware, calibration procedures, and even the supply chain for components. I once reviewed a backup power system that used the same battery chemistry and the same manufacturer as the primary. A raw material defect in one shipment affected both. Dual sourcing or alternate chemistry should be part of the redundancy plan from the start, not an afterthought. Operational discipline matters as much as hardware. Checklists, go/no-go decision points, and independent verification steps are the procedural layer that catches what design redundancy misses. The Apollo 13 crew survived because the ground team used checklists and manual override procedures that had been developed during earlier program phases. The hardware alone would not have been enough.
When to Walk Away From the Motto
There are scenarios where pursuing zero failure is the wrong decision. Uncrewed systems with acceptable loss boundaries, prototyping phases where learning velocity matters more than reliability, and cost-constrained programs all fall into this category. In those cases, designing for recoverability or mission tolerance is more practical than designing for impossibility of failure. The alternative is to accept a defined failure rate, build in graceful degradation, and plan for operational response rather than prevention. The phrase itself is useful as a cultural anchor. It sets a standard. But standards without measurable criteria become empty. If your program cannot quantify what failure probability you are targeting, document how you are tracking it, and maintain a culture where finding a flaw is rewarded rather than penalized, you do not have the philosophy. You have a poster on the wall.


