Why You Should Stop Writing Python Scripts Without a Structured Approach
I learned this the hard way. Two years ago, I was debugging a data pipeline that processed roughly 400GB of log files nightly. It worked fine in staging. In production, it silently dropped records every third run because of a timezone edge case I hadn't accounted for. The fix took six hours. Not because the bug was complex, but because there was no systematic way I'd checked the code against my mental model of what could go wrong. I was relying on memory and ad-hoc testing. That approach stopped working when the codebase grew beyond a handful of scripts.
A Field Guide For Python Checklist is just that — a living document you carry through projects, not a product you buy and install. It's a structured set of questions and verification steps you work through before you consider something done. The format matters less than the habit of using it consistently.
What a Field Guide For Python Checklist Actually Is
It's a reference framework. When you start a new Python project, you go through the checklist items before writing any production code. Each item represents a decision point or verification step that beginners commonly skip. The items cover areas like environment setup, dependency management, error handling strategy, logging standards, test coverage targets, deployment configuration, and documentation requirements.
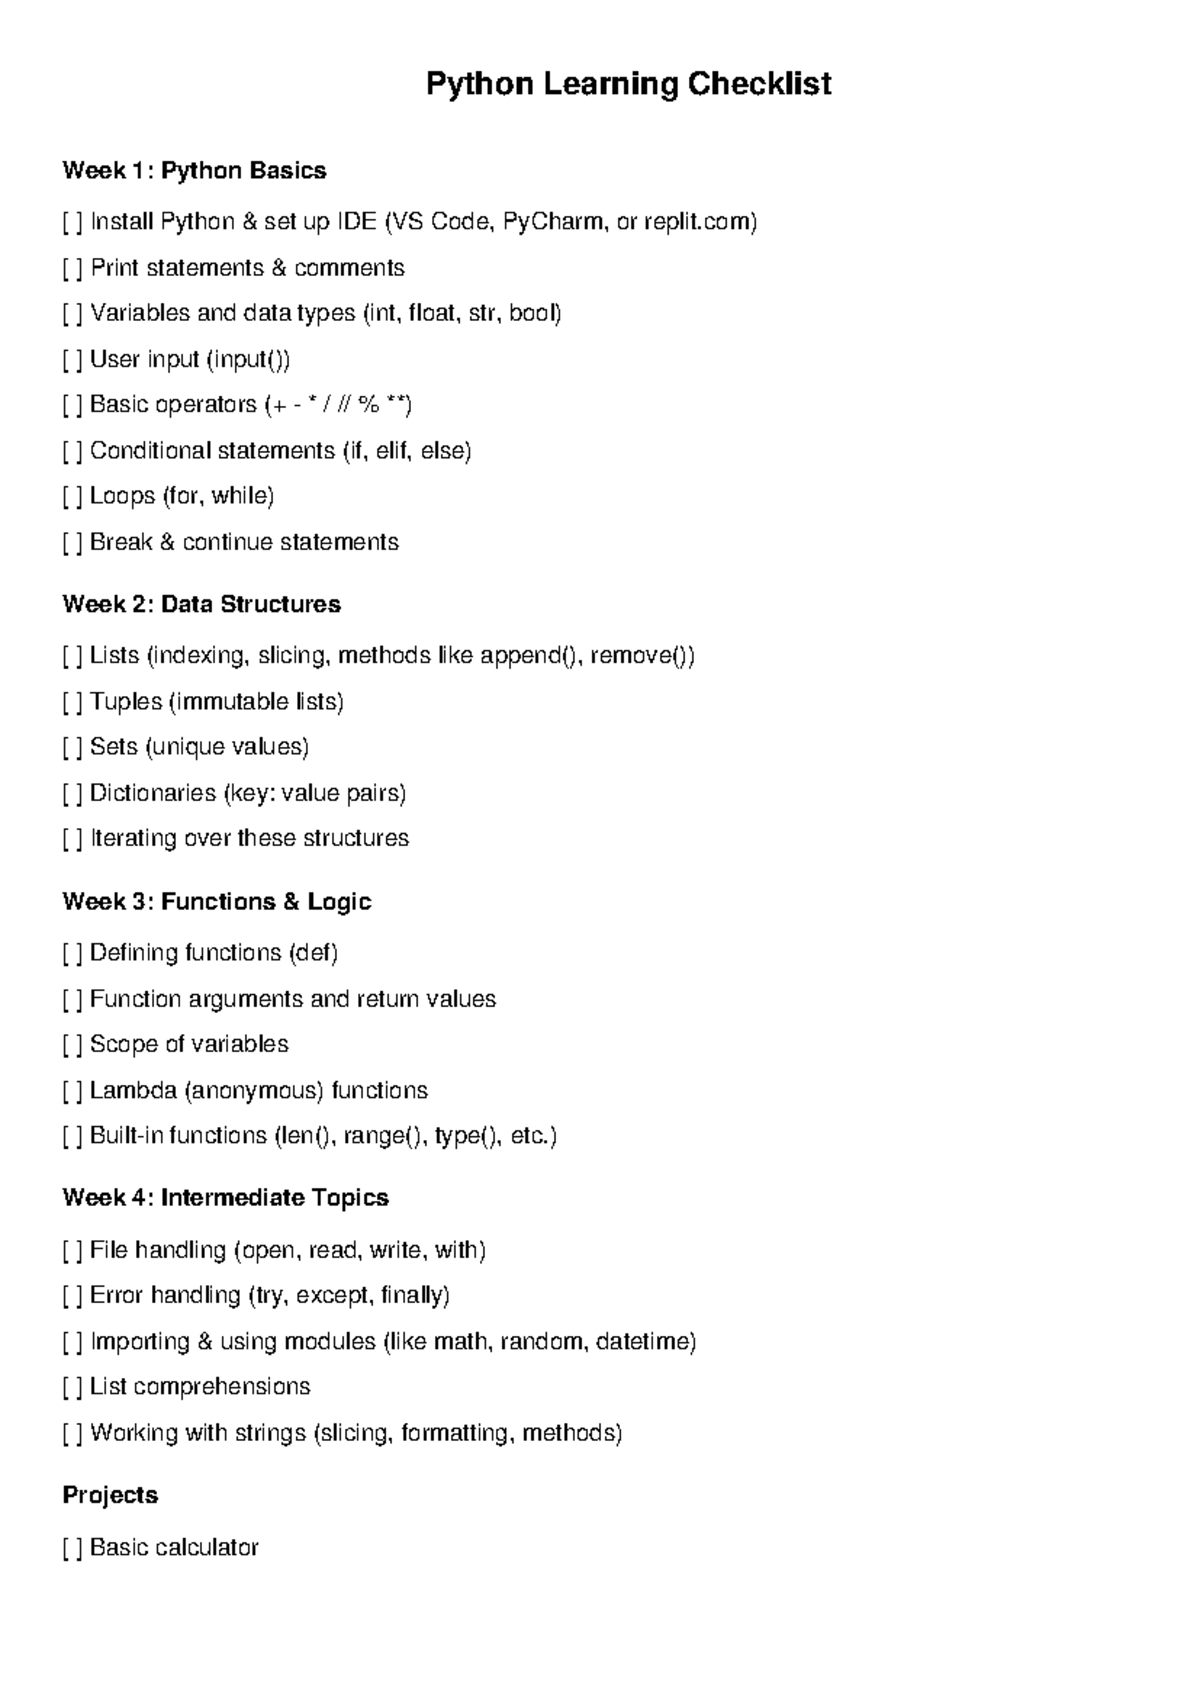
Here's a condensed version you can copy and adapt:
Environment and Setup
- [ ] Python version locked in pyproject.toml or requirements.txt with exact pins for critical packages
- [ ] Virtual environment created with venv or conda, not global installs
- [ ] .python-version or .tool-versions file present for IDE and CI compatibility
- [ ] Local dev server and test database confirmed working before starting features
- [ ] secrets.env or equivalent loaded via python-dotenv, never hardcoded
Dependencies and Packaging
- [ ] All dependencies declared in one place (pyproject.toml preferred)
- [ ] dev and prod dependencies separated
- [ ] requirements.txt generated via pip freeze or pip-compile for reproducibility
- [ ] External API version constraints specified where applicable
- [ ] License file included
Error Handling and Logging
- [ ] Specific exception types caught, not bare except clauses
- [ ] Custom exceptions defined for domain-specific failure modes
- [ ] Log levels assigned consistently (DEBUG for trace data, WARNING for expected issues, ERROR for failures requiring action)
- [ ] Sensitive data excluded from log output
- [ ] Error messages include context (request ID, user ID, timestamps) without exposing credentials
Testing
- [ ] pytest configured with conftest.py fixtures for common setups
- [ ] Unit tests cover pure functions and data transformations
- [ ] Integration tests hit actual services or mocked versions consistently
- [ ] Test coverage tracked with pytest-cov, threshold set at project level
- [ ] Fast tests separated from slow tests with markers
Deployment and Operations
- [ ] Health check endpoint present for long-running services
- [ ] Graceful shutdown handlers registered
- [ ] Configuration externalized from code (use pydantic-settings or environ)
- [ ] Database migrations version-controlled and tested in staging first
- [ ] Rollback strategy documented
Data Handling
- [ ] Input validation with pydantic or equivalent at all boundaries
- [ ] Data types explicitly declared in function signatures where they matter
- [ ] Large datasets processed in chunks, not loaded entirely into memory
- [ ] Encoding (UTF-8) specified for all file I/O operations
How I Actually Use This in Practice
I keep mine as a markdown file in every new project's root directory. The name is just FIELD_GUIDE.md. When I start a sprint, I open it and work through the unchecked items first. If the project doesn't need a database, I skip that section and move on. The point isn't to fill every box — it's to make sure the boxes that apply have been explicitly considered.
One thing most people get wrong: they write the checklist once and never update it. Mine has grown to include project-specific items over time. After a production incident where a missing timeout on an external HTTP call caused the entire worker queue to stall, I added this line to the checklist:
- [ ] All external service calls have explicit timeouts and retry logic
That line has since prevented three more incidents. The checklist works because it accumulates your actual failures, not because it contains generic best practices you already knew.
Common Pitfalls People Miss
Pin vs. range confusion. Most beginners put exact version pins everywhere, which creates maintenance debt. A better approach is pinning direct dependencies exactly but using compatible release ranges for transitive dependencies. Tools like pip-tools (pip-compile) handle this automatically. Without it, you end up with broken builds whenever a sub-dependency releases a breaking change.
Logging format inconsistency. I've seen teams mix print statements, the logging module, and custom handlers across the same codebase. Pick one. Configure it at the application entry point with a dictionary config in logging.config.dictConfig. Everything else inherits from that. Setting this up at project start takes about ten minutes and prevents an entire category of debugging headaches later.
Environment variable naming collisions. When you have multiple developers setting local overrides in their shell profiles, you get silent behavior differences between machines. Use a consistent naming convention and document it in the checklist. The pattern APP_NAME_SERVICE_ACTION works well. Anything shorter becomes ambiguous within a week.
The Parts That Don't Work Well
A checklist like this has real limitations. It doesn't catch logic errors. If your business rule is wrong, checking off every item on the list won't save you. It also creates a false sense of security — developers often stop at the checkboxes and treat them as a completion metric rather than a thinking tool. That's the biggest failure mode I've seen.
It also doesn't scale well to very small scripts. A five-line automation script doesn't need a deployment checklist. You'd be wasting time. The framework works best for anything that runs in production, touches external systems, or involves more than one person maintaining the code.
For data science notebooks specifically, this approach needs adaptation. Notebooks are execution order-dependent and stateful by design. A traditional checklist misses things like kernel restart verification, data leakage in cross-validation, and reproducibility of random seeds. I maintain a separate notebook-specific section that covers those gaps.
Getting Started
Copy the checklist items above into a new file in your project. Don't overthink the format. The first version will be incomplete. That's normal. Add items after each time you encounter a problem that should have been caught earlier. Over six months, you'll have something far more useful than any template you find online because it reflects your actual work patterns and failure modes.
I've updated my version roughly forty times across different projects. The core structure hasn't changed in two years, but the specific items I add after each incident keep it relevant. The value isn't in the initial document. It's in the habit of returning to it after something breaks and asking whether that failure should have been on the list.