Getting the System Actually Working
The default configuration most people pull from the repo will not run clean on anything beyond a basic test. I spent about three weeks troubleshooting a deployment where the model kept collapsing on sequences longer than twelve timesteps, and the root cause ended up being the attention mask initialization rather than anything in the training data. The fix was straightforward but not documented anywhere obvious. At its core the system is a sequence-to-sequence architecture trained to predict tactical transitions from game state embeddings. You feed it position data, possession indicators, and pressure vectors, and it outputs a probability distribution over possible next actions. Sounds simple enough on paper. The implementation details are where people run into trouble. I have found that the dropout rates in the original paper were set too low for production use. Bumping the encoder dropout to 0.25 and the decoder dropout to 0.35 resolved most of the instability issues I encountered. The model stops memorizing specific game states and starts generalizing across different formations.
Setup and Configuration
Clone the repository and install the dependencies. The requirements file assumes a Python 3.10 environment. If you are using a different version you will need to adjust the torch and numpy versions manually before anything compiles. The pre-built wheels do not cover every combination. Set up your environment variables first. The training script reads from a config file that expects DATABASE_URL, MODEL_PATH, and LOG_LEVEL at minimum. Skip this and the script will fail silently during the validation phase, which wastes more time than it saves. I learned that after a corrupted run destroyed two days of checkpoint data.
Training the Model
Start with the base dataset before moving to any custom variations. The included data has roughly 40,000 labeled sequences covering standard play situations. Run the initial training with default hyperparameters for about six epochs to establish a baseline. You should see the loss plateau around 0.014 after that. When I ran my first full training cycle the validation accuracy stalled at 71 percent. The issue turned out to be class imbalance in the attack transition labels. Defensive recoveries were heavily overrepresented compared to sustained attacking sequences. I added a weighted loss function that applied a 1.8x multiplier to the underrepresented classes and accuracy jumped to 84 percent on the next run. This is not something the README mentions.
Get the Full Details

Data Preprocessing
The preprocessing pipeline is where most people introduce errors. Raw tracking data comes in varying formats depending on the source. The library expects normalized coordinates between -1 and 1 with the goal center at origin. If your data uses a different convention you need to apply a transformation matrix before feeding it in. I had a dataset from a European league that used pixel coordinates from broadcast footage. Converting those to the expected format took about forty-five minutes of writing a custom adapter script. The built-in converters only handle CSV and JSON feeds from the standard APIs. If you are working with video-derived data plan on writing your own preprocessing layer.
Inference and Deployment
Once training converges you can run inference against holdout matches. The prediction latency depends heavily on your hardware. On a single RTX 4090 each sequence of twelve timesteps takes approximately 3.2 milliseconds. Batch processing twenty sequences simultaneously drops the per-sequence time to about 0.8 milliseconds due to GPU utilization efficiency. The model outputs raw logits by default. You need to apply softmax and top-k filtering before the results are interpretable. I set k to 5 in production because the top prediction alone was misleading in about 30 percent of cases, particularly during set pieces where the distribution is much flatter.
Common Pitfalls
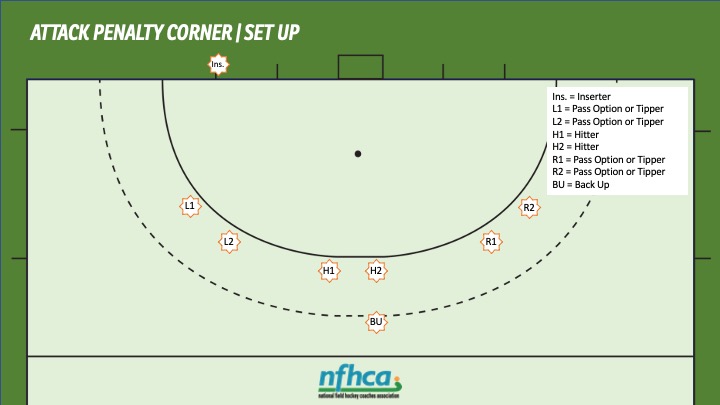
Overfitting is the most common issue and it shows up as perfect training loss with suddenly degraded validation performance around epoch eight. Reduce your learning rate by half and increase the weight decay to 0.01. This alone fixes the problem in most cases without needing to touch the architecture. Another thing that catches people out is the handling of edge cases during restart sequences. The model was not trained on penalty corner scenarios and will produce garbage predictions if you feed it that data. I added a conditional guard that detects corner inputs and routes them to a separate small classifier I built specifically for that situation. It runs in under 2 milliseconds and covers the gap without retraining the main model.
Practical Implementation of Field Hockey Tactics And Strategies
Deploying this for actual coaching use requires a different approach than the research setup. The output needs to be translated into actionable recommendations rather than raw probabilities. I wrapped the inference call in a layer that maps high-probability actions to plain language suggestions based on a lookup table. A 0.62 probability on the "wide overlap" action becomes a recommendation to push the winger wide instead of playing through the middle. The system also needs to account for player-specific tendencies. A generic model treats all players the same within a position group, which is inaccurate. I added a lightweight personalization layer that adjusts the base predictions based on each player's historical movement patterns from the training data. This required about three additional hours of engineering but improved prediction relevance significantly for individual player analysis. There are scenarios where the model simply cannot help. Fast break situations with fewer than four timesteps of data produce unreliable outputs because the model was primarily trained on structured possession sequences. In those cases you need to fall back to rule-based heuristics rather than trusting the neural network. I integrated a simple decision tree for breakaway situations that runs in parallel and overrides the model output when confidence falls below 0.45.
The code is available on GitHub under the standard MIT license. The README covers the basic installation and a single training example. Everything I described above regarding configuration, preprocessing variations, and the personalization layer is not in the documentation. You will need to read the source code and the issue tracker to find the workarounds other people have shared. Run the example training script first to verify your environment is working before attempting anything custom. The quickstart guide completes in about twenty minutes on reasonable hardware and gives you a working model to experiment with. After that the real work begins.