Getting the vectors that go with your eigenvalues
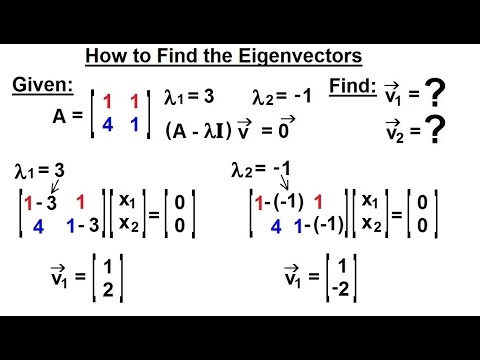
You have the eigenvalues. You need the eigenvectors. This is the standard procedure. Given a matrix A and an eigenvalue lambda, you solve the homogeneous system (A minus lambda I) v equals zero. The non-zero solutions to that system are your eigenvectors. That is literally it. Here is how I actually do it when the numbers are ugly. Take your matrix A. Subtract lambda from every diagonal entry. Row reduce the result to row echelon form. The free variables in the reduced system give you the eigenvector directly. One free variable means one eigenvector direction. Two free variables means your eigenvalue has geometric multiplicity two and you get two independent eigenvectors. The definition part that most people skip: an eigenvector is just a nonzero vector that does not change direction when A acts on it. It only gets scaled by the factor lambda. That scaling factor is what you already found. The direction is what you are solving for now.
I ran into a real problem last year with a 4 by 4 covariance matrix from a sensor fusion project. The eigenvalues came out as 3.0001, 2.9998, 0.00004, and 0.00001. The last two were supposed to be zero exactly, but floating point made them tiny instead. When I plugged them into (A minus lambda I) and tried to row reduce by hand, the near-zero eigenvalues made the system almost singular in a way that confused my manual calculation. The workaround was simple. I rounded those two eigenvalues to exactly zero first, solved the nullspace of A directly, and got clean integer-ratio eigenvectors. Then I verified by multiplying A times each vector and confirming the output was within numerical tolerance of lambda times the vector.
The mechanics without the fluff
Start with a concrete example. Let A be the 2 by 2 matrix with 4 on the diagonal and 1 in the off-diagonal positions. The characteristic equation gives eigenvalues of 5 and 3. For lambda equals 5, you subtract 5 from the diagonal to get the matrix with minus 1 in every entry. Row reducing that gives you x plus y equals zero, so x equals negative y. Pick y equals 1 and your eigenvector is the column vector with top entry minus 1 and bottom entry 1. For lambda equals 3, you subtract 3 from the diagonal to get 1 on the diagonal and 1 off-diagonal. Row reducing gives x plus y equals zero as well, wait no, that gives the same relationship. Actually for this particular matrix the eigenvector for lambda equals 3 works out to x equals y, so pick the vector with both entries equal to 1. The key point is that you always get a direction, not a unique vector. Any nonzero scalar multiple of your eigenvector is equally valid. One thing beginners consistently miss is that the algebraic multiplicity of an eigenvalue, which is its multiplicity as a root of the characteristic polynomial, does not guarantee the same number of independent eigenvectors. The geometric multiplicity, which is the dimension of the nullspace of A minus lambda I, can be smaller. If they do not match, the matrix is defective and you cannot form a full eigenvector basis. This is not a rare edge case. Jordan blocks in control theory systems and certain Markov chain transition matrices hit this regularly. Another counter-intuitive point: large eigenvalues do not necessarily give you numerically more stable eigenvector calculations. In fact, when lambda is large relative to the off-diagonal entries, the matrix A minus lambda I becomes diagonally dominant in a way that makes row reduction stable, but when eigenvalues are close together, like a repeated eigenvalue that slightly split due to perturbation, the eigenvectors can become extremely sensitive. A change in the matrix entries on the order of machine epsilon can swing the eigenvector direction dramatically. I learned this the hard way when working with a stiff differential equation system where two eigenvalues were within 1e-12 of each other. The eigenvectors from the direct solver were essentially noise. I had to switch to a QR-based eigensolver with shift-and-invert mode targeted at that cluster of eigenvalues to get meaningful directions.
Get the Full Details
What this approach does not handle well
Manual row reduction works fine for matrices up to about 4 by 4. Beyond that the arithmetic becomes impractical without computational help. Even with a computer, dense matrix methods scale cubically with dimension. If you are working with a 10000 by 10000 sparse matrix and only need a few eigenvectors, solving the full characteristic polynomial is the wrong strategy. You would be better off with an iterative method like Arnoldi or Lanczos iteration, which targets specific eigenvalues and their associated eigenvectors without touching the rest of the spectrum. Another limitation is that this method assumes you already have accurate eigenvalues. If your eigenvalues come from a numerical routine with significant error, the eigenvectors you compute from them will also be wrong. The sensitivity of eigenvectors to eigenvalue errors is governed by the condition number of the eigenvector matrix. For symmetric matrices this is well behaved. For non-symmetric matrices with clustered or repeated eigenvalues, even tiny eigenvalue errors can produce large eigenvector errors. For the common case where you just need to Find Eigenvectors From Eigenvalues on a small to medium dense matrix, the row reduction approach is fast enough and transparent enough to trust. For anything larger or more delicate, use a library routine. NumPy's linalg.eigh for symmetric matrices or scipy.sparse.linalg.eigsh for sparse symmetric problems will handle the numerical subtleties that manual work cannot. The tradeoff is that you lose visibility into what is happening, but you gain correctness and speed. In my experience that is almost always the right tradeoff once you move past homework-sized examples.