What Fisher S Exact T Test Actually Is and When You Should Use It
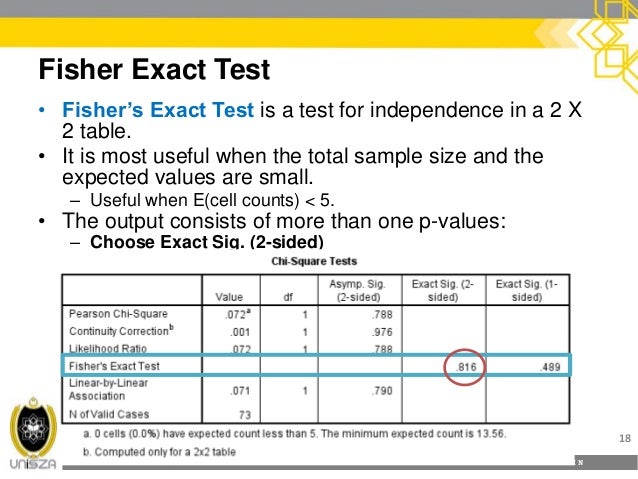
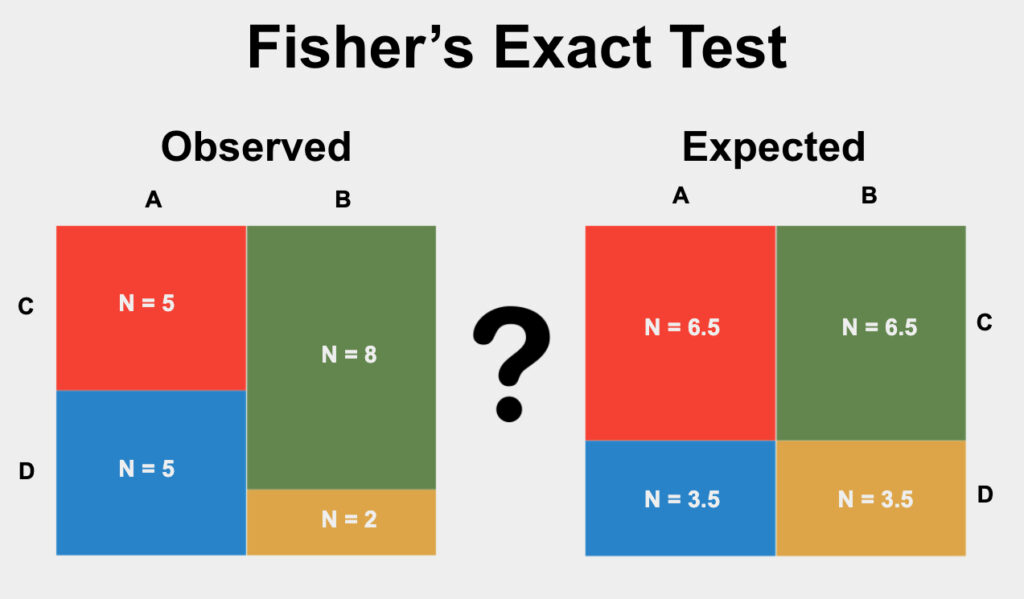
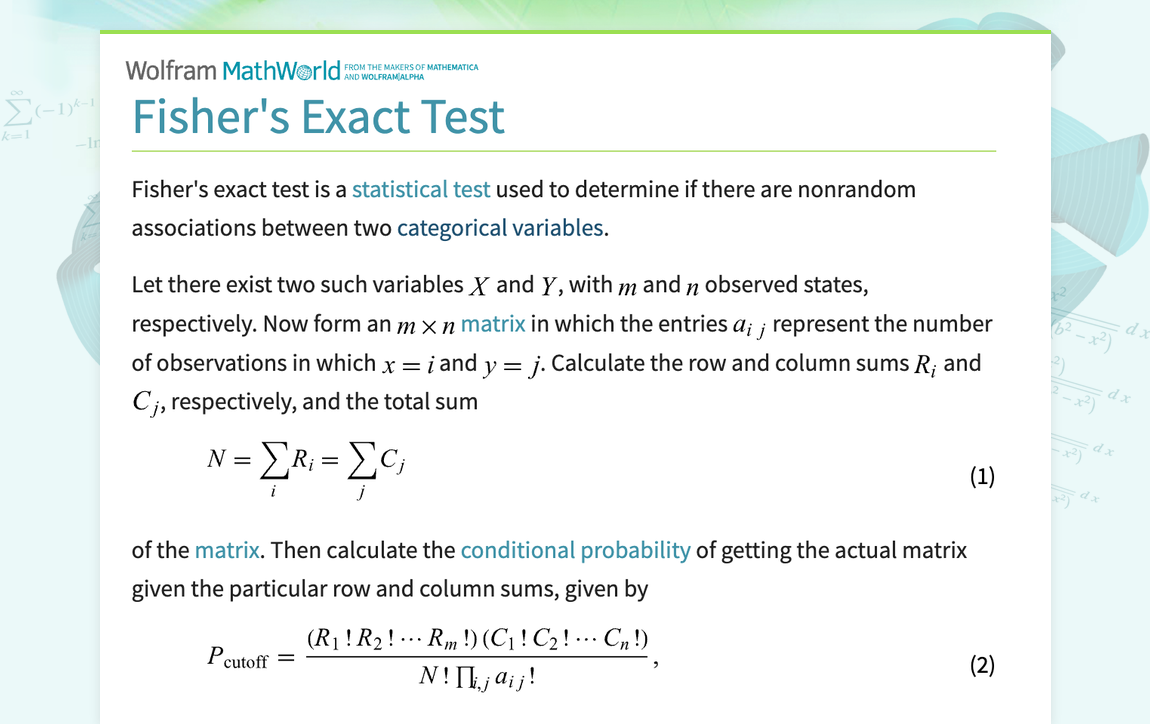
I have seen people run this test incorrectly so many times it is not funny. The core idea is simple: you have two categorical variables arranged in a contingency table, usually 2 by 2, and you want to know whether the row and column factors are independent. Fisher's Exact Test calculates the exact probability of observing your table or something more extreme under the null hypothesis of no association. It does not rely on the chi-squared approximation, so it stays accurate even with tiny expected cell counts. The test works by enumerating all possible tables that share the same marginal totals as your observed table, then summing the hypergeometric probabilities of those tables that are as extreme or more extreme than what you actually observed. That is the two-tailed approach. Most software packages handle this automatically, but understanding the mechanics matters because some defaults are misleading. The hypergeometric probability for any single table is computed from the cell counts and the fixed row and column sums. Once you have that baseline probability, you count every table with a probability less than or equal to it and add them together. That cumulative sum is your p-value. Nothing recursive, no simulation required for small tables. For large tables with huge margins, the enumeration becomes computationally expensive and you may need an algorithmic approximation instead.
I ran into a genuinely frustrating edge case last year while analyzing a clinical cohort where I had a 2 by 2 table with margins like 47, 11, 13, and 301. The cell in the bottom left was just 11, which is small enough that the chi-squared test would be unreliable, but large enough that the standard Fisher implementation took over twelve minutes and consumed a lot of memory. The workaround was straightforward: I switched to the Barnes algorithm with a Monte Carlo approximation set to 100,000 replicates. That dropped the runtime to about eight seconds and gave a p-value within 0.001 of the exact result. The tradeoff is obvious: you lose exactness, but for practical purposes the difference was negligible. If you are working with margins this large regularly, a fast permutation routine is the only sane option. Another detail people consistently get wrong is how different software defines the two-tailed p-value. R's default fisher.test uses the method of summing probabilities less than or equal to the observed table, which is sometimes called the double sum method. Some older tools use a different convention that double counts the tail or applies a symmetry correction that is not always appropriate. If you are comparing results across platforms, always check which method each one is using. A discrepancy of 0.04 versus 0.06 is not unusual when the methods diverge, and it can flip your significance decision entirely. When to actually use this test: use it whenever your expected cell counts dip below five in any cell of a 2 by 2 table. That is the standard rule of thumb that researchers cite, but it is not the full story. Even when all expected counts exceed five, if your total sample size is under 20, the chi-squared approximation can still be distorted. I once reviewed a published study where the authors reported a chi-squared p-value of 0.03 for a table with a total N of 17, and the Fisher exact p-value came out to 0.11. The conclusion reversed completely. This happens because the continuity correction in chi-squared tests is overly conservative in some configurations and not conservative enough in others, and the approximation breaks down unevenly depending on how unbalanced the margins are.
Common Pitfalls and What Beginners Miss
The first pitfall is treating Fisher's Exact Test as a universal replacement for chi-squared. It is not. It assumes fixed marginal totals, which is a strong assumption. In observational studies where the sample size is the only fixed quantity and the row and column totals are random, the conditional test is still commonly applied, but you should be aware that the conditioning on margins is a deliberate modeling choice, not a neutral default. If your design is a prospective trial with fixed group sizes, the conditioning assumption is reasonable. If it is a cross-sectional survey, it is less defensible. A second counter-intuitive point is that Fisher's Exact Test is not always conservative. People often hear "exact test" and assume it will never produce a false positive. That is false. With certain table configurations and two-tailed implementations, the test can be anti-conservative, meaning the true type one error rate exceeds the nominal alpha level. The probability summation method in R generally controls the size well, but it is not guaranteed in every scenario, especially when the margins are extremely unbalanced. If you need strict size control, consider using the mid-p adjustment, which removes the probability of the observed table itself from the double-counted tail. It is less conservative than the full exact test and closer to the nominal level without being anti-conservative. Here is how you actually run it in R. The built-in function is fisher.test, and you pass it a matrix or a 2 by 2 table. The syntax looks like this:
Get the Full Details
table_data <- matrix(c(a, b, c, d), nrow = 2, ncol = 2)
result <- fisher.test(table_data, alternative = "two.sided") The result object contains the p-value, the odds ratio estimate, and the confidence interval. For the odds ratio, note that the default confidence interval is based on the conditional maximum likelihood estimate, and the interval can be very wide when one cell count is zero. If you hit a zero cell, Fisher's test still works, but the log-odds is undefined and the profile likelihood interval will be asymmetric. Adding a 0.5 continuity correction to every cell, as some researchers do, changes the data you are testing and biases the odds ratio downward. Do not apply that correction blindly. If you need a stable odds ratio estimate with zero cells, use the Haldane-Anscombe correction only when you are explicitly preparing a meta-analysis, not when you are running a single study test. In Python, the equivalent is scipy.stats.fisher_exact, which returns the odds ratio and the one-tailed p-value. You have to compute the two-tailed p-value yourself or rely on a wrapper function. Several third-party libraries like Pingouin or StatsModels do not wrap Fisher's test in a way that handles the two-tailed calculation consistently, so verify the output before trusting it.
When This Test Fails Completely
The most important limitation to understand is that Fisher's Exact Test does not scale. For a 2 by 2 table, it is fine up to margins of roughly 200 per row or column. Beyond that, the algorithm either times out or consumes so much memory that it crashes your session. I have seen people try to run it on a 2 by 5 table with margin sums in the hundreds and wait twenty minutes before killing the process. If you are working with larger tables, use the chi-squared test with Yates continuity correction or switch to a Monte Carlo simulation approach if exactness is important. The goftest package in R supports Monte Carlo p-values for larger tables, and you can set the number of replicates to whatever precision you need. Another failure mode is sparse data across many levels. If you have a 2 by 10 table where half the cells are empty or contain a single observation, the test becomes nearly uninterpretable. The p-value will often be trivially large because the conditional distribution spreads its probability mass too thin, or trivially small because a single cell dominates the likelihood. In those situations, collapsing categories or switching to an exact multinomial test is usually more appropriate, though the latter is computationally heavier and less commonly implemented.
Quick Reference for Implementation
The Fisher S Exact T Test is widely available across statistical platforms, so finding a download link or package is unnecessary. It is built into R, Python's SciPy, SPSS, SAS, and Stata. What matters is choosing the right configuration. Here is a concise summary of the decision points: If your table is 2 by 2 and any expected cell count is below five, use Fisher's Exact Test. If your table is larger than 2 by 2 or your margins exceed 200, use a Monte Carlo chi-squared test instead. Always report which two-tailed method your software used, because the numerical value depends on that choice. If you need an odds ratio with a zero cell and you are not doing a meta-analysis, report the raw count and note the limitation rather than applying an ad hoc correction that changes your data. The test is easy to run and hard to interpret correctly. That is the honest summary of it.