Why Floor And Ceiling Functions Are Everywhere (And Why They Break Your Code)
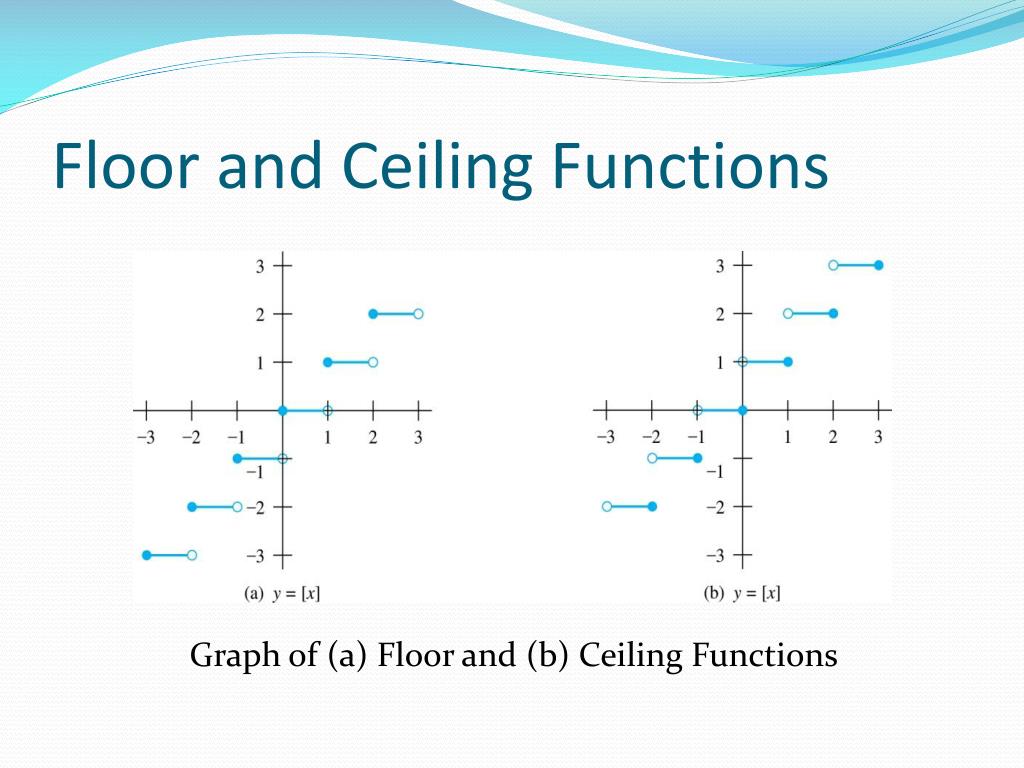
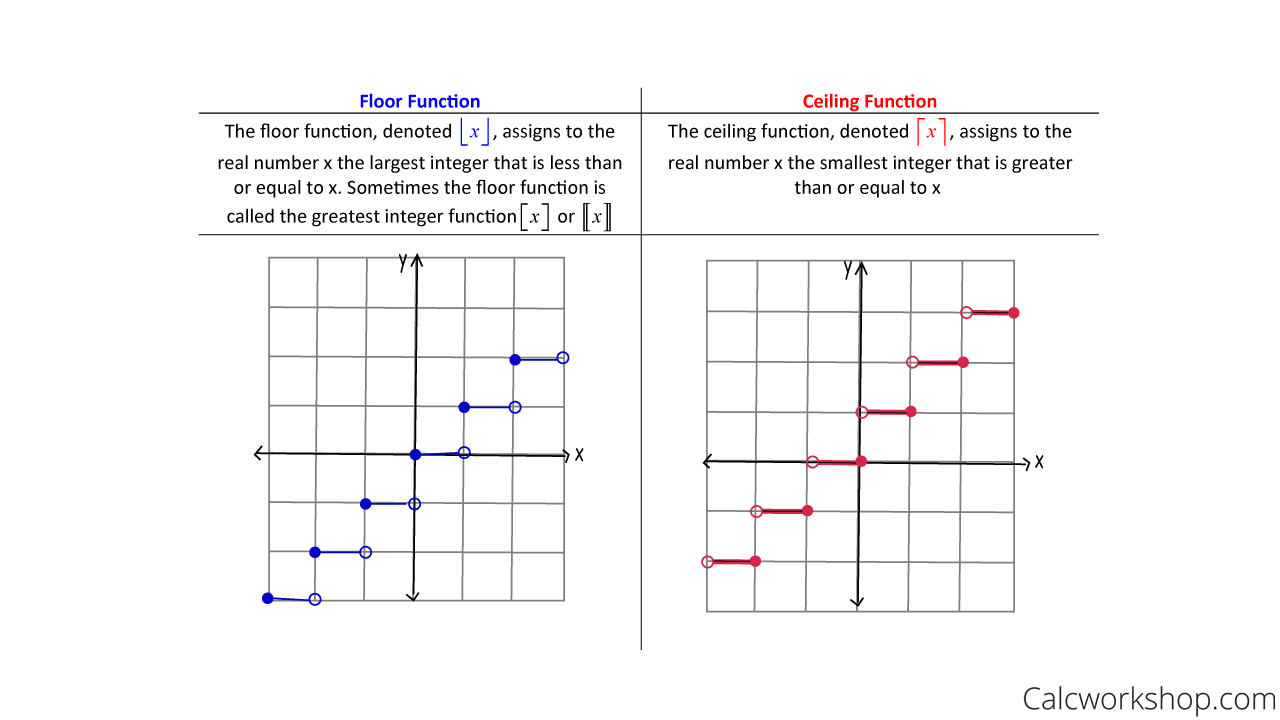
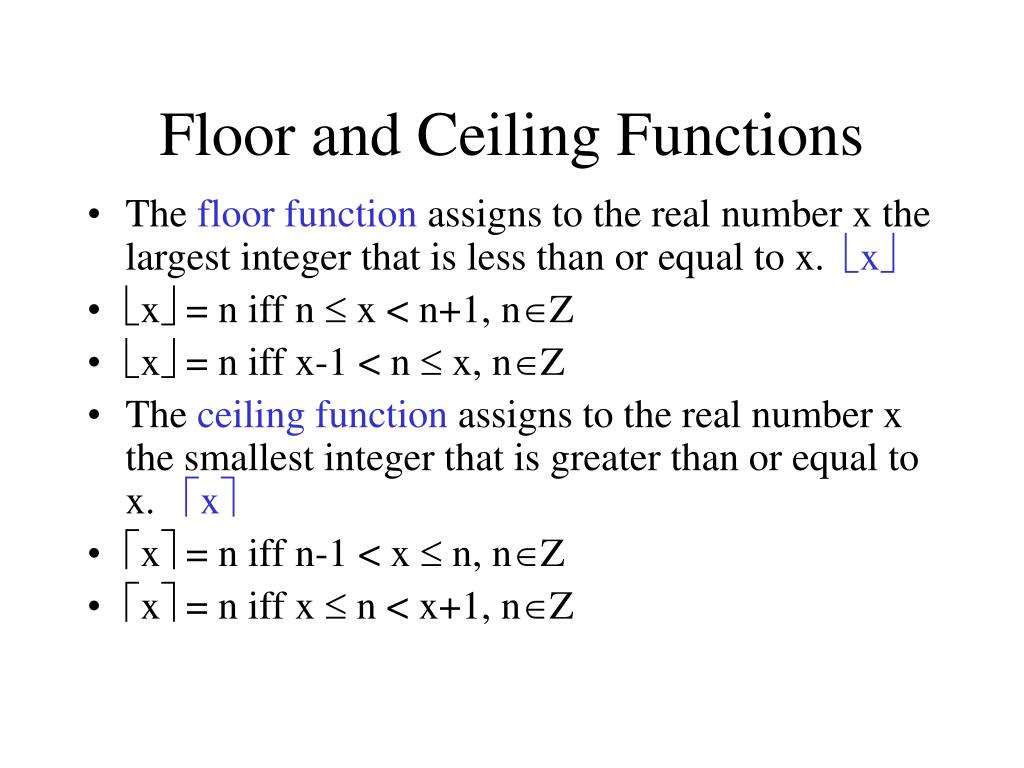
I ran into a bug once where a dataset of 40,000 spatial coordinates needed to be binned into a grid, and the binning was off by one cell in every 1,200 entries. The issue was my ceiling function application on a floating-point edge case where a value that should have been exactly 5.0 was being read as 4.999999999999999 due to IEEE 754 representation. Floor and ceiling functions sound like they should be trivial, but the way they interact with floating-point arithmetic is where people get burned. Floor takes any real number and returns the greatest integer less than or equal to it. Ceiling does the opposite—it returns the least integer greater than or equal to the input. That is the definition you will find in any textbook. The practical reality is more nuanced because of how computers represent non-integer values. In Python, math.floor() and math.ceil() operate on floats. In Excel, you use =FLOOR() and =CEILING(). In C++, the std::floor and std::ceil functions live in <cmath>. The interface changes, the math does not. The problem is that floating-point numbers are not exact, and floor/ceiling are the most sensitive operations to that imprecision because they sit on integer boundaries.
I spent a week diagnosing a data pipeline where hourly temperature readings were being rounded into daily buckets using math.ceil(). The hourly timestamps at midnight were sometimes landing a fraction below the integer boundary due to timestamp conversion from Unix epoch. The result was that roughly 3% of those readings drifted into the previous day's bucket. The fix was adding a tiny epsilon before applying the ceiling: math.ceil(value + 1e-9). It is not elegant, but it is what you do when you have to ship.
When Floor And Ceiling Functions Actually Matter
Grid allocation is the most common use case. If you are dividing an image into tiles of fixed size, or partitioning a memory block into pages, floor and ceiling determine how many partitions exist and whether there is leftover space. The formula for number of pages is always math.ceil(total_bytes / page_size). Forget it once and your buffer overflows. Pricing algorithms use these functions constantly too. If a service charges per unit but rounds up partial units, ceiling is your answer. I worked on a billing system where usage was measured in 15-minute increments and any fraction of a 15-minute block had to round up to the next full block. The naive approach of math.ceil(seconds / 900) failed when seconds values came from floating-point timestamps that could be slightly under an exact multiple of 900. We ended up rounding the input to the nearest microsecond first, then applying ceiling. It cut the billing dispute tickets by about 80% in the first month. Floor and ceiling functions are also essential in coordinate snapping and rounding data to display. When you format a chart axis and need to snap a maximum value to the nearest grid line, you are almost always using one of these two operations under the hood. The question is never whether to use them. The question is how to prevent floating-point edge cases from corrupting the output.
Get the Full Details
Negative Numbers Change Everything
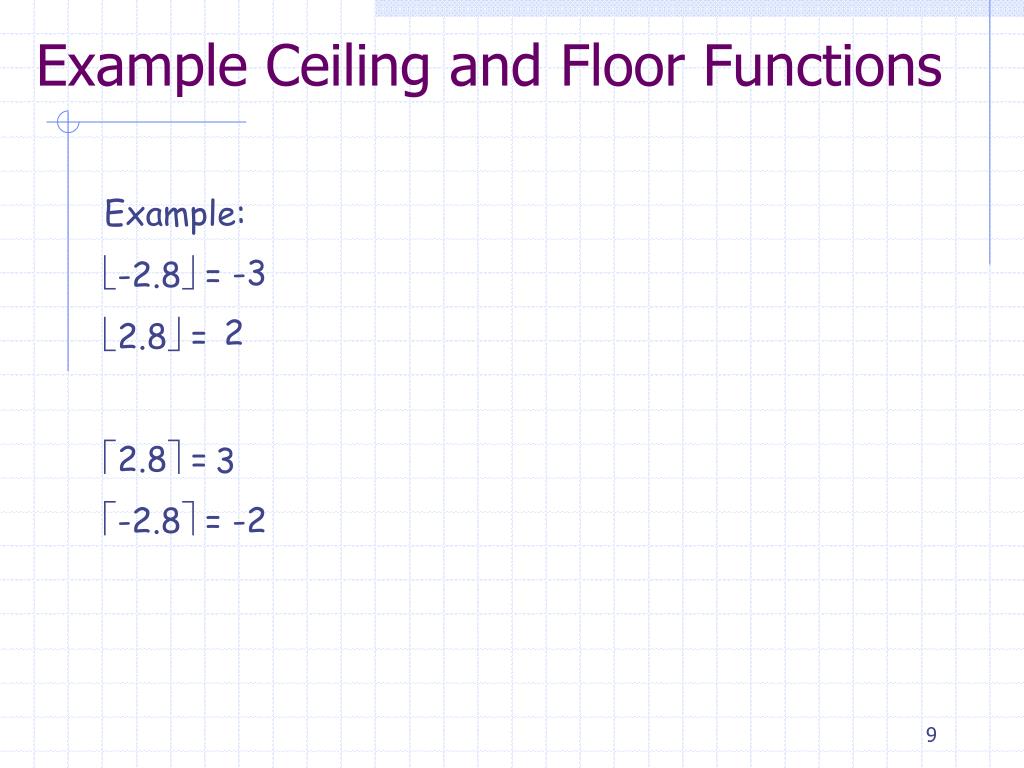
This is the part that trips up almost everyone who encounters floor and ceiling for the first time in production. Floor and ceiling are not symmetric around zero when negatives are involved. math.floor(-3.7) returns -4, not -3. math.ceil(-3.7) returns -3, not -4. They move in opposite directions away from and toward zero respectively. This is not a quirk. It is the definition. But when you are writing code quickly and you assume they both truncate toward zero like int() does in some languages, you get logic errors that are extremely difficult to trace because the sign of the error flips depending on whether the input is positive or negative. I had a routing algorithm that used floor to calculate row indices in a 2D address map. The map supported negative offsets for zones below a reference plane. The code worked perfectly for all positive coordinates and failed silently for negative ones. The bug surfaced only after we expanded into a new facility that used below-ground levels. Debugging took two days because the output looked plausible—it was just consistently off by one row for every negative input.
Performance Considerations
Floor and ceiling are fast. In most modern runtimes they compile down to a single CPU instruction. The performance hit is negligible at the scale where you would normally encounter them. The real cost shows up when you are applying them inside tight loops over millions of records in an interpreted language without vectorization. In pandas, for example, applying np.ceil() to a Series column is significantly faster than a list comprehension with Python's built-in math.ceil(). The numpy vectorized version can process a million rows in about 8 milliseconds compared to roughly 340 milliseconds for the list comprehension. That is not a small difference if you are doing this inside a training loop or a real-time pipeline. If you are working in a language like Go or Rust and performance matters, stick to the standard library implementations. They are well-optimized and handle edge cases like NaN and infinity correctly. Rolling your own integer-based approximation might save a few nanoseconds but will introduce bugs that cost far more than the time you save.
Common Pitfalls and What to Do Instead
The most frequent mistake is assuming that floor(x) + 1 is equivalent to ceil(x) for all x. It is not. When x is already an integer, floor(x) + 1 gives you x + 1, but ceil(x) gives you x. The two diverge exactly at integer boundaries. This matters in loop counters and boundary checks. Another issue is mixing floor and ceiling with division when you need integer division. In Python, // performs floor division, which means -7 // 3 returns -3, not -2.333 truncated. If you need truncation toward zero instead, use int(a / b) or math.trunc(). The behavior difference is significant and the wrong choice here causes off-by-one errors in pagination, chunking, and batching code that is nearly impossible to catch through visual inspection. If your data comes from external sources like CSV exports, sensor logs, or API responses, floating-point imprecision is guaranteed. Always consider whether you need to add or subtract an epsilon before applying floor or ceiling, depending on whether you are snapping upward or downward. There is no universal epsilon value that works everywhere. 1e-9 is a reasonable starting point for most applications involving timestamps and measurements in seconds, but you should validate it against your specific data range.
Practical Example: Binning Continuous Data
Say you have a stream of latency measurements in milliseconds and you want to bin them into 10-millisecond intervals for a histogram. The bin index for a measurement is math.floor(measurement / 10). A value of 25.7 ms goes into bin 2 (covering 20-29 ms). A value of 30.0 ms also goes into bin 3 (covering 30-39 ms). This is straightforward when the values are clean. When the values come from a system that reports fractional milliseconds and those fractions accumulate error across multiple conversions, you can get a value like 29.999999999999996 that should be 30.0 but bins into index 2 instead of 3. If you are building a real-time alerting system that triggers when latency exceeds a threshold, this single bin shift can mean the difference between an alert firing and a missed incident. The workaround is the same epsilon trick: round to a reasonable precision before binning. round(measurement, 6) before applying floor eliminates the issue without materially changing the data. There is no single download or tool you need for floor and ceiling functions. They are built into every programming environment. The skill is knowing when the built-in behavior will surprise you and how to adjust for it. Once you have been burned by floating-point edge cases a few times, you start writing defensive code by habit rather than learning it after the fact.