What Actually Happens When You Try to Enter Data Science
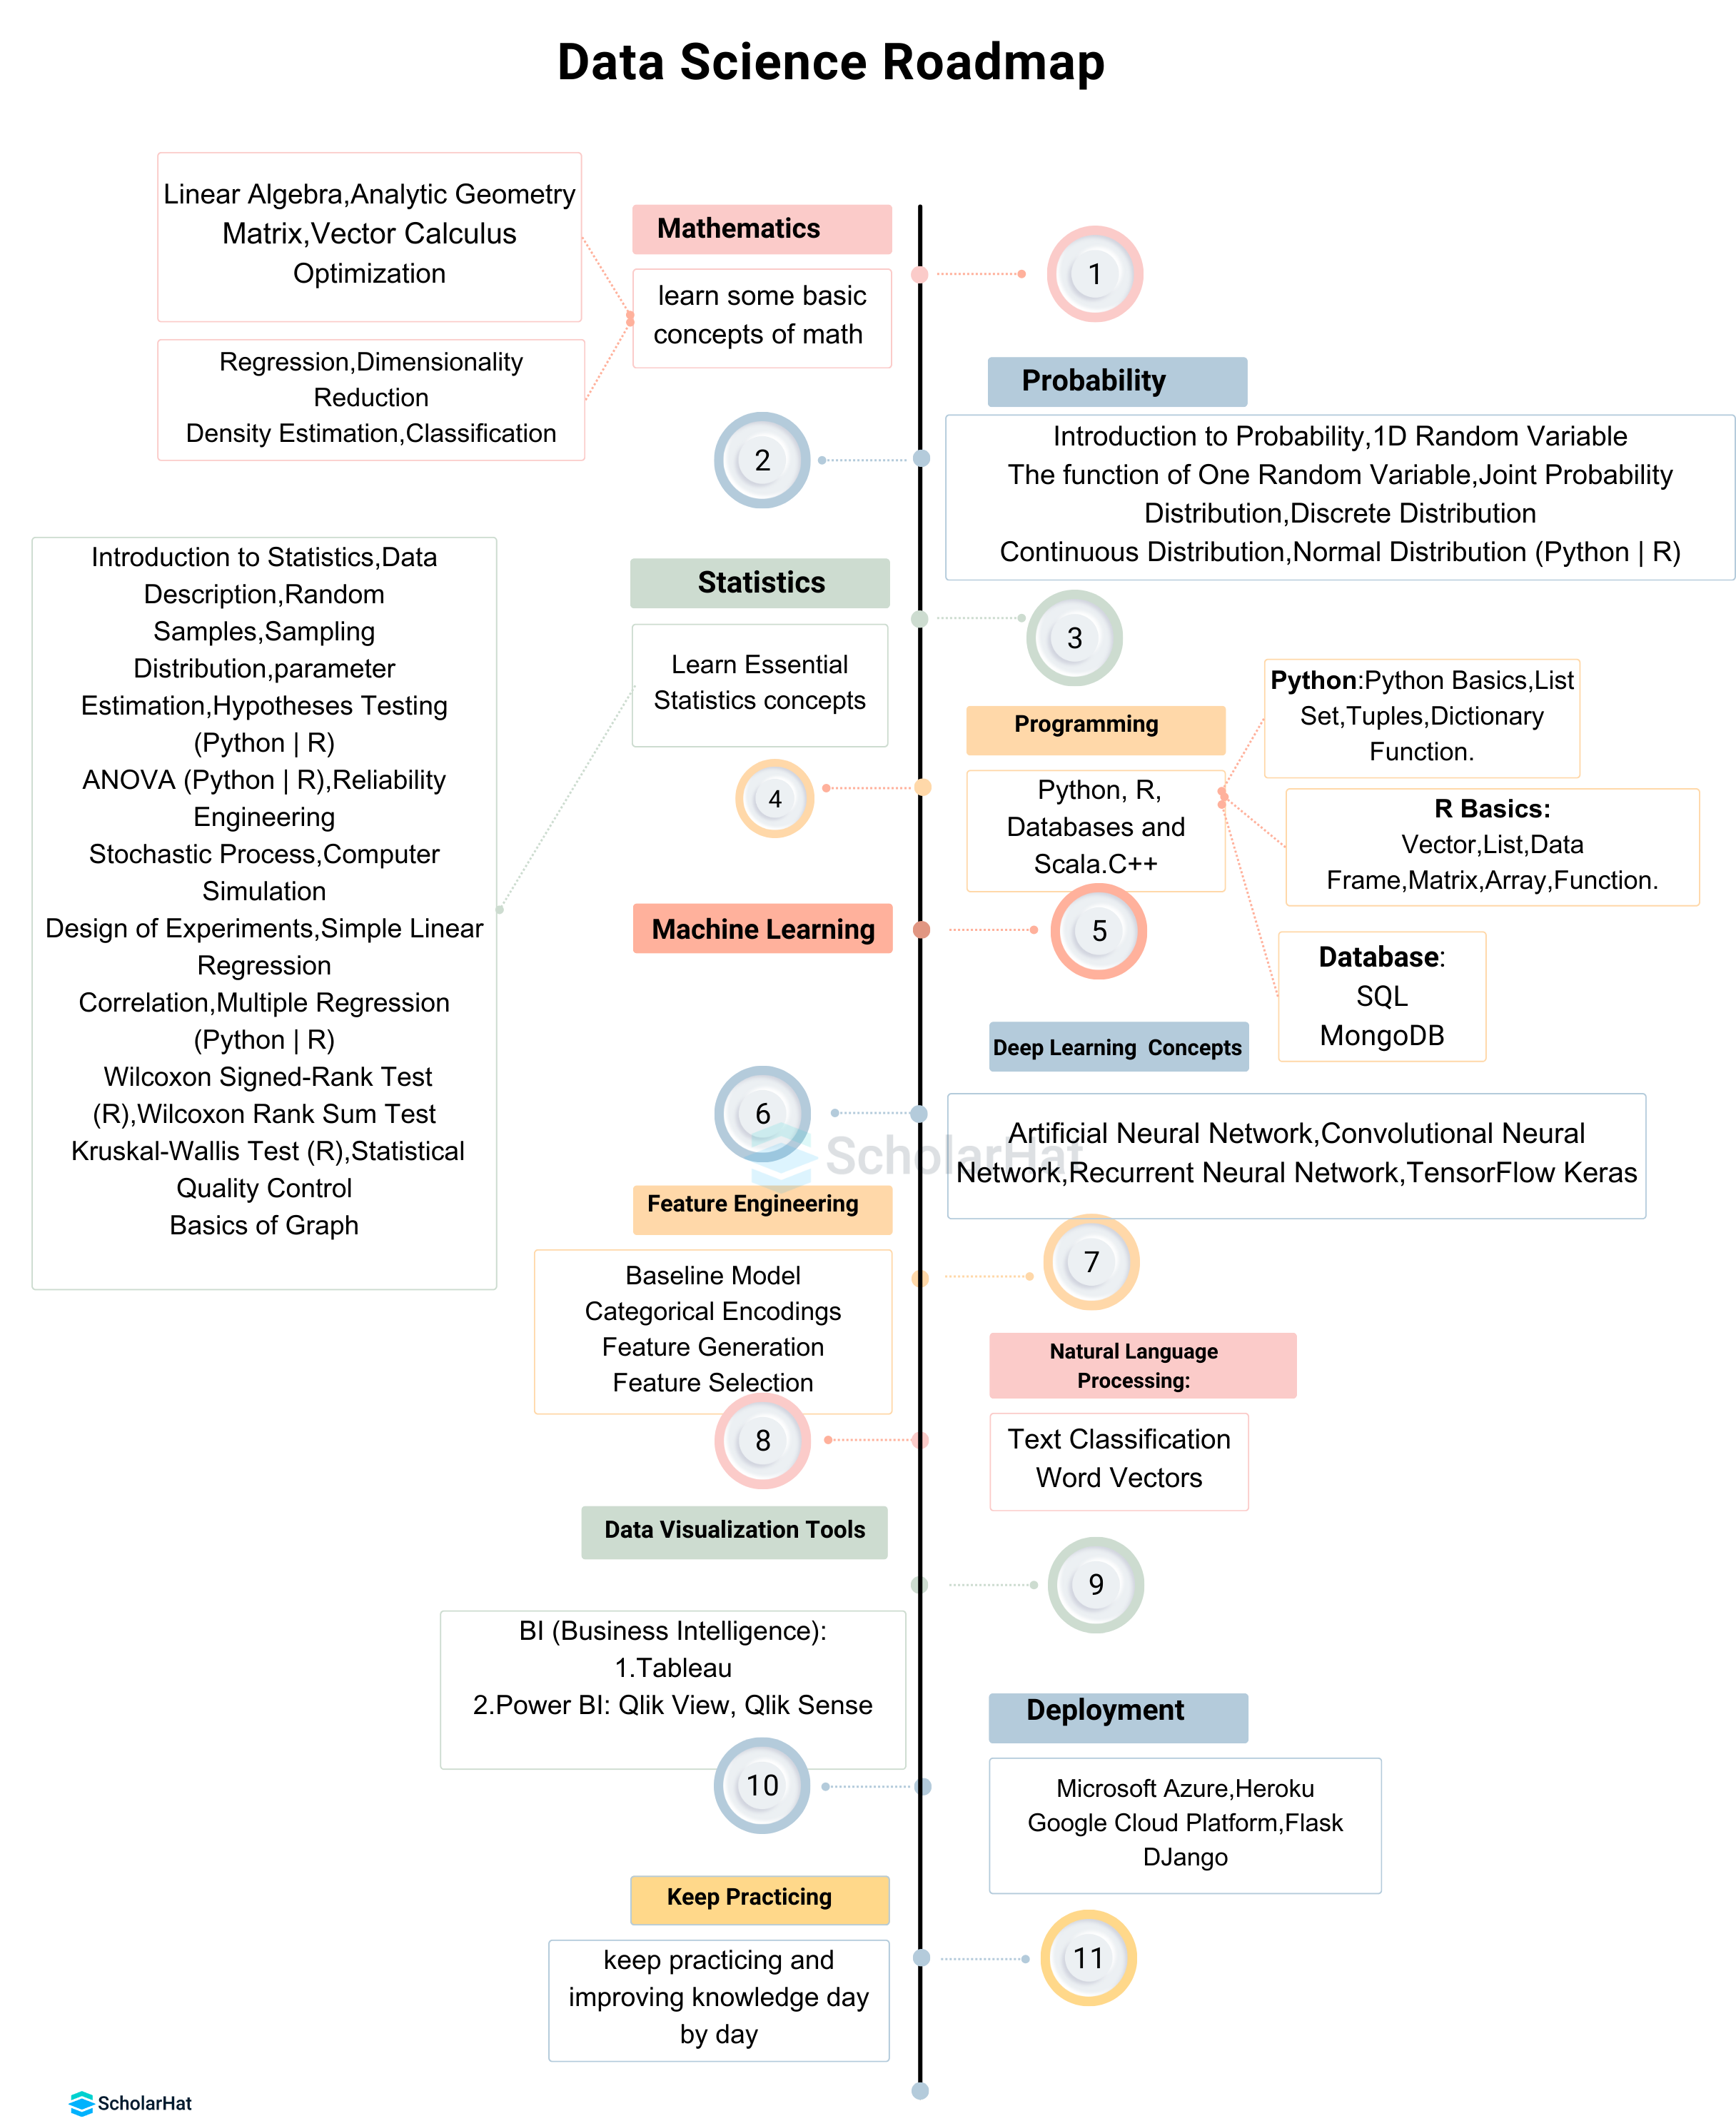
I spent three years building a career path for data science, and the honest answer is that most roadmaps are garbage. They look nice on paper — Python first, then statistics, then machine learning, maybe a dash of SQL — but they fall apart the moment you try to follow them. The problem isn't the order. It's that nobody tells you what you'll actually be doing on day one, and nobody mentions that you'll probably spend more time cleaning data than modeling anything. Here's what I learned the hard way: a For Data Science Roadmap isn't about checking boxes. It's about surviving your first six months without burning out. The roadmap below isn't theoretical. It's based on watching people succeed and fail, sometimes in the same company.
The Foundation Phase (Months 1-3)
You need Python before anything else. Not because Python is magic, but because it's the language every team already uses. I've seen people waste four months trying to learn R first. It's not wrong, but you're fighting uphill against every job posting. Learn these libraries in order: pandas, numpy, matplotlib. Don't skip matplotlib. Learning seaborn first gives you pretty charts but makes you helpless when something goes wrong. You'll thank me later when you need to customize a plot at 2 AM before a stakeholder meeting. Statistics comes next, but only the parts you'll actually use. Mean, median, standard deviation, distributions, hypothesis testing, confidence intervals. Skip the proofs. You're not applying to a research position. I failed my first technical interview because I could derive Bayes' theorem by hand but couldn't explain p-values to a product manager.
The Applied Phase (Months 4-6)
This is where most people quit. You start touching real datasets and everything breaks. Missing values. Inconsistent formats. Columns named things like "user_id_v2_final" because three different people modified the schema. This is normal. This is the job. SQL becomes essential here. Not the easy kind — the JOIN-heavy, subquery, window-function kind. You'll be writing queries that touch multiple tables because no one built the dashboard you need. I once spent two weeks debugging a metric only to discover the data engineer had joined on the wrong column. It happened to match by coincidence for our test period. Machine learning starts with scikit-learn. Linear regression, logistic regression, decision trees, random forests. That's it for now. Don't jump to neural networks. You don't understand the fundamentals yet, and deep learning will just confuse you. I watched a junior analyst spend three months trying to build a transformer model for a classification task that a random forest solved better in five minutes.
Get the Full Details

The Realization Phase (Months 7-12)
You'll discover that the work is 80% data engineering and 20% modeling. This isn't a bug. It's the reality. Every dataset you touch will need cleaning, transformation, validation. The models are the easy part. Deployment basics matter now. Learn how to save a model with pickle or joblib. Understand what a REST API is. Deploy something, even if it's just a Flask app on your local machine. The gap between "I built a model" and "the model is used in production" is where careers get made or stalled. Portfolio projects need to reflect this reality. Don't build another iris classification demo. Build something messy. A scraper that pulls data from a broken website. A pipeline that handles missing data gracefully. A model that explains why it made its predictions. These are the projects that get you hired.
The Skills That Actually Matter
Communication. This sounds cliché until you realize that the best model in the world is useless if you can't explain why the business should care. I've seen data scientists promoted past people with better technical skills because they could translate analysis into decisions. Version control. Git isn't optional. You'll break things. You'll need to undo changes. Your team will need to collaborate. Learning git early saves you from hours of frustration later. I still remember the panic of losing two days of work because I didn't commit. Domain knowledge. The industry you work in matters more than the tools you use. Healthcare data has different problems than e-commerce. Finance has compliance requirements. Retail has seasonality. Pick a domain and learn its vocabulary. It compounds over time.
A Problem I Haven't Seen Covered Anywhere
Here's something nobody talks about: your first real dataset will likely be smaller than you expect. Everyone assumes data science means massive datasets and big infrastructure. In practice, you'll often work with files under 100MB on a laptop. The challenge isn't scale. It's signal. Finding something meaningful in noise with limited resources requires a different mindset than what the bootcamp tutorials teach you. My workaround was simple but changed everything: I started treating small datasets as a feature, not a limitation. I could iterate faster. I could visualize every observation. I could spot anomalies by eye. The large-scale problems can wait. Learning to extract value from limited data is a rarer skill than handling big data.

When This Roadmap Won't Work
If you're aiming for a research role at a lab, this path falls short. You'll need mathematics, publications, and likely a graduate degree. If you want to build large-scale data infrastructure, focus on engineering instead. This roadmap is for someone who wants to analyze data and build predictive models within a business context. Also, timelines are optimistic. Three months for the foundation phase assumes you can study full-time. Most people are working while learning. Extend everything by 50%. The material doesn't get easier, but you'll get more efficient at learning it. Finally, the field moves fast. What's relevant today might shift in two years. The underlying principles — statistics, programming, domain understanding — stay constant. Focus on those. The tools are disposable.
Where to Find Resources
FreeCodeCamp has solid Python courses. Kaggle offers hands-on micro-courses that are better than most paid content. For SQL, Mode Analytics has a free tutorial that covers the practical stuff. StatQuest on YouTube makes statistics understandable without dumbing it down. For the For Data Science Roadmap, I've compiled the progression above into a structured learning path with specific milestones, resource links, and project ideas at each stage. The goal isn't to cover everything. It's to give you enough direction that you're not guessing what to learn next. The hardest part isn't the technical content. It's staying consistent when progress feels slow. You'll hit plateaus. You'll forget what you learned last week. This is normal. Keep going. The people who succeed aren't the smartest. They're the ones who didn't stop.