What Actually Makes a Data Science Project Simple
Simple data science isn't about dumbing things down. It's about removing every unnecessary step between the question and the answer. I've watched teams spend three weeks building a pipeline for a classification task that a two-hour pandas script could have solved. The cost isn't just time. It's the fragility of those systems. When something breaks in production, someone at 2 AM is debugging a custom wrapper around a thing that already exists. The real barrier to simple data science is usually not technical. It's institutional. People build complex solutions because they think complexity signals rigor. A 500-line script feels more impressive than a 50-line one, even when the 50-line version does the same job and can actually be maintained. This is especially true in consulting environments where deliverables are measured by artifacts, not outcomes.
For Data Science Simple, Start With the Answer, Not the Architecture
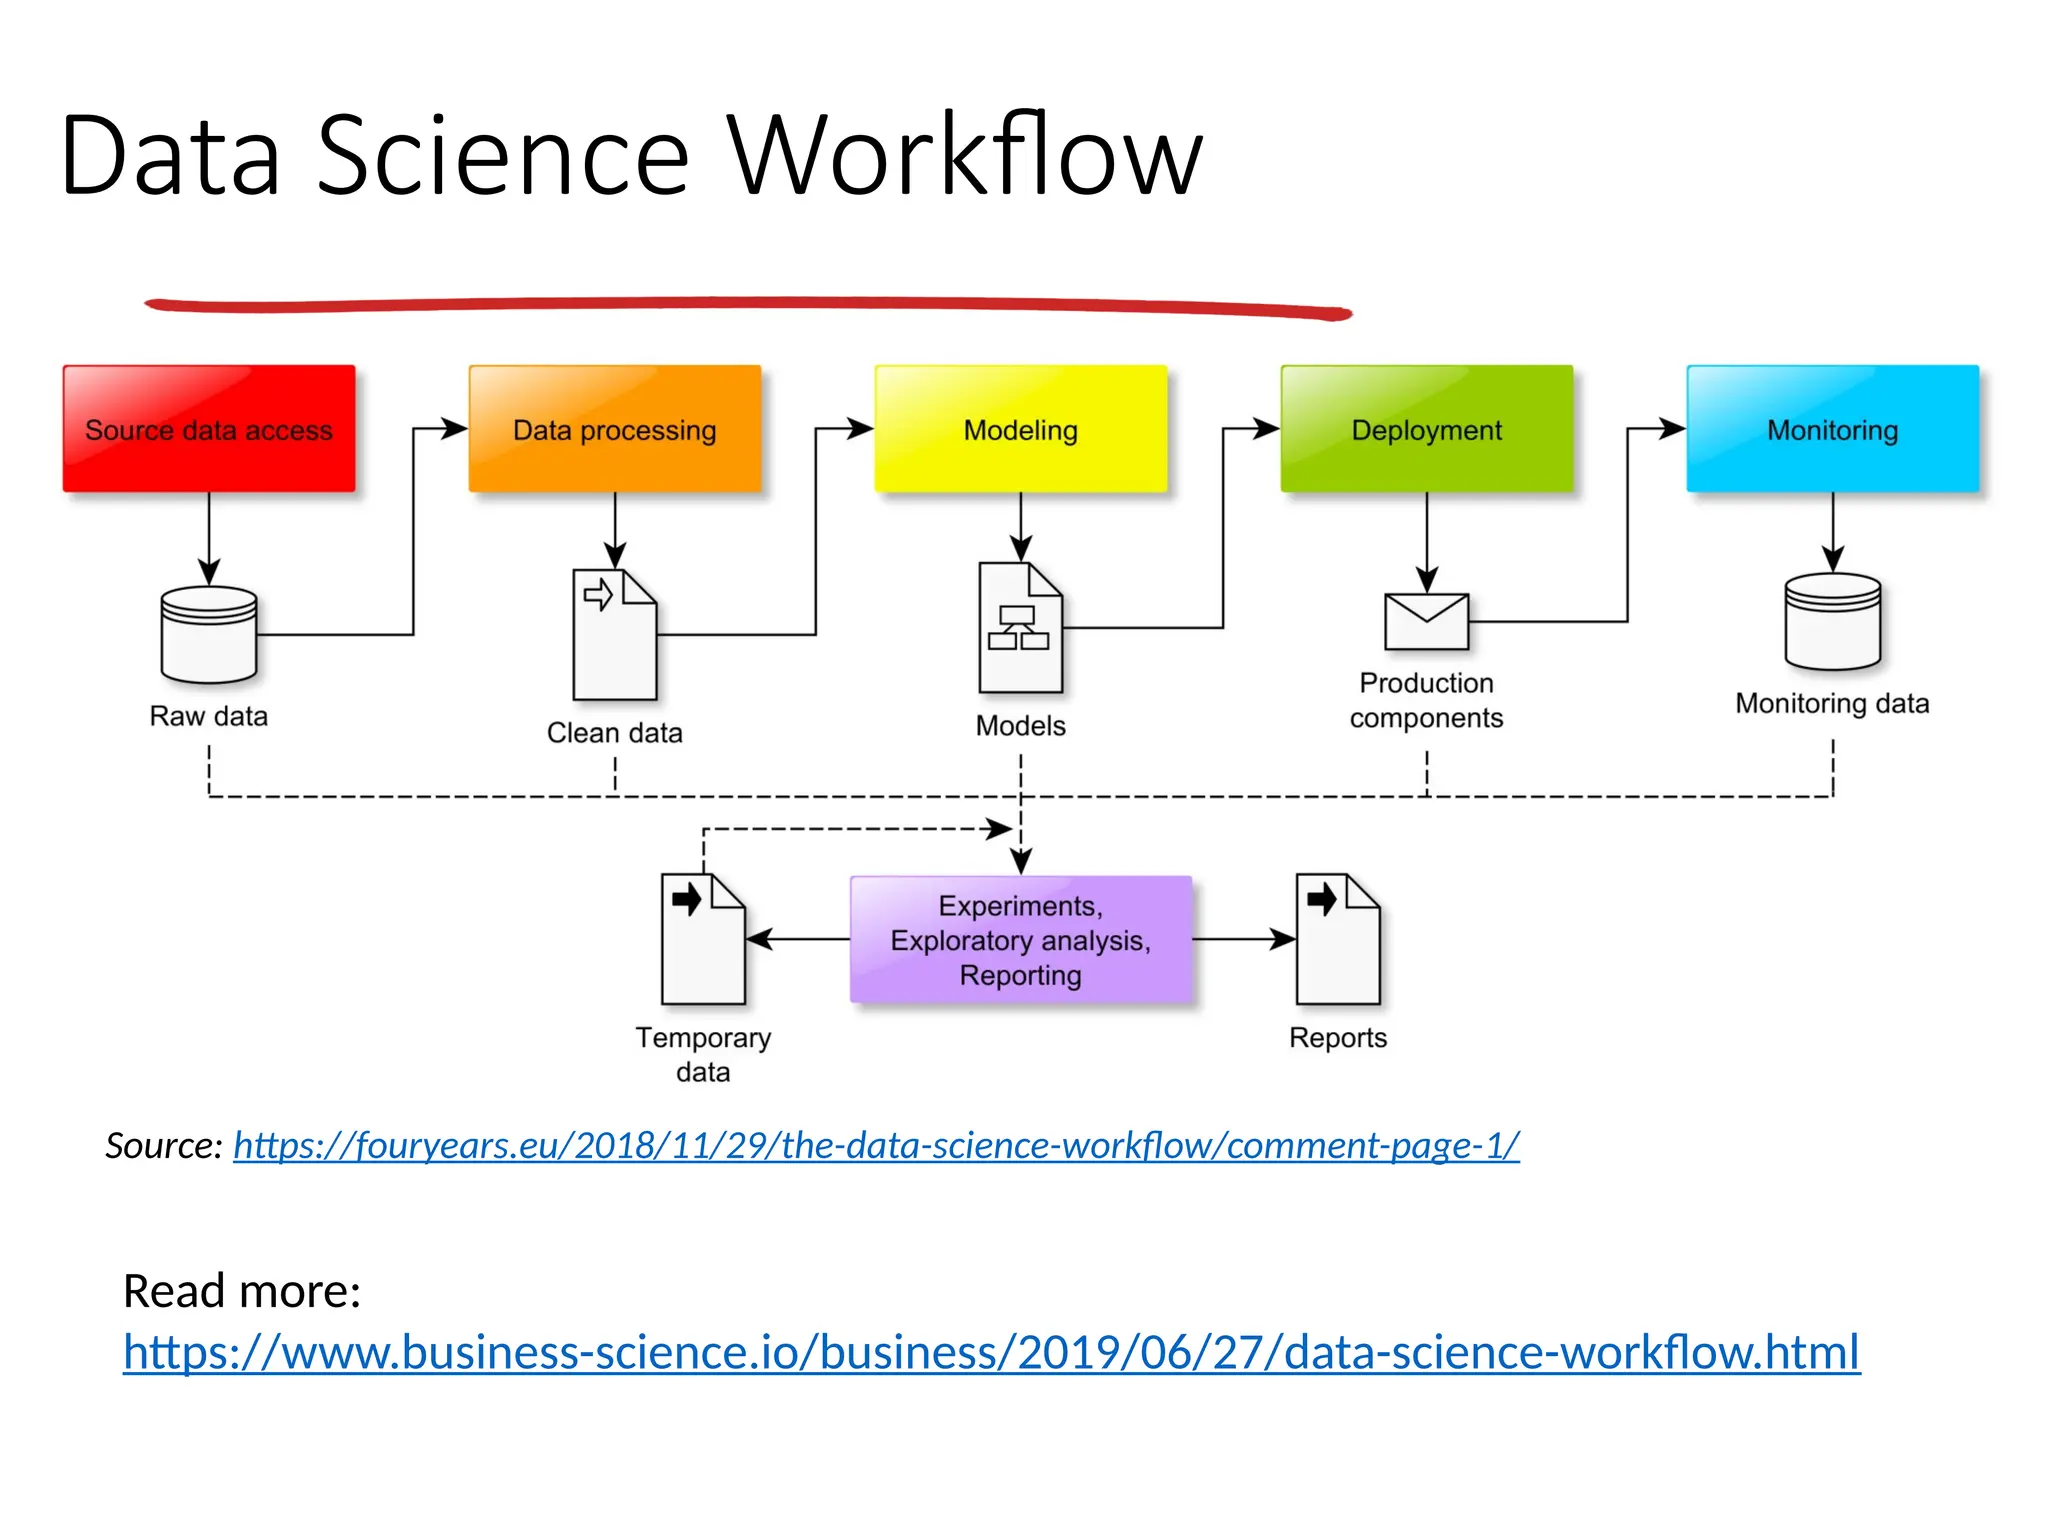
Here is the workflow I use now instead of the one I used to waste months on. You start by writing the answer you want, then work backward to figure out what you need to get there. Most people do it the opposite way. They set up the infrastructure first, then realize halfway through that the question doesn't actually need any of it. Step one is defining the output in concrete terms. Not "a machine learning model" but "a CSV file that tells the marketing team which customers will churn this month." That single sentence changes everything about how you build the thing. It forces you to identify the actual consumers, the actual format they need, and the actual decision they will make with it. Everything else is noise. Step two is figuring out what data sources you need. List them. Check if they exist. If a source requires permission from three different teams, you already know this project has a timeline problem before you write a line of code. I learned this the hard way on a project where I spent six weeks negotiating access to a single table that turned out to be mostly duplicate data from another table I already had. Two weeks in, not six.
Step three is the simplest part and the one most people skip. Build a baseline using the dumbest possible method. Linear regression. A decision tree with depth three. Even just grouping and averaging. This baseline gives you a reference point. If your fancy model doesn't beat it by a meaningful margin, you now have a conversation to have about whether the complexity was worth it. Without the baseline, you never know. Step four is iteration, not rebuild. Add one thing at a time. One feature. One model change. One preprocessing step. Measure the impact of each. Write down what changed and by how much. If you can't measure the impact, you're not doing data science, you're doing craft. I keep a single notebook for each project. Not ten notebooks. One. Jupyter, RMarkdown, or just a markdown file with Python code in it. The reason is that context switching between notebooks destroys reproducibility. I once spent an entire Friday trying to reproduce results from a project I'd built six months earlier, and the final model was different from what I thought it was because I had accidentally switched branches in a git repo I wasn't even tracking properly. A single file per project prevents that class of error entirely.
Get the Full Details

The Tradeoffs Nobody Talks About
Simple data science has real limitations. It fails when the problem genuinely requires distributed computing. It fails when you are working with streaming data that needs real-time inference. It fails when regulatory requirements demand auditable, versioned, documented pipelines that junior data scientists won't maintain. In those cases, the "simple" approach is the wrong approach, and pretending otherwise gets people fired. The middle ground is where most projects live, and it is the hardest to navigate. You need something more than a notebook but less than an enterprise platform. Apache Airflow is overkill for a monthly report. dbt is overkill if you are not already using a data warehouse. The right tool is usually a cron job or a GitHub Actions workflow that runs a Python script and emails the result. It is not glamorous. It works. Another limitation is organizational. Simple data science requires stakeholders who accept simple answers. If your management team expects a PowerPoint deck with twelve slides and three charts per slide, they are not going to be happy with a two-sentence email that says "the data shows X, we recommend Y." The gap between what the analysis produces and what the audience expects is a real bottleneck. I solve this by front-loading the narrative. I write the conclusion first, then build the analysis to support it, then add just enough detail to make it defensible. This takes less time than the alternative and usually produces better decisions.
The biggest pitfall I see is overfitting to the data rather than the problem. A model can have 99% accuracy and still be useless if it predicts the wrong thing. I had a client once who wanted a model to predict customer churn. The model predicted churn with excellent accuracy, but the features it relied on were things like "days since last purchase," which meant it was essentially predicting that people who haven't bought anything recently are churned. That was already obvious from the raw data. The model added no information. It was sophisticated nonsense. When simplicity fails, the alternative is usually a modular architecture. Break the pipeline into discrete steps. Each step has an input, an output, and a test. If something breaks, you know exactly which step failed. This is more work upfront but it saves you from debugging a monolithic script at midnight. The rule of thumb is: if a project will run more than ten times, it needs modularity. Before that, just write the script. The tools available today make simple data science easier than it has ever been. Pandas, scikit-learn, Polars, DuckDB, and a few other libraries cover the vast majority of use cases without requiring a cluster. The bottleneck is rarely the tool. It is the habit of reaching for the most powerful tool instead of the simplest one that solves the problem. I catch myself doing this still. It takes practice to choose the boring solution.