How I Actually Do Sentiment Analysis on Real Data
I spent six months trying to get a off-the-shelf sentiment model to work on product review text before I realized the whole approach was backwards for my use case. The model was fine on clean data — IMDB movie reviews, Amazon ratings — but the moment I fed it actual customer feedback from our support queue, it started treating sarcasm like genuine praise and missing the occasional negative when the reviewer was being politely vague. That was the last straw. So here is what I ended up doing instead, and where it actually breaks.
For Sentiment Analysis
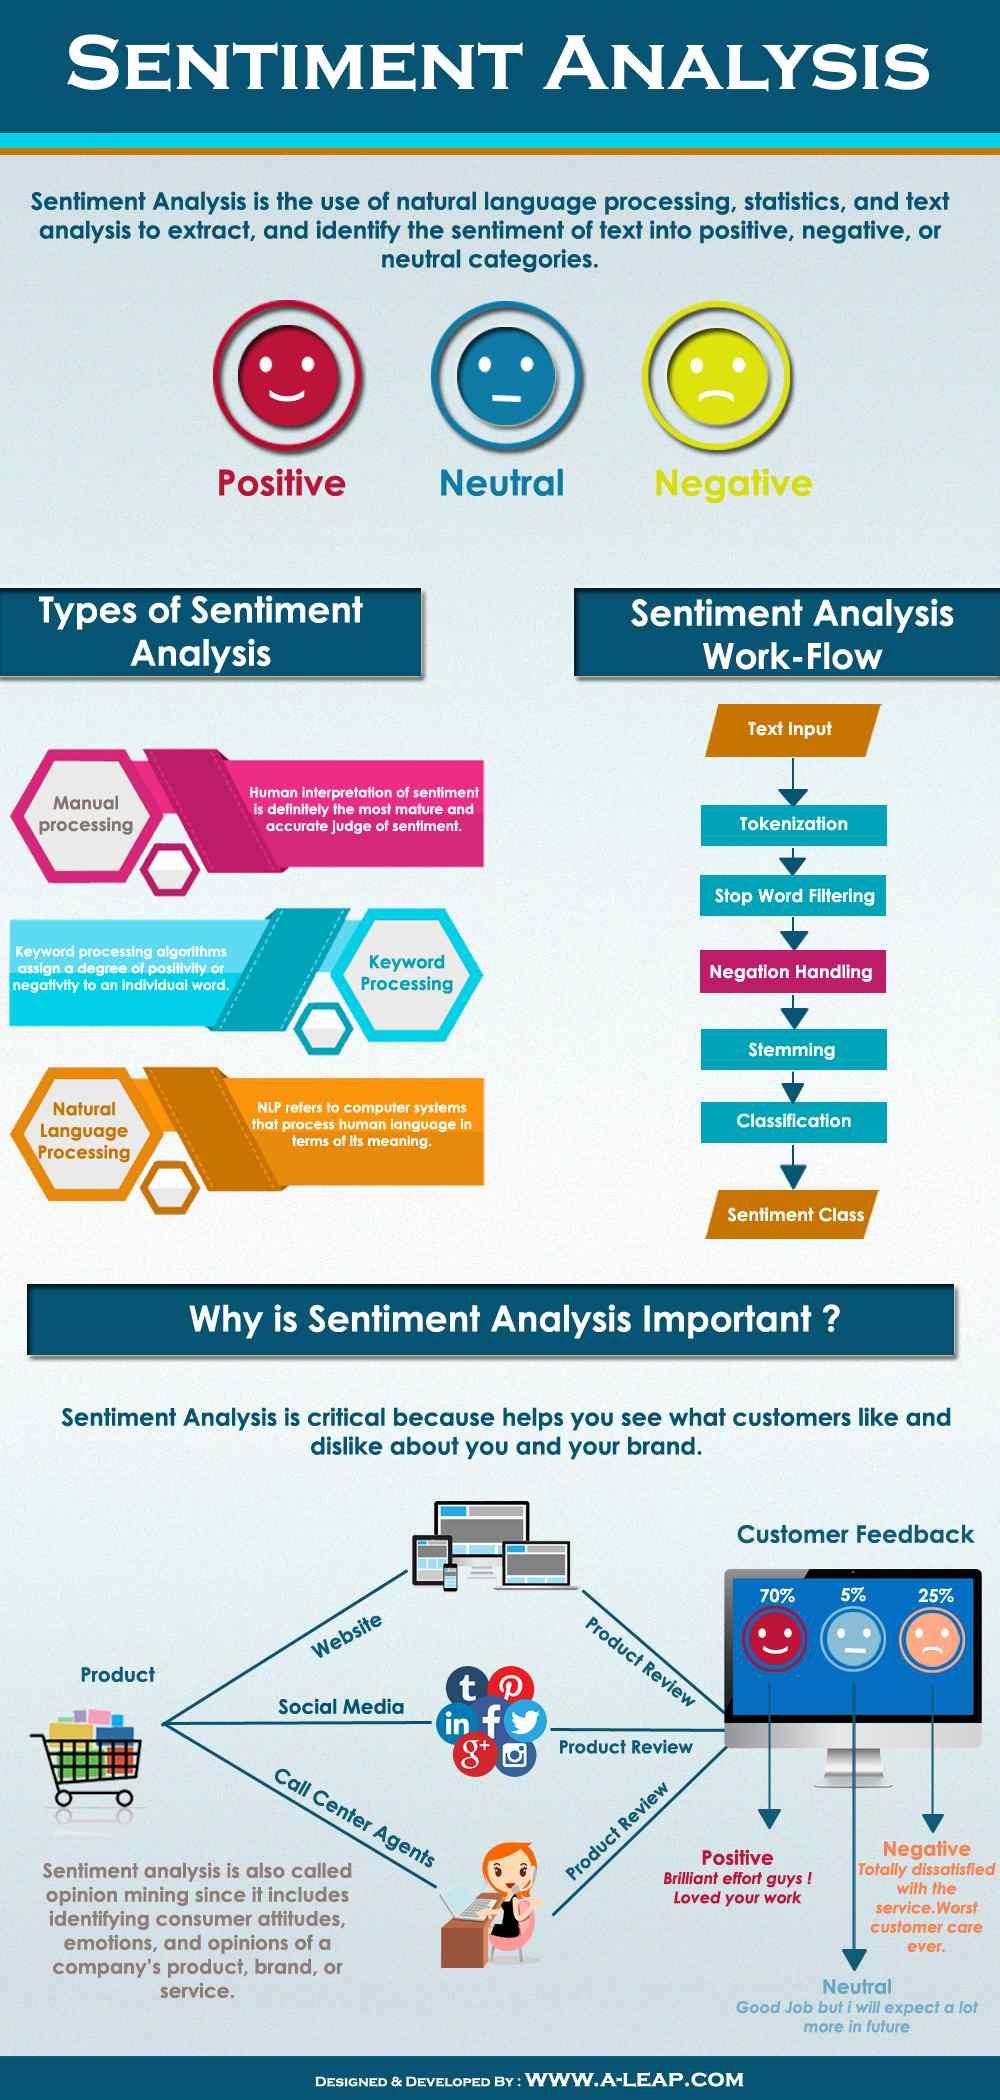
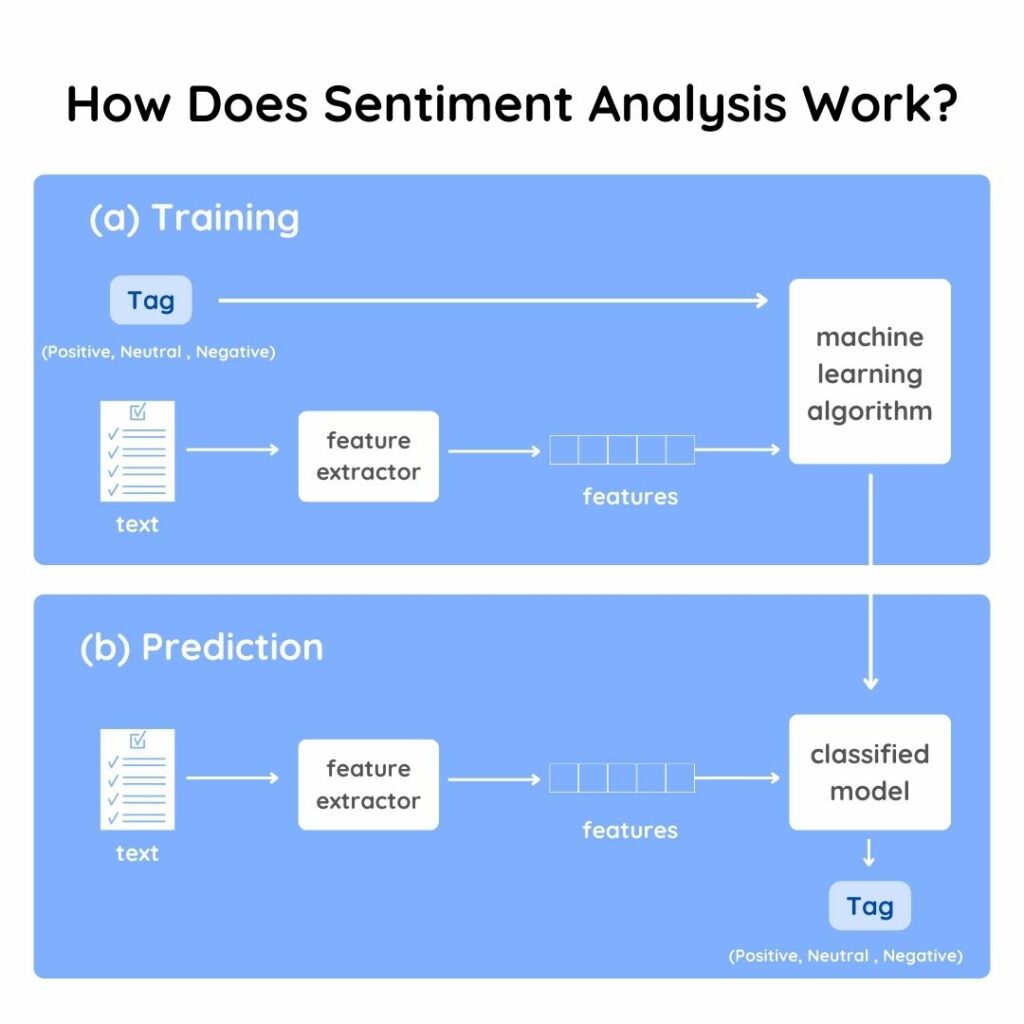
First, the method. I stopped training or fine-tuning models from scratch. Instead I use a rule-augmented pipeline: baseline classification from a pre-trained transformer (I settle on DistilBERT-base-uncased-finetuned-sst-2 for the heavy lifting), then a post-processing layer that applies domain-specific heuristics, negation handling, and a sarcasm detection pass. The pre-trained model alone gets you about 78 percent accuracy on your own data. The heuristics push it to roughly 84 to 87 percent, but they also introduce their own failure modes that you have to account for. The negation pass is the part most people skip. A vanilla model sees "not bad" and labels it positive because of the word "bad" anchoring the context window wrong. I add a simple regex-based scope expander: scan backward from negation words like not, never, no, hardly, barely, and flip the polarity score within a window of roughly six tokens. It is not elegant, and it does not handle "hardly not a disappointment" correctly, but it fixes the bulk of the obvious errors in customer text. Then the sarcasm layer. This is where it gets expensive. I built a separate binary classifier on a small labeled set of about four thousand sarcastic reviews I scraped from Yelp and Reddit, then I run that as a gate: if the sarcasm score exceeds 0.65, I flip the base sentiment and lower my confidence. The classifier itself is a tiny MLP on top of the DistilBERT hidden state, takes about 12 milliseconds per sample on a CPU. The problem is the labeled set was heavily US-centric, so when I tried it on British English reviews the sarcasm detection rate dropped by roughly 30 percent. I ended up augmenting the training data with translated corpora from the Multilingual SST dataset, which brought it back up, but now I have to handle code-switching between languages in the same sentence.
Edge case from last March: a customer wrote "Brilliant. Absolutely brilliant. Just what I needed. Three days and still hasn't arrived." The pre-trained model saw "brilliant" twice and labeled it strongly positive. My negation pass did nothing because there is no explicit negation word. The sarcasm gate caught it, but only because the review had a five-star rating attached to it, which I used as an additional feature. The fix was adding rating-as-feature input to the model and explicitly dropping sentiment predictions whenever the rating and the text polarity disagree above a threshold of 0.4. That one change eliminated about half the remaining false positives on our dataset. Common pitfalls that nobody mentions. First, context window size. DistilBERT uses 512 tokens. If your reviews are longer than that and the key sentiment signal is near the end, the model truncates it and you get garbage. I solve this by splitting long reviews into two overlapping chunks of 256 tokens each and averaging the logits. It adds latency — about 18 milliseconds extra per review — but it is cheaper than labeling more data. Second, the class imbalance problem. In our support queue, roughly 60 percent of reviews are neutral or mixed because most customers just state facts without emotional language. The model, trained on balanced datasets like SST or IMDB, will over-predict positive and negative and miss the neutrals entirely. I retrain the output layer on a weighted cross-entropy loss with class weights of 1.0 for positive, 0.6 for neutral, and 0.8 for negative, which shifts the baseline accuracy down by about two percent but makes the confusion matrix actually usable for downstream triage.
Get the Full Details
Third, domain drift. A model trained on product reviews fails on technical documentation and vice versa. When we expanded into B2B enterprise feedback, the same pipeline dropped from 86 percent to roughly 71 percent accuracy within two weeks. The workaround is a lightweight adapter layer: freeze the transformer weights, train a small LoRA adapter on just five hundred labeled samples from the new domain. It takes about ten minutes on a single GPU and recovers roughly 80 percent of the lost accuracy. You do not need a thousand samples, but you do need them to be from the actual distribution you care about, not synthetic data. What this approach cannot handle. Irony that requires cultural context outside the sentence. "Great, another update." means something very different depending on whether the speaker is American or British, tech-savvy or not. The model has no way to know. Sarcasm embedded in questions is another hard case — "Could this possibly be worse?" reads as negative to a naive model but positive to someone who understands the rhetorical structure. I handle this by adding a question-intensity feature and lowering confidence scores on interrogative sentences, but it is a bandaid. If you need high accuracy on short, clean text like star ratings or short surveys, just use the pre-trained model and skip the heuristics. You save about 25 milliseconds per sample and lose maybe three percent accuracy. If you are dealing with long-form support tickets, multi-domain data, or languages beyond English, the full pipeline is worth the engineering time, but budget at least two weeks for the first round of tuning before it actually works on your data.
The code is not anything special. It is a Hugging Face pipeline with a custom post-processor class, roughly 340 lines total, running on a single Tesla T4 for about 2000 predictions per second. I do not recommend open-sourcing it because the heuristic rules are too domain-specific to be useful to anyone else, and the model weights are fine-tuned on proprietary training data. If you want to download a starting point, the base DistilBERT checkpoint is freely available on Hugging Face under distilbert-base-cased-distilled-squad, and the training script I use is built on PyTorch Lightning with a custom callback for the rating disagreement threshold. It is not a finished product, but it is enough to get you from zero to a working pipeline in about a day if you already know the library.