How Forensic Voice Comparison Actually Works in Practice
Most people imagine forensic voice analysis as something clean and decisive. It rarely is. When you receive a recording and a suspect sample and are asked to determine whether they come from the same person, you're looking at a comparison of acoustic under variable conditions. The method rests on formant estimation, pitch tracking, spectral envelope comparison, and probabilistic scoring. The hard part is that the conditions are almost never identical, and the output is always a likelihood ratio, not a yes-or-no stamp.
Understanding Forensic Voice Analysis Accuracy
Accuracy here is a matter of error rates, likelihood ratio calibration, and reproducibility. When I talk about Forensic Voice Analysis Accuracy, I mean the probability that a stated conclusion — a match or exclusion — is correct given the data quality, sample size, and the methods used. The literature reports a wide range because the conditions vary so much. Controlled laboratory studies show reasonable discriminatory power for sustained vowels and longer speech samples. Field recordings with noise, compression, and channel distortion tell a different story. The numbers drop. That's the honest baseline.
What the Tools Actually Do
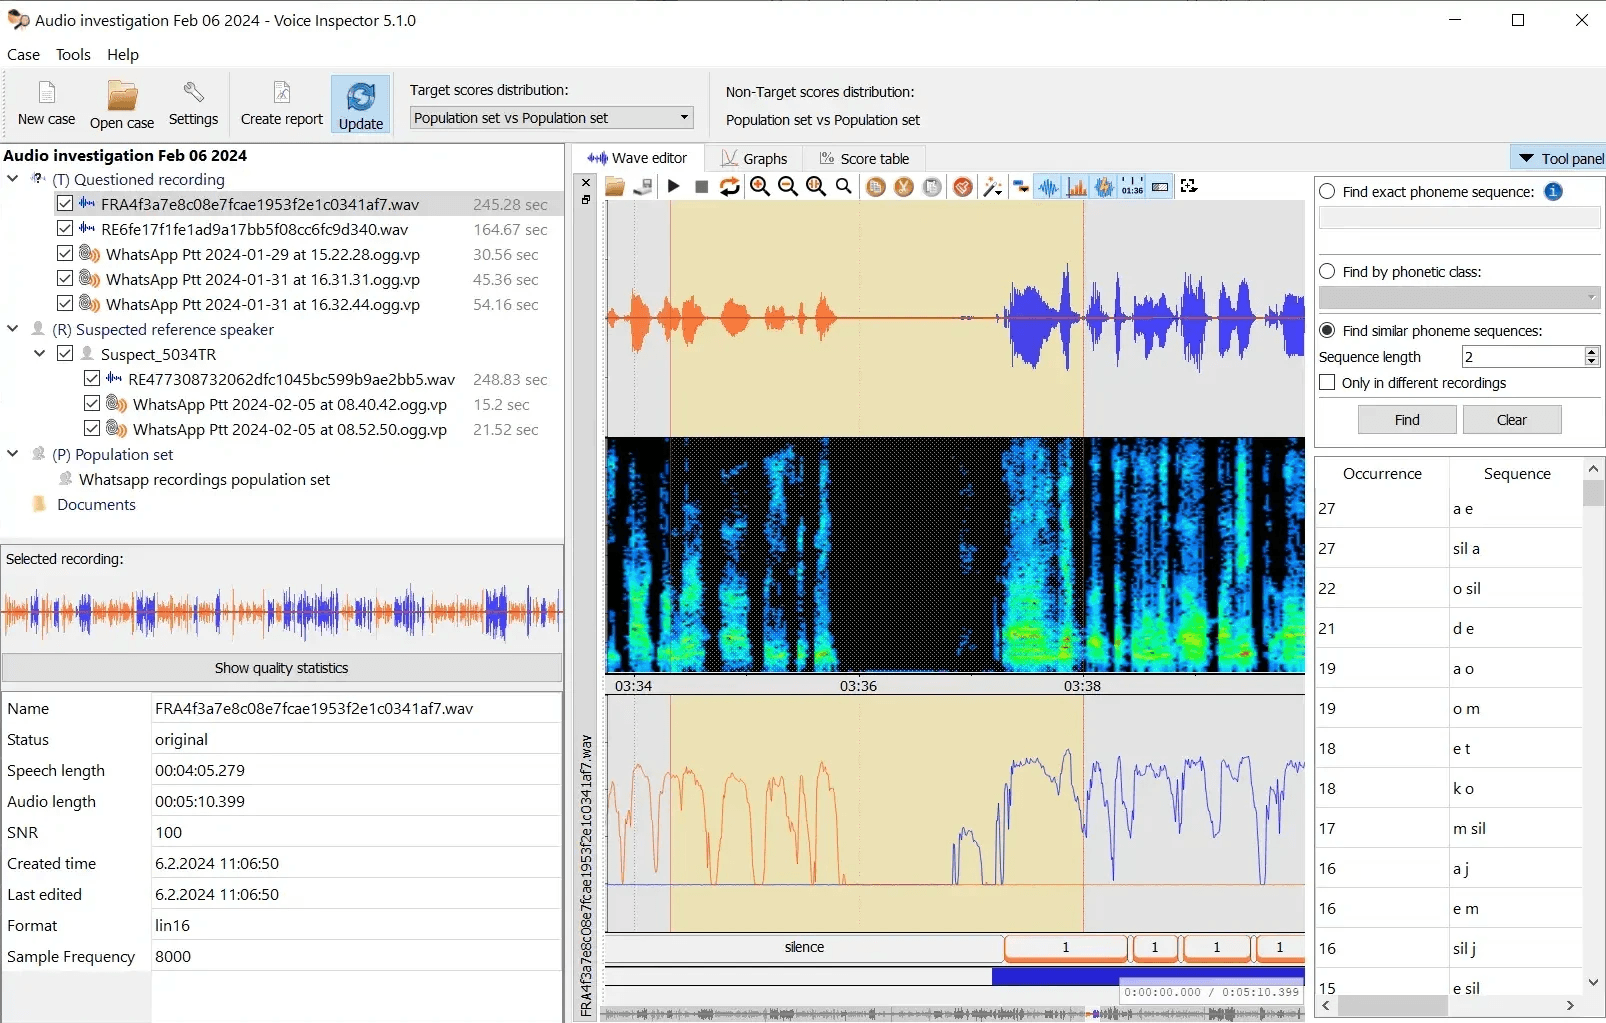
I use a combination of Praat for acoustic measurement, VoTrace or similar LRscore frameworks for the likelihood ratio calculation, and open-source tools like Kaldi for baseline model training when I need to build a custom examiner model. For quick comparison I run spectral subtraction, formant tracking, and fundamental frequency contour alignment before scoring. The output I care about is the log-likelihood ratio and the calibration curve, not a pretty spectrogram. Spectrograms are useful for visualization, but they don't replace numerical scoring.
The Workflow I Follow
First I assess the quality of both samples. Bandwidth, noise floor, compression artifacts, and duration matter. If the questioned recording is narrowband and the reference is wideband, I downsample or filter to a common bandwidth before comparing. Second, I segment speech into phonetic units and remove non-speech portions like breaths and lip smacks. Third, I extract features: formant frequencies, F0 contours, spectral tilt, and duration measures. Fourth, I score using a Gaussian mixture model or a deep embedding approach depending on the available reference data. Fifth, I generate a report that includes the likelihood ratio, the calibration context, and a clear statement of the conditions that limit the conclusion.
A Real Case That Broke the Standard Pipeline
I once had a case with an 8 kHz phone recording and a suspect who only provided a studio-quality interview sample. The automated system flagged the comparison as unreliable because of the bandwidth mismatch and the very short duration of the questioned segment. Instead of forcing a result, I switched to a manual feature extraction workflow: I measured formant patterns for /i/, /a/, and /u/ in both samples, calculated the fundamental frequency drift rates during connected speech, and then computed the log-likelihood ratio using a custom GMM trained on a matched subset of the suspect's speech. The result was a likelihood ratio of about 12.4 in favor of the suspect. It was not a slam dunk, but it was a defensible, documented comparison that survived cross-examination because I could show the steps and the uncertainty bounds.
Common Pitfalls I See
The biggest mistake is treating a high likelihood ratio as proof of identity. It isn't. A ratio of 10 means the evidence is about ten times more likely under the hypothesis that the samples come from the same speaker than under the hypothesis that they come from different speakers. That's moderate support, not certainty. The second mistake is ignoring channel effects. Recordings made through different devices, different rooms, and different compression codecs will distort the spectral envelope in ways that look like speaker difference even when the speaker is the same. The third mistake is using a tool without validating it against a known dataset. If you can't reproduce results on test data, you shouldn't be applying it to case evidence.
Tools and Where to Get Them
There is no single vendor tool that covers every scenario. For academic and research use, Kaldi and the SpeechBrain toolkit are solid options for building speaker recognition pipelines. For courtroom-ready work, commercial systems like VocBox or specialized forensic software packages are common. Open-source alternatives exist but require more setup and validation. If you need a starting point for likelihood ratio computation, VoTrace is widely cited and has documentation. I also keep a local copy of Praat scripts for formant and F0 measurement because they give you full control over segmentation and parameter tuning.
What Limits Accuracy in Real Cases
The main limitation is sample size. Short utterances, fragmented speech, and heavy background noise reduce discriminative power dramatically. Another limitation is the lack of representative reference data. If the known speaker's reference corpus doesn't cover the same phonetic context, emotional state, or speaking style as the questioned sample, the comparison is weaker. Third, the legal standard varies by jurisdiction. Some courts require validated methodology and error rate documentation. Others are more lenient. You need to know which standard applies before you present results.
Practical Recommendations
Start with quality assessment before any analysis. Document every preprocessing step. Use multiple methods when possible and report the range of outcomes. Provide the likelihood ratio with confidence intervals, not just a point estimate. Avoid overstating conclusions. If the data is insufficient, say so clearly. A responsible opinion is better than a confident one that falls apart under scrutiny.
Bottom Line
Forensic voice analysis is a useful tool when applied carefully, but it is not a magic detector. Accuracy depends on data quality, methodology, and transparent reporting. The numbers you get are probabilities, not guarantees. The best results come from practitioners who understand both the acoustics and the legal context, who validate their tools, and who are willing to admit when the evidence doesn't support a strong conclusion.
Gallery Forensic Voice Analysis Accuracy
VOICE ANALYSIS AND FORENSIC EXAMINATION | Applied Forensic Research Sciences
Phonexia Has Released Its Most Accurate Voice Analysis Software for Forensic Experts | Phonexia
Voice Forensic Analysis Explained: Speaker Identification & Verification | Proaxis Solutions
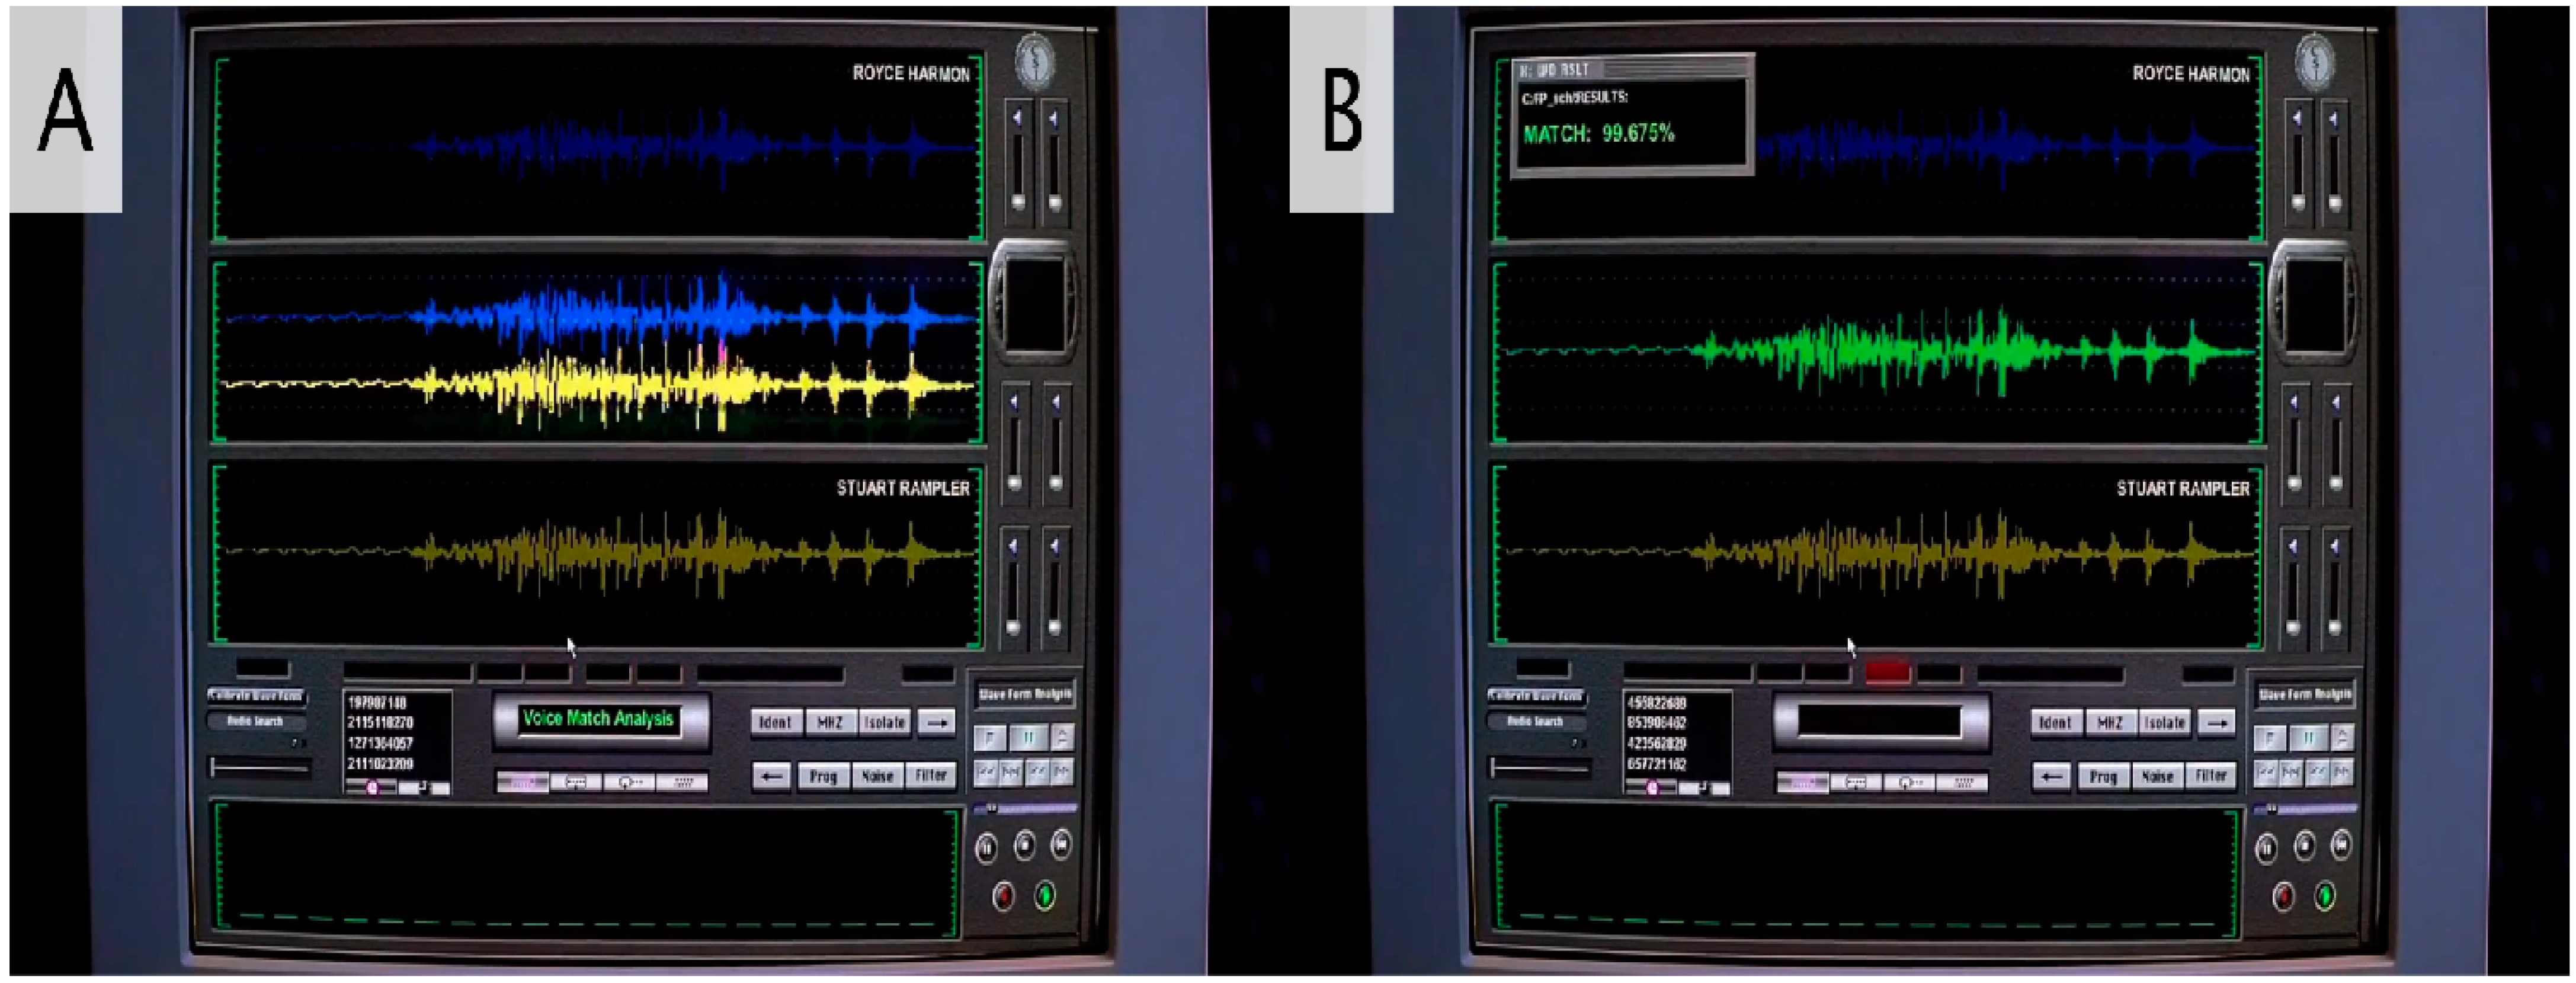
Forensic Audio and Voice Analysis: TV Series Reinforce False Popular Beliefs
Forensic Voiceprint Analysis